Guides / 動画ウォークスルー
Jev Agent Harness: Where the Decision Gate Sits in Your LLM Loop
最終更新日: 2026-09-26
The Stack dissects the agent harness pattern: LangChain published the design two days after launch — Jev routes each run to a small or flagship model, guards every tool call in auto mode, and lets the LLM keep writing — with independent numbers on what the gate really saves.
要点
An agent harness puts a decision gate around the LLM loop, and Jev is the gate: two days after launch LangChain published a harness where job 1 routes each run to a small model or a flagship before the agent starts, and job 2 (auto mode) vets every tool call and blocks risky ones before execution. The division of labor is the point — the LLM keeps writing and designing while Jev answers locked questions like allow, ask a human, or block in one pass. Audited numbers: a DSPy pipeline that offloaded yes/no and pick-one steps ran 15.9% faster (1.958s vs 2.329s) and 30.1% cheaper ($0.000377 to $0.000263 per ticket); TypeSafe’s 193x/444x homepage claims measured 3x and 12x in an independent 2,000-email test. And trust is earned, not assumed: one broad phishing question scored 62.6% (Haiku 4.5: 81.3%) while five narrow signals with tuned weights lifted Jev to about 95% — so gates escalate on confidence and hardcoded checks stay in the code.
ステップごとのウォークスルー
- 1
See the harness pattern: the LLM writes, Jev answers right next to it
Two days after Jev launched, LangChain engineers Sydney Runkle and Hunter Lovell published “Building a Harness with Jev” — the design this guide dissects. The pattern starts from the ordinary agent cycle (request in, LLM reasons, tools get called, results come back) and admits its weakness: an LLM is expensive to consult for the hundreds of tiny judgments a run needs, and every extra LLM check makes agents slow. A harness splits the work instead. The generative model keeps the jobs it is built for — writing and designing — while Jev, the System One decision model that returns typed answers instead of prose, sits right next to it answering the small questions your code asks. As LangChain puts it, Jev is not a replacement for the LLM; it is the cheap, fast decision layer beside it.
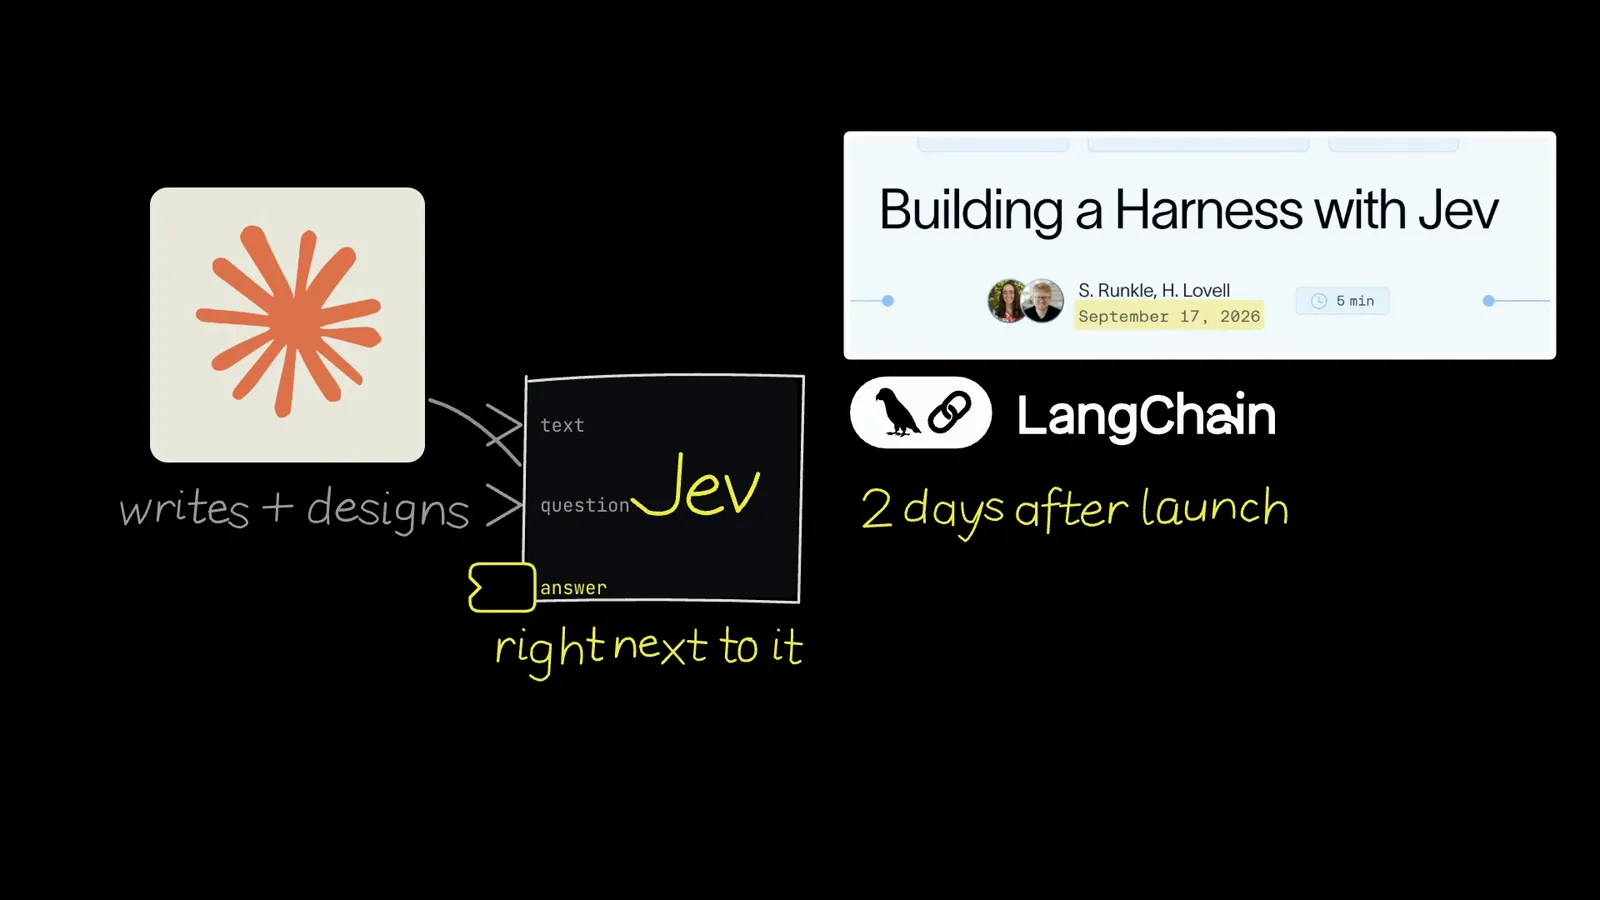
The harness pattern: generation stays with the LLM; judgment moves to Jev.タイムスタンプ 5:10 を見る - 2
Anchor the division of labor with a command your code already fears
The cleanest way to feel the pattern is a destructive shell command. A scheduling agent wants to run rm -rf ./project, and no rule in your code can tell routine cleanup from a catastrophe. The old move — ask a chat model for a verdict — means paying for a paragraph and waiting seconds while the model explains its feelings (and grades its own homework). In the harness, the coding agent hands the command to a Jev gate first: Jev evaluates the state and returns one of the options you locked in advance — allow, ask a human, or block — with a probability, and an ordinary if statement acts on it. Claude keeps writing and designing the software; Jev answers the one question the pipeline cannot decide alone. The whole exchange costs a fraction of a cent and finishes in a few hundred milliseconds.
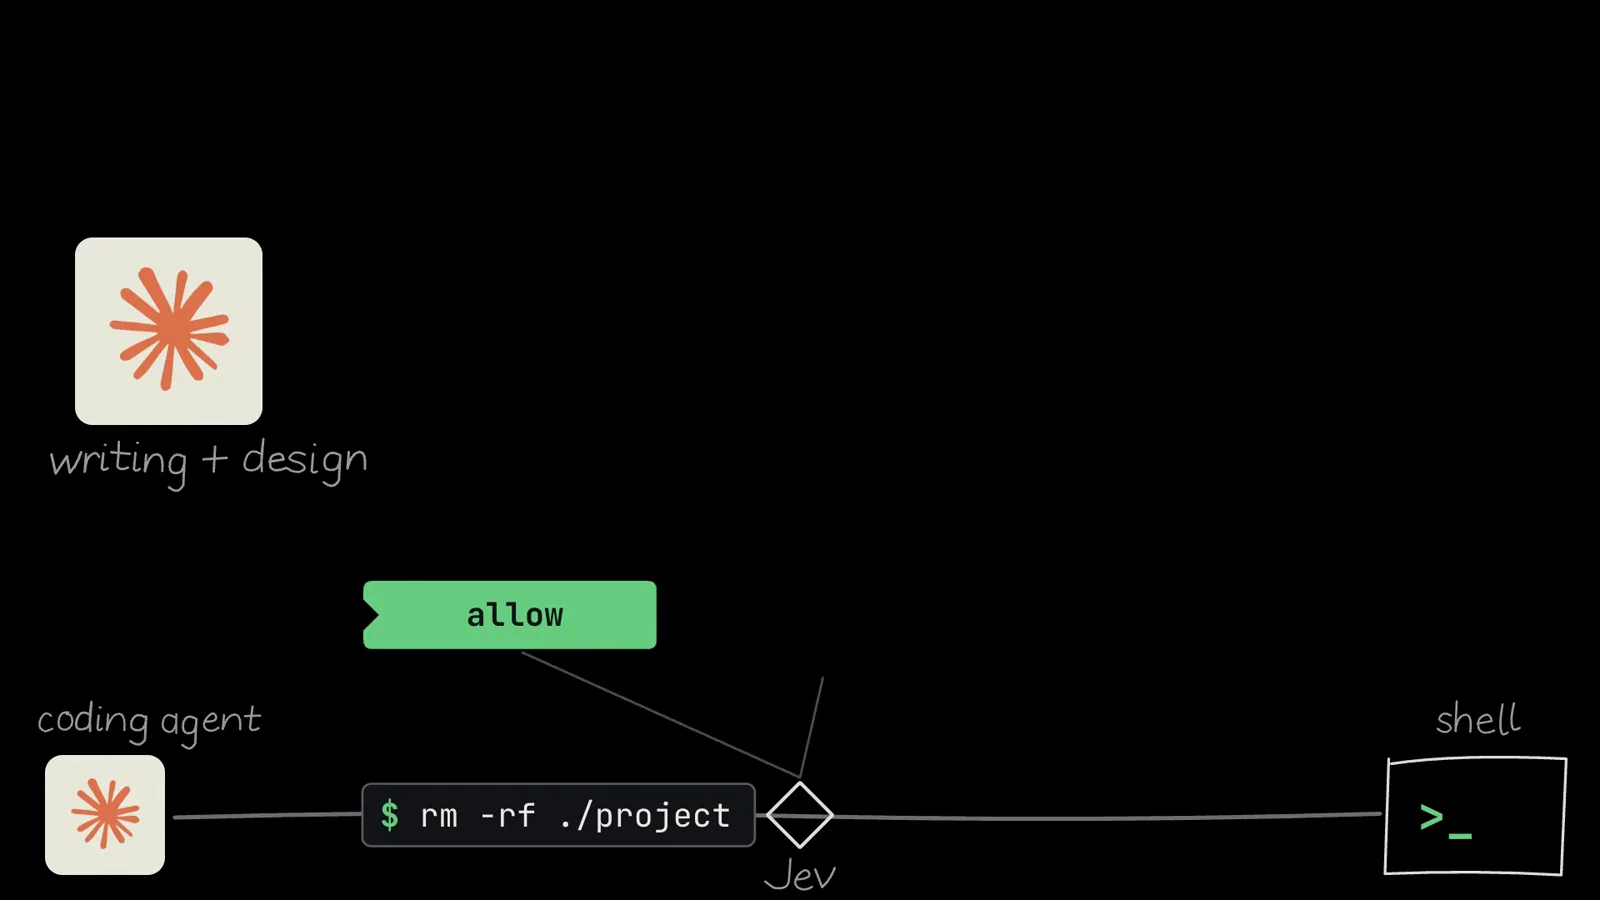
Claude writes and designs; Jev rules on the one command the code cannot judge.タイムスタンプ 6:05 を見る - 3
Wire the two harness jobs: model routing and Auto Mode
LangChain’s harness gives Jev exactly two jobs. Job 1, model routing: before the agent starts, Jev classifies the user’s prompt — “fix this typo” goes to the small model, “plan the db migration” to the flagship — so you stop paying flagship prices for typo fixes. Job 2, Auto Mode: a middleware that inspects every tool call the agent attempts and blocks risky ones before execution — in the webinar demo a CRM note update sailed through while “delete this customer” was stopped right before the tool fired. The before-and-after is the part worth remembering: Sydney Runkle had turned auto mode off in her own coding agent because the LLM-based risk check was too slow, and switched it back on once Jev made the classification nearly free. A guard that costs seconds per call is a guard you will disable; a guard that costs a fraction of a cent stays on.
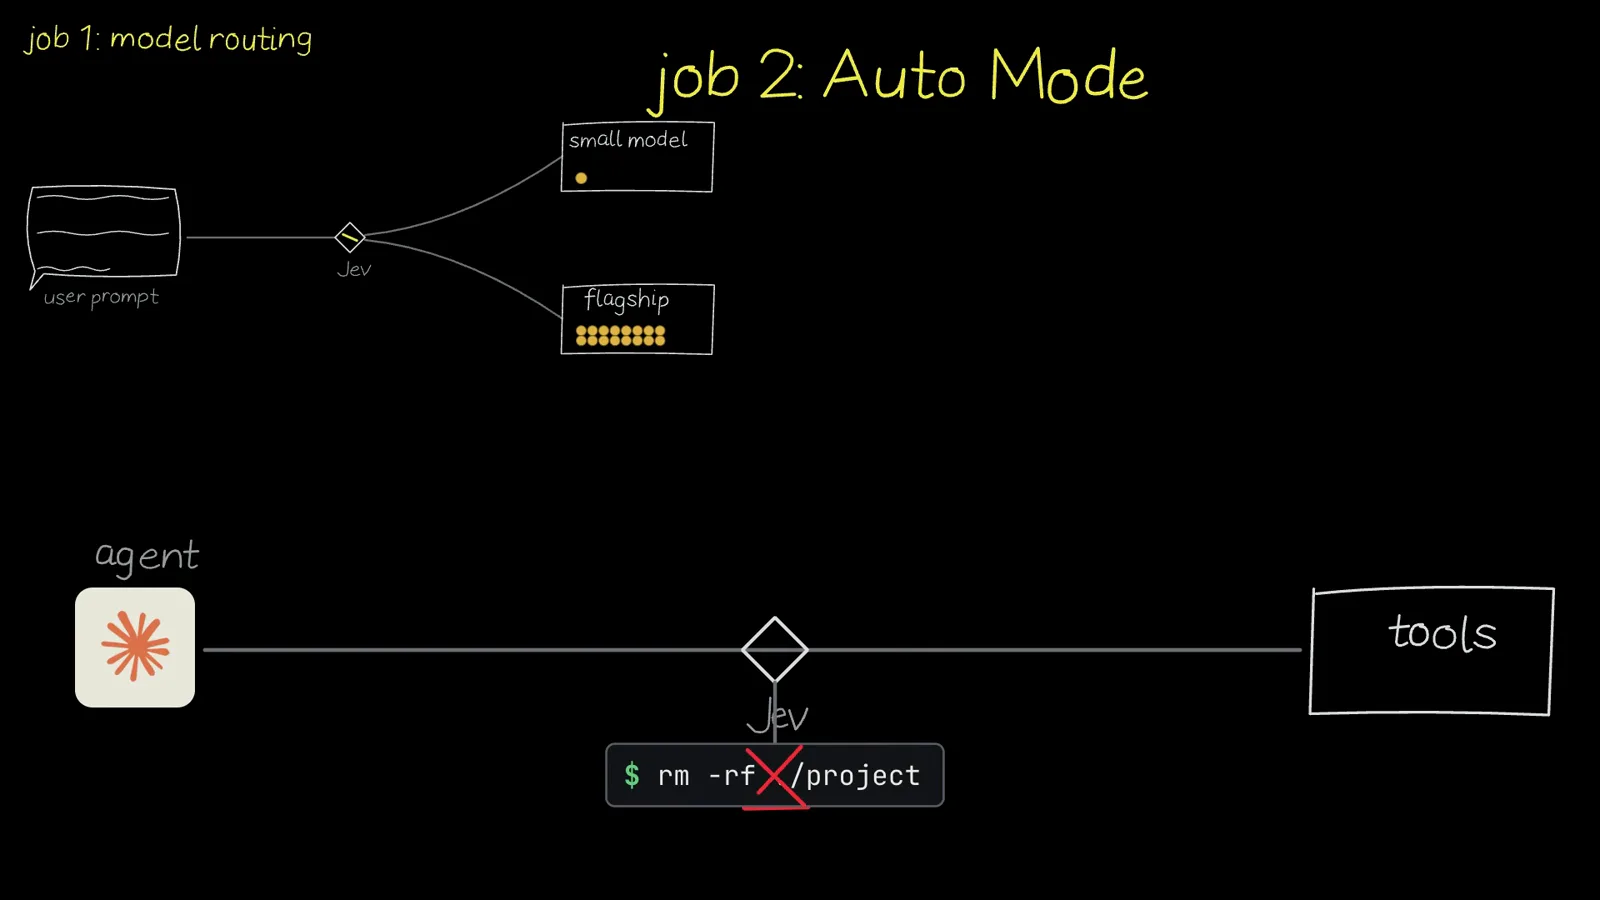
Two jobs: route the run before it starts, guard every tool call inside it.タイムスタンプ 5:35 を見る - 4
Ask typed questions, not chat: Choice for the verdict, Noul for the risk
What does a gate actually say to Jev? Two atomic questions in a single call. A Choice question — “Should this command run?” over the options allow, ask a human, block — returns a probability for every option, so you see not just the winner but how close the call was. A Noul question — “Is this destructive?” — returns a yes/no probability on a zero-to-one scale. Both evaluate in parallel in one pass, and the answer is structurally locked to your option list: Jev cannot invent a fourth verdict, which is all the “zero hallucination” claim ever meant. It can still pick the wrong option — a type-valid answer can be semantically wrong — so the probabilities are inputs to your policy code, not orders. Keep each question atomic: one concern per question, criteria in plain language, levels described so a panel of strangers would agree on them.
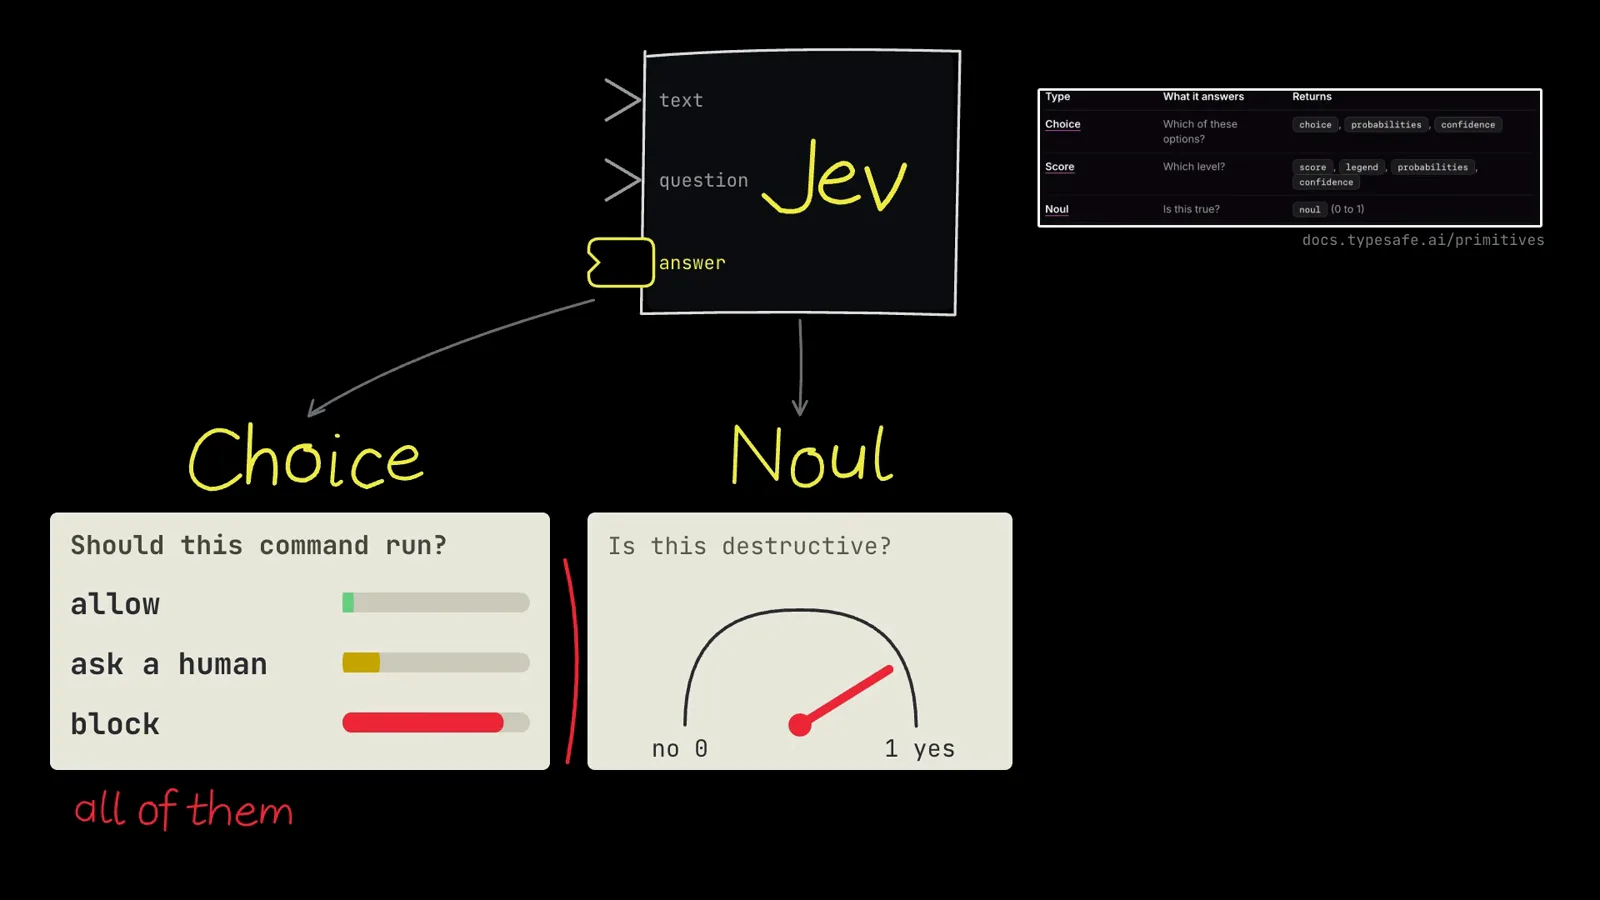
The gate’s vocabulary: per-option probabilities plus a destructive yes/no — one call.タイムスタンプ 3:05 を見る - 5
Budget honestly: what the gate saves when you measure it
TypeSafe’s homepage advertises 193.6x faster and 444.6x cheaper; the company itself flags those as the high end, measured from its own laptops against its own evals. Independent numbers are smaller and more useful. In a 2,000-email benchmark posted to GitHub, Jev decided in 239 ms where Claude Haiku 4.5 took 687 ms — about 3x, not 200x — and cost roughly 4 cents per 1,000 emails against 46 ¢ — about 12x. The pipeline experiment shows where those savings actually land: offload only the yes/no and pick-one steps of a DSPy workflow to Jev and keep WRITE on the LLM, and the decorated path averaged 1.958 s versus 2.329 s (15.9% faster) with modeled cost falling from $0.000377 to $0.000263 per ticket (30.1% off). The generation step still charges full price — that is expected. The harness wins by making the small calls nearly free, not by replacing the writer.
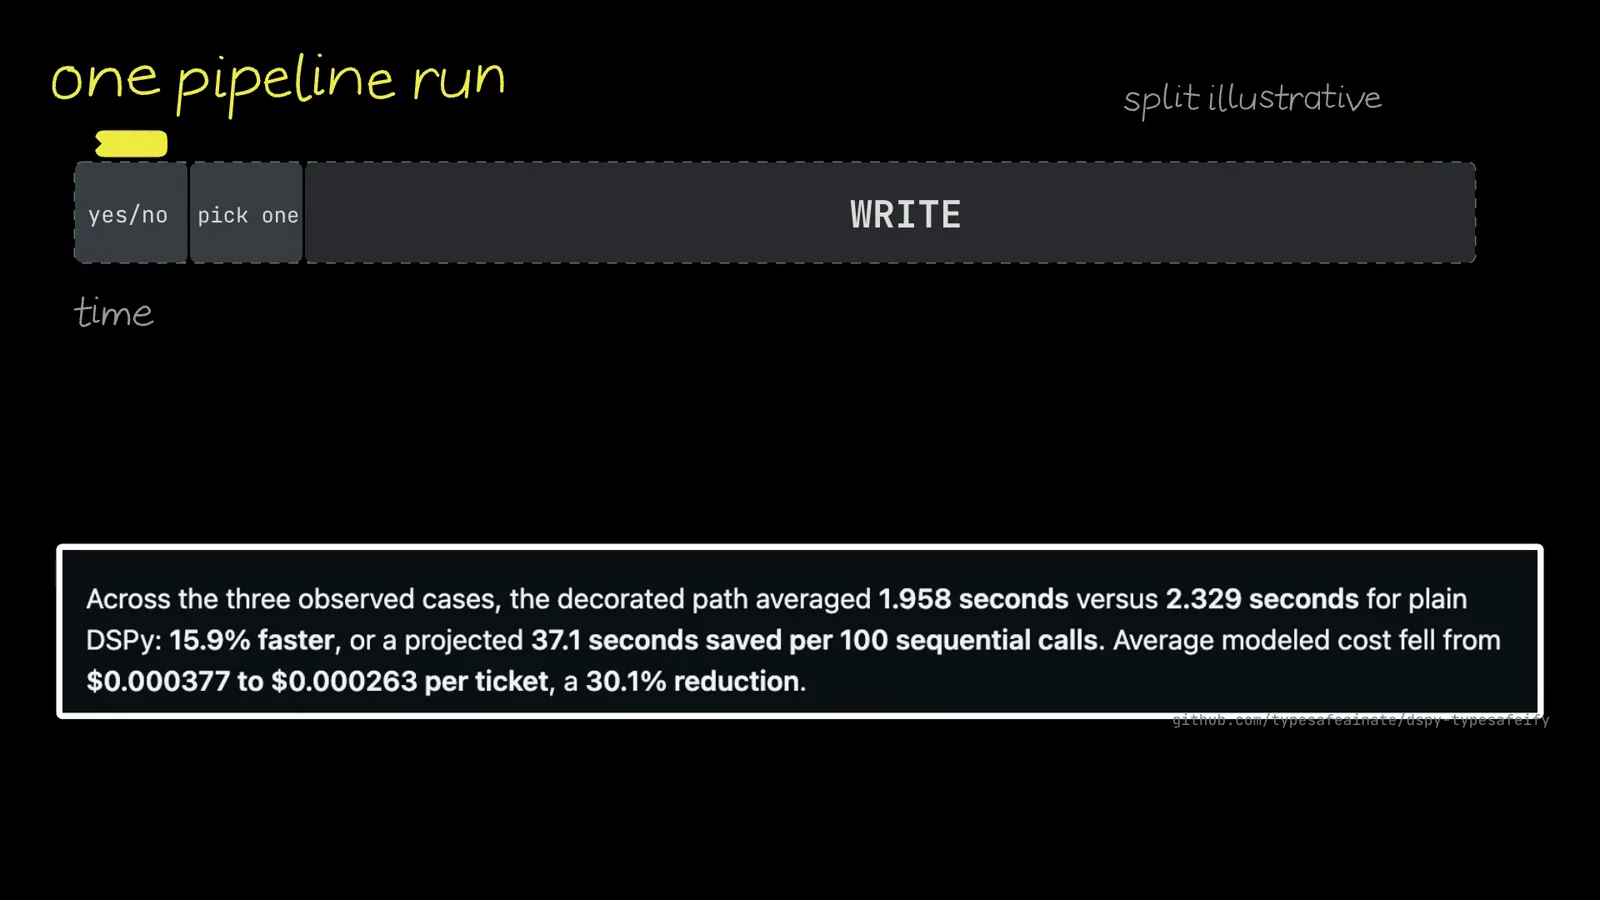
Offload the two tiny steps, keep WRITE on the LLM: 15.9% faster, 30.1% cheaper.タイムスタンプ 9:10 を見る - 6
Earn the gate’s trust: narrow questions, confidence gates, hard checks
A gate you overtrust is worse than no gate. Asked one broad question — phishing or legitimate? — Jev was right on 62.6% of 2,000 test emails; Claude Haiku 4.5 hit 81.3% on the same prompt. Split into five narrow signals (urgent tone, link mismatch, unknown sender, asks for money, odd domain) with weights tuned on 1,000 labeled examples, Jev’s combined accuracy reached about 95% and edged past Haiku’s 93% — narrow, well-defined checks are where it wins. Ship the gate accordingly: use confidence as a second axis beside the class (high confidence and low risk automates; ambiguity takes the safer path; high risk escalates even when the class looks clear), know that confidence measures spread on the probability map so legitimately competing options read low, and log state, answers, and gate decisions so you can audit them. Start in shadow mode against decisions you already know the truth about, and keep hardcoded checks for the irreversible stuff — a full root wipe should die in an if statement, not in a model call.
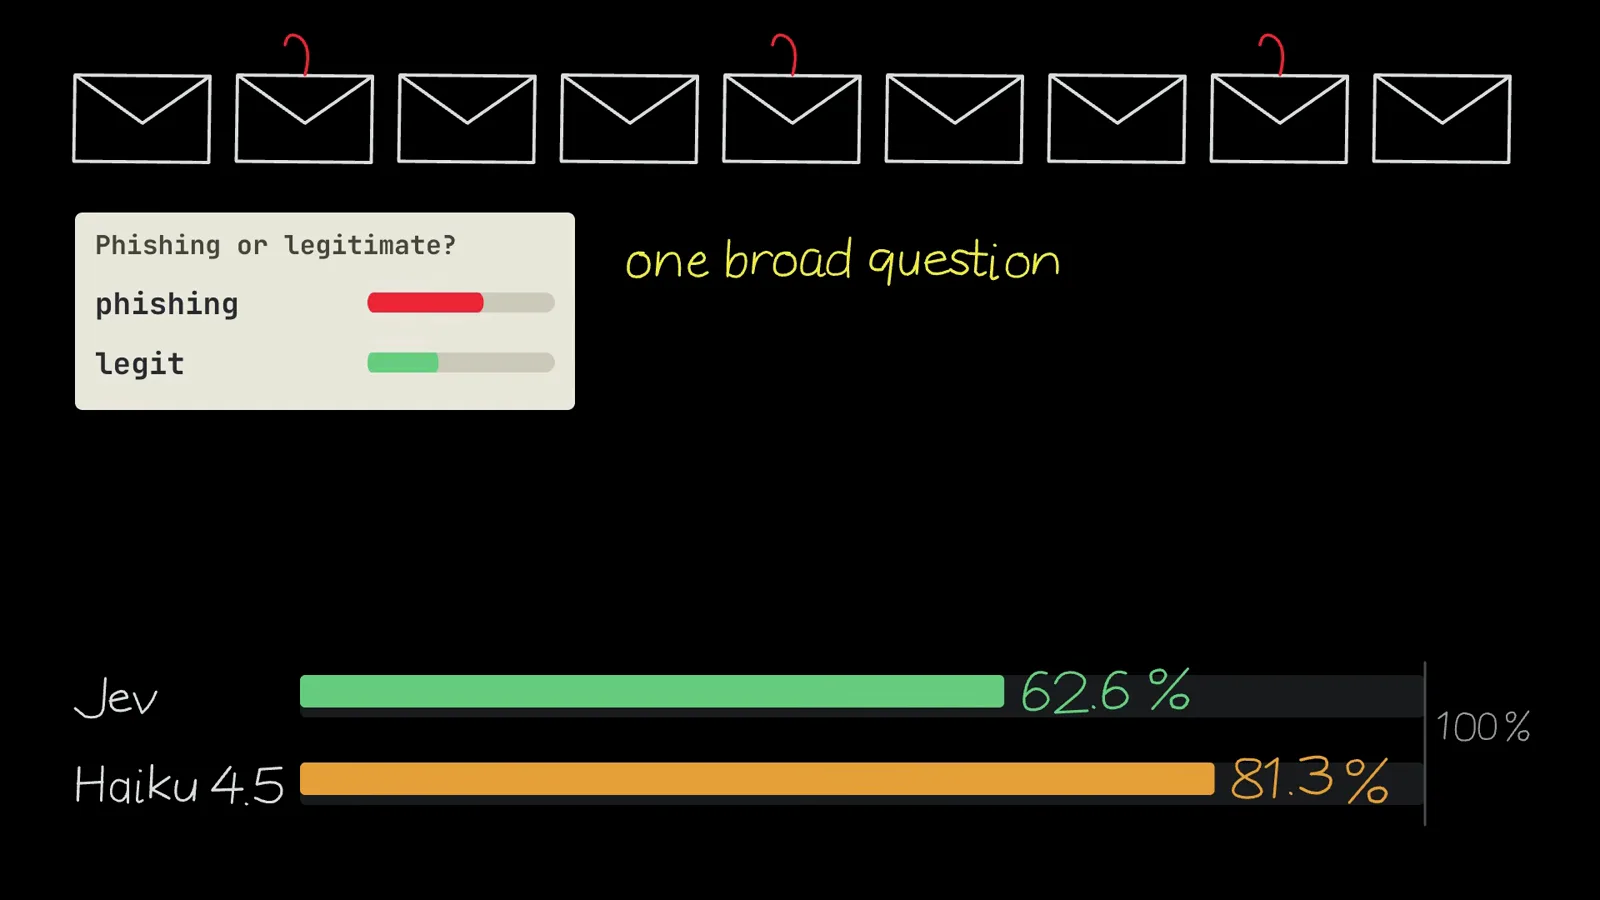
One broad question loses to Haiku; five narrow signals with tuned weights win.タイムスタンプ 11:10 を見る
よくある質問(FAQ)
What is a Jev agent harness?
A thin layer around your agent loop that turns Jev’s typed, probability-scored answers into routing, gating, and escalation decisions your code acts on. In the LangChain design it has two jobs: model routing (pick the cheap or powerful lane before the run starts) and auto mode (vet every tool call and block risky ones before execution). The LLM keeps generating; the harness owns the small decisions.
Won’t a Jev check on every tool call slow my agent down?
The opposite was the killer before Jev: LLM-based risk classification was slow enough that LangChain’s own PM had auto mode switched off in her coding agent. Jev decides in roughly 70–500 ms end to end (239 ms per decision in the independent email benchmark, and 0.114 s in TypeSafe’s Doom-state demo where GPT-5.6 Terra took 8.566 s), at a fraction of a cent per call — cheap enough to leave the guard on.
Jev “can’t hallucinate” — so can I trust it to gate destructive commands?
Treat the claim precisely: Jev cannot invent an answer outside the options you listed (a schema guarantee, not an accuracy result), but it can absolutely pick the wrong option — adversarial text in tool results can even nudge the verdict. Gate safely with three layers: narrow questions whose criteria you wrote down, confidence thresholds where ambiguity escalates instead of blocking blindly, and hardcoded rules that still stop irreversible commands like a root wipe. Jev is the smart first filter, not the only line of defense.
What limits should I know before wiring the harness?
Four from the sources: context is about 32k tokens for state plus your biggest question (roughly 64k with all questions combined — split beyond that); Jev reads the literal text you send and is unreliable at counting, arithmetic, and date comparisons, so keep the state minimal and relevant; official 40–200x speed and 40–400x cost claims shrink to roughly 3x and 12x in independent tests, so budget from the measured numbers; and centralize your questions and criteria in one auditable place — vibe-coded criteria scattered across files are the most common failure the TypeSafe team sees.
関連ガイド
LangChain + Jev Integration Guide
The package-level implementation of these two jobs: ModelRouter and AutoModeGuard middleware on create_agent, step by step.
読むWhen to Use Jev
The decision framework from the same channel: where Jev belongs in your stack, and where it does not.
読むAgent Routing Recipe
A concrete recipe for the routing half: a typed Choice plus threshold picks the model per task.
読むLLM Fallback Strategy
Confidence-based escalation patterns for the cases your gate is unsure about.
読むその他の動画ウォークスルー
- Jev Classification Quickstart: OpenRouter API, Primitives & Real Probabilities
- Jev Architecture Explained: Why 70ms Decision Models Beat LLMs for Workflow Automation
- Ultra-Fast Browser Agents with Jev: 178ms DOM Loops & Dual Model Orchestration
- Open Jev Models Are Here: Semif, Nimble, Decider, DiffusionGemma & Laya Hands-On
- Jev vs LLM: Will Jev Replace LLMs? Krish Naik's Whiteboard Explainer
- Jev Trader Tutorial: Build a Subsecond AI Trading Bot on Monad
- Jev Model Router: Build a Privacy-Gated LLM Router with Jev & OpenJev
- Jev Tutorial for Beginners: State, Questions & the TypeScript SDK
- Run Jev Locally: Kev, SemIf & Von on Your Own GPU (OpenJev Guide)
- Jev RAG Reranker: Policy-Steered Reranking for Retrieval-Augmented Generation
- When to Use Jev: An Engineer's Audit of Claims, Gates, and Failure Modes
- LangChain + Jev Integration Tutorial: Routing, Guardrails & Evals
- Jev MCP Server: Connect Jev Decisions to Claude Code & Cursor
- Jev vs Luna: Independent Benchmarks Put "Better, Faster, Cheaper" to the Test
- Jev Playground Walkthrough: The Hotdog Lesson, Criteria, and a Four-Console Token Test
- Jev Text Classification API: Zero-Shot CLI & REST with classifier.dev
- Jev API Examples: First Request, curl & All Three Question Types
- Expanso Edge と Jev でログをトリアージする
- Treg と Jev でリードをエンリッチする: ICP 判定と登録スコアリング
- Heym で Jev Decision Node を使う: モデルルーティングを制御する
- Laya Tutorial: Open-Source AI Routing With Calibrated Probabilities (Laya vs Jev Setup)
- Train Your Own Jev: Fine-Tune a Jev-Style Decision Model for $5–$17 (What You Can and Cannot Train)
- Jev Tips: 8 Best Practices for Better Decisions (State, Questions, Criteria & Thresholds)
- Jev Context Compaction: Prune AI Agent Memory Without Generative Summaries
- Jev as an LLM Judge: Confidence-Gated Cascades at 0.36% of the Cost
- TypeSafe Computer Use: Local Desktop Automation with Jev, Step by Step
- Jev Resume Screening: Build an AI Resume Evaluator with the Jev JavaScript SDK
- Jev + Claude Code Guide: Voice-Controlled Browser Automation with Typed Decisions
- Jev + Codex: Install the TypeSafe Skill and Triage a Real Gmail Inbox
- Jev vs Ollama: Can Local AI Replace Hosted Jev Without Sending Your Data Away?
- Build Your Own Jev: Train a Free Open-Source Zero-Shot Classifier (That Plays Doom)
- CUA-S1-Forms: a 706K-Parameter Jev-Like Model That Fills GUI Forms on Your CPU
- NOC/SOC Alert Triage with Jev: Rules First, One Typed Question, a Policy Gate
- Ollama Decision Models: Run tev1 and Nimble Locally (Tested on an 8 GB Card)
- Jev Guardrails in Production: A Five-Step Playbook for Decision Automation
- A Session Drift Guard for Pi Agent: Let the Jev Model Propose, Let Code Decide
- 50 Tev1 Use Cases: What a Local Decision Model Can Actually Do (Tested on an 8 GB Laptop)
- Jev, Hands-On: Where the Official Claims Meet Independent Remeasurement
- Jev Ticket Classification in a Real App: the After-Insert Hook and the Calculated Field
- OpenJev RLCD: Run the Open-Source Calibrated Decision Model Locally (Full Guide)
- Clef-Flash vs Jev: I Tested Cloudflare's Decision Model Locally in Ollama (Q4_K_M)
- Clef-Flash Tutorial: Install and Run Cloudflare's 9B Multimodal Decision Model Locally on Ubuntu
- CLM-8B: the Contrastive Decision Model That Scores 1,024 Options in 44 ms (13x Faster Than Jev)
- Nox 4B Tutorial: Run the Decision 2.0 Model Locally and Put It Through Four Real Decisions (One Ends in a Fail)
- Julia-1 Tutorial: Install the Open-Source Jev Replacement in Pure Python (and Watch It Beat If-Statements 9 to 2)
- OpenJev 0.8B on CPU: I Built a Ticket-Routing Inbox and Calibrated the Thresholds
- Jev n8n Integration: the JevGate Community Node, Step by Step (Plus a Plain-HTTP Fallback)
- NanoJev Tutorial: Install the 0.6B Open-Source Jev Replica and Watch It Route Decisions at 47 ms
- PPLX Decider Tutorial: Perplexity's Open 27B Decision Model, Its Decisions API, and a 12-Ticket Triage Run
- AutoTrust JEV-27B Tested Locally: Four Arms, 72 Cases, and One 0.969 Score That Was Wrong
- Clef 27B Locally: Watch Cloudflare’s Multimodal Decision Model Read an Image, a Video and an Uzbek Newspaper in One Pass
- Ollaya Guide: Install the "Ollama for Decision Models" Runner, Read Every Vendor-Reported Number, and Run the CPU Test It Leaves Open
- Strands Decider 2B Tutorial: Install the AWS Strands Decision Model on an 8GB Laptop — and Keep Its Failures In
- Liquid AI Open d1 Locally: d1-3B and d1-omni-600M on a MacBook Air M5 — Guardrails, Screen Checks, Voice Routing and Document Triage, Every Number Frame-Checked
- Image Decision Models for RPA: Watch Two Open Models Review an Unsigned W-8BEN With No OCR
- GLiNER2.5-Decide (340M) vs Jev (4B): Which Decision Model Actually Wins? A Frame-by-Frame Selection Guide
- Decision Models on Jetson: Jev vs Strands Decider 2B vs Laya vs d1-3B — Skill Master Scores, Thor Latency and JevBench, Every Number Frame-Checked
- Microsoft Decision-1 Tested: 146 Independent Tests, a 93% Mean, 124/125 When Confident — Every Number Frame-Checked
- Wire Jev into an Azure AI Foundry Agent as the Evaluation Layer — OpenAPI Tool, TypeSafe Connection, Triage Instructions and an Honest First-Run Failure