Guides / 動画ウォークスルー
Jev Architecture Explained: Why 70ms Decision Models Beat LLMs for Workflow Automation
最終更新日: 2026-10-24
Seven-minute breakdown of why autoregressive LLMs bottleneck workflow automation, how Jev parallel sampling delivers 70–500ms responses, and where specialized models sit on the Pareto frontier.
要点
Frontier LLMs excel at human chat and coding agents but impose sequential token generation that blocks sub-second workflow automation. Jev inverts the stack: structured state in, typed probabilistic decisions out—40–200× faster end-to-end (70–500ms) because parallel sampling replaces autoregressive generation. Think logic gates, not paragraphs.
ステップごとのウォークスルー
- 1
See how the AI application stack reshapes model design
From ChatGPT (2022) through coding agents (2025), models optimized for human assistance and verifiable coding rewards. Workflow automation—email sorting, RAG routing, game ticks, model routing—always felt possible in demos but collapsed under latency and cost at production scale. TypeSafe AI argues the bottleneck is architectural: forcing chat-optimized models into deterministic automation is the wrong abstraction.
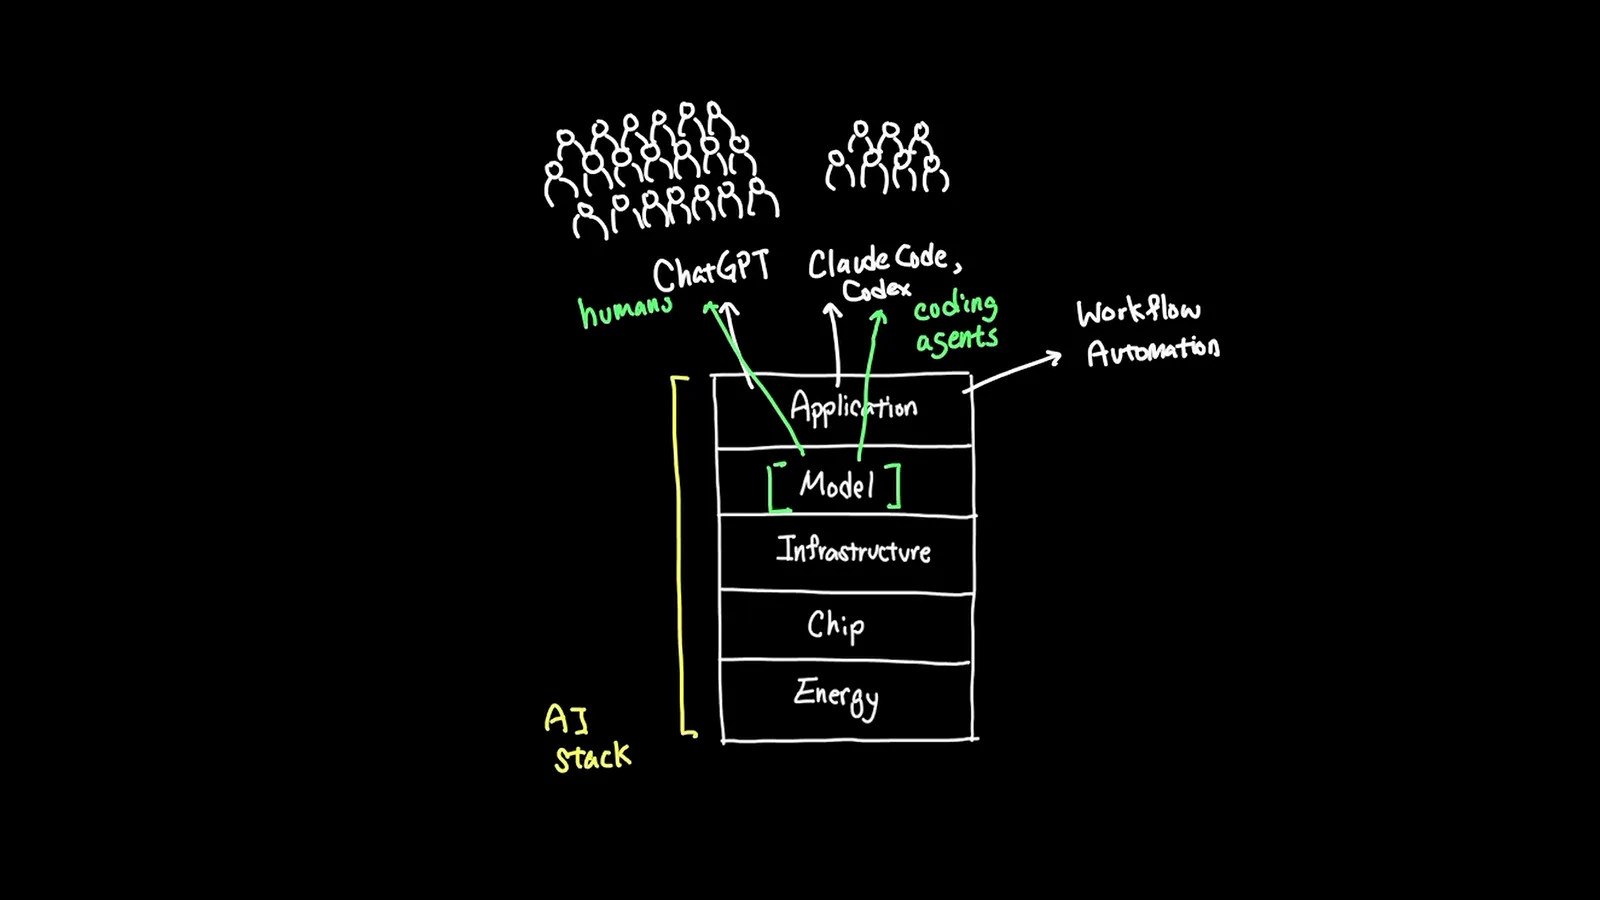
Application-layer demand for speed pulls the stack toward decision-native models.タイムスタンプ 0:45 を見る - 2
Compare autoregressive latency with Jev parallel sampling
LLMs can mimic Jev JSON outputs, but they generate tokens one after another until completion—impossible to match 70–500ms end-to-end at scale. Jev is built for parallel sampling and typed probabilistic decisions in a single pass. Community projects showcase speed first: inbox triage, RAG improvement, Doom at 10 queries/sec for ~$7/hour—tasks LLMs can do, but not at automation-grade cadence.
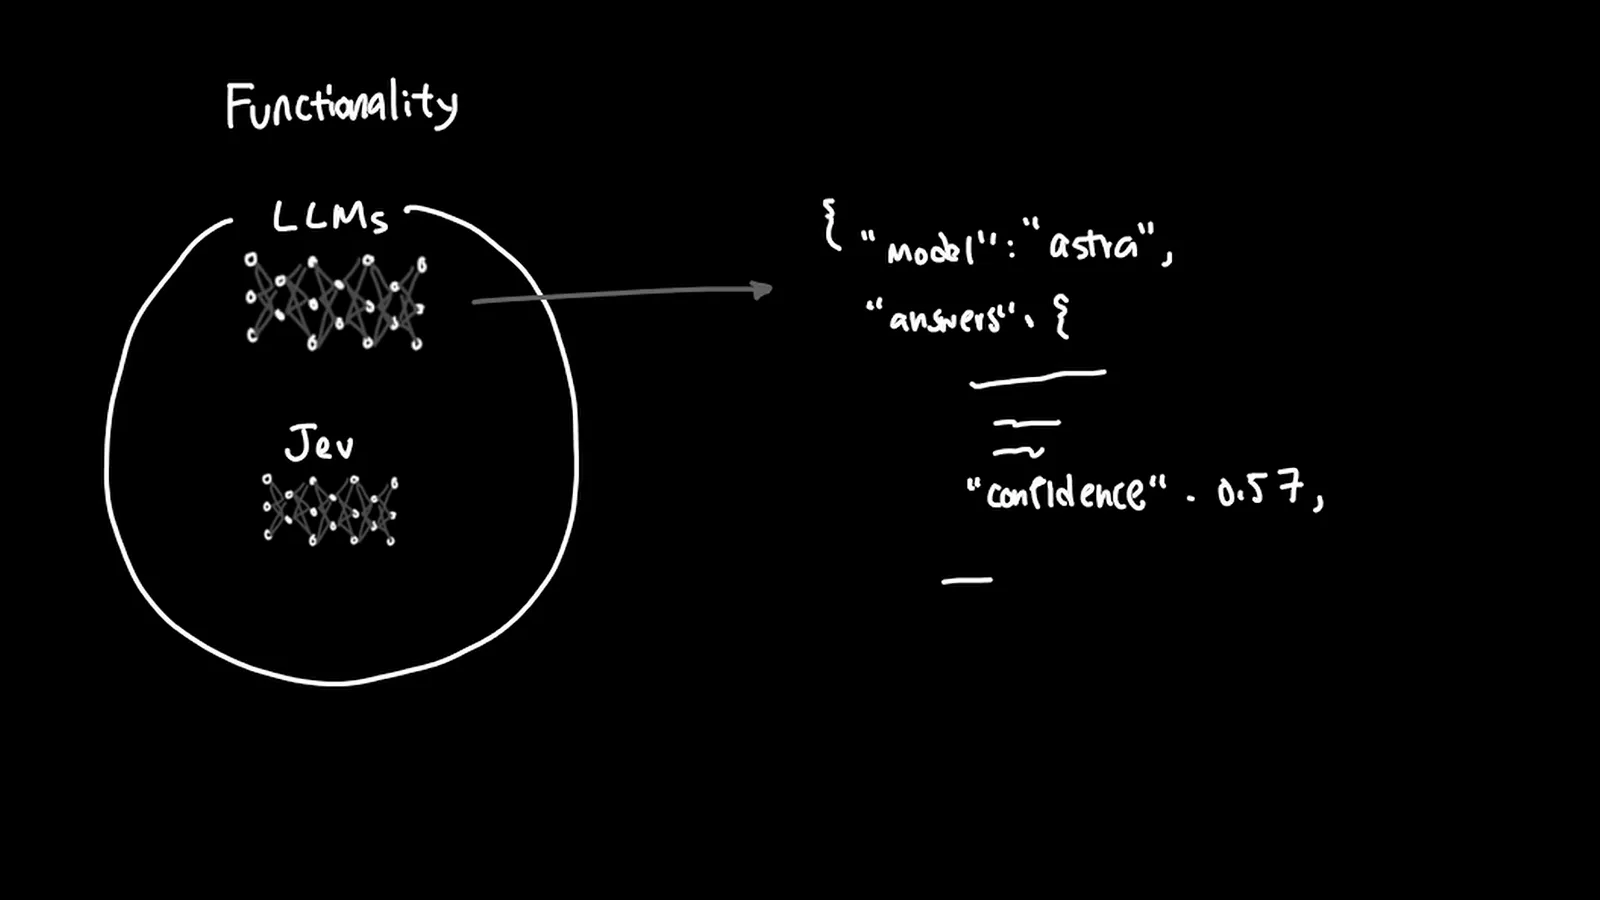
End-to-end 70–500ms vs multi-second autoregressive loops—the automation threshold.タイムスタンプ 2:20 を見る - 3
Treat Choice, Score, and Noul as software logic gates
Jev forbids raw-text Q&A. Inputs are structured state; outputs are probability distributions over your schema. Choice picks a category, Score orders on your scale, Noul returns P(yes). These three primitives compose like registers and logic gates—engineers stack abstractions above them rather than parsing free-form LLM replies. Sorting a long plant list through Claude Opus takes seconds; Jev finishes in one to two.
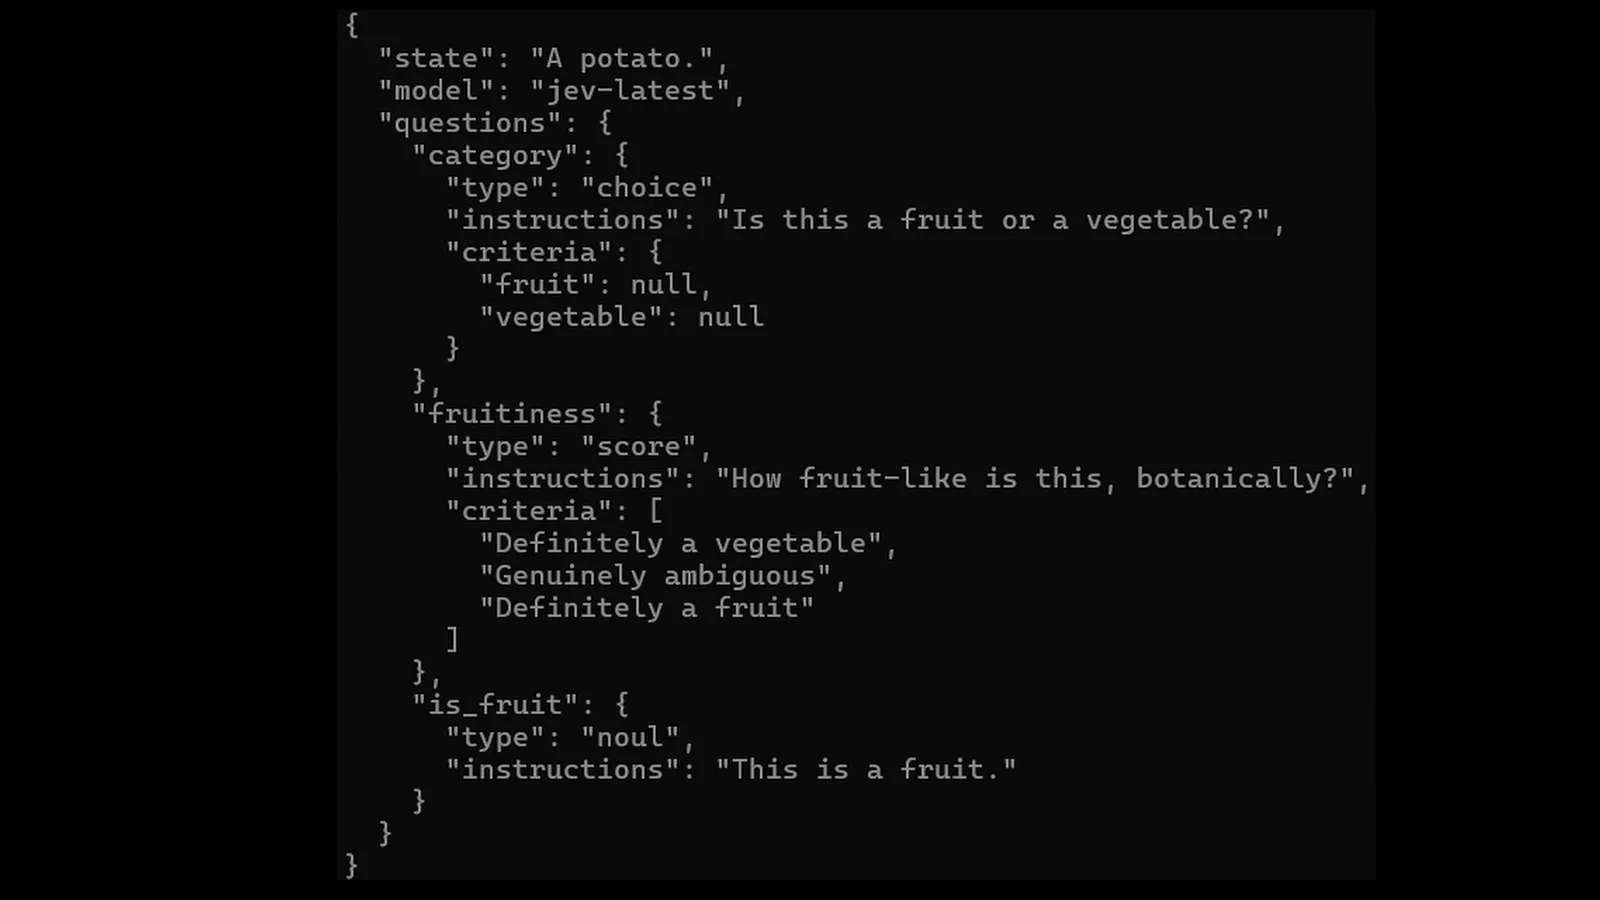
Three typed primitives replace fuzzy natural-language instructions.タイムスタンプ 4:30 を見る - 4
Locate Jev on the Pareto frontier of specialized models
On workflow-specific tasks, Jev competes with Flash/Nano tiers (GPT-5.6 Luna, DeepSeek v4 Flash, Sonnet 5) on speed and cost—not on open-ended reasoning. The vision is horizontal growth: frontier models for creative work, daily drivers for mundane chat, and decision models like Jev filling the automation quadrant. Narrow specialists existed before generative AI; Jev makes the category legible again.
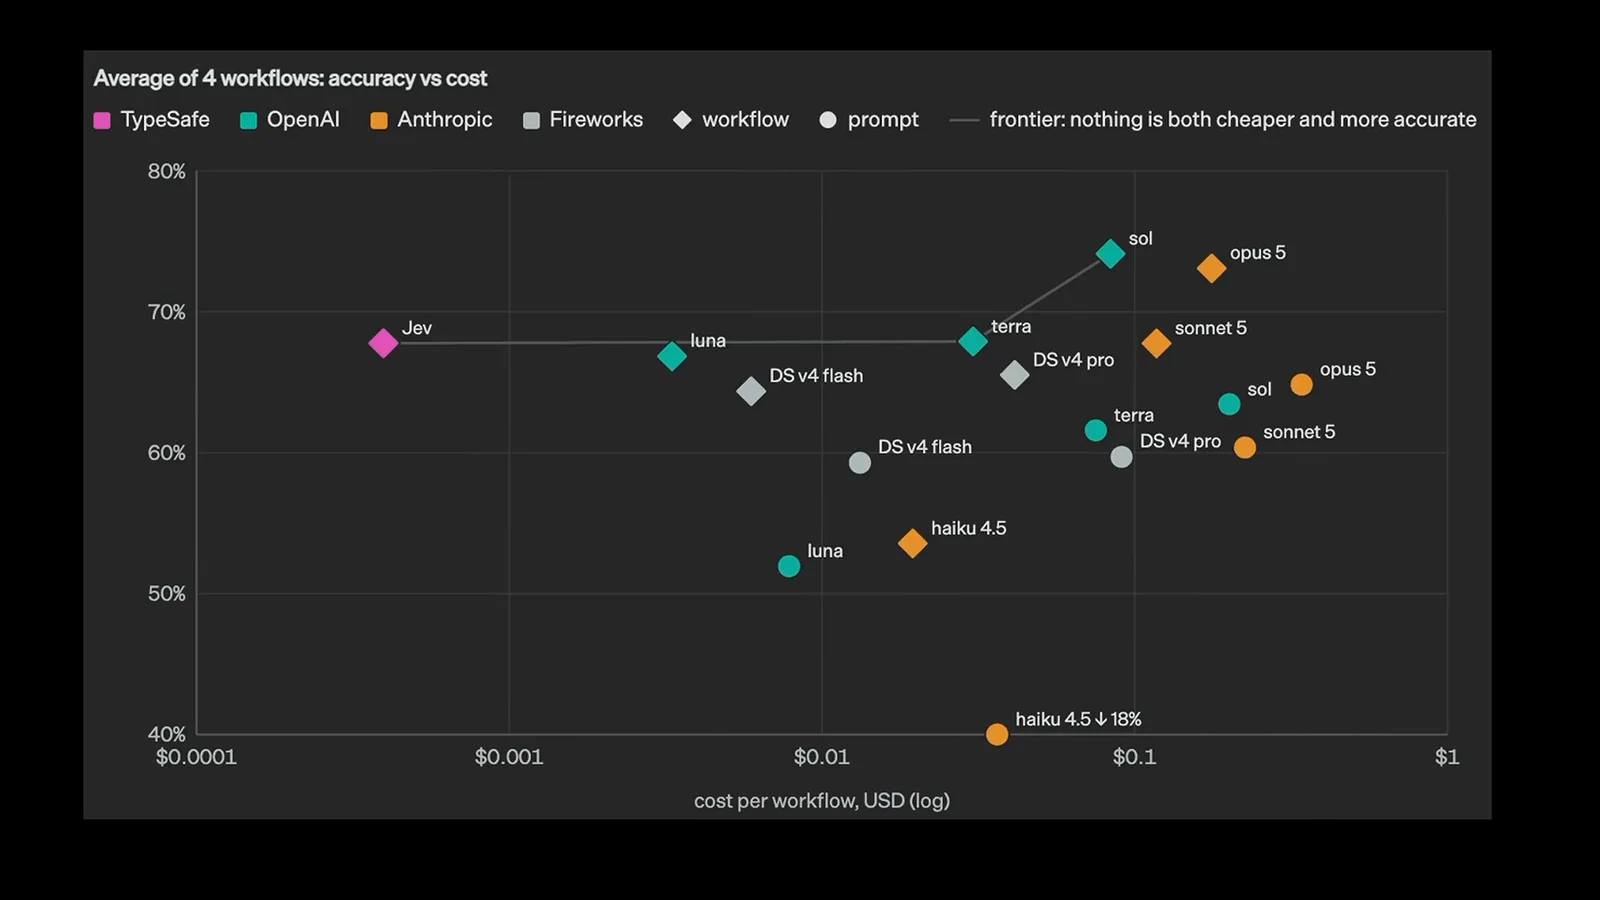
Specialized decision models occupy a distinct cost/latency niche on the frontier.タイムスタンプ 5:30 を見る
よくある質問(FAQ)
Can frontier LLMs replicate Jev outputs exactly?
Functionally yes—structured outputs and JSON mode can return similar labels. But matching Jev latency (70–500ms) and calibrated probabilities requires a different architecture (parallel sampling, RLCD training), not longer prompts on autoregressive models.
What is RLCD and why does it matter for automation?
Reinforcement Learning for Calibrated Decisions optimizes probability outputs against empirical outcomes instead of human-preferred chat tone. RLHF can make models sound confident while wrong; RLCD targets epistemic honesty so 90% confidence means ~90% accuracy in aggregate—safe for if/else automation.
Is Jev a smaller LLM or a new architecture?
TypeSafe AI has not published a full architecture paper. Likely a transformer using prefill-stage heads for classification/regression rather than sequential decoding—but the operational guarantee is schema-bounded outputs with parallel inference, not model size alone.
When should I still use a general LLM instead of Jev?
Open-ended generation, multi-step reasoning, code synthesis, and creative writing remain LLM territory. Use Jev when software needs a typed decision with confidence: routing, moderation gates, agent tool pick, game state classification, or any smart if-statement at scale.
関連ガイド
What is Jev?
Foundational overview of decision models vs generative chat tools.
読むJev vs LLM: When to Use Which
Complementary roles, hybrid decision-plus-generation architecture, and tool routing.
読むBrowser Agent Guide
178ms DOM loops, dual-model orchestration, and production guardrails.
読むその他の動画ウォークスルー
- Jev Classification Quickstart: OpenRouter API, Primitives & Real Probabilities
- Ultra-Fast Browser Agents with Jev: 178ms DOM Loops & Dual Model Orchestration
- Open Jev Models Are Here: Semif, Nimble, Decider, DiffusionGemma & Laya Hands-On
- Jev vs LLM: Will Jev Replace LLMs? Krish Naik's Whiteboard Explainer
- Jev Trader Tutorial: Build a Subsecond AI Trading Bot on Monad
- Jev Model Router: Build a Privacy-Gated LLM Router with Jev & OpenJev
- Jev Tutorial for Beginners: State, Questions & the TypeScript SDK
- Run Jev Locally: Kev, SemIf & Von on Your Own GPU (OpenJev Guide)
- Jev RAG Reranker: Policy-Steered Reranking for Retrieval-Augmented Generation
- When to Use Jev: An Engineer's Audit of Claims, Gates, and Failure Modes
- LangChain + Jev Integration Tutorial: Routing, Guardrails & Evals
- Jev MCP Server: Connect Jev Decisions to Claude Code & Cursor
- Jev vs Luna: Independent Benchmarks Put "Better, Faster, Cheaper" to the Test
- Jev Agent Harness: Where the Decision Gate Sits in Your LLM Loop
- Jev Playground Walkthrough: The Hotdog Lesson, Criteria, and a Four-Console Token Test
- Jev Text Classification API: Zero-Shot CLI & REST with classifier.dev
- Jev API Examples: First Request, curl & All Three Question Types
- Expanso Edge と Jev でログをトリアージする
- Treg と Jev でリードをエンリッチする: ICP 判定と登録スコアリング
- Heym で Jev Decision Node を使う: モデルルーティングを制御する
- Laya Tutorial: Open-Source AI Routing With Calibrated Probabilities (Laya vs Jev Setup)
- Train Your Own Jev: Fine-Tune a Jev-Style Decision Model for $5–$17 (What You Can and Cannot Train)
- Jev Tips: 8 Best Practices for Better Decisions (State, Questions, Criteria & Thresholds)
- Jev Context Compaction: Prune AI Agent Memory Without Generative Summaries
- Jev as an LLM Judge: Confidence-Gated Cascades at 0.36% of the Cost
- TypeSafe Computer Use: Local Desktop Automation with Jev, Step by Step
- Jev Resume Screening: Build an AI Resume Evaluator with the Jev JavaScript SDK
- Jev + Claude Code Guide: Voice-Controlled Browser Automation with Typed Decisions
- Jev + Codex: Install the TypeSafe Skill and Triage a Real Gmail Inbox
- Jev vs Ollama: Can Local AI Replace Hosted Jev Without Sending Your Data Away?
- Build Your Own Jev: Train a Free Open-Source Zero-Shot Classifier (That Plays Doom)
- CUA-S1-Forms: a 706K-Parameter Jev-Like Model That Fills GUI Forms on Your CPU
- NOC/SOC Alert Triage with Jev: Rules First, One Typed Question, a Policy Gate
- Ollama Decision Models: Run tev1 and Nimble Locally (Tested on an 8 GB Card)
- Jev Guardrails in Production: A Five-Step Playbook for Decision Automation
- A Session Drift Guard for Pi Agent: Let the Jev Model Propose, Let Code Decide
- 50 Tev1 Use Cases: What a Local Decision Model Can Actually Do (Tested on an 8 GB Laptop)
- Jev, Hands-On: Where the Official Claims Meet Independent Remeasurement
- Jev Ticket Classification in a Real App: the After-Insert Hook and the Calculated Field
- OpenJev RLCD: Run the Open-Source Calibrated Decision Model Locally (Full Guide)
- Clef-Flash vs Jev: I Tested Cloudflare's Decision Model Locally in Ollama (Q4_K_M)
- Clef-Flash Tutorial: Install and Run Cloudflare's 9B Multimodal Decision Model Locally on Ubuntu
- CLM-8B: the Contrastive Decision Model That Scores 1,024 Options in 44 ms (13x Faster Than Jev)
- Nox 4B Tutorial: Run the Decision 2.0 Model Locally and Put It Through Four Real Decisions (One Ends in a Fail)
- Julia-1 Tutorial: Install the Open-Source Jev Replacement in Pure Python (and Watch It Beat If-Statements 9 to 2)
- OpenJev 0.8B on CPU: I Built a Ticket-Routing Inbox and Calibrated the Thresholds
- Jev n8n Integration: the JevGate Community Node, Step by Step (Plus a Plain-HTTP Fallback)
- NanoJev Tutorial: Install the 0.6B Open-Source Jev Replica and Watch It Route Decisions at 47 ms
- PPLX Decider Tutorial: Perplexity's Open 27B Decision Model, Its Decisions API, and a 12-Ticket Triage Run
- AutoTrust JEV-27B Tested Locally: Four Arms, 72 Cases, and One 0.969 Score That Was Wrong
- Clef 27B Locally: Watch Cloudflare’s Multimodal Decision Model Read an Image, a Video and an Uzbek Newspaper in One Pass
- Ollaya Guide: Install the "Ollama for Decision Models" Runner, Read Every Vendor-Reported Number, and Run the CPU Test It Leaves Open
- Strands Decider 2B Tutorial: Install the AWS Strands Decision Model on an 8GB Laptop — and Keep Its Failures In
- Liquid AI Open d1 Locally: d1-3B and d1-omni-600M on a MacBook Air M5 — Guardrails, Screen Checks, Voice Routing and Document Triage, Every Number Frame-Checked
- Image Decision Models for RPA: Watch Two Open Models Review an Unsigned W-8BEN With No OCR
- GLiNER2.5-Decide (340M) vs Jev (4B): Which Decision Model Actually Wins? A Frame-by-Frame Selection Guide
- Decision Models on Jetson: Jev vs Strands Decider 2B vs Laya vs d1-3B — Skill Master Scores, Thor Latency and JevBench, Every Number Frame-Checked
- Microsoft Decision-1 Tested: 146 Independent Tests, a 93% Mean, 124/125 When Confident — Every Number Frame-Checked
- Wire Jev into an Azure AI Foundry Agent as the Evaluation Layer — OpenAPI Tool, TypeSafe Connection, Triage Instructions and an Honest First-Run Failure