Guides / 動画ウォークスルー
When to Use Jev: An Engineer's Audit of Claims, Gates, and Failure Modes
最終更新日: 2026-10-05
The Stack audits Jev for engineering teams: verifying the 193x/444x vendor claims, the allow/ask-a-human/block command gate, calibration curves, six failure modes, and a shadow-mode path to production.
要点
Jev is a decision engine, not a chatbot: your code sends text plus a question whose answers are fixed in advance — a Choice from a list, a binary Noul, or a numeric Score — and gets a typed answer with a probability back in as little as 0.114 seconds. The video stress-tests the marketing: the headline 193.6x faster / 444.6x cheaper figures come from TypeSafe's own West-Coast-laptop evals, while an independent 2,000-email benchmark measured 239ms vs 687ms against Claude Haiku 4.5 (about 3x faster, not 200x) and roughly 4 vs 46 cents per 1,000 emails (about 12x cheaper). The zero-hallucination claim is a schema guarantee, not an accuracy promise: on a broad phishing question Jev scored 62.6% correct versus Haiku's 81.3%, but split into five narrow signals and weighted on 1,000 labeled emails it reached about 95% versus 93%. The safe adoption path is shadow mode first, confidence thresholds second, hardcoded rules always.
ステップごとのウォークスルー
- 1
Start with the gate: allow, ask a human, or block
The recurring example is a scheduling agent that wants to run rm -rf ./project. Rules in code cannot tell safe cleanup from disaster, and a chat model asked for a one-word verdict may return three paragraphs explaining its feelings. Jev removes the chat box: your code sends the command text plus a question whose answers are locked in advance — allow, ask a human, or block — and gets back one of those exact options with a probability score, so an ordinary if statement can act immediately. In the LangChain agent harness published two days after launch, this pattern is Jev's second job: reviewing every tool call an autonomous agent attempts and stopping risky ones before execution. Type-safe's own Doom demo ran on the same trick — a move chosen in 0.114 seconds versus 8.566 seconds for GPT-5.6 Terra.
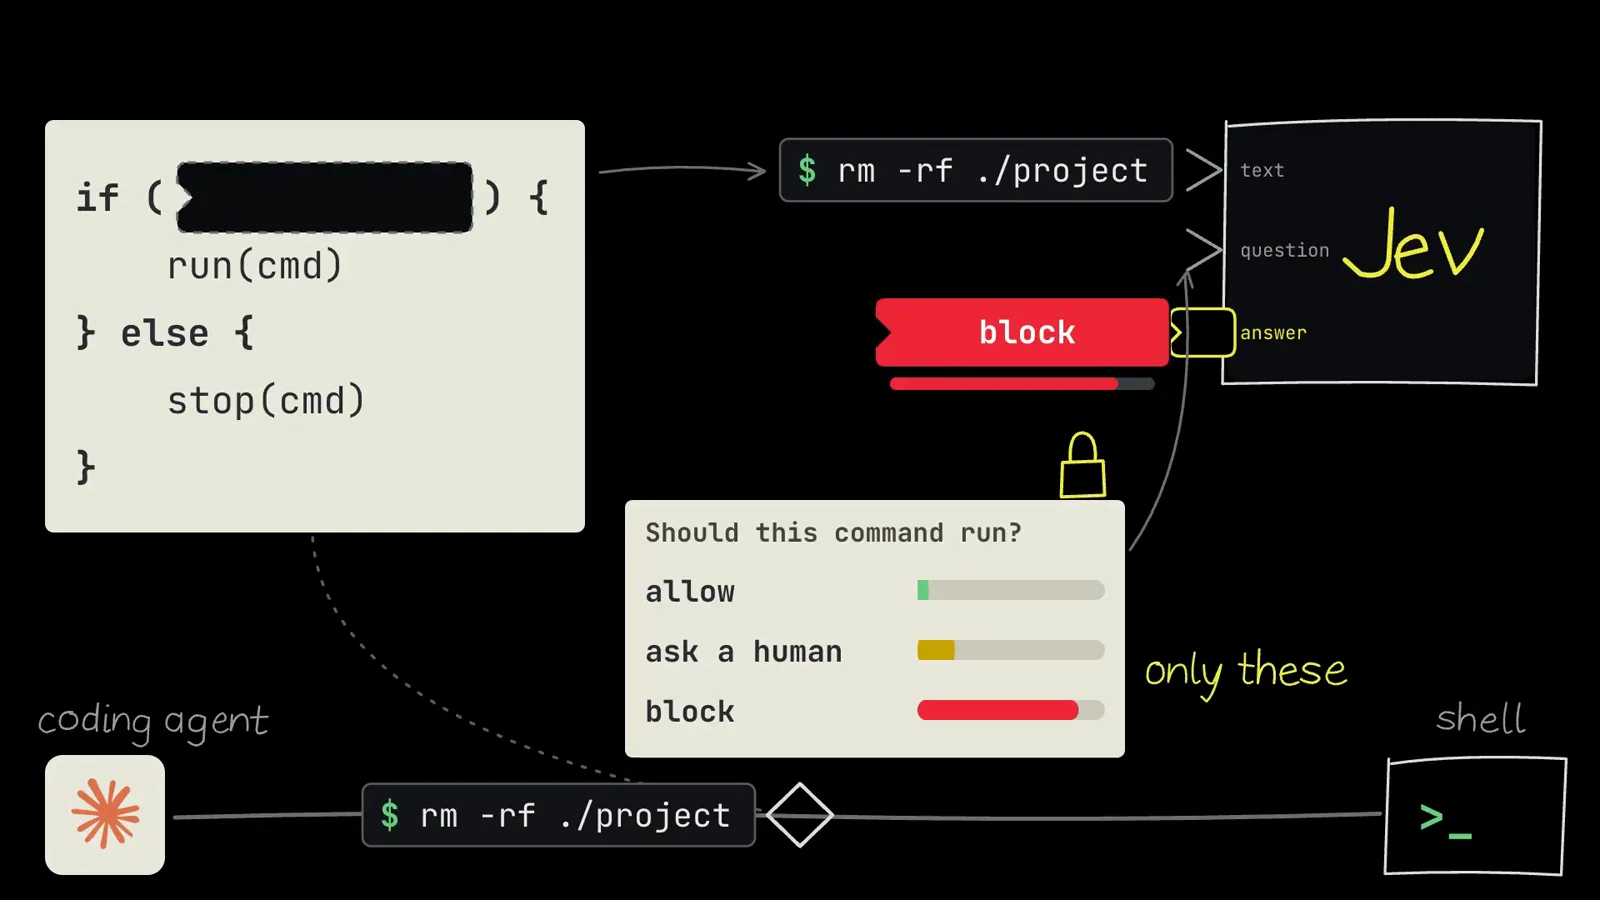
The gate: one rm -rf command, three allowed answers.タイムスタンプ 2:28 を見る - 2
Three question types: Choice, Noul, and Score
Every question you write falls into one of three categories. A Choice selects one option from your fixed list — allow, ask a human, block — and returns probabilities for all of them. A Noul, a strangely named binary check, asks a yes-or-no question and returns a single probability between zero and one, like is this destructive. A Score rates the input along a numerical scale you define, such as how risky is this command from 1 to 5. Note what never happens anywhere in the cycle: Jev never writes a word of explanation. Standard models pay for token-by-token generation like a painfully slow typist charging per syllable; Jev skips generation entirely and evaluates all responses in parallel in a single pass. As developer Flavio Copes put it, it works like a smart if statement built into your software — a decision engine called by code, not a conversationalist.
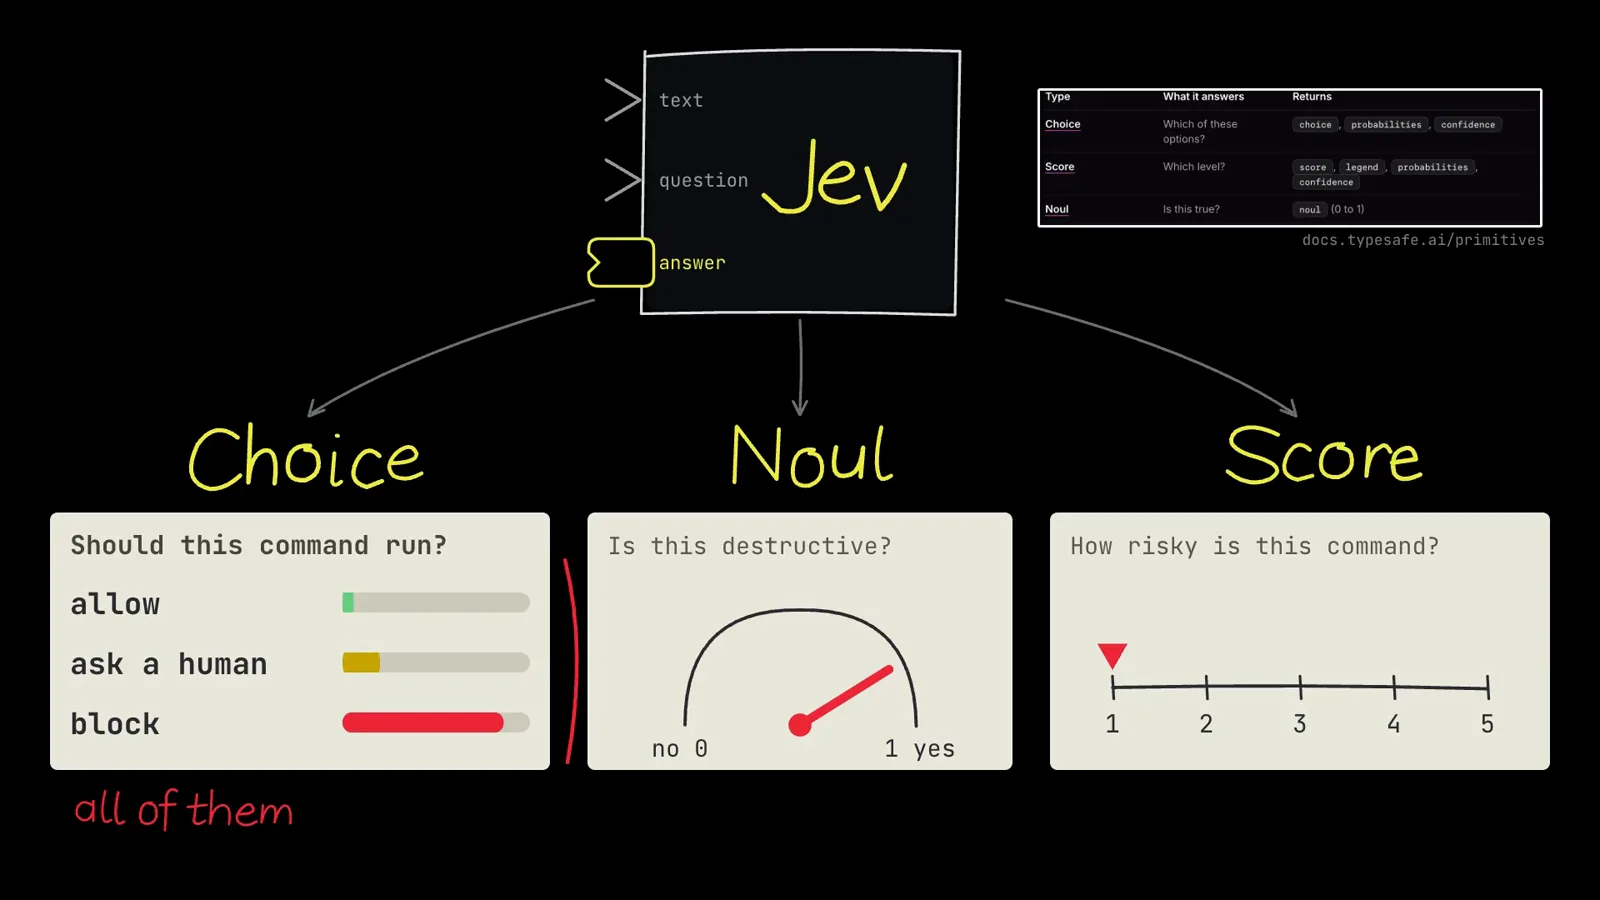
Choice picks from a list, Noul answers yes/no, Score rates 1-5.タイムスタンプ 3:08 を見る - 3
Audit the 193x and 444x claims before you believe them
On paper Jev lists at 4.2 cents per million input tokens with replies free — a reseller listing puts it near 5.8 cents — and TypeSafe quotes end-to-end responses of 70ms-500ms, claiming 40x-200x speedups with peaks of 193.6x faster and 444.6x cheaper. Read the footnotes. TypeSafe's launch notes admit it cannot prove the service is not subsidized, that its speed tests ran from the team's West Coast laptops, and that its evals were written by its own researchers, so local bias exists. When an independent developer in France benchmarked Jev against Claude Haiku 4.5 on 2,000 emails, Jev took 239 milliseconds per decision versus 687 — about three times faster, not 200 — and cost roughly 4 cents per 1,000 emails versus 46, about 12 times cheaper. A mixed DSPy pipeline that moved only its yes/no and pick-one steps to Jev gained 16% speed and 30% cost.
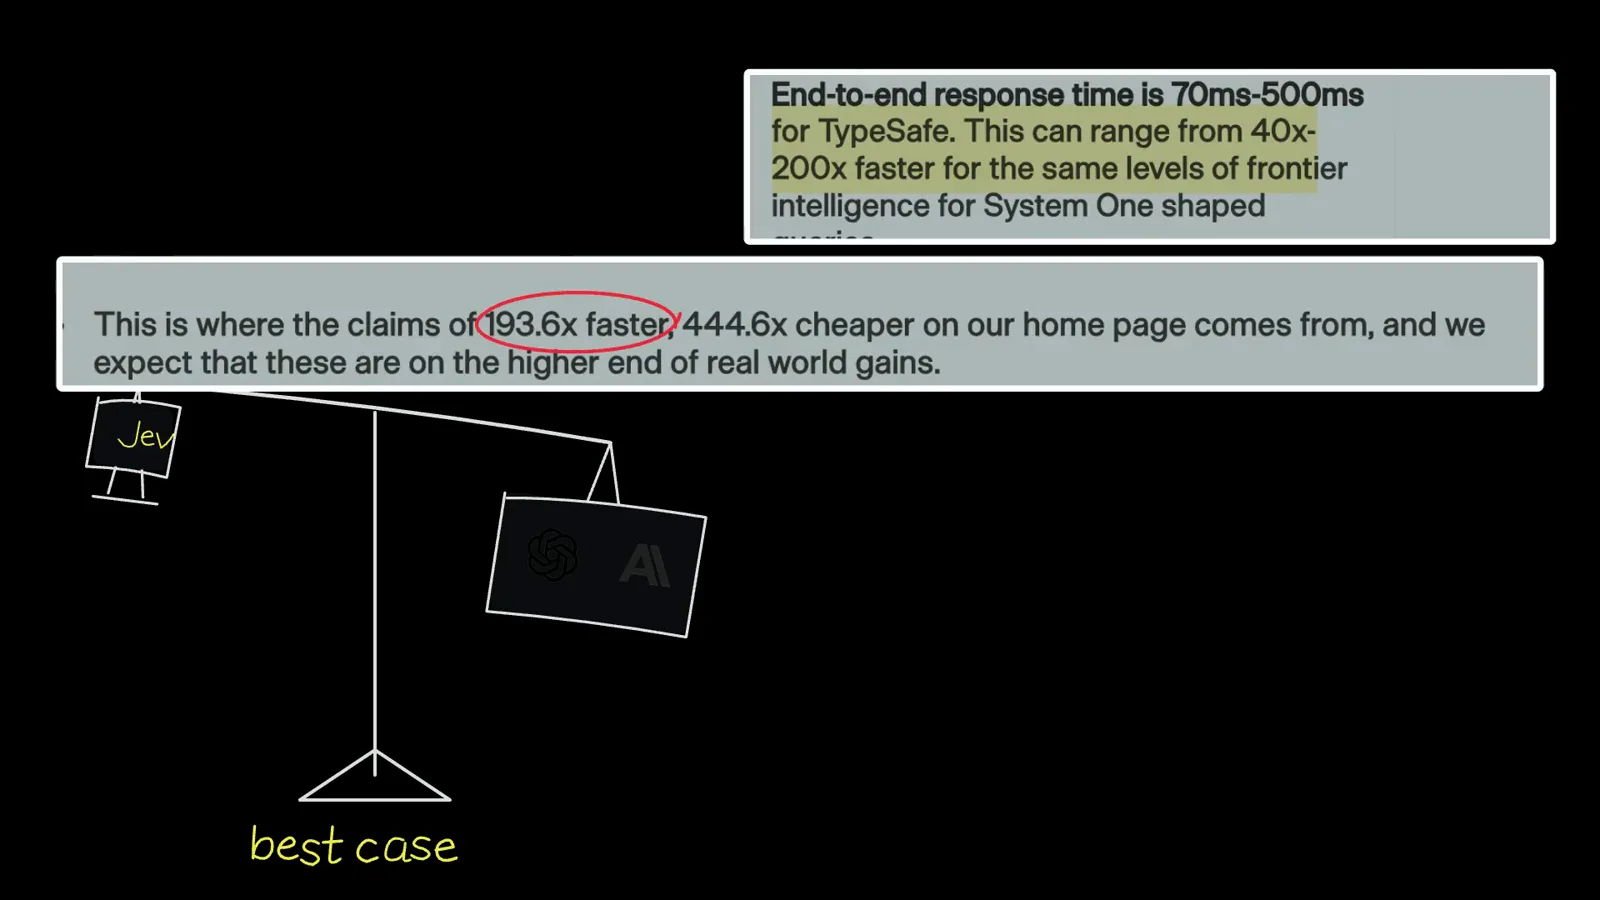
Even TypeSafe files 193.6x and 444.6x under best case.タイムスタンプ 7:52 を見る - 4
Narrow checks and a weighted sum beat one broad prompt
The same independent benchmark exposed the accuracy gap. Asked one broad question — is this email phishing or legitimate — Jev was correct 62.6% of the time while Claude Haiku 4.5 hit 81.3% on the identical prompt, so a cheap general chat model easily won the unassisted decision. Jev caught up when the developer stopped treating it like an oracle and split the problem into five narrow technical signals — sender domain versus claimed brand, artificial urgency, and similar markers shown as sig_ gauges — then fit weights on 1,000 labeled training emails and combined the signals with a weighted sum. Combined accuracy jumped to about 95%, with Haiku at about 93% using the same approach: a technical tie. The lesson is that Jev excels on narrow, well-defined checks, but 95% required labeled examples and a scoring setup you build and maintain yourself.
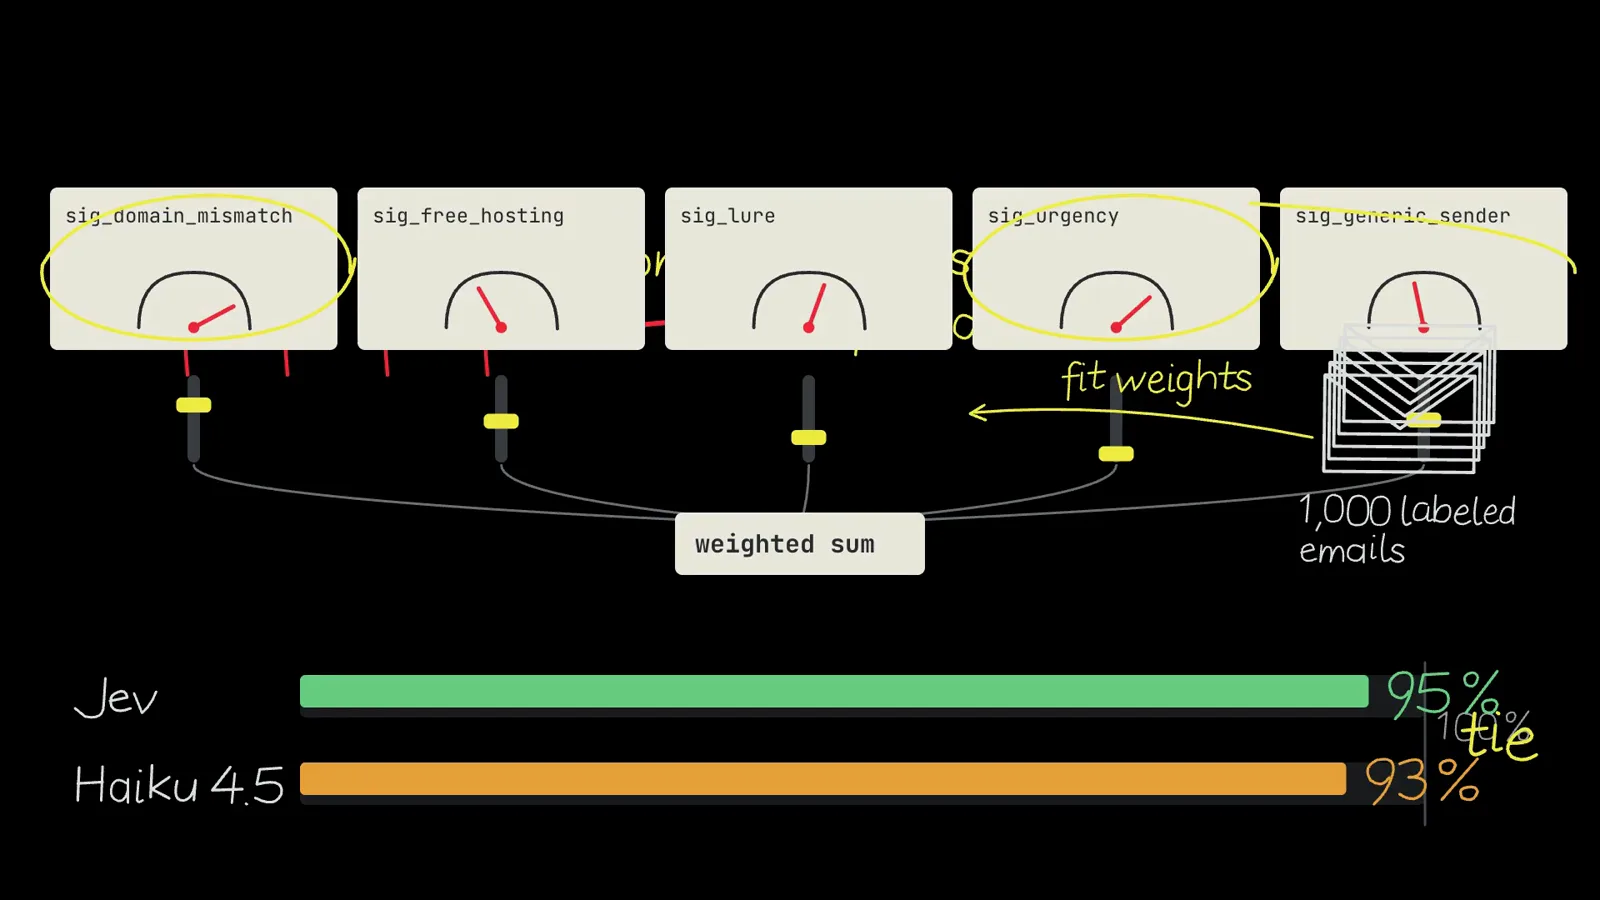
Five narrow signals plus a weighted sum lift Jev to 95%.タイムスタンプ 11:48 を見る - 5
Calibration and the six documented failure modes
The zero-hallucination promise is narrower than it sounds: Jev physically cannot emit text outside your fixed answer list — 2,000 independent calls produced zero malformed responses — but it can absolutely pick the wrong option, and schema-valid is not the same as correct. TypeSafe calibrates Jev so a 90%-confidence answer should be right nine times in ten, yet in independent email testing Haiku's confidence tracked reality more closely: ECE 0.097 versus Jev's 0.134 on the video's calibration chart. The official benchmarks also measure agreement with frontier models like GPT-6 Astra and Fable 5.1 rather than verified truth. The Jev 1.13 documentation lists six failure modes: literal reading, math and numbers, date and time comparison, indirection, large states full of irrelevant detail, and adversarial content — a file arguing that deleting the folder is safe can nudge the gate toward allow.
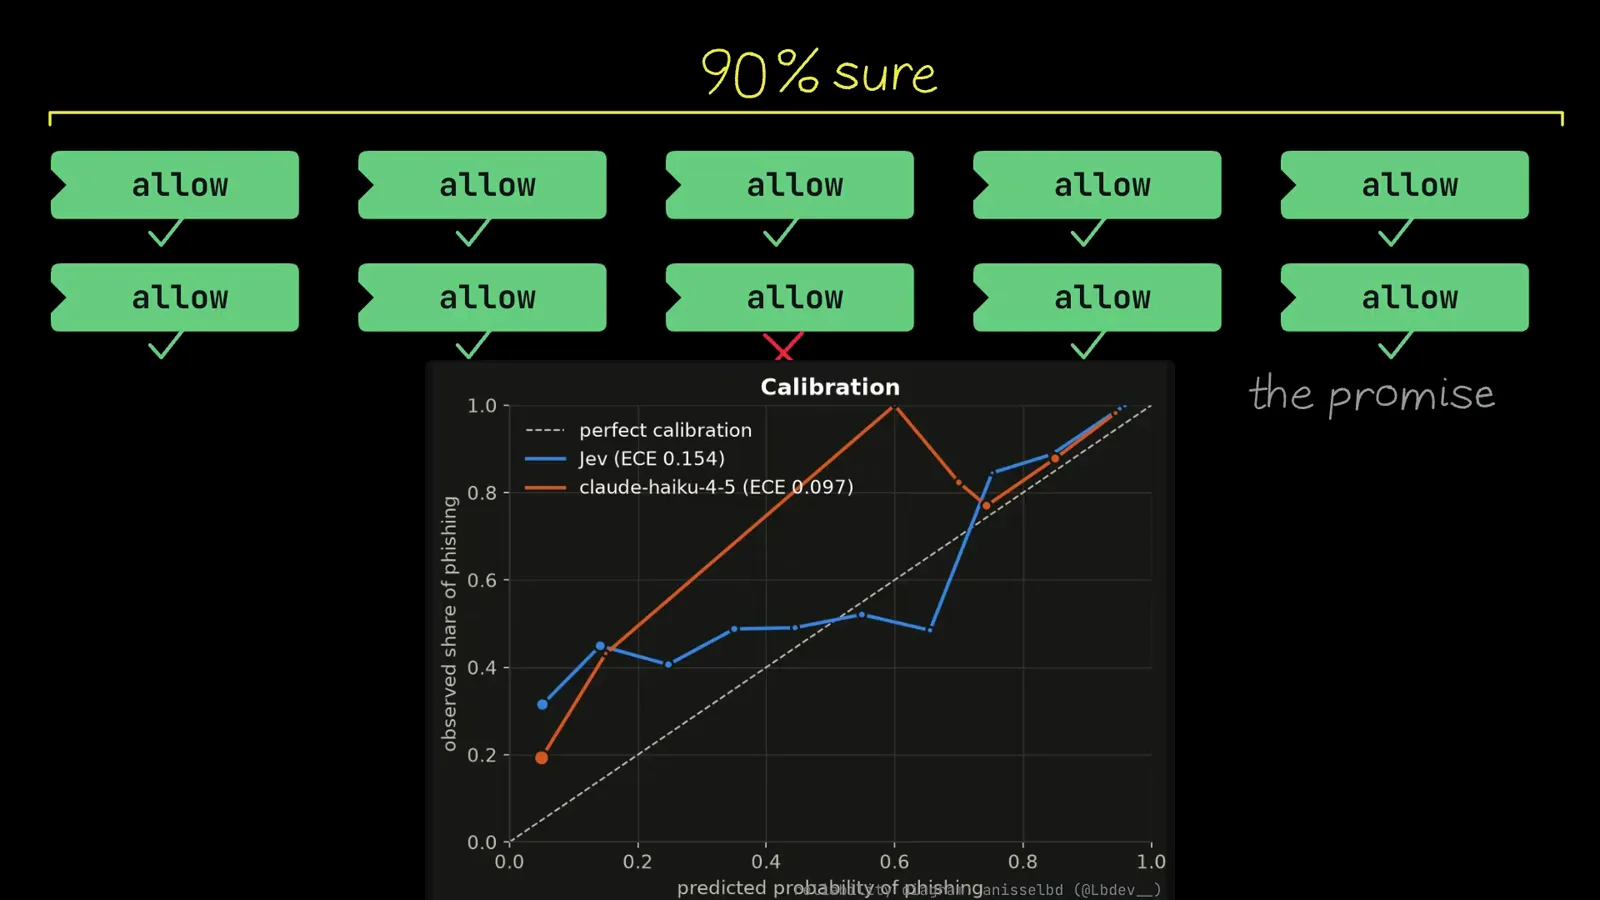
On confidence, Haiku 4.5 tracks reality more closely than Jev.タイムスタンプ 12:08 を見る - 6
Roll out in shadow mode, then gate on confidence
The safe adoption path starts with shadow mode: run Jev beside your current workflow, let it quietly evaluate real traffic on decisions where you already know the absolute truth, and compare answers before handing over control. Then use the reported confidence scores to set thresholds — high-confidence answers pass straight through, borderline cases escalate to a person or a more powerful model, and destructive actions stay denied by strict rules in your own code. In the recurring example, Jev instantly authorizes common read commands like cat notes.md, folder deletions route to manual approval, and a full root wipe is blocked by hardcoded shell checks regardless of what Jev says. Keep questions specific, remember Jev is still in early access under a waitlist with only days of public data, and treat it as a decision maker, not a code writer — test before trusting it with anything mission-critical.
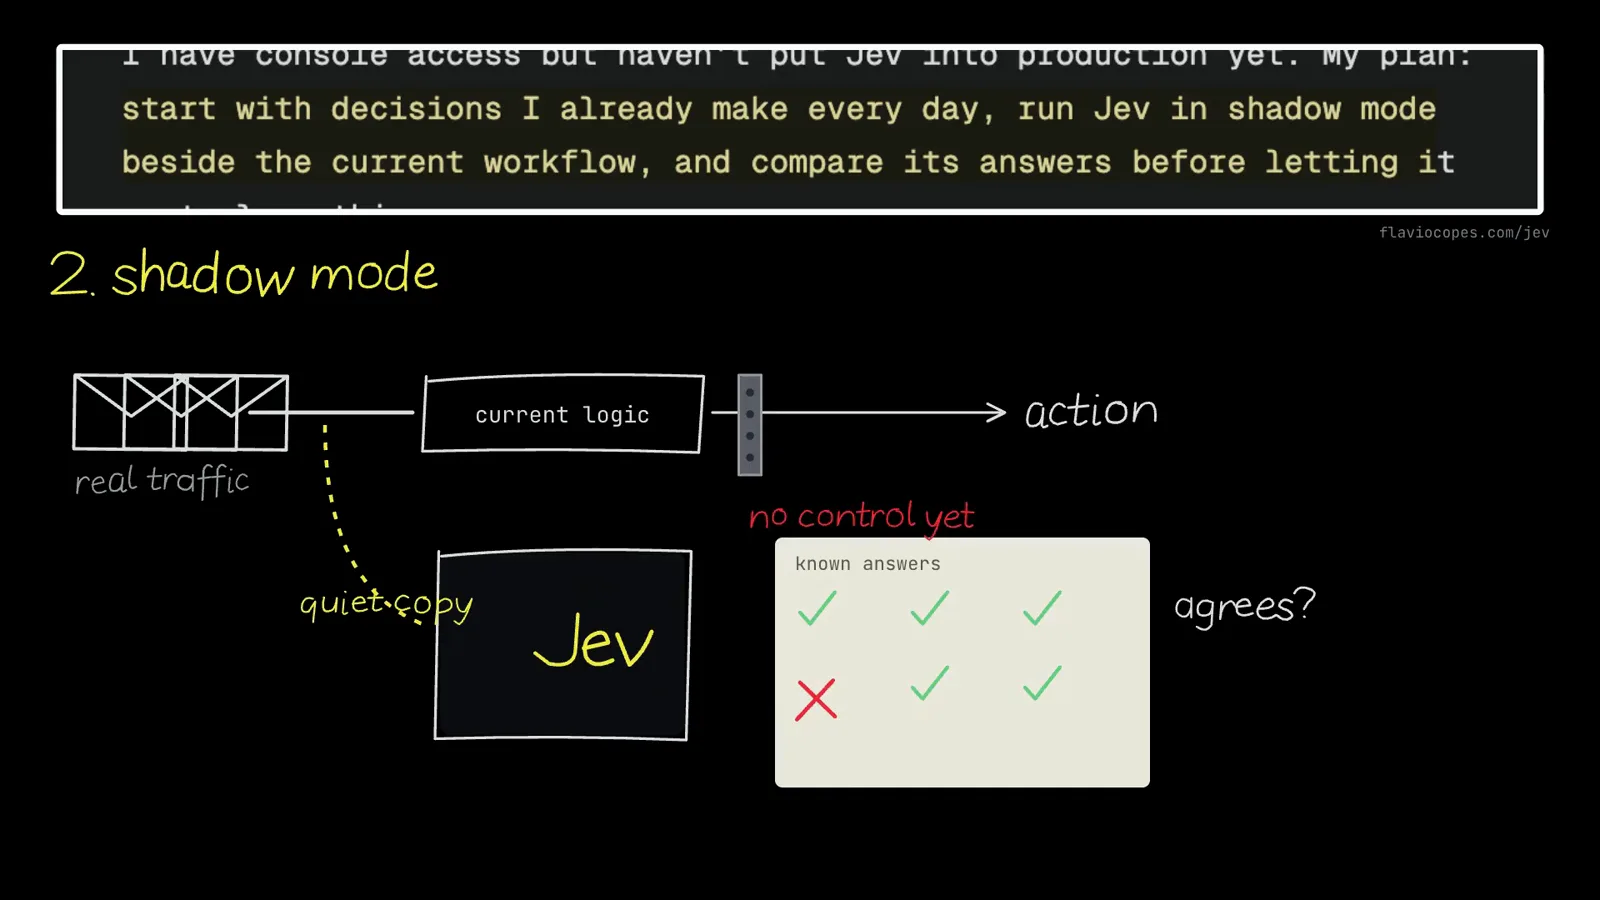
Shadow mode first: let Jev listen beside the workflow before it acts.タイムスタンプ 14:53 を見る
よくある質問(FAQ)
When should you actually use Jev?
When your software constantly makes small, repetitive decisions where every possible response is predetermined: classifying support tickets, categorizing exceptions, routing requests to the right model tier, or screening every tool call an AI agent attempts. It is the wrong tool for chatting with customers, writing text or code, arithmetic, counting, and date comparisons — and it should never be the sole security control, only a smart first filter alongside strict rules in your own code.
Is Jev really 193x faster and 444x cheaper than big models?
Those are TypeSafe best-case numbers from its own evals, run on the team's West Coast laptops with tests its own researchers wrote. Independent testing against Claude Haiku 4.5 on 2,000 emails measured 239ms per decision versus 687ms — about 3x faster — and about 4 versus 46 cents per 1,000 emails, roughly 12x cheaper. A mixed DSPy pipeline that only moved its binary and choice steps to Jev became 16% faster and 30% cheaper.
Can Jev hallucinate?
Not in the schema sense: it physically lacks the mechanism to produce text outside your fixed answer list, and 2,000 independent calls returned zero malformed responses. But schema-valid is not correct — on a broad phishing-or-legitimate question Jev was right 62.6% of the time versus Haiku 4.5's 81.3%. Split into five narrow signals with weights fit on 1,000 labeled emails, Jev reached about 95% and Haiku about 93%.
What are Jev’s documented failure modes?
The TypeSafe documentation for Jev 1.13 lists six: literal reading (it evaluates the text you sent, not what you meant), math and numbers (counting and arithmetic are unreliable), date and time comparison, indirection, large states full of irrelevant detail, and adversarial content — persuasive text inside an evaluated file, such as an argument that deleting a folder is safe, can push the decision toward allow.
How do you roll Jev out safely in production?
Run it in shadow mode first: let it evaluate real traffic beside your current stack on decisions where you already know the truth, and measure agreement before giving it control. Then set thresholds on its confidence scores — high-confidence answers flow straight through, borderline cases escalate to a human or a bigger model — and keep hardcoded rules for destructive actions so a root wipe is blocked no matter what any model says.
関連ガイド
Jev Guardrails: The Five-Step Production Playbook
You have decided where Jev fits — this is how to wire it in safely: thresholds, REST constraints, and human review from day one.
読むJev vs LLM Guide
A deeper head-to-head on where a decision engine beats a chat model — and where it never will.
読むLLM Fallback Strategy
Confidence-gated fallbacks are exactly how low-risk Jev answers pass and doubtful ones escalate.
読むJev Benchmarks
Independent latency, cost, and accuracy numbers to compare against vendor best-case claims.
読むTrain Your Own Jev
The build-it-yourself exit: fine-tune a Jev-style decision model when hosted volume pricing does not fit.
読むWhat Is Jev?
The input-only pricing and parallel evaluation that make fractions-of-a-cent decisions possible.
読むCalibration deep-dive: ECE, thresholds and the confidence debate
The page that expands this video’s calibration-curve segment into a full ECE workflow with the Synthpop audit numbers.
読むその他の動画ウォークスルー
- Jev Classification Quickstart: OpenRouter API, Primitives & Real Probabilities
- Jev Architecture Explained: Why 70ms Decision Models Beat LLMs for Workflow Automation
- Ultra-Fast Browser Agents with Jev: 178ms DOM Loops & Dual Model Orchestration
- Open Jev Models Are Here: Semif, Nimble, Decider, DiffusionGemma & Laya Hands-On
- Jev vs LLM: Will Jev Replace LLMs? Krish Naik's Whiteboard Explainer
- Jev Trader Tutorial: Build a Subsecond AI Trading Bot on Monad
- Jev Model Router: Build a Privacy-Gated LLM Router with Jev & OpenJev
- Jev Tutorial for Beginners: State, Questions & the TypeScript SDK
- Run Jev Locally: Kev, SemIf & Von on Your Own GPU (OpenJev Guide)
- Jev RAG Reranker: Policy-Steered Reranking for Retrieval-Augmented Generation
- LangChain + Jev Integration Tutorial: Routing, Guardrails & Evals
- Jev MCP Server: Connect Jev Decisions to Claude Code & Cursor
- Jev vs Luna: Independent Benchmarks Put "Better, Faster, Cheaper" to the Test
- Jev Agent Harness: Where the Decision Gate Sits in Your LLM Loop
- Jev Playground Walkthrough: The Hotdog Lesson, Criteria, and a Four-Console Token Test
- Jev Text Classification API: Zero-Shot CLI & REST with classifier.dev
- Jev API Examples: First Request, curl & All Three Question Types
- Expanso Edge と Jev でログをトリアージする
- Treg と Jev でリードをエンリッチする: ICP 判定と登録スコアリング
- Heym で Jev Decision Node を使う: モデルルーティングを制御する
- Laya Tutorial: Open-Source AI Routing With Calibrated Probabilities (Laya vs Jev Setup)
- Train Your Own Jev: Fine-Tune a Jev-Style Decision Model for $5–$17 (What You Can and Cannot Train)
- Jev Tips: 8 Best Practices for Better Decisions (State, Questions, Criteria & Thresholds)
- Jev Context Compaction: Prune AI Agent Memory Without Generative Summaries
- Jev as an LLM Judge: Confidence-Gated Cascades at 0.36% of the Cost
- TypeSafe Computer Use: Local Desktop Automation with Jev, Step by Step
- Jev Resume Screening: Build an AI Resume Evaluator with the Jev JavaScript SDK
- Jev + Claude Code Guide: Voice-Controlled Browser Automation with Typed Decisions
- Jev + Codex: Install the TypeSafe Skill and Triage a Real Gmail Inbox
- Jev vs Ollama: Can Local AI Replace Hosted Jev Without Sending Your Data Away?
- Build Your Own Jev: Train a Free Open-Source Zero-Shot Classifier (That Plays Doom)
- CUA-S1-Forms: a 706K-Parameter Jev-Like Model That Fills GUI Forms on Your CPU
- NOC/SOC Alert Triage with Jev: Rules First, One Typed Question, a Policy Gate
- Ollama Decision Models: Run tev1 and Nimble Locally (Tested on an 8 GB Card)
- Jev Guardrails in Production: A Five-Step Playbook for Decision Automation
- A Session Drift Guard for Pi Agent: Let the Jev Model Propose, Let Code Decide
- 50 Tev1 Use Cases: What a Local Decision Model Can Actually Do (Tested on an 8 GB Laptop)
- Jev, Hands-On: Where the Official Claims Meet Independent Remeasurement
- Jev Ticket Classification in a Real App: the After-Insert Hook and the Calculated Field
- OpenJev RLCD: Run the Open-Source Calibrated Decision Model Locally (Full Guide)
- Clef-Flash vs Jev: I Tested Cloudflare's Decision Model Locally in Ollama (Q4_K_M)
- Clef-Flash Tutorial: Install and Run Cloudflare's 9B Multimodal Decision Model Locally on Ubuntu
- CLM-8B: the Contrastive Decision Model That Scores 1,024 Options in 44 ms (13x Faster Than Jev)
- Nox 4B Tutorial: Run the Decision 2.0 Model Locally and Put It Through Four Real Decisions (One Ends in a Fail)
- Julia-1 Tutorial: Install the Open-Source Jev Replacement in Pure Python (and Watch It Beat If-Statements 9 to 2)
- OpenJev 0.8B on CPU: I Built a Ticket-Routing Inbox and Calibrated the Thresholds
- Jev n8n Integration: the JevGate Community Node, Step by Step (Plus a Plain-HTTP Fallback)
- NanoJev Tutorial: Install the 0.6B Open-Source Jev Replica and Watch It Route Decisions at 47 ms
- PPLX Decider Tutorial: Perplexity's Open 27B Decision Model, Its Decisions API, and a 12-Ticket Triage Run
- AutoTrust JEV-27B Tested Locally: Four Arms, 72 Cases, and One 0.969 Score That Was Wrong
- Clef 27B Locally: Watch Cloudflare’s Multimodal Decision Model Read an Image, a Video and an Uzbek Newspaper in One Pass
- Ollaya Guide: Install the "Ollama for Decision Models" Runner, Read Every Vendor-Reported Number, and Run the CPU Test It Leaves Open
- Strands Decider 2B Tutorial: Install the AWS Strands Decision Model on an 8GB Laptop — and Keep Its Failures In
- Liquid AI Open d1 Locally: d1-3B and d1-omni-600M on a MacBook Air M5 — Guardrails, Screen Checks, Voice Routing and Document Triage, Every Number Frame-Checked
- Image Decision Models for RPA: Watch Two Open Models Review an Unsigned W-8BEN With No OCR
- GLiNER2.5-Decide (340M) vs Jev (4B): Which Decision Model Actually Wins? A Frame-by-Frame Selection Guide
- Decision Models on Jetson: Jev vs Strands Decider 2B vs Laya vs d1-3B — Skill Master Scores, Thor Latency and JevBench, Every Number Frame-Checked
- Microsoft Decision-1 Tested: 146 Independent Tests, a 93% Mean, 124/125 When Confident — Every Number Frame-Checked
- Wire Jev into an Azure AI Foundry Agent as the Evaluation Layer — OpenAPI Tool, TypeSafe Connection, Triage Instructions and an Honest First-Run Failure