Guides / 動画ウォークスルー
Jev RAG Reranker: Policy-Steered Reranking for Retrieval-Augmented Generation
最終更新日: 2026-09-25
Prompt Engineering walks through Jev as a policy-steered reranker inside a RAG pipeline: criteria written as executable policy filter top-100 chunks down to a top-5, rankings flip when the written policy flips, and BM25’s 21% top-1 accuracy climbs to 54% at a cost that stays flat as chunks grow.
要点
A RAG pipeline is full of decision points — rerank, filter, cite — and this 11-minute build puts Jev in charge of the rerank one. The setup: candidate chunks come back from vector or full-text search for a query like "how do I fix a 401 unauthorized error from the API", and a Jev reranker built on the binary Noul primitive scores them against criteria that act as an executable policy — true when a passage directly answers the question with the specific answer asked for, false when it only shares words or topics. Because the criteria are written down, the same corpus ranks differently under a strict authoritative-version-2 policy versus a looser fast-workaround policy: steerability a cross encoder cannot offer (it is frozen in time) at a cost an LLM reranker cannot match (Gemini Flash’s bill grows roughly linearly with chunk size while Jev stays flat; a batch of decisions that takes about 40 seconds sequentially finishes in 7.6 seconds with 64 concurrent pools). On the benchmark, BM25’s 21% top-1 accuracy rose to 54% with Jev reranking — and reranking a realistic top-K of 10–20 chunks would score higher still.
ステップごとのウォークスルー
- 1
Find the decision points where your RAG pipeline needs a policy
RAG looks like plumbing, but the video opens by marking the three places where it is really decision-making: the rerank step that narrows retrieval from top-100 to top-5, a filter gate that passes or rejects chunks, and the citation check on what the LLM finally answers. Jev slots into each gate because every gate is a typed decision, not a generation task. The running example is a documentation system with several competing policy versions that must be resolved at query time. The failure mode is subtle: vector distance only measures semantic proximity, not correctness under your business logic, so answers silently drift when the official API docs change — or when the same query deserves an in-depth architectural explanation instead of a quick copy-paste snippet.
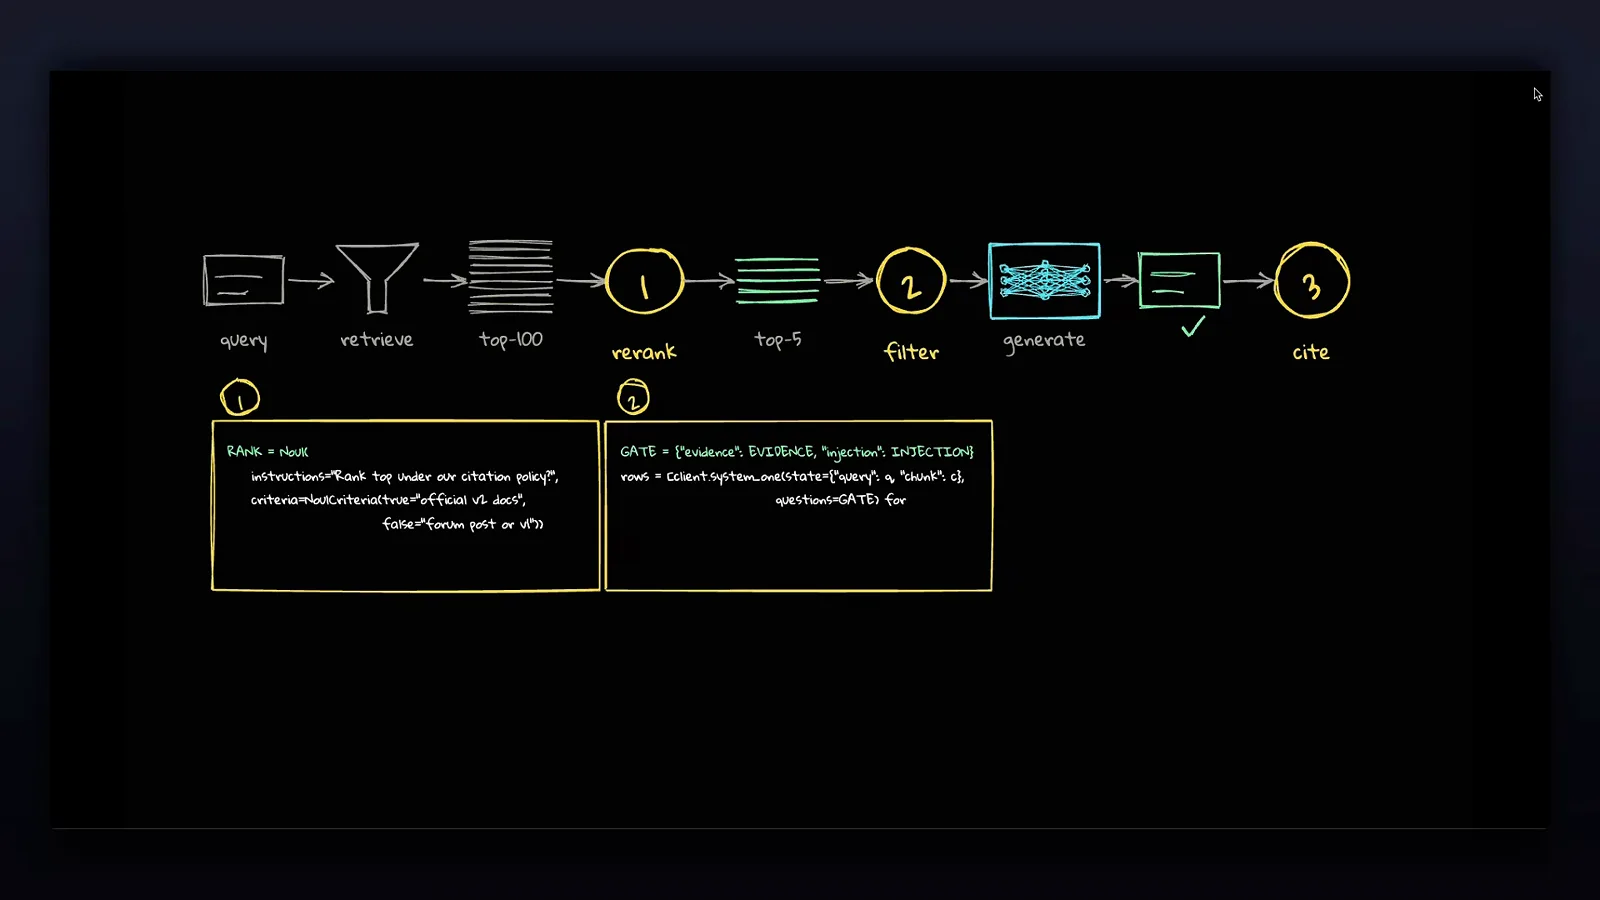
Three Jev gates in one pipeline: score the rerank, gate the filter, check the cite.タイムスタンプ 0:48 を見る - 2
Compare the three rerankers: frozen, expensive, or steerable
Before reranking, the video frames Jev’s three primitives: a binary true/false classifier, a choice ranker driven by a criterion, and a score ladder that assigns different scores to options. Reranking exercises them, and the whiteboard compares the three tools you could reach for. A cross encoder scores question-and-chunk pairs and is accurate, but it cannot follow instructions — it is frozen in time, which is exactly why it fails when your organization’s policy changes while the underlying business logic stays the same. An LLM reranker does follow instructions, but it is prohibitively expensive and noticeably slower. Jev is pitched as the third option: steerable like the LLM, priced closer to the cross encoder, which turns a policy change into a configuration edit instead of a re-training job.
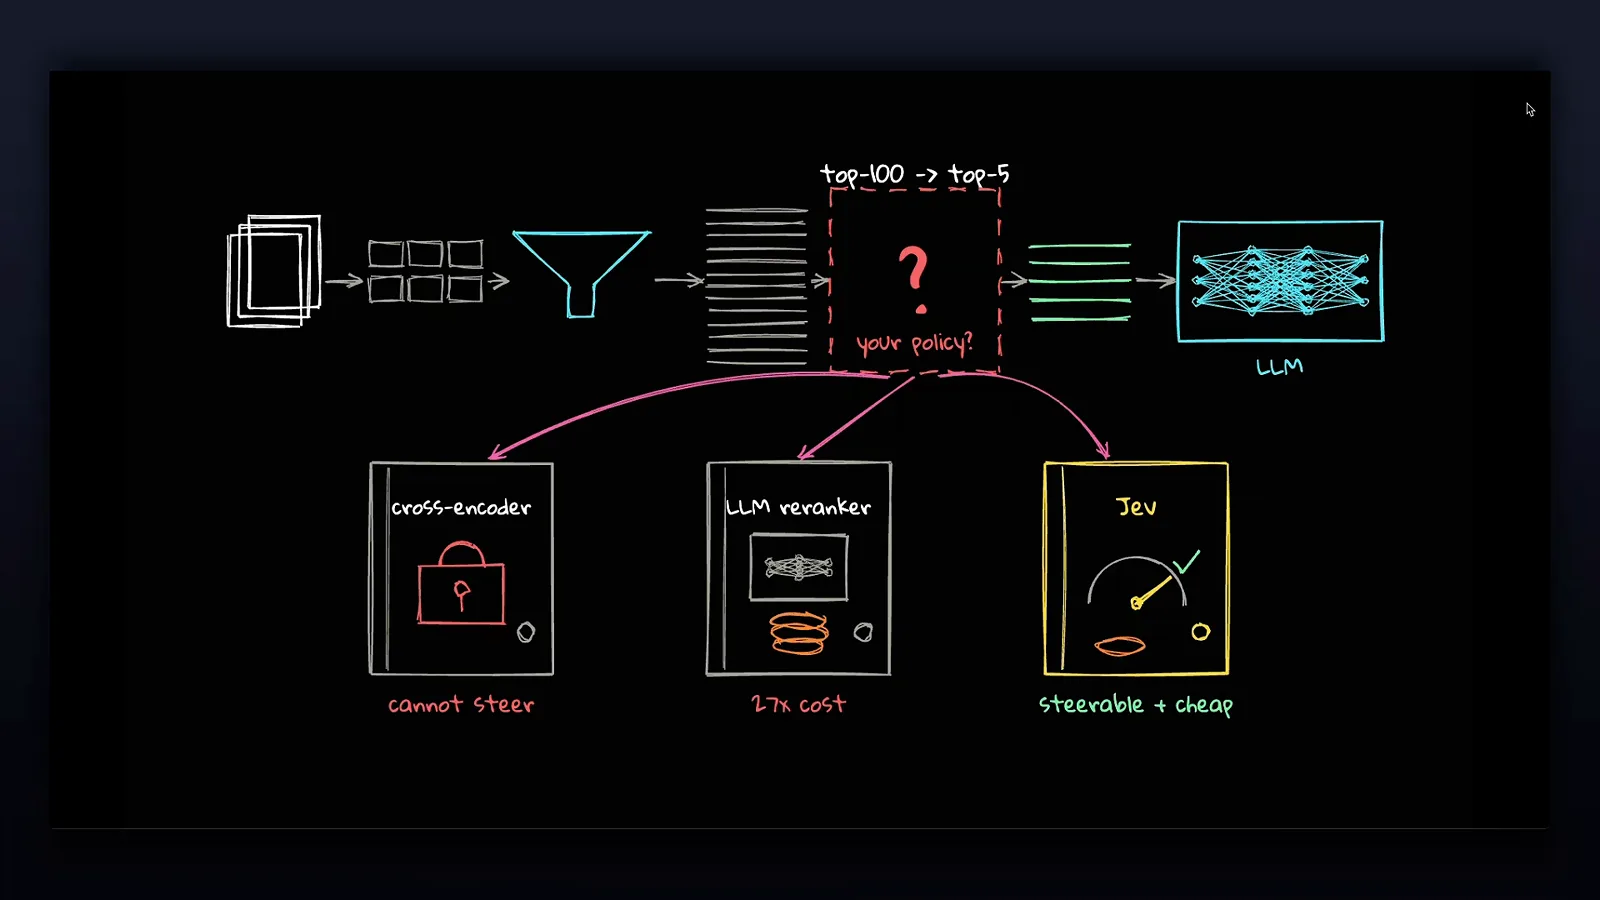
Cross-encoders cannot steer, LLM rerankers cost $$$ — Jev is steerable and cheap.タイムスタンプ 2:11 を見る - 3
Turn criteria into an executable policy, not a prompt suggestion
The notebook (official Python SDK, or REST API if you prefer; signing up includes $5 of free credit) wires a reranker around Jev’s binary Noul primitive, which returns a calibrated probability instead of free text. The trick is treating criteria as an executable policy: rather than soft prompt instructions, the criteria draw strict decision boundaries — true when the passage directly answers the question with the specific answer it asks for, false when it merely shares words or topics without answering. A sanity check runs four passages — a direct refund answer, a topical overlap, a keyword match, and an unrelated chunk — and the direct answer takes the highest probability while the rest score low, giving you a threshold classifier: accept above the line, discard below. Throughput holds up too: the same batch of decisions drops from about 40 seconds sequentially to 7.6 seconds using the 64 concurrent pools.
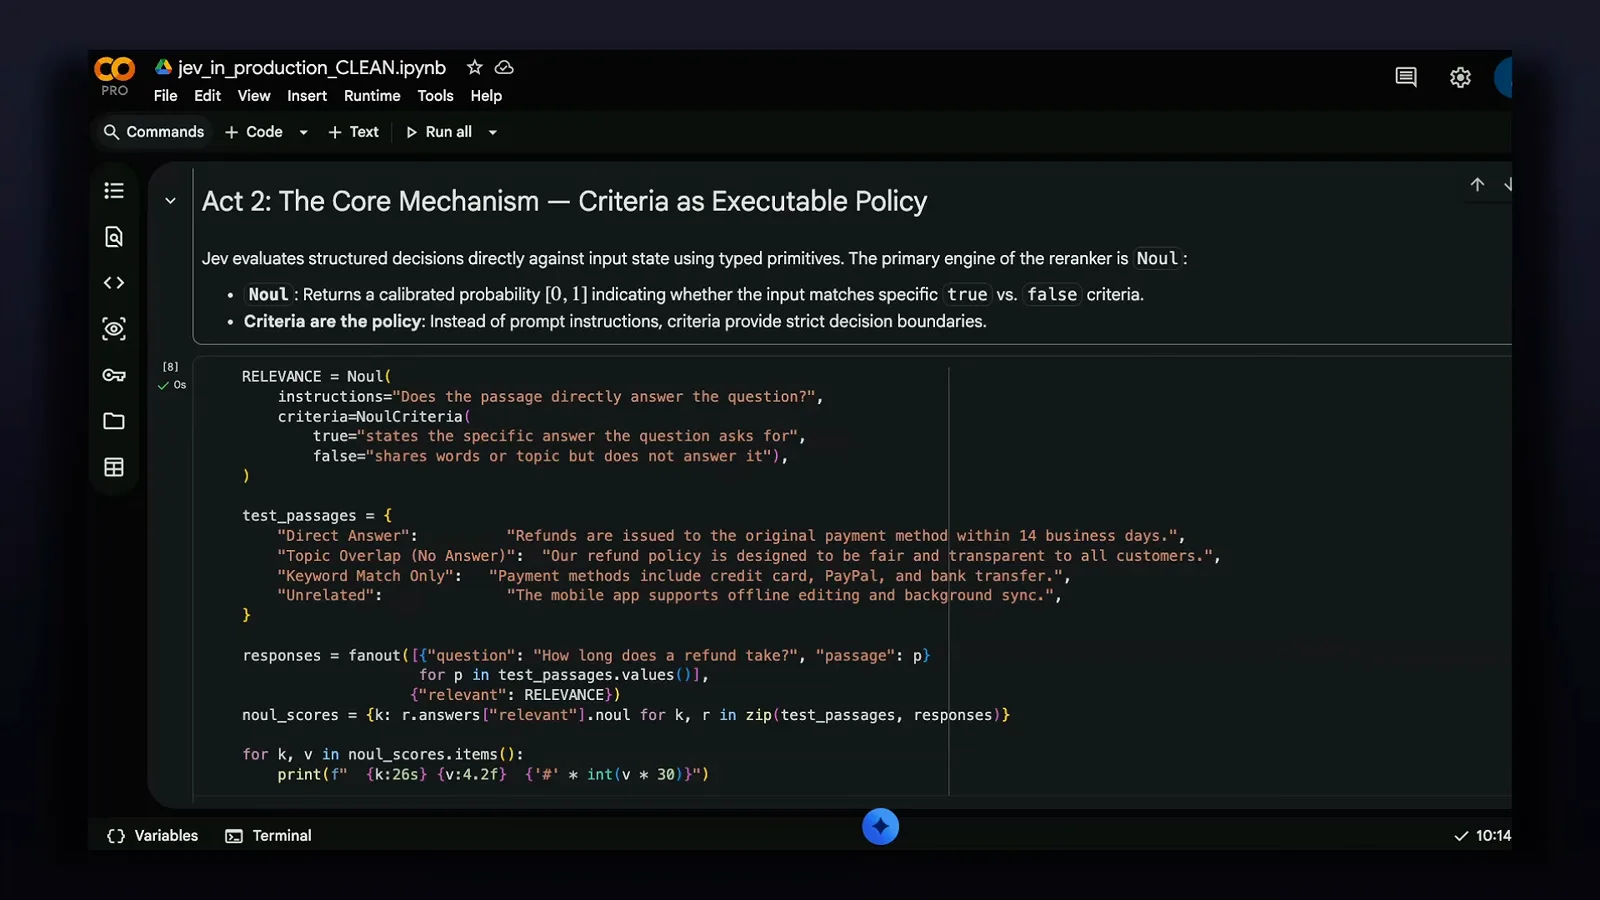
Criteria as executable policy: strict true/false boundaries instead of prompt suggestions.タイムスタンプ 5:52 を見る - 4
Steer the same corpus into different rankings with two policies
The benchmark query is deliberately mundane — how do I fix a 401 unauthorized error from the API — with candidate chunks returned by vector or full-text search carrying normal metadata. The reranker then runs under two written policies: an authoritative version two policy that is strict about sourcing, and a fast workaround policy that is deliberately less strict. The bar chart is the payoff: the same eight candidates, drawn from official docs, Stack Overflow, blog, and forum pages at v1 and v2, come back in a different order under each policy. That is the whole point of a steerable reranker — the ranking follows the criteria you write, so changing what your organization means by "best answer" is a one-line edit instead of a new model.
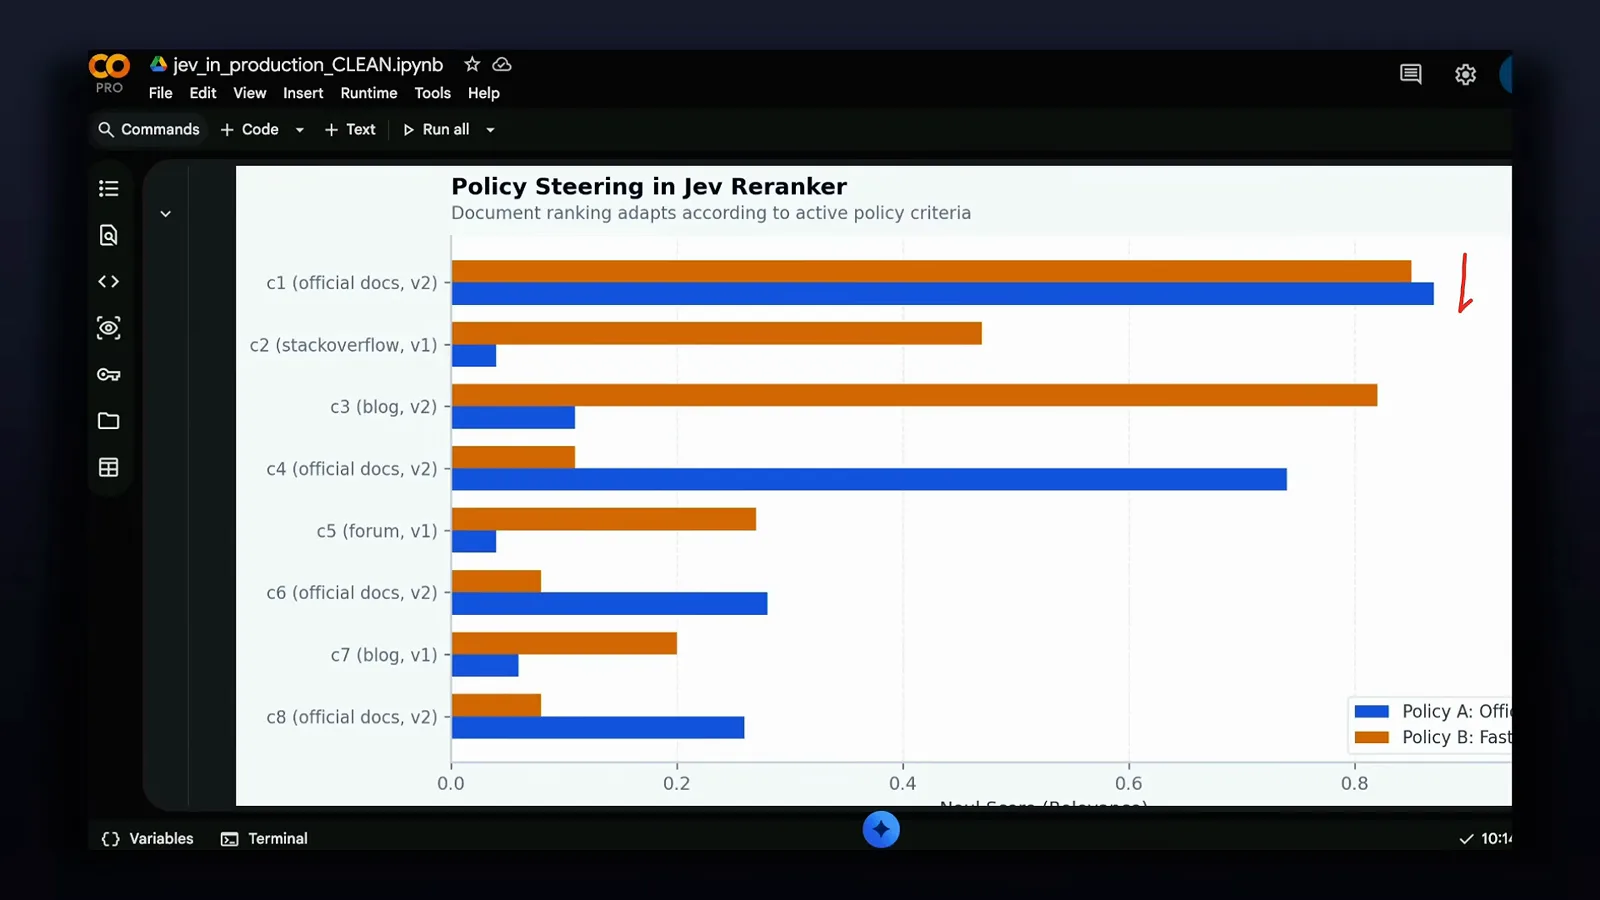
Same eight chunks, two policies, two different rankings — the steerability payoff.タイムスタンプ 8:20 を見る - 5
Price the reranker: flat against a linear LLM bill
The cost benchmark pits Jev against Gemini Flash-Lite and Gemini Flash acting as LLM rerankers, running the same prompt and query through each. At small chunk sizes Jev’s cost and latency sit close to Flash-Lite, but the two charts diverge as chunks grow: the LLM cost curve climbs roughly linearly with chunk length while Jev stays nearly flat — and the video notes that larger chunks are exactly where this approach shines. Throughput matters as much as unit cost: the concurrency test measured about 17 decisions per second even running serially. The practical read is that you can afford to re-score the whole candidate list on every request, and the bill stops growing every time retrieval starts returning longer passages.
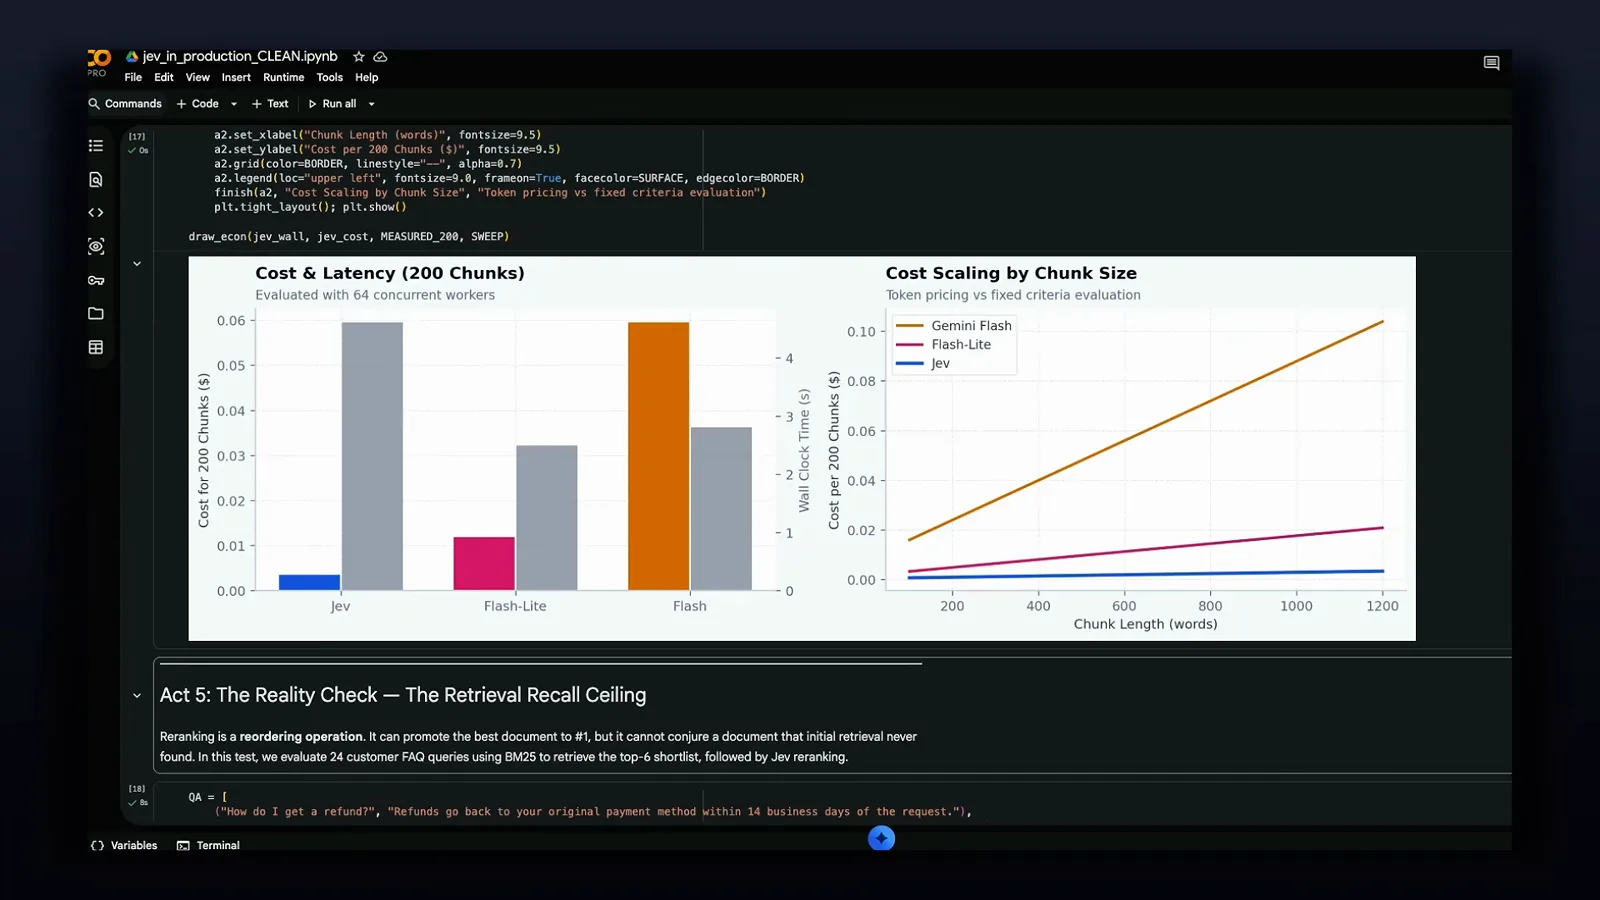
Jev stays flat as chunk size grows; the Gemini reranker bill climbs linearly.タイムスタンプ 9:20 を見る - 6
Check the ceiling: 21% to 54% top-1 accuracy
The final chart is the reality check. A BM25 full-text-search baseline answers only 21% of test queries with its top-1 chunk; adding Jev as a reranker pushes top-1 accuracy to 54% — and the video is careful to note this is the hardest metric, since reranking over a normal top-K of 10 to 20 chunks scores considerably higher. The chart’s subtitle carries the second insight: the reranker achieves 100% of candidate recall, so the misses that remain are bounded by the initial retrieval, not the reranker. The closing argument generalizes beyond reranking: anywhere an existing workflow makes a decision — rerank, filter, cite, validate — Jev can be plugged in as a drop-in replacement, and the decisions do not have to be binary.
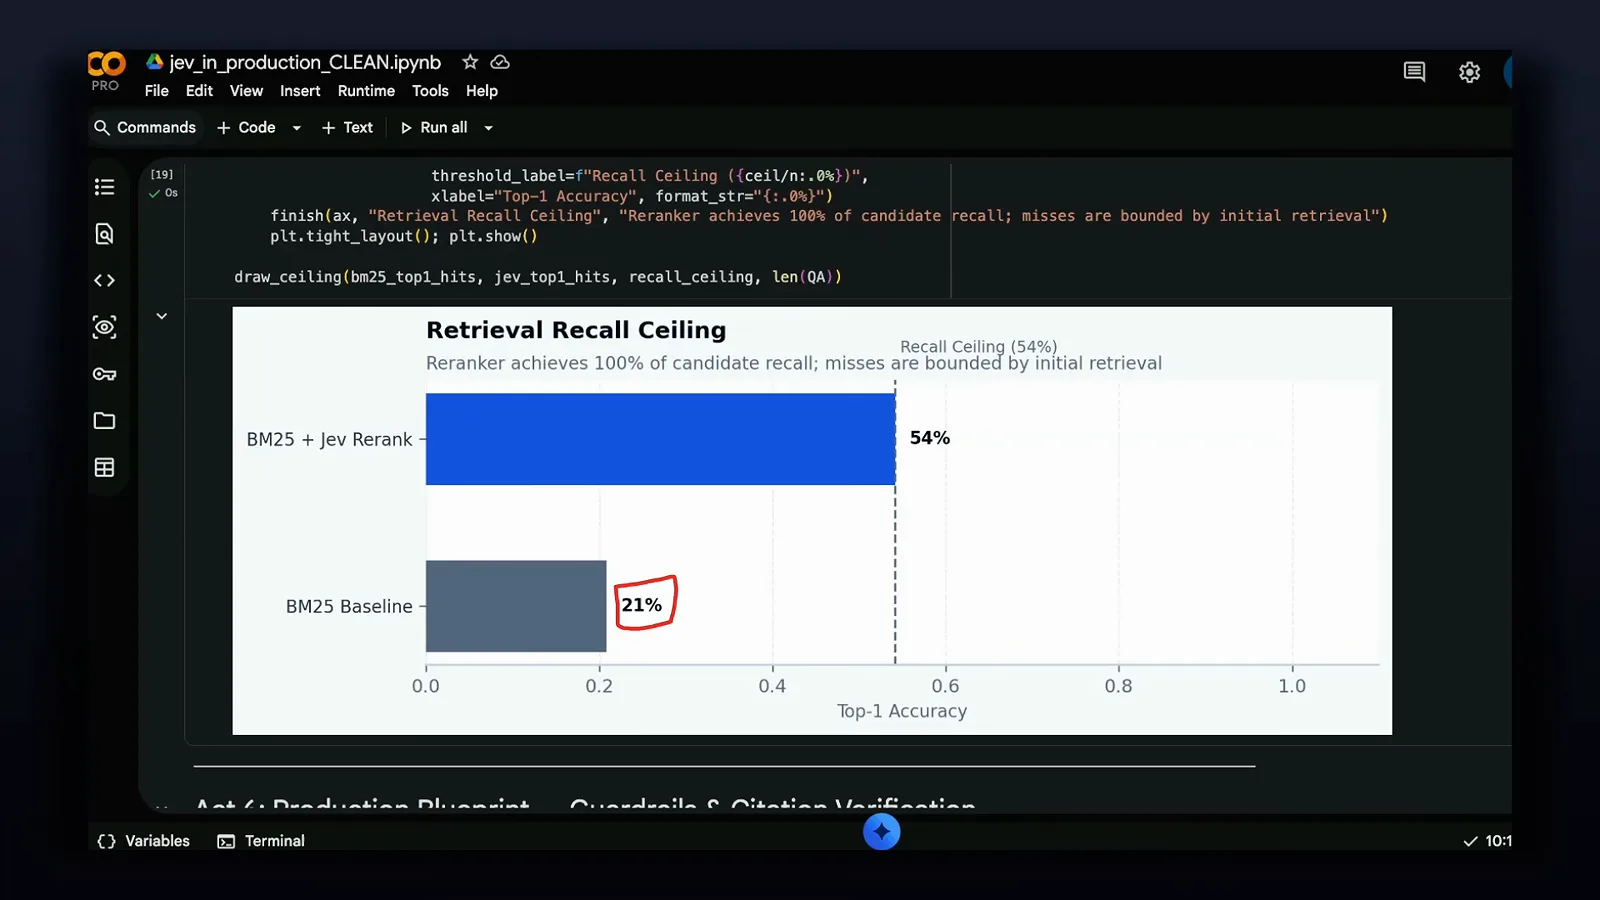
Top-1 accuracy: 21% on BM25 alone, 54% with Jev reranking.タイムスタンプ 10:17 を見る
よくある質問(FAQ)
What is a Jev RAG reranker?
A rerank step in which Jev scores every retrieved chunk against written criteria using its binary Noul primitive, which returns a calibrated probability that the passage directly answers the query. Unlike a cross encoder it follows instructions, so the ranking enforces your business policy, and unlike an LLM reranker its cost stays flat as chunks grow.
Why not just use a cross encoder or an LLM as the reranker?
Cross encoders only measure semantic proximity between question and chunk — they cannot follow instructions, so they fail exactly when your policy changes while the business logic stays the same. LLM rerankers do follow instructions but are prohibitively expensive and slower, with cost climbing roughly linearly as chunk size grows. Jev combines instruction-following with a cost close to the cross encoder.
How does policy steering change the ranking?
You write the criteria as an executable policy — in the video, a strict authoritative version two policy and a deliberately looser fast workaround policy. The same candidate chunks then come back in a different order under each policy, so changing what your organization means by "best answer" is an edit to the criteria, not a model retrain.
How much accuracy does Jev reranking add?
In the video’s benchmark, a BM25 full-text-search baseline answered 21% of queries correctly at top-1; adding Jev as a reranker pushed that to 54%. The chart also notes the reranker achieves 100% of candidate recall, meaning remaining misses are bounded by initial retrieval — and over a realistic top-K of 10 to 20 chunks accuracy runs higher still.
Can Jev reranking keep up with production traffic?
Yes. The concurrency test measured about 17 decisions per second even running serially — roughly 40 seconds for the full batch — and the same batch finished in 7.6 seconds using the 64 concurrent pools, which is enough throughput to re-score a top-100 candidate list on every query.
関連ガイド
Jev Model Router Guide
The same Choice, Score, and Noul primitives driving a privacy-gated model router.
読むLLM Fallback Strategy
Confidence-based degradation patterns for decisions that come back low-confidence.
読むJev API Reference
The evaluate endpoint and typed questions behind every Noul reranker call.
読むWhat is Jev?
The binary, choice, and score primitives explained beyond the hype.
読むJev Playground
Write your own criteria and watch the ranking flip live.
読むその他の動画ウォークスルー
- Jev Classification Quickstart: OpenRouter API, Primitives & Real Probabilities
- Jev Architecture Explained: Why 70ms Decision Models Beat LLMs for Workflow Automation
- Ultra-Fast Browser Agents with Jev: 178ms DOM Loops & Dual Model Orchestration
- Open Jev Models Are Here: Semif, Nimble, Decider, DiffusionGemma & Laya Hands-On
- Jev vs LLM: Will Jev Replace LLMs? Krish Naik's Whiteboard Explainer
- Jev Trader Tutorial: Build a Subsecond AI Trading Bot on Monad
- Jev Model Router: Build a Privacy-Gated LLM Router with Jev & OpenJev
- Jev Tutorial for Beginners: State, Questions & the TypeScript SDK
- Run Jev Locally: Kev, SemIf & Von on Your Own GPU (OpenJev Guide)
- When to Use Jev: An Engineer's Audit of Claims, Gates, and Failure Modes
- LangChain + Jev Integration Tutorial: Routing, Guardrails & Evals
- Jev MCP Server: Connect Jev Decisions to Claude Code & Cursor
- Jev vs Luna: Independent Benchmarks Put "Better, Faster, Cheaper" to the Test
- Jev Agent Harness: Where the Decision Gate Sits in Your LLM Loop
- Jev Playground Walkthrough: The Hotdog Lesson, Criteria, and a Four-Console Token Test
- Jev Text Classification API: Zero-Shot CLI & REST with classifier.dev
- Jev API Examples: First Request, curl & All Three Question Types
- Expanso Edge と Jev でログをトリアージする
- Treg と Jev でリードをエンリッチする: ICP 判定と登録スコアリング
- Heym で Jev Decision Node を使う: モデルルーティングを制御する
- Laya Tutorial: Open-Source AI Routing With Calibrated Probabilities (Laya vs Jev Setup)
- Train Your Own Jev: Fine-Tune a Jev-Style Decision Model for $5–$17 (What You Can and Cannot Train)
- Jev Tips: 8 Best Practices for Better Decisions (State, Questions, Criteria & Thresholds)
- Jev Context Compaction: Prune AI Agent Memory Without Generative Summaries
- Jev as an LLM Judge: Confidence-Gated Cascades at 0.36% of the Cost
- TypeSafe Computer Use: Local Desktop Automation with Jev, Step by Step
- Jev Resume Screening: Build an AI Resume Evaluator with the Jev JavaScript SDK
- Jev + Claude Code Guide: Voice-Controlled Browser Automation with Typed Decisions
- Jev + Codex: Install the TypeSafe Skill and Triage a Real Gmail Inbox
- Jev vs Ollama: Can Local AI Replace Hosted Jev Without Sending Your Data Away?
- Build Your Own Jev: Train a Free Open-Source Zero-Shot Classifier (That Plays Doom)
- CUA-S1-Forms: a 706K-Parameter Jev-Like Model That Fills GUI Forms on Your CPU
- NOC/SOC Alert Triage with Jev: Rules First, One Typed Question, a Policy Gate
- Ollama Decision Models: Run tev1 and Nimble Locally (Tested on an 8 GB Card)
- Jev Guardrails in Production: A Five-Step Playbook for Decision Automation
- A Session Drift Guard for Pi Agent: Let the Jev Model Propose, Let Code Decide
- 50 Tev1 Use Cases: What a Local Decision Model Can Actually Do (Tested on an 8 GB Laptop)
- Jev, Hands-On: Where the Official Claims Meet Independent Remeasurement
- Jev Ticket Classification in a Real App: the After-Insert Hook and the Calculated Field
- OpenJev RLCD: Run the Open-Source Calibrated Decision Model Locally (Full Guide)
- Clef-Flash vs Jev: I Tested Cloudflare's Decision Model Locally in Ollama (Q4_K_M)
- Clef-Flash Tutorial: Install and Run Cloudflare's 9B Multimodal Decision Model Locally on Ubuntu
- CLM-8B: the Contrastive Decision Model That Scores 1,024 Options in 44 ms (13x Faster Than Jev)
- Nox 4B Tutorial: Run the Decision 2.0 Model Locally and Put It Through Four Real Decisions (One Ends in a Fail)
- Julia-1 Tutorial: Install the Open-Source Jev Replacement in Pure Python (and Watch It Beat If-Statements 9 to 2)
- OpenJev 0.8B on CPU: I Built a Ticket-Routing Inbox and Calibrated the Thresholds
- Jev n8n Integration: the JevGate Community Node, Step by Step (Plus a Plain-HTTP Fallback)
- NanoJev Tutorial: Install the 0.6B Open-Source Jev Replica and Watch It Route Decisions at 47 ms
- PPLX Decider Tutorial: Perplexity's Open 27B Decision Model, Its Decisions API, and a 12-Ticket Triage Run
- AutoTrust JEV-27B Tested Locally: Four Arms, 72 Cases, and One 0.969 Score That Was Wrong
- Clef 27B Locally: Watch Cloudflare’s Multimodal Decision Model Read an Image, a Video and an Uzbek Newspaper in One Pass
- Ollaya Guide: Install the "Ollama for Decision Models" Runner, Read Every Vendor-Reported Number, and Run the CPU Test It Leaves Open
- Strands Decider 2B Tutorial: Install the AWS Strands Decision Model on an 8GB Laptop — and Keep Its Failures In
- Liquid AI Open d1 Locally: d1-3B and d1-omni-600M on a MacBook Air M5 — Guardrails, Screen Checks, Voice Routing and Document Triage, Every Number Frame-Checked
- Image Decision Models for RPA: Watch Two Open Models Review an Unsigned W-8BEN With No OCR
- GLiNER2.5-Decide (340M) vs Jev (4B): Which Decision Model Actually Wins? A Frame-by-Frame Selection Guide
- Decision Models on Jetson: Jev vs Strands Decider 2B vs Laya vs d1-3B — Skill Master Scores, Thor Latency and JevBench, Every Number Frame-Checked
- Microsoft Decision-1 Tested: 146 Independent Tests, a 93% Mean, 124/125 When Confident — Every Number Frame-Checked
- Wire Jev into an Azure AI Foundry Agent as the Evaluation Layer — OpenAPI Tool, TypeSafe Connection, Triage Instructions and an Honest First-Run Failure