Guides / illustrated walkthrough
Open Jev Models Are Here: Semif, Nimble, Decider, DiffusionGemma & Laya Hands-On
Sam Witteveen tests the open Jev ecosystem in 21 minutes: JevBench rankings, the Semif logit readout on a frozen Qwen3.5-4B, Nimble's contrastive LoRA recipe, Decider's ~33 ms typed answers, DiffusionGemma batch routing, and Laya fine-tuned on a free Colab T4.
Quick takeaway
Within ~24 hours of Jev taking off, 20-30 open implementations appeared. On JevBench (intelligence, calibration, speed, cost at 25% each), Jev 1.13.0 scores 75.3 with Semif (frozen Qwen3.5-4B) right behind at 74.6 — close on easy work, still behind on hard tiers. Zero-training option: read option-token logits like Semif. Narrow high-accuracy option: Nimble's contrastive LoRA on ~3,000 pairs. Fastest serving: Decider at ~33 ms per answer and DiffusionGemma at 27.4 decisions/s. Smallest local setup: Laya, a 421M-parameter ModernBERT, fine-tunable on a free T4. For hard multi-hop cases, cascade up to a reasoning model.
Video source
Sam Witteveen
Step-by-step walkthrough
- 1
Start from the JevBench scoreboard to pick your open Jev
JevBench v1.2.2 runs 534 decisions per system and scores intelligence, calibration, speed, and cost at 25% each with a geometric mean. Jev 1.13.0 tops the official board at 75.3; right behind sits Semif (Qwen3.5-4B) at 74.6, then djev (Maisa, diffusion-gemma) at 74.3 and Laya at 70.1. Frontier models flip the picture: GPT-5.6 Luna posts a 97 intelligence sub-score but only 66.0 overall while costing roughly six times as much as Jev and running far slower. Switch the weighting to accuracy-only and the gap to the smaller open models widens — and note Jev's own terms of service even forbid benchmarking it against other models.
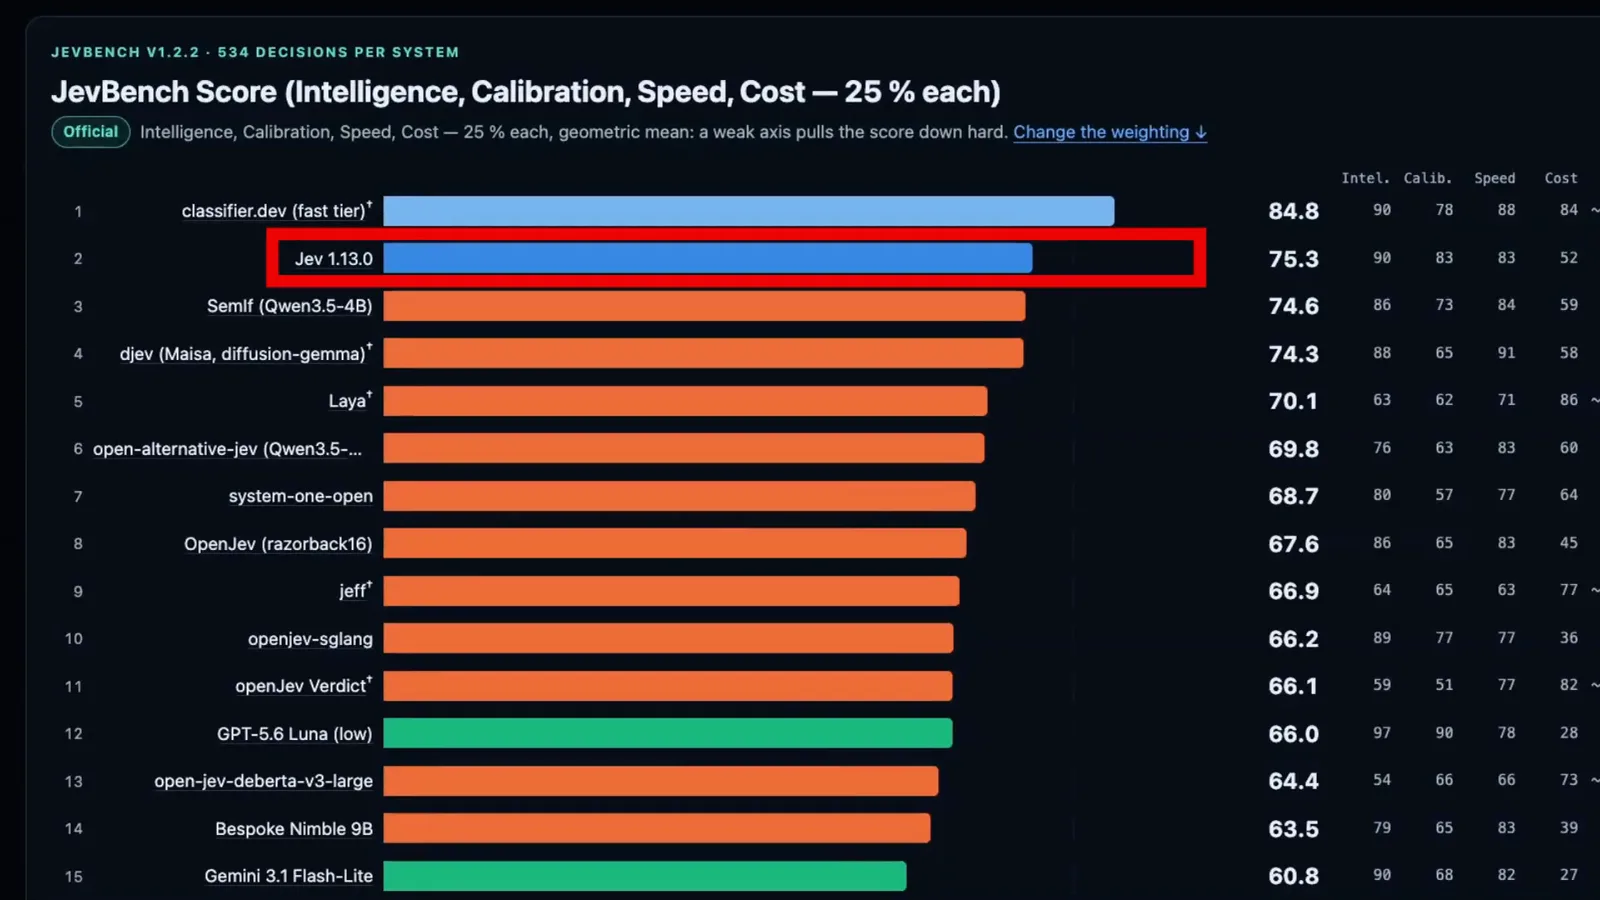
The official JevBench board: Jev 75.3, Semif 74.6, djev 74.3 — the open pack is close on blended score.Watch at 4:02 - 2
Run the zero-training Semif readout on a model you already host
Semif (formerly OpenJev) is a frozen Qwen3.5-4B with no training at all. Put the question and options in the prompt, run the prefill once, then read the logits of the option tokens and softmax over them instead of letting the model generate text. In the demo, a double-charge support ticket scores billing 86.7%, account_access 9.1%, sales 1.6%, escalate 2.6% — a 31 ms forward pass, 35 ms total, zero output tokens, 209 input tokens. Sam points out this matches his guess that Jev itself predicts off the prefill stage, and changing the policy wording immediately moves the distribution.
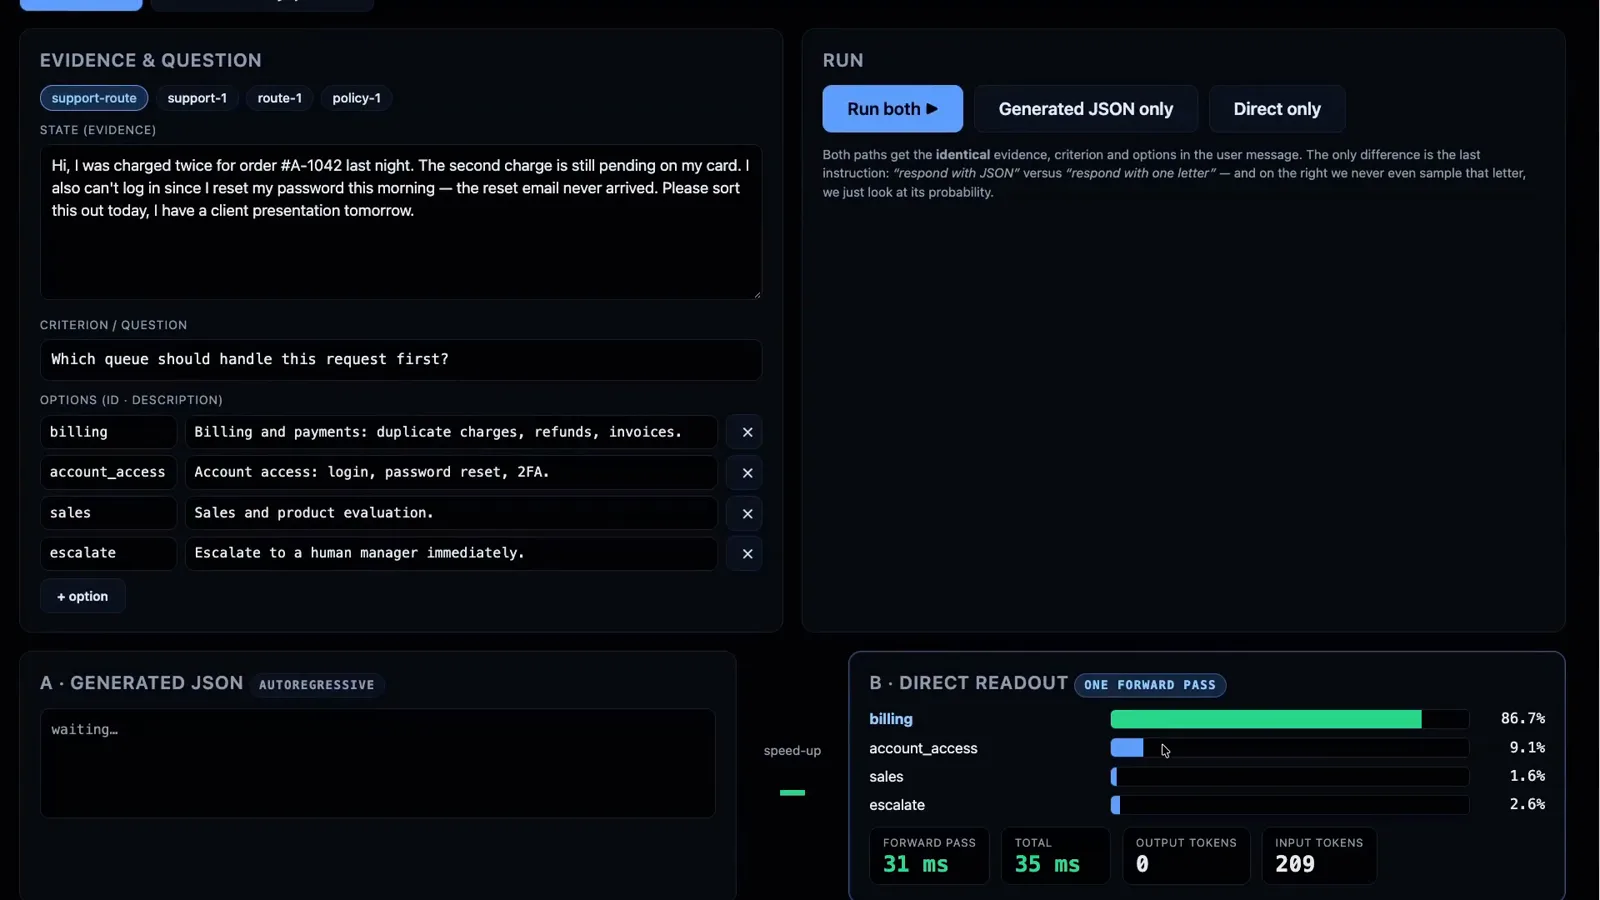
One forward pass: billing 86.7% read off raw option-token logits — no generation.Watch at 6:16 - 3
Fine-tune with Bespoke Nimble's contrastive pairs
Bespoke Nimble puts a LoRA on Qwen3.5-9B and trains it with fewer than 3,000 examples, explicitly not distilled from Jev. The trick is contrastive data curation: write two nearly identical records and flip one fact so the correct answer flips — a refund signed by Mira is authorized, the same record signed by Noah is not. The playground returns refund_authorized true with customer_tone CALM in 141 ms (47 ms per field), and the Flip the fact button swaps Mira for Noah to demonstrate the flip. On their own holdout it hits ~90% where the base model gets ~66% and Jev ~93%, but only ~44 on JevBench's hard tier — and the Priya pre-approval example shows the adapter can miss until the wording matches, so expect strong-but-narrow behavior.
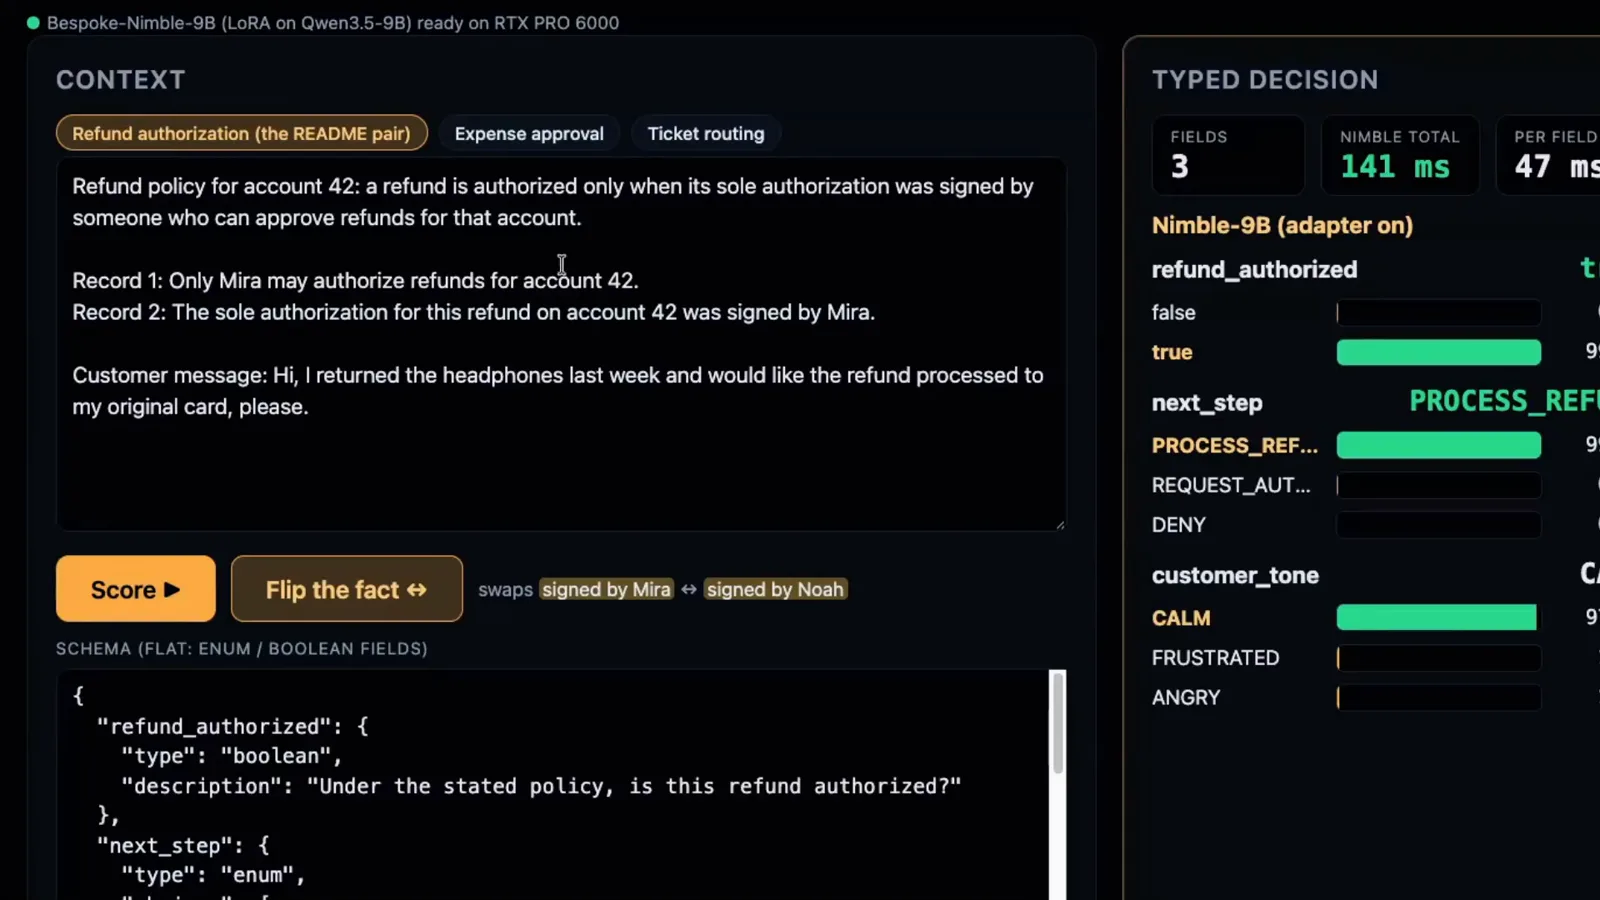
Flip the fact: swap signed-by-Mira for signed-by-Noah and watch the verdict flip.Watch at 9:08 - 4
Serve typed answers at ~33 ms with Decider
Decider (from Mapika) runs on a much smaller Qwen3.5 base model and reads the hidden state at each answer slot, projecting it onto your options instead of using output logits. It speaks the same three question types as Jev (choice, score, null), takes up to 32K context, and serves the same wire format as the Type Safe API, so it can drop in behind existing clients. The ANSWERS dashboard routes a double-charge ticket to billing at 99.8% with urgency 1.78, escalate yes at 72.3%, and frustration 1.52 — averaging about 33 ms per answer across ten runs. Sam's caveat: the model hedges, sitting near the middle of its distributions where Jev commits with high confidence.
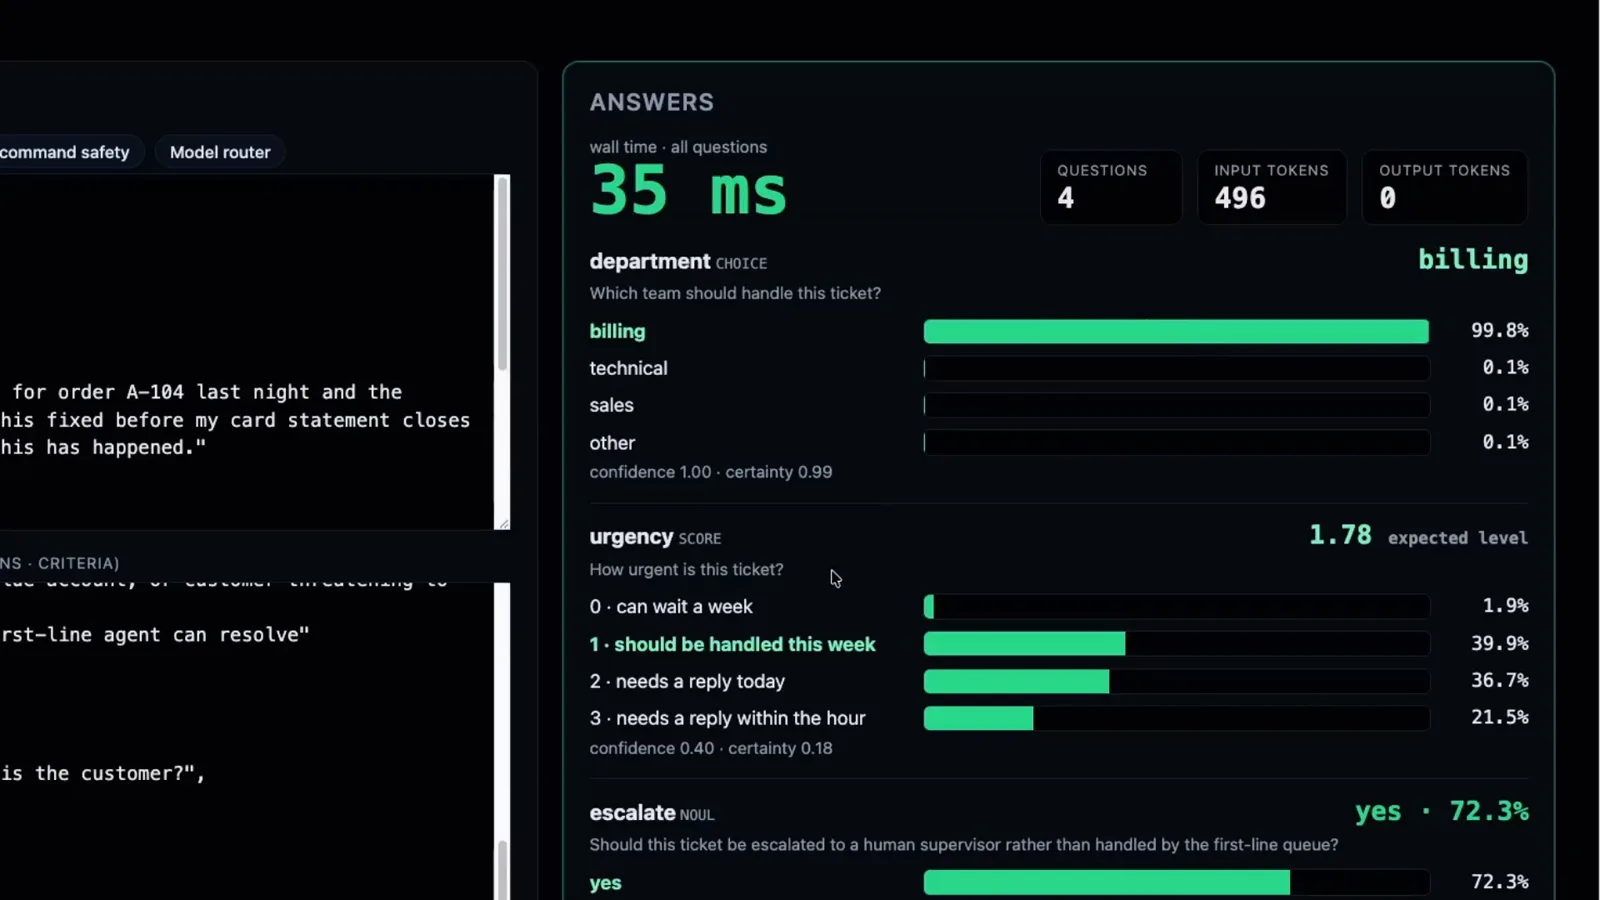
Decider's ANSWERS board: billing 99.8%, ~33 ms average, escalate 72.3%.Watch at 12:00 - 5
Batch decisions at DiffusionGemma speed
DiffusionGemma is a different class entirely: a 26B diffusion language model (diffusiongemma-26B-A4B, NVFP4 here on an RTX Pro 6000) that denoises a whole canvas per step and reads every answer slot's distribution at once, wired to Jev's schema format through a vLLM PR. In the demo, 16 support tickets fire concurrently at concurrency 16 and are simply done, with the MEASURED panel reporting about 27.4 decisions per second. Sam calls the throughput insane and notes it keeps quality on technical-vs-billing routing and annoyed-customer tone, though he found it under-trained next to Gemma or Qwen peers of similar size. If you need absurd question volume, this is the one to try.
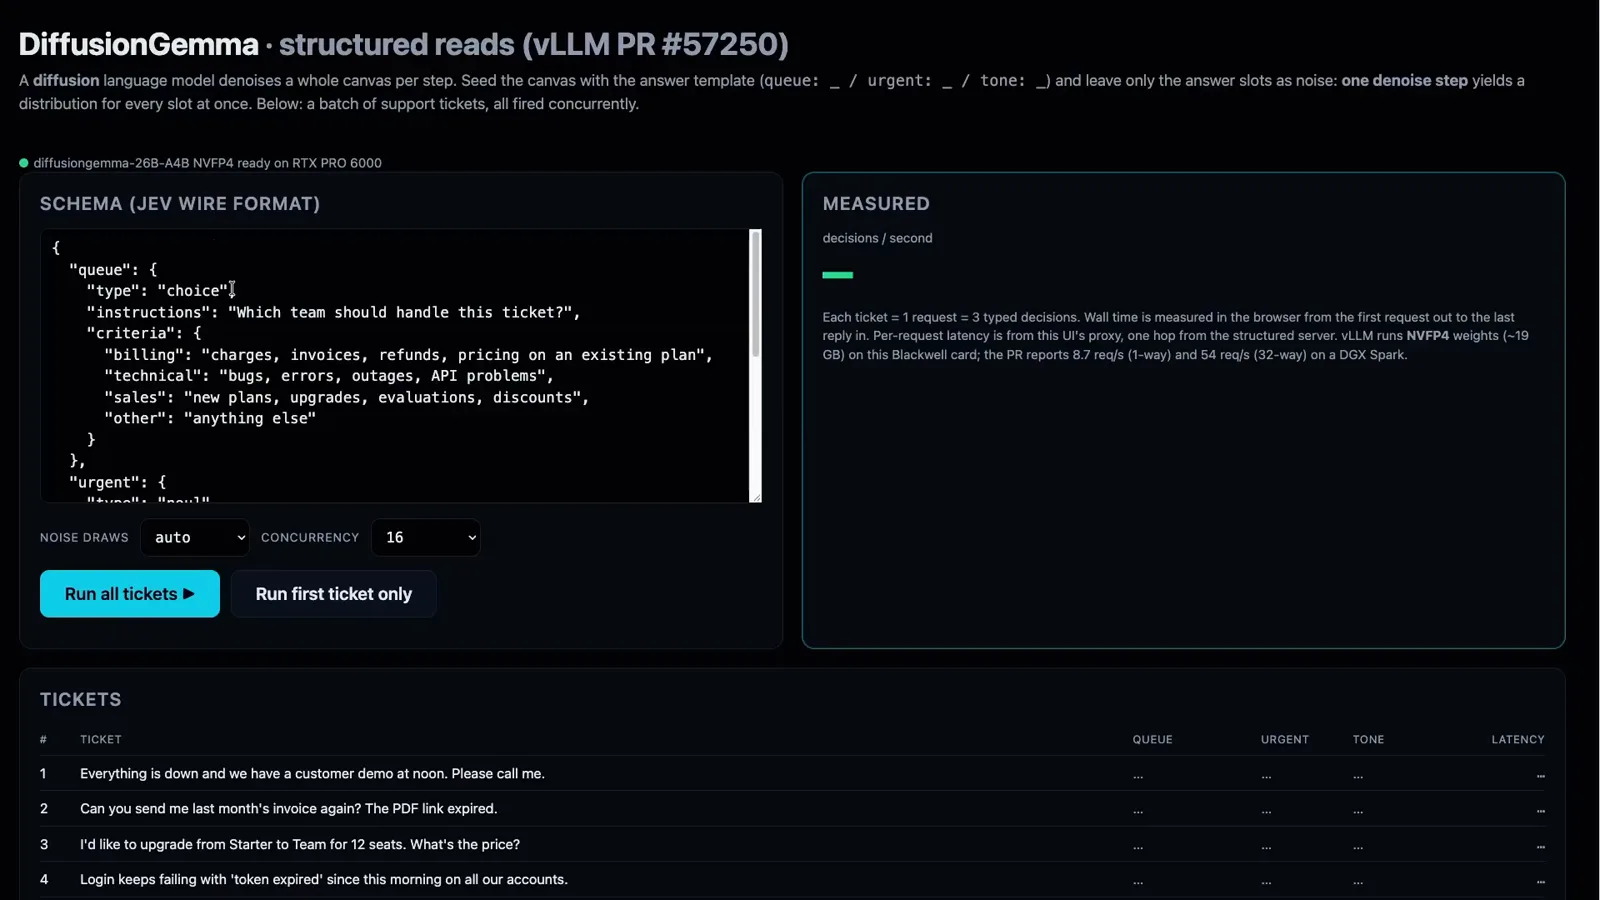
16 tickets, one denoise pass each: DiffusionGemma measures 27.4 decisions/s.Watch at 14:48 - 6
Run and fine-tune Laya on a free Colab T4
Laya is the old-school path reborn: a 421M-parameter non-autoregressive decision model built on ModernBERT-large with a 2-layer decision head, answering choice, score, and null questions in one ~35 ms forward pass across roughly 100 languages. The team publishes a Google Colab that fine-tunes it with RLCD policy gradients (log-score + spherical score + ranked probability score) on a free T4, peaking at about 6.5 GB of VRAM with FP16. Sam's take: impressive for its size, but on accuracy-weighted JevBench it trails the bigger models, most likely because a single-author fine-tune of an older encoder generalizes less than a well-funded lab's model. Still, it is the cheapest way to touch a Jev-style model on hardware you already have.
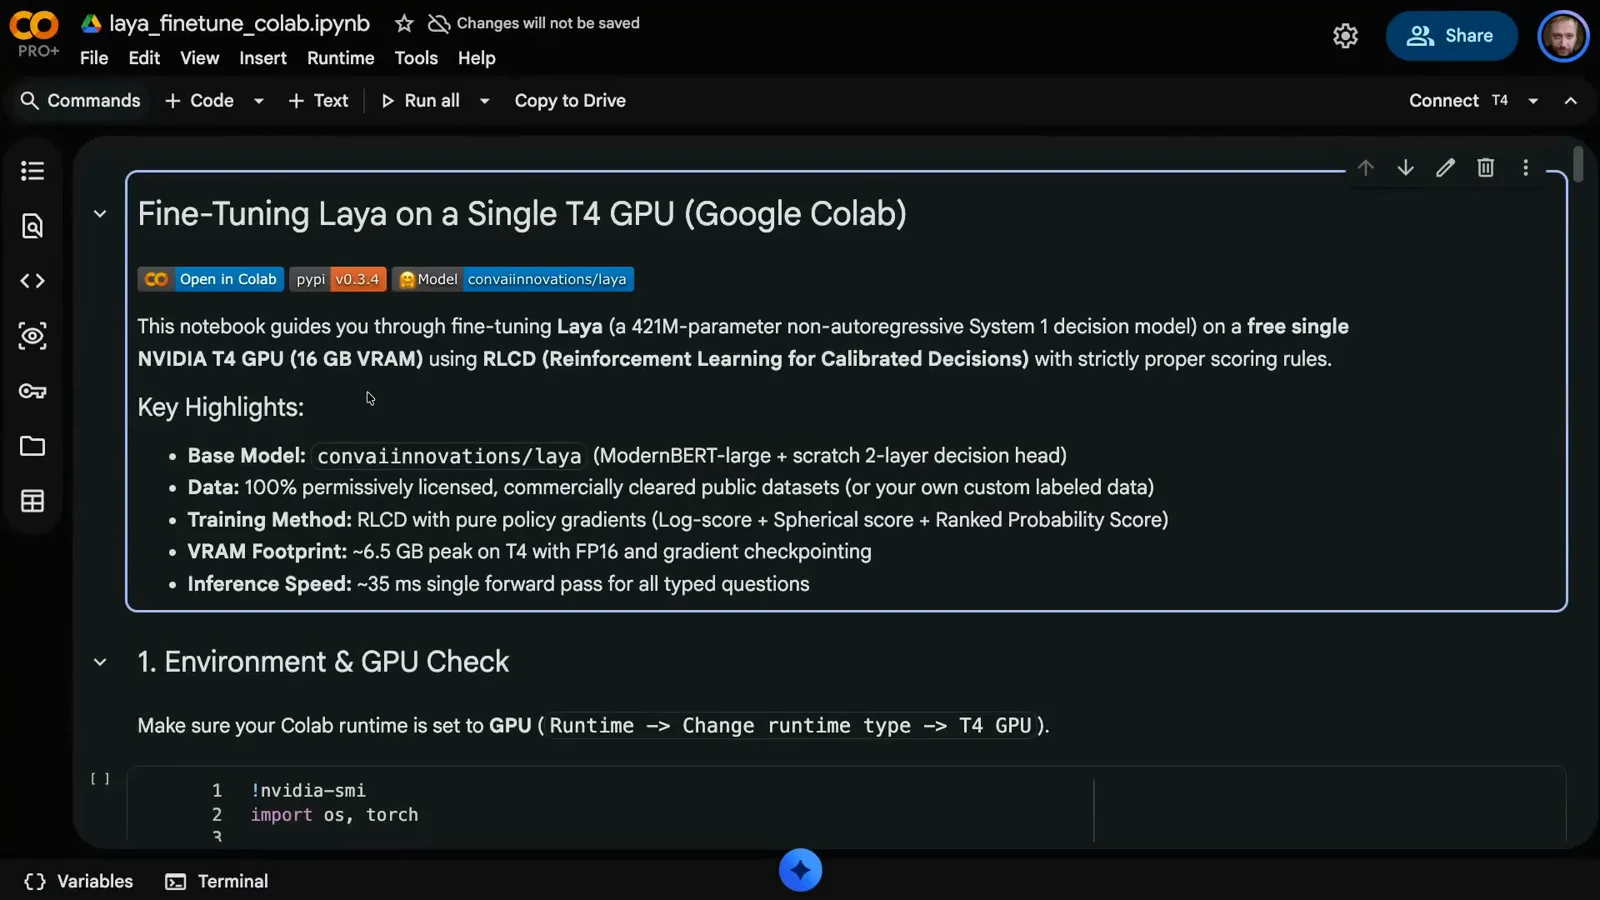
Fine-tuning Laya (421M params) on a free T4: ~6.5 GB VRAM, ~35 ms inference.Watch at 18:22
Frequently asked questions
What are the best open source alternatives to Jev?
As of this video there are 20-30 open implementations. The strongest on JevBench are Semif (a frozen Qwen3.5-4B logit readout, 74.6 vs Jev's 75.3), djev (74.3), and Laya (70.1). For image inputs try Alex Wartega's OpenJev, which can play Doom and Minecraft from screen states; Nano Jev is a 600M-parameter model that plays a Pac-Man-style game from grid choices.
Can I run a Jev-style classifier locally for free?
Yes. Laya ships a Google Colab that fine-tunes and runs a 421M-parameter model on a free T4 GPU (~6.5 GB peak VRAM, ~35 ms forward pass). Semif's readout trick works on any model you already host, and the video runs six implementations on a single RTX Pro 6000 workstation.
How close do open Jev models get to the real Jev?
On blended JevBench scores, very close: Jev 75.3 vs Semif 74.6 and djev 74.3. The gap opens on hard tiers — Bespoke Nimble scores only ~44 there despite ~90% on its own holdout — and multi-hop reasoning plus date arithmetic still favor cascading to a reasoning model on low or medium effort.
How do I fine-tune an open Jev model on my own data?
Copy Bespoke Nimble's contrastive data curation: write pairs of nearly identical records where one flipped fact flips the correct answer, then train a LoRA — about 3,000 such examples took them to ~90% on their holdout vs ~66% for the base Qwen3.5-9B. Sam also suggests MiniCPM 5 2B as a promising base for this recipe.
Related guides
OpenJev RLCD: Run the Decider Locally
The deep dive on the open-source head of this landscape: OpenJev decider mode, the Mspika/decoder RLCD family, and an honest latency face-off vs a parallel LLM.
ReadJev Benchmarks
How intelligence, calibration, speed, and cost are scored — and where open models land.
ReadAwesome Jev Projects
Curated open Jev implementations, including Semif, Decider, DiffusionGemma, and Nano Jev.
ReadJev Classification Quickstart
Try the hosted Jev API with Choice, Score, and Noul before you self-host an open model.
ReadJulia-1: an openly downloadable decision model you install with pip
The newest entry in the open-weights wave — a pure-Python install with a 10-message routing duel against if-rules.
ReadClef 27B Multimodal Guide
The multimodal heavyweight that outgrew this text-only lineup: Cloudflare’s 27B Clef reads images and video in the same one-pass contract.
ReadStrands Decider Guide
The AWS Strands Agents family joins this lineup: a 1.9B pointer-head decision model installed on an 8GB laptop and tested locally, failures kept in.
ReadLiquid AI d1 guide: the newest open decision family
Liquid AI's multimodal d1-3B and d1-omni-600M tested on a MacBook — audio input included.
ReadMore video walkthroughs
- Jev Classification Quickstart: OpenRouter API, Primitives & Real Probabilities
- Jev Architecture Explained: Why 70ms Decision Models Beat LLMs for Workflow Automation
- Ultra-Fast Browser Agents with Jev: 178ms DOM Loops & Dual Model Orchestration
- Jev vs LLM: Will Jev Replace LLMs? Krish Naik's Whiteboard Explainer
- Jev Trader Tutorial: Build a Subsecond AI Trading Bot on Monad
- Jev Model Router: Build a Privacy-Gated LLM Router with Jev & OpenJev
- Jev Tutorial for Beginners: State, Questions & the TypeScript SDK
- Run Jev Locally: Kev, SemIf & Von on Your Own GPU (OpenJev Guide)
- Jev RAG Reranker: Policy-Steered Reranking for Retrieval-Augmented Generation
- When to Use Jev: An Engineer's Audit of Claims, Gates, and Failure Modes
- LangChain + Jev Integration Tutorial: Routing, Guardrails & Evals
- Jev MCP Server: Connect Jev Decisions to Claude Code & Cursor
- Jev vs Luna: Independent Benchmarks Put "Better, Faster, Cheaper" to the Test
- Jev Agent Harness: Where the Decision Gate Sits in Your LLM Loop
- Jev Playground Walkthrough: The Hotdog Lesson, Criteria, and a Four-Console Token Test
- Jev Text Classification API: Zero-Shot CLI & REST with classifier.dev
- Jev API Examples: First Request, curl & All Three Question Types
- Jev Log Triage with Expanso Edge
- Jev Lead Enrichment with Treg: ICP and Signup Scoring
- Use Jev Decision Nodes in Heym for Model Routing
- Laya Tutorial: Open-Source AI Routing With Calibrated Probabilities (Laya vs Jev Setup)
- Train Your Own Jev: Fine-Tune a Jev-Style Decision Model for $5–$17 (What You Can and Cannot Train)
- Jev Tips: 8 Best Practices for Better Decisions (State, Questions, Criteria & Thresholds)
- Jev Context Compaction: Prune AI Agent Memory Without Generative Summaries
- Jev as an LLM Judge: Confidence-Gated Cascades at 0.36% of the Cost
- TypeSafe Computer Use: Local Desktop Automation with Jev, Step by Step
- Jev Resume Screening: Build an AI Resume Evaluator with the Jev JavaScript SDK
- Jev + Claude Code Guide: Voice-Controlled Browser Automation with Typed Decisions
- Jev + Codex: Install the TypeSafe Skill and Triage a Real Gmail Inbox
- Jev vs Ollama: Can Local AI Replace Hosted Jev Without Sending Your Data Away?
- Build Your Own Jev: Train a Free Open-Source Zero-Shot Classifier (That Plays Doom)
- CUA-S1-Forms: a 706K-Parameter Jev-Like Model That Fills GUI Forms on Your CPU
- NOC/SOC Alert Triage with Jev: Rules First, One Typed Question, a Policy Gate
- Ollama Decision Models: Run tev1 and Nimble Locally (Tested on an 8 GB Card)
- Jev Guardrails in Production: A Five-Step Playbook for Decision Automation
- A Session Drift Guard for Pi Agent: Let the Jev Model Propose, Let Code Decide
- 50 Tev1 Use Cases: What a Local Decision Model Can Actually Do (Tested on an 8 GB Laptop)
- Jev, Hands-On: Where the Official Claims Meet Independent Remeasurement
- Jev Ticket Classification in a Real App: the After-Insert Hook and the Calculated Field
- OpenJev RLCD: Run the Open-Source Calibrated Decision Model Locally (Full Guide)
- Clef-Flash vs Jev: I Tested Cloudflare's Decision Model Locally in Ollama (Q4_K_M)
- Clef-Flash Tutorial: Install and Run Cloudflare's 9B Multimodal Decision Model Locally on Ubuntu
- CLM-8B: the Contrastive Decision Model That Scores 1,024 Options in 44 ms (13x Faster Than Jev)
- Nox 4B Tutorial: Run the Decision 2.0 Model Locally and Put It Through Four Real Decisions (One Ends in a Fail)
- Julia-1 Tutorial: Install the Open-Source Jev Replacement in Pure Python (and Watch It Beat If-Statements 9 to 2)
- OpenJev 0.8B on CPU: I Built a Ticket-Routing Inbox and Calibrated the Thresholds
- Jev n8n Integration: the JevGate Community Node, Step by Step (Plus a Plain-HTTP Fallback)
- NanoJev Tutorial: Install the 0.6B Open-Source Jev Replica and Watch It Route Decisions at 47 ms
- PPLX Decider Tutorial: Perplexity's Open 27B Decision Model, Its Decisions API, and a 12-Ticket Triage Run
- AutoTrust JEV-27B Tested Locally: Four Arms, 72 Cases, and One 0.969 Score That Was Wrong
- Clef 27B Locally: Watch Cloudflare’s Multimodal Decision Model Read an Image, a Video and an Uzbek Newspaper in One Pass
- Ollaya Guide: Install the "Ollama for Decision Models" Runner, Read Every Vendor-Reported Number, and Run the CPU Test It Leaves Open
- Strands Decider 2B Tutorial: Install the AWS Strands Decision Model on an 8GB Laptop — and Keep Its Failures In
- Liquid AI Open d1 Locally: d1-3B and d1-omni-600M on a MacBook Air M5 — Guardrails, Screen Checks, Voice Routing and Document Triage, Every Number Frame-Checked
- Image Decision Models for RPA: Watch Two Open Models Review an Unsigned W-8BEN With No OCR
- GLiNER2.5-Decide (340M) vs Jev (4B): Which Decision Model Actually Wins? A Frame-by-Frame Selection Guide
- Decision Models on Jetson: Jev vs Strands Decider 2B vs Laya vs d1-3B — Skill Master Scores, Thor Latency and JevBench, Every Number Frame-Checked
- Microsoft Decision-1 Tested: 146 Independent Tests, a 93% Mean, 124/125 When Confident — Every Number Frame-Checked
- Wire Jev into an Azure AI Foundry Agent as the Evaluation Layer — OpenAPI Tool, TypeSafe Connection, Triage Instructions and an Honest First-Run Failure