
learn / structured curriculum
Learn Jev: from core concepts to production decisions
Leave brittle text prompts behind. Follow a structured learning path covering model foundations, output types, server API integration, and resilient fallback boundaries.
Quick Answer: What is the Jev learning path?
Jev is a typed AI decision model designed for deterministic software logic (System One Models). Unlike conversational LLMs that produce unstructured prose, Jev evaluates context state against typed questions to return categorical decisions (Choice), scalar ratings (Score), or binary gates (Noul) alongside native confidence probabilities. Learning Jev focuses on structuring schema criteria and handling uncertainty rather than prompt hacking.
Learning Tracks
Three Recommended Learning Tracks
Select the optimal starting track based on your role and engineering objectives:
Interactive Playground & Concepts
Ideal for first-time visitors. Test state inputs, typed answers, and confidence probability bars directly in the browser with zero local setup.
- Test live inputs in Playground
- Read "What is Jev?" overview
- Compare Choice vs Score vs Noul
API Protocols & Safe Integration
Built for backend engineers adding automation to production stacks. Learn the REST contract, SDK patterns, and zod schema validation.
- Examine Jev API payload shape
- Implement TypeScript / Node.js client
- Enforce runtime schema validation
Schema Design & Fallback Safety
Crafted for architects building automated routing, moderation, and agent logic. Formalize business criteria and define fail-safe fallbacks.
- Draft criteria in Schema Builder
- Study 5 production Recipes
- Implement confidence & fallback policies
Curriculum
Core Topical Guides
Six deep dives spanning foundations, output types, dual-language setups, and safety:
What is Jev?
Differentiate decision models from generative chat tools, understanding state, questions, and typed outputs.
Read guideChoice, Score, and Noul
Select the minimal, most verifiable output primitive that matches your application next step.
Read guideJev API Reference
Inspect the JSON request payload, auth keys, multi-provider dispatch, usage accounting, and error lifecycles.
Read guideJev with Python
Execute decisions from scripts, notebooks, backend worker queues, and offline batch evaluation pipelines.
Read guideJev with TypeScript
Validate returned decisions inside Node.js, Next.js route handlers, or Cloudflare Workers safely.
Read guideConfidence and Fallback
Treat confidence as a probability metric rather than absolute truth; configure graceful human handoffs.
Read guideVideo Guides
Illustrated Video Walkthroughs
Browse YouTube walkthroughs rebuilt as step guides with checked screenshots, distinct image descriptions, and links to the matching source timestamps.
Jev Classification Quickstart: OpenRouter API, Primitives & Real Probabilities
OpenRouter integration, three typed primitives, and live probability distributions for routing, sentiment, and yes/no gates.
Read guide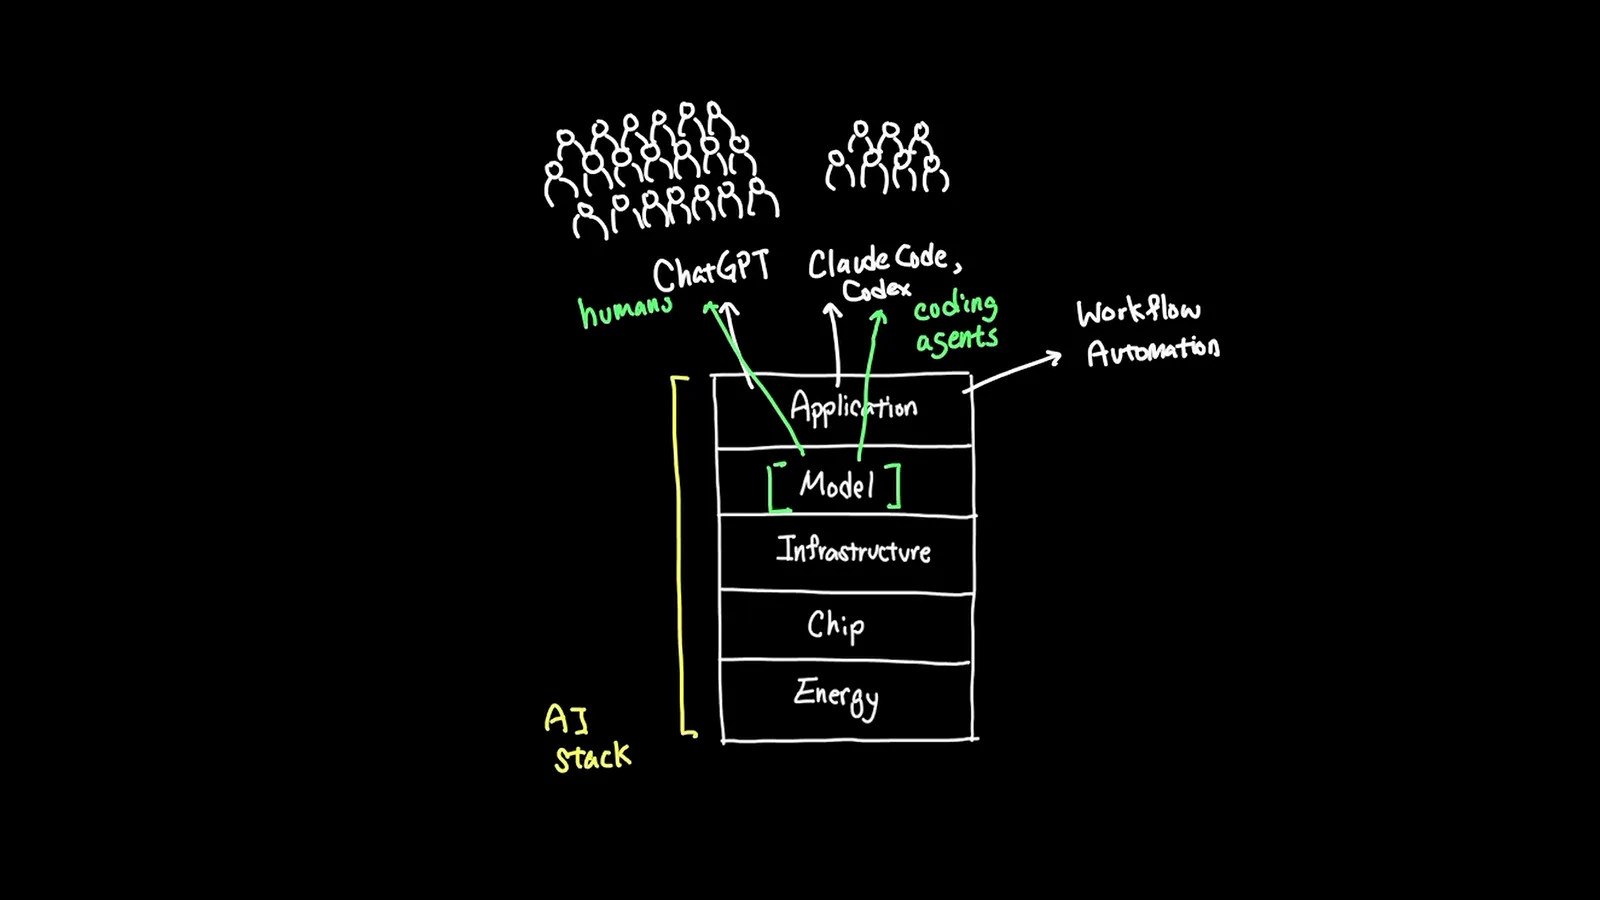
Jev Architecture Explained: Why 70ms Decision Models Beat LLMs for Workflow Automation
Why chat-optimized LLMs fail automation SLAs, and how Jev parallel sampling becomes the logic gate layer at 70–500ms.
Read guide
Ultra-Fast Browser Agents with Jev: 178ms DOM Loops & Dual Model Orchestration
DOM snapshot filtering, parallel sampler actions, RLCD calibration, and dual-model loops for sub-second browser automation.
Read guide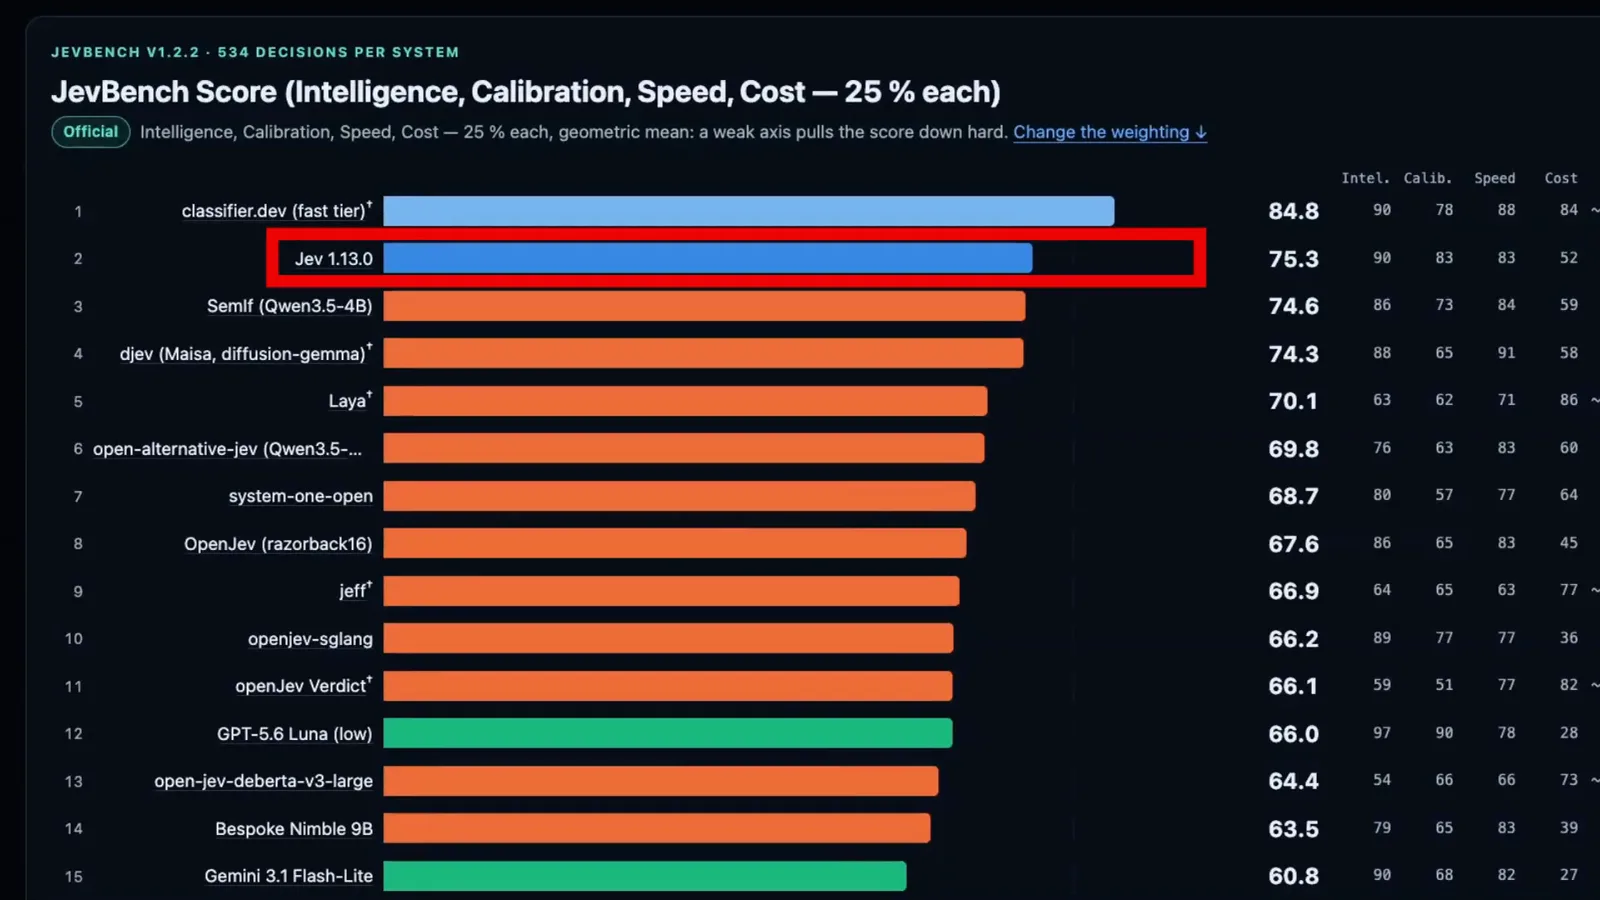
Open Jev Models Are Here: Semif, Nimble, Decider, DiffusionGemma & Laya Hands-On
A field guide to the open Jev ecosystem: how six open implementations work, where JevBench ranks them, and which one to run locally.
Read guide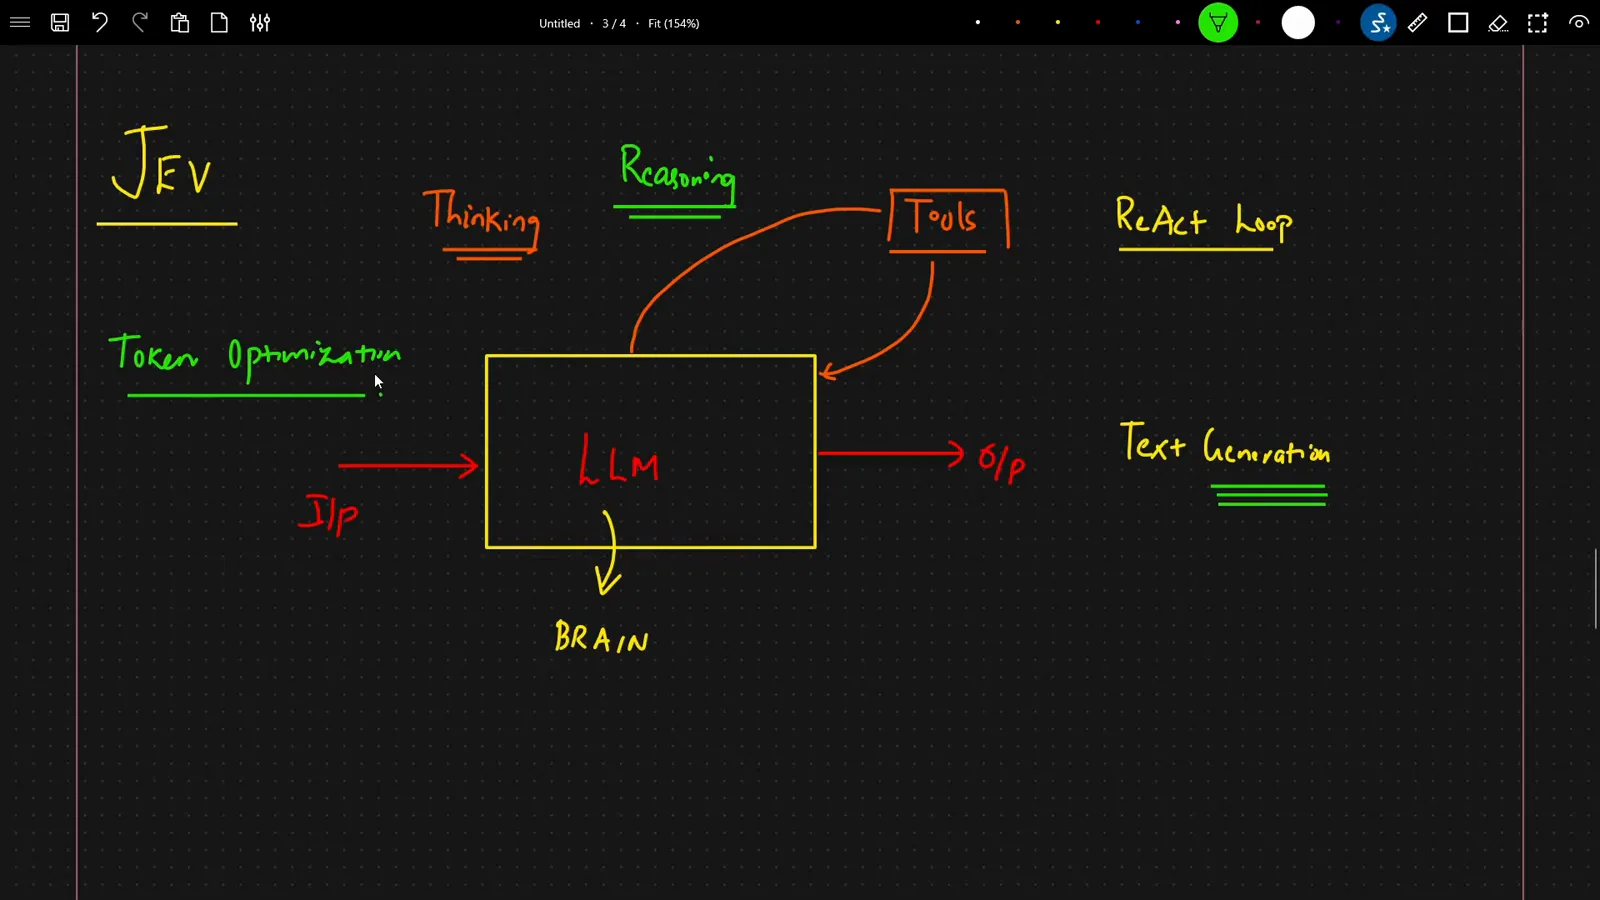
Jev vs LLM: Will Jev Replace LLMs? Krish Naik's Whiteboard Explainer
A whiteboard walkthrough of Jev vs LLM: what the ReAct loop costs in tokens, how Jev turns unstructured queries into probabilities, and the hybrid architecture that uses both.
Read guide
Jev Trader Tutorial: Build a Subsecond AI Trading Bot on Monad
A six-minute build log for Jev Trader: clone the repo, install with bun, split your RPC paths, pass the 18ms benchmark, and watch a dry-run market maker think inside the 300ms block window.
Read guide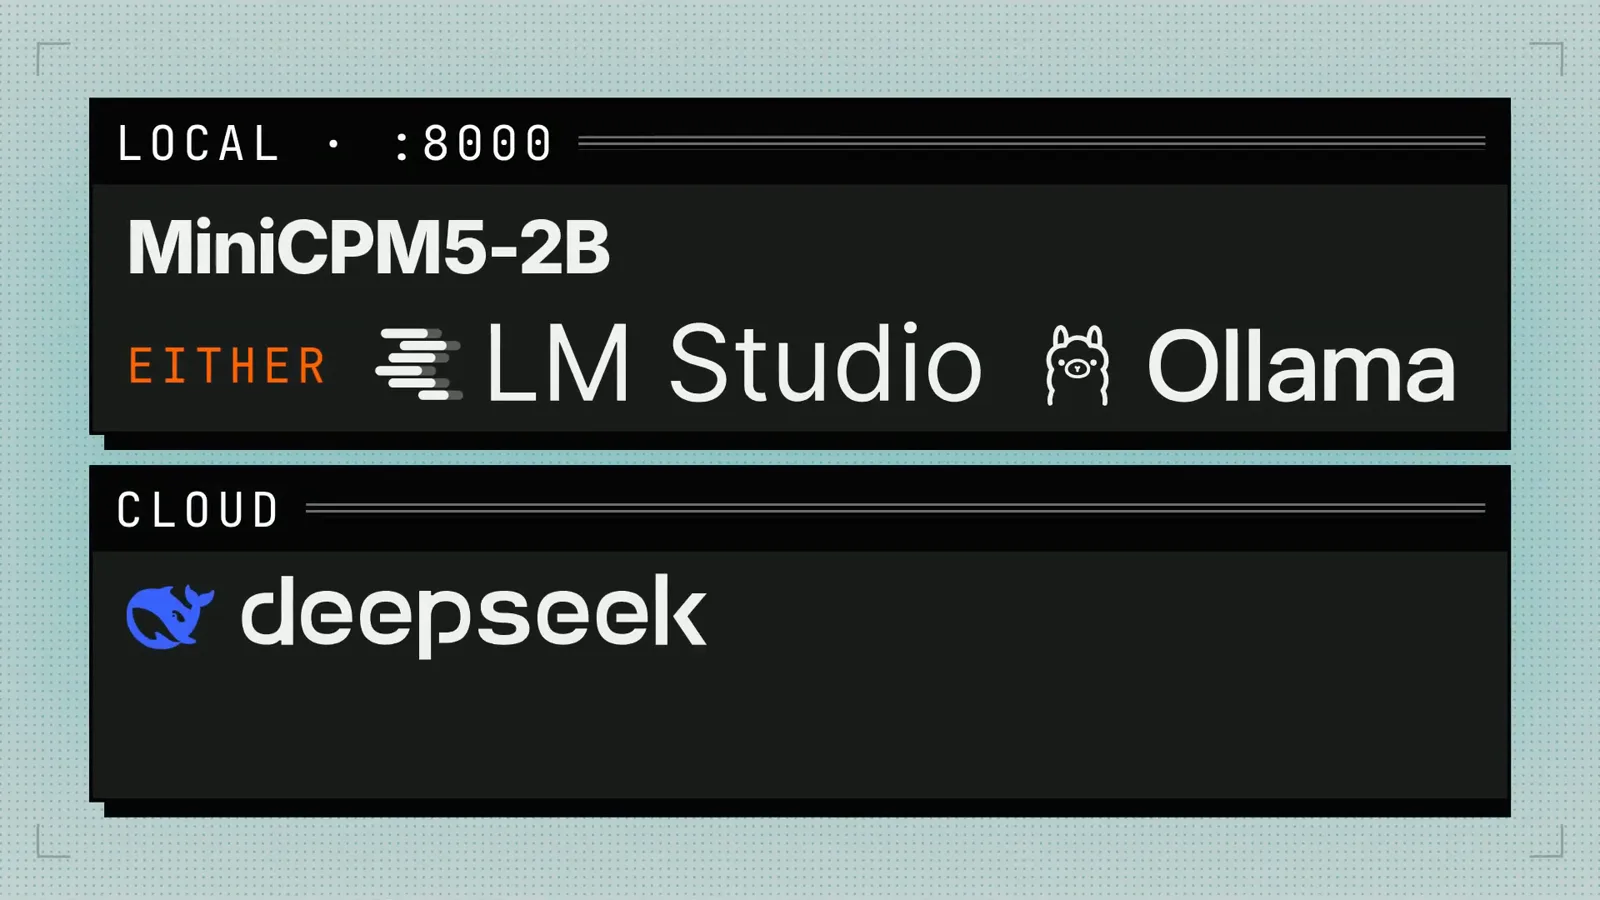
Jev Model Router: Build a Privacy-Gated LLM Router with Jev & OpenJev
A 19-minute build of a local model router: one Jev call picks the lane, gates on PII, and answers 75% of requests fully locally.
Read guide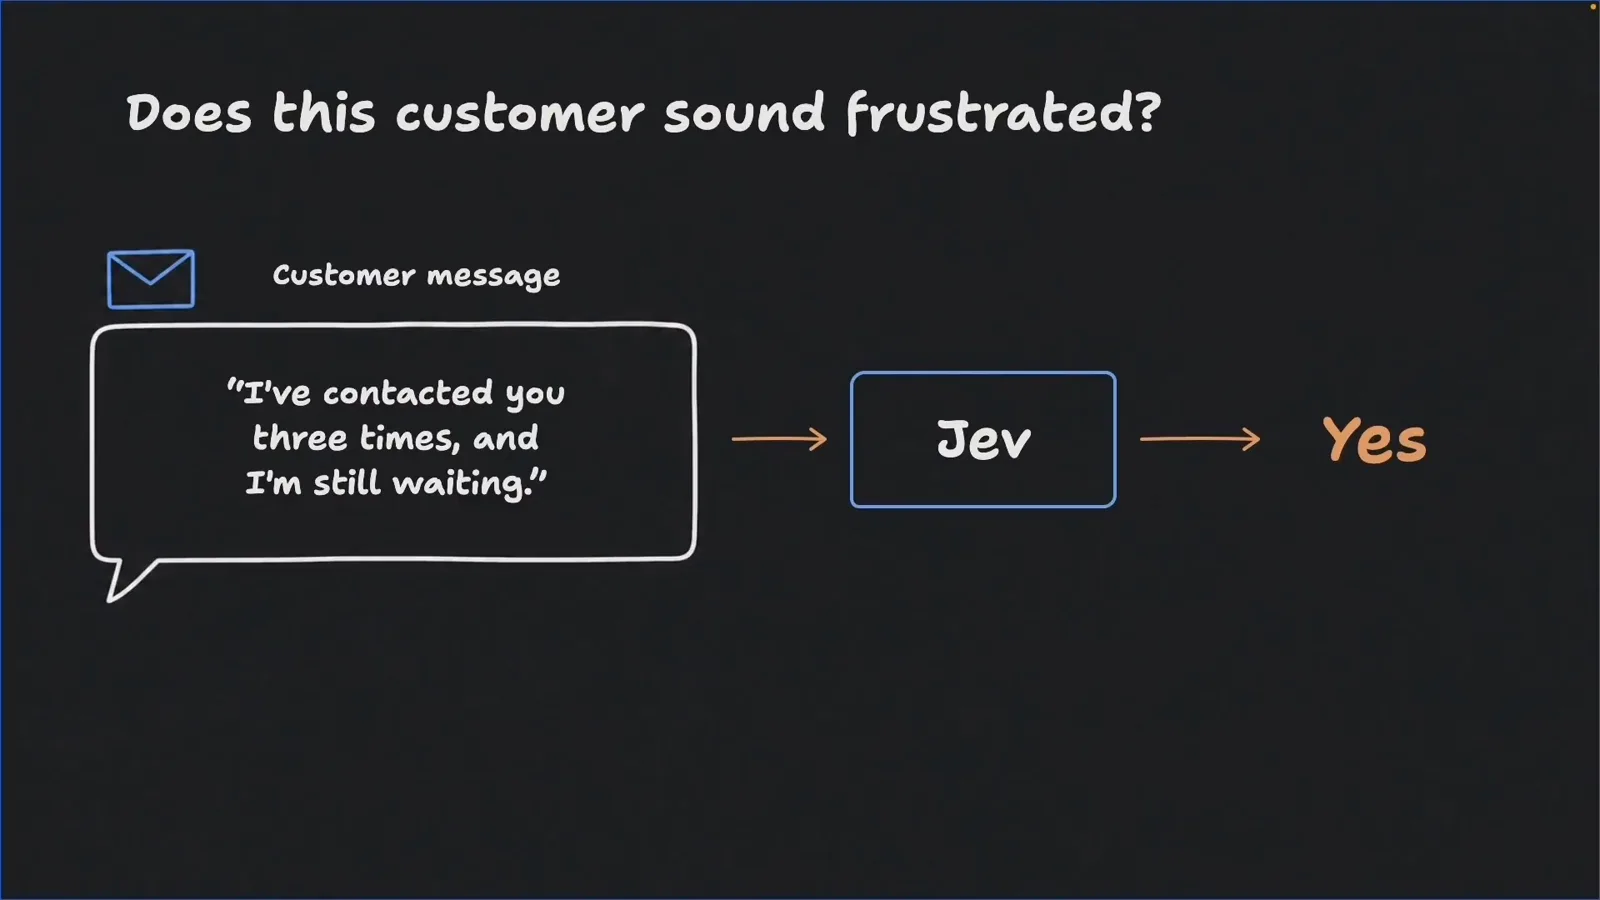
Jev Tutorial for Beginners: State, Questions & the TypeScript SDK
A 22-minute beginner course on Jev rebuilt as six illustrated steps: from the smart-if-statement idea to a working TypeScript demo.
Read guide
Run Jev Locally: Kev, SemIf & Von on Your Own GPU (OpenJev Guide)
Which open Jev-style model to run on your own hardware: Kev, SemIf, or Von — with the benchmarks and hardware tiers to choose between them.
Read guide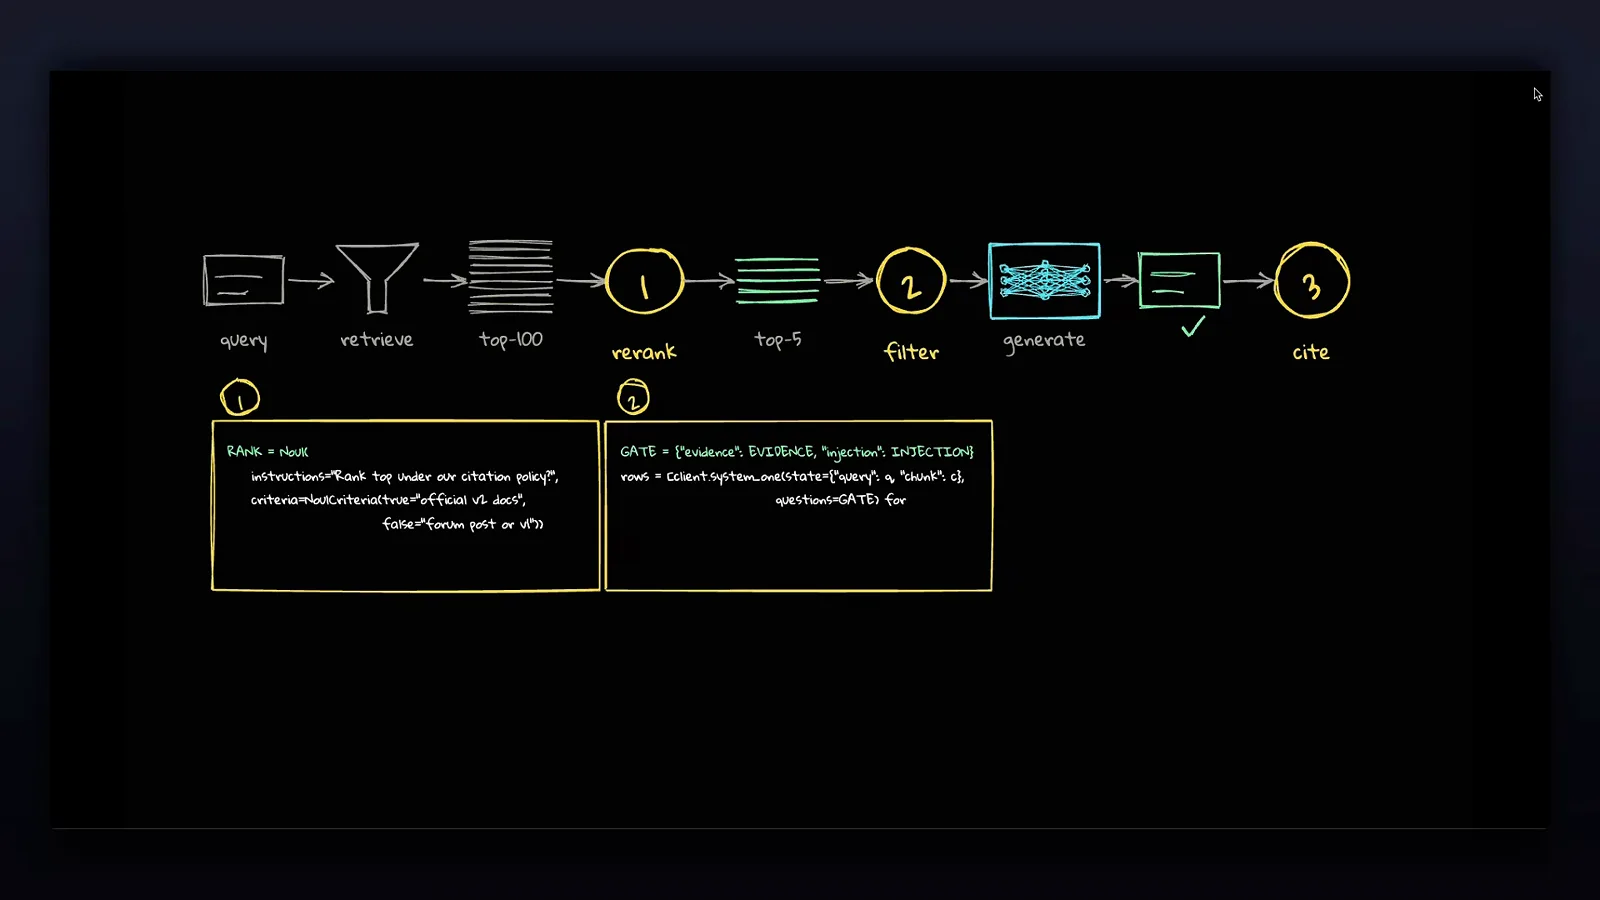
Jev RAG Reranker: Policy-Steered Reranking for Retrieval-Augmented Generation
An 11-minute tour of Jev as a policy-steered RAG reranker: executable criteria cut top-100 to top-5, rankings follow policy changes, and top-1 accuracy climbs from 21% to 54% at a flat cost.
Read guide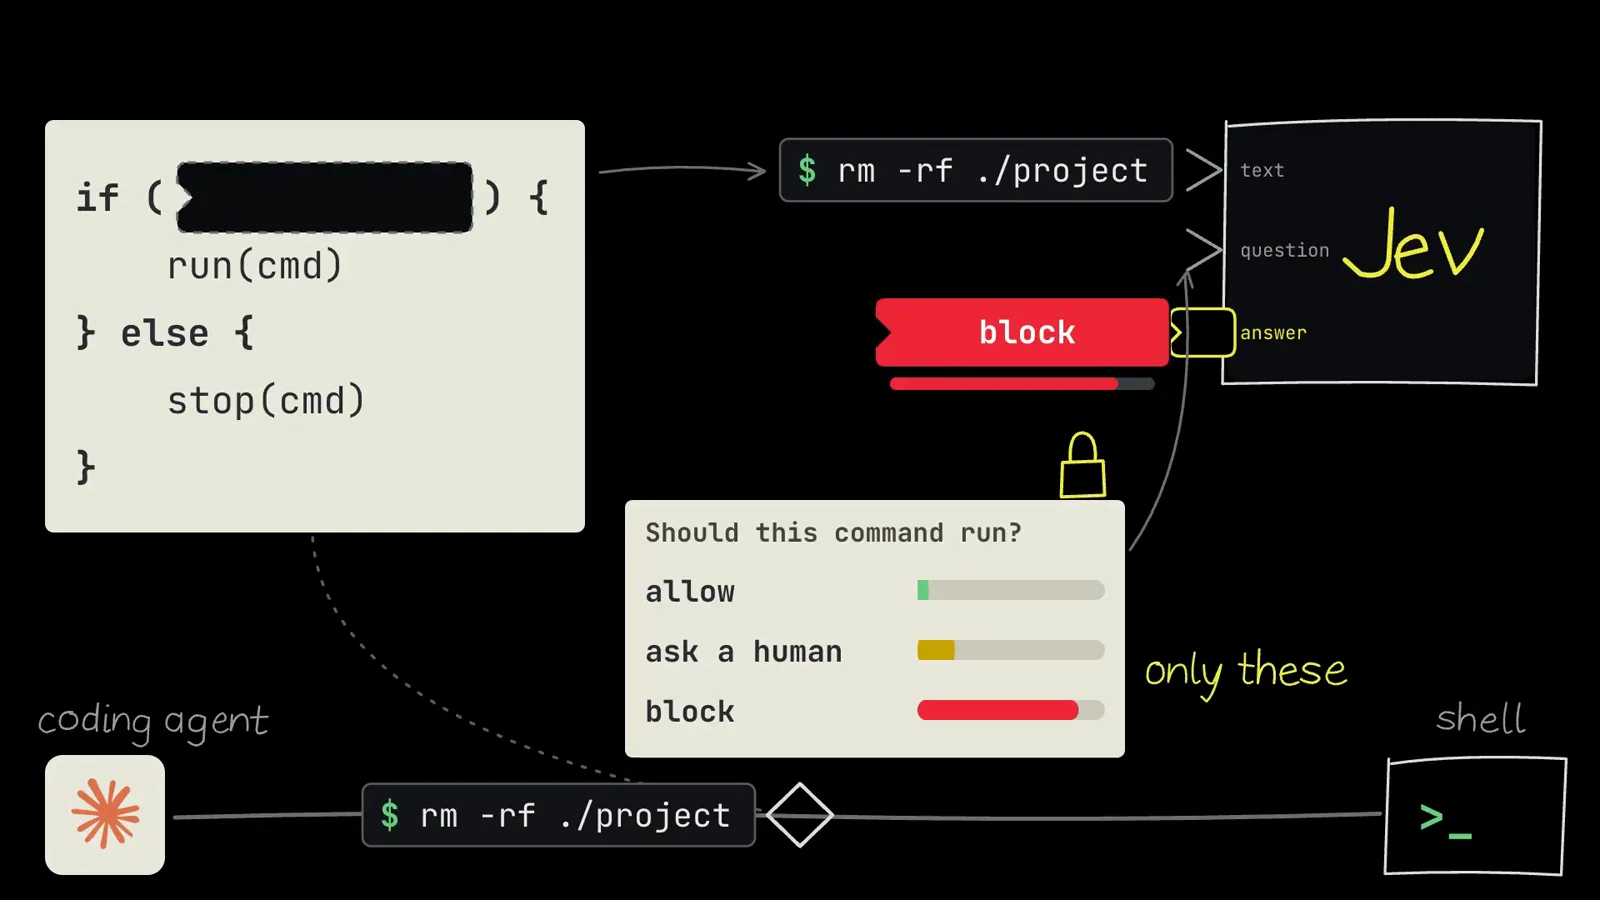
When to Use Jev: An Engineer's Audit of Claims, Gates, and Failure Modes
A 16-minute engineering audit: Jev's wild multipliers shrink to 3x faster and 12x cheaper in independent tests, and narrow checks beat broad prompts.
Read guide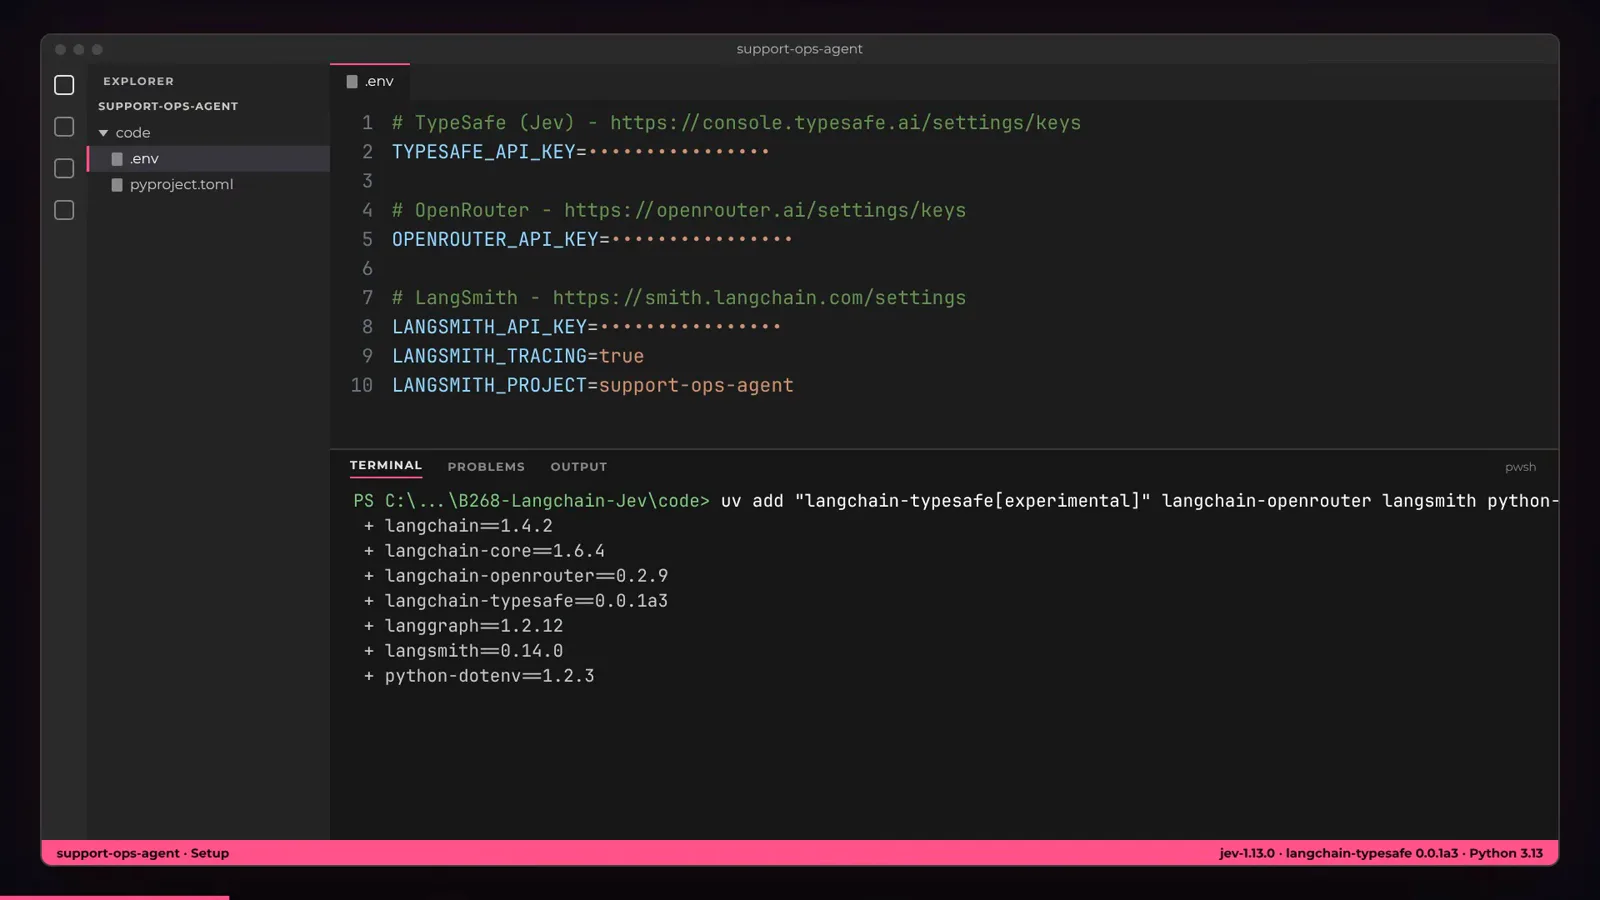
LangChain + Jev Integration Tutorial: Routing, Guardrails & Evals
A 17-minute LangChain integration: one typed Jev invoke, three middleware (triage, router, guard), and a judge that matches Sonnet verdicts for about 1/230th of the price.
Read guide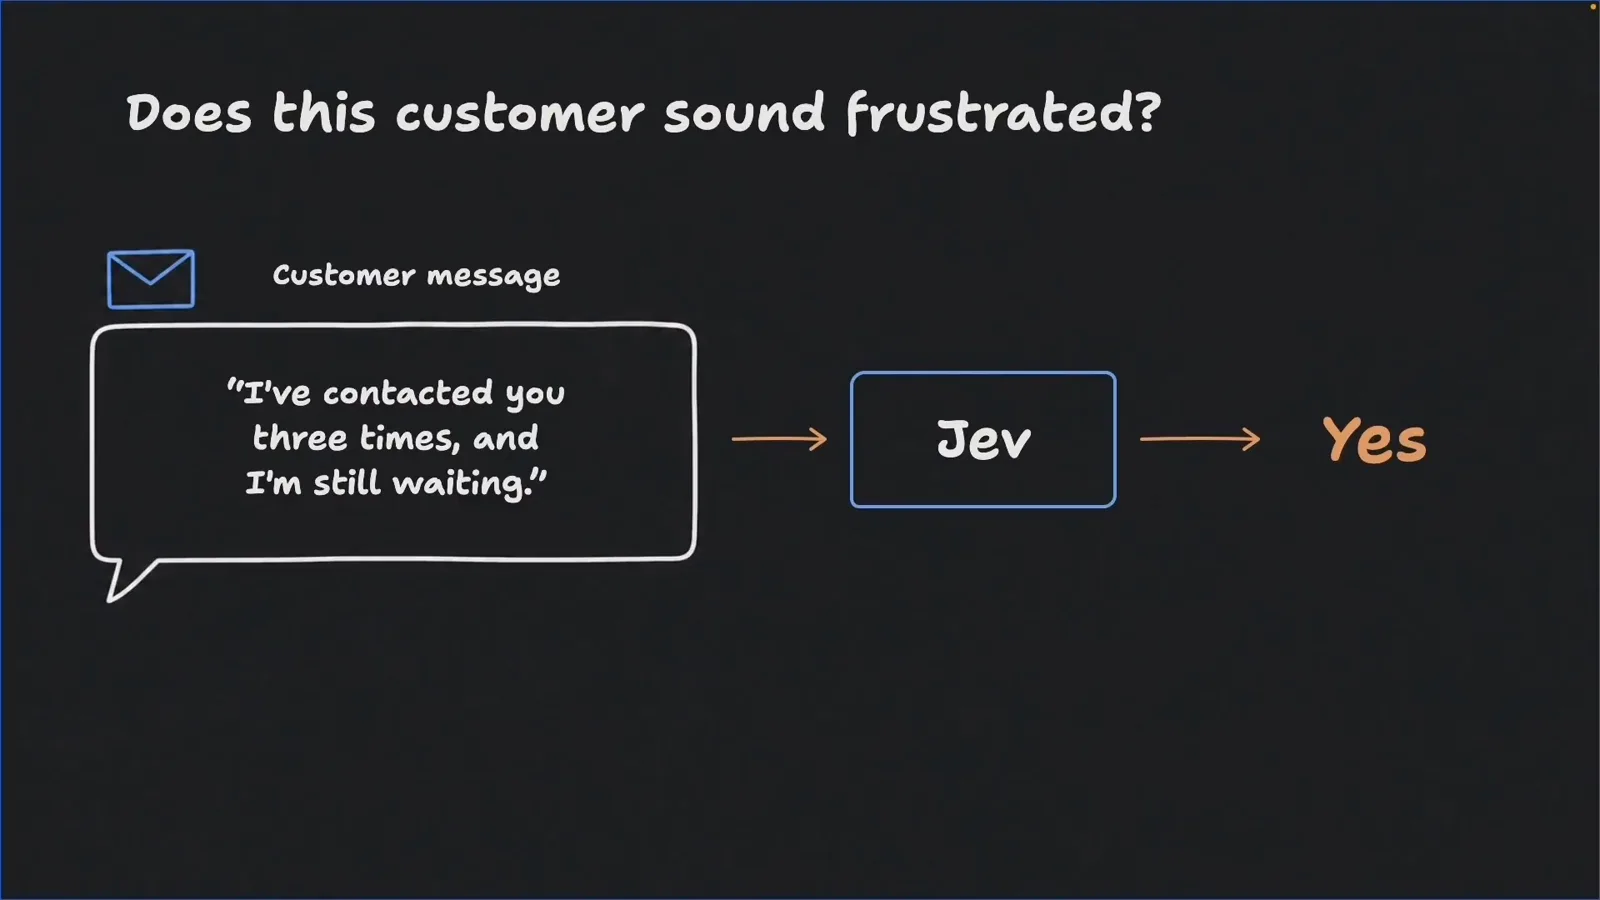
Jev MCP Server: Connect Jev Decisions to Claude Code & Cursor
No official Jev MCP server exists — TypeSafe ships an Agent Skill and the community built 20+. Master the state + typed-question layer they all wrap, in 22 minutes of frames.
Read guide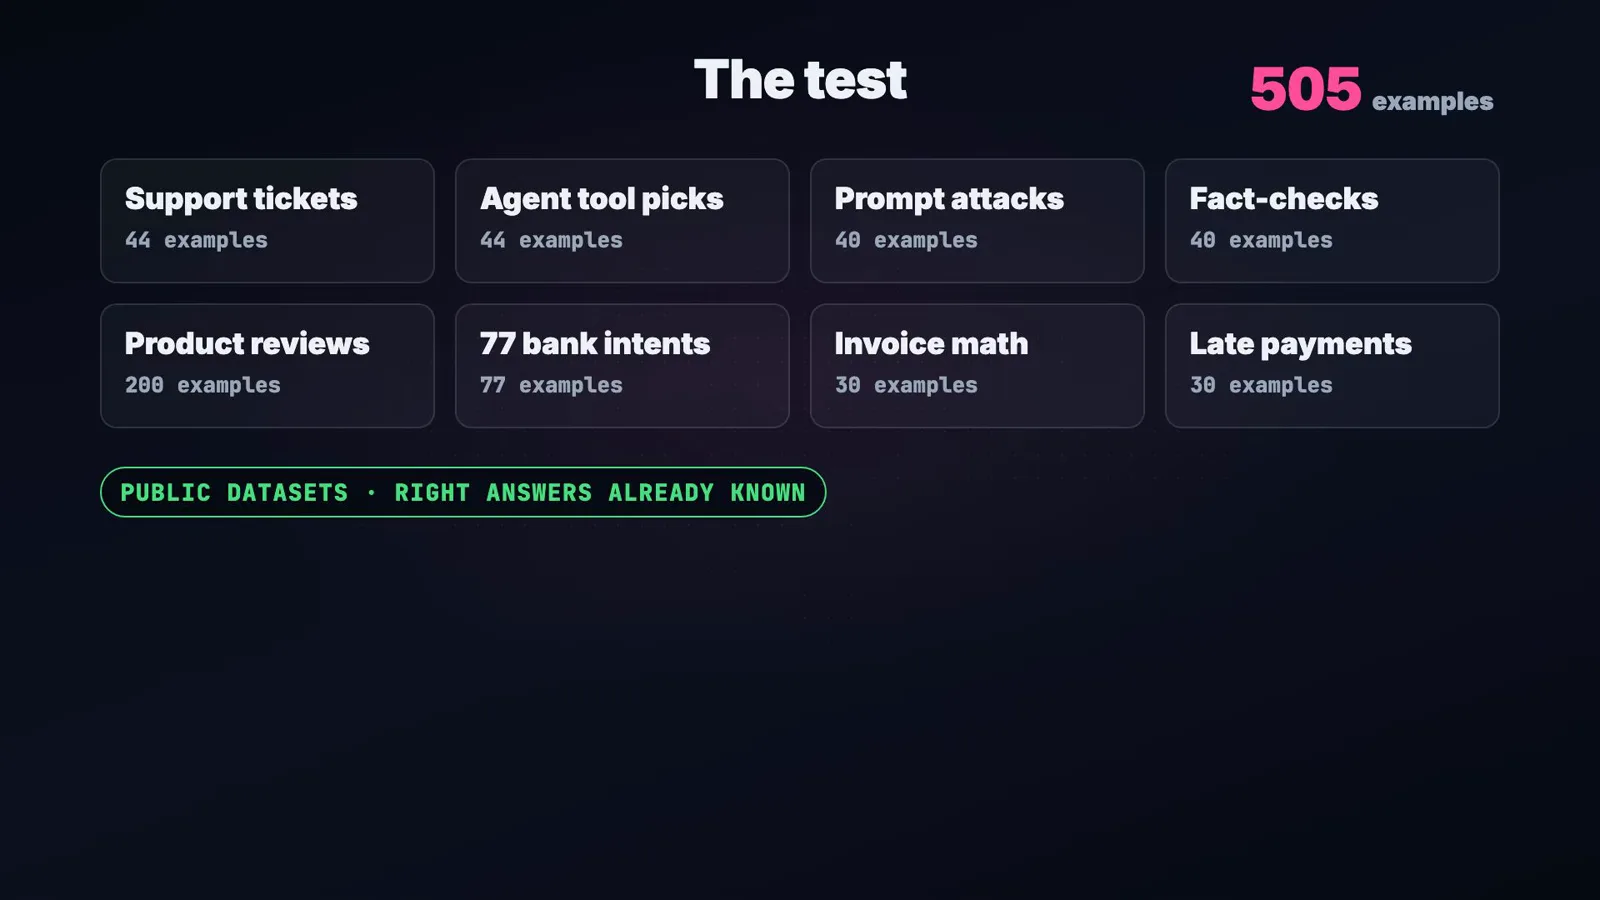
Jev vs Luna: Independent Benchmarks Put "Better, Faster, Cheaper" to the Test
Two independent benchmarks — 505 graded decisions and 200 price guesses — put Jev head-to-head with GPT-5.6 Luna, Terra, and Claude Opus 5.5.
Read guide
Jev Agent Harness: Where the Decision Gate Sits in Your LLM Loop
Where Jev sits in an agent harness: route before the run, guard every tool call, let the LLM write — with the measured gains and the accuracy caveats.
Read guide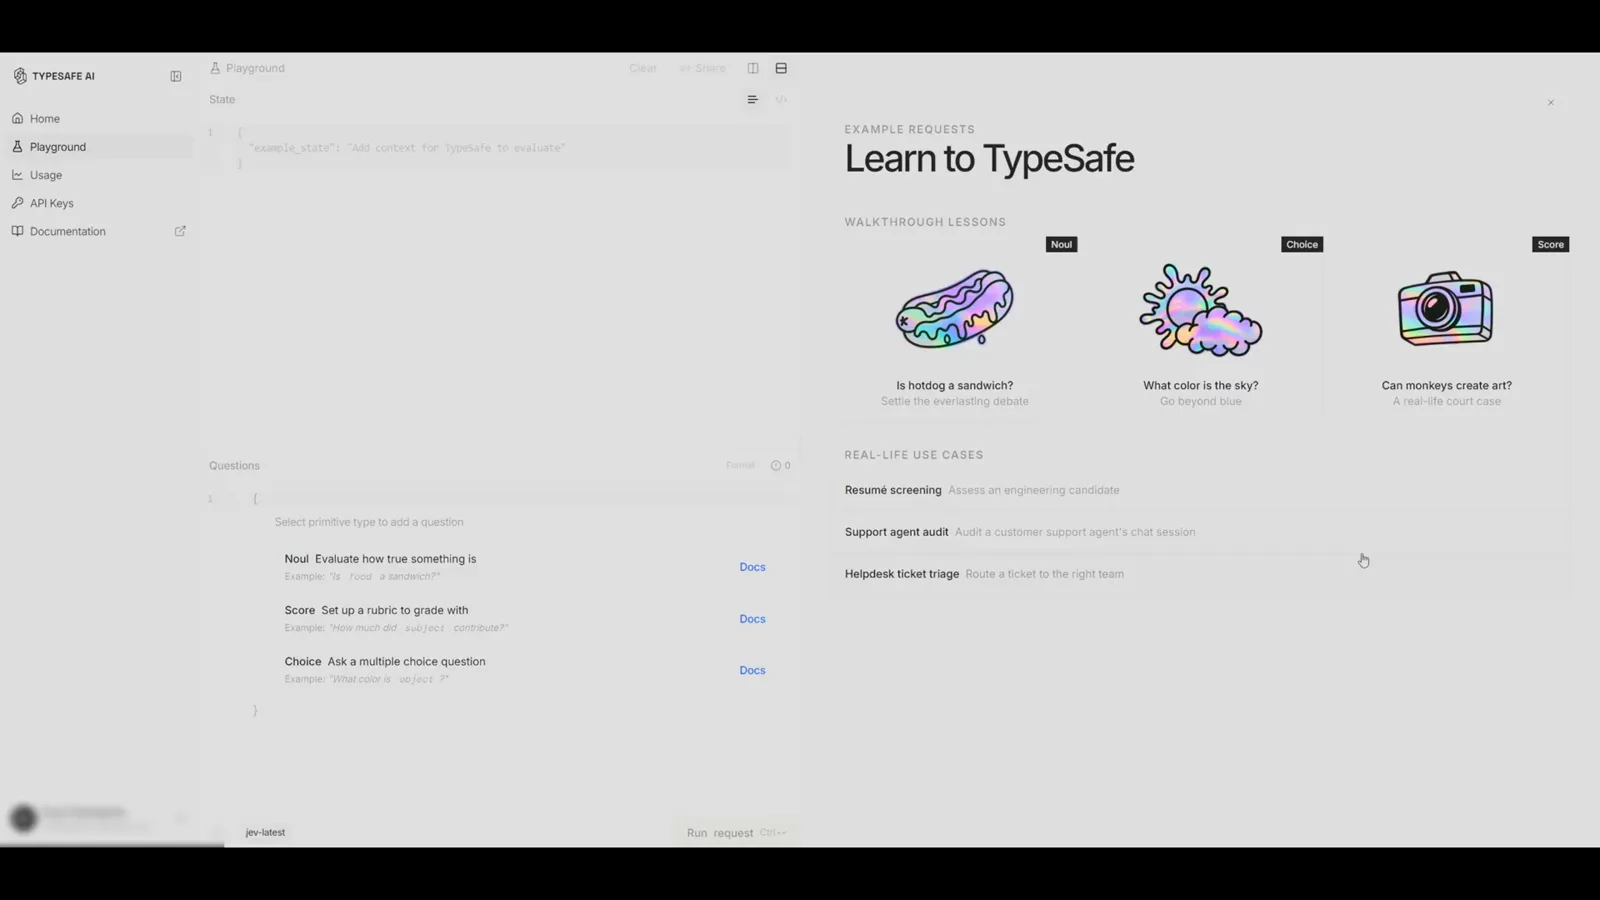
Jev Playground Walkthrough: The Hotdog Lesson, Criteria, and a Four-Console Token Test
A screen-only walkthrough of the TypeSafe console playground: learn the three primitives, calibrate the hotdog lesson, build a cube-rule Choice question, then race the same prompt against GPT-5.6 Luna, Sonnet 5, and Gemini 3.7 Flash.
Read guide
Jev Text Classification API: Zero-Shot CLI & REST with classifier.dev
Install classifier.dev, classify bulk text files from the terminal, gate on confidence, then call the REST API and read label, confidence, scores, and ms.
Read guide
Jev API Examples: First Request, curl & All Three Question Types
Copy-paste Jev API examples from a real working session: curl, Python requests, JavaScript fetch — one state, typed questions, calibrated answers.
Read guide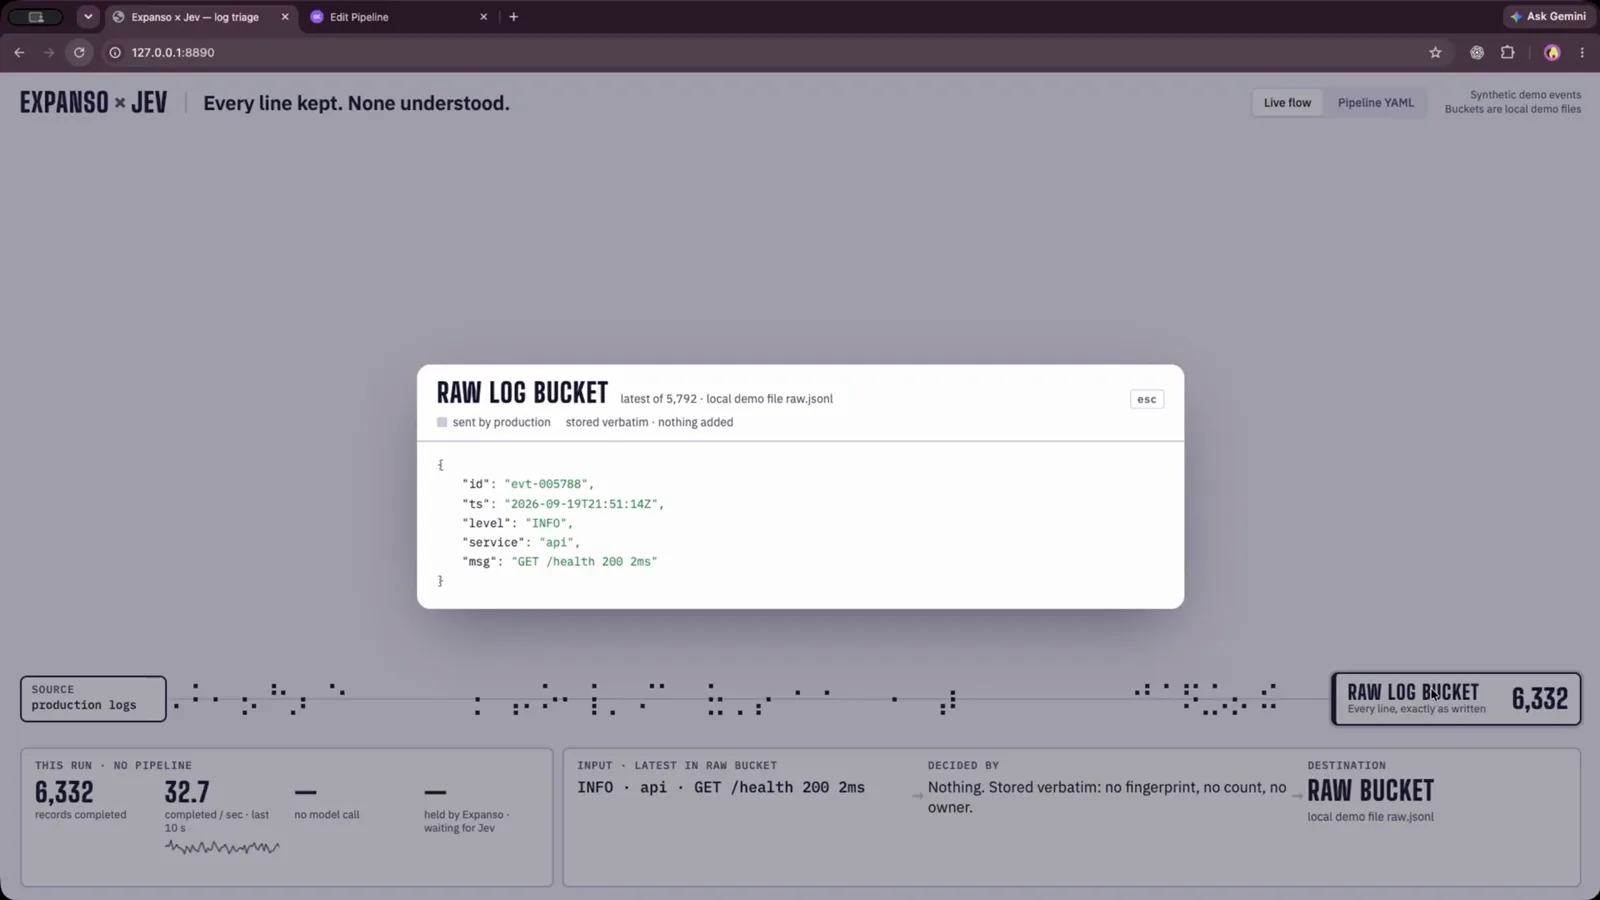
Jev Log Triage with Expanso Edge
A screen-by-screen Expanso Edge and Jev log-triage demo using synthetic events and local demo files, with deterministic filtering, selective decisions, notification, review, and outage recovery.
Read guide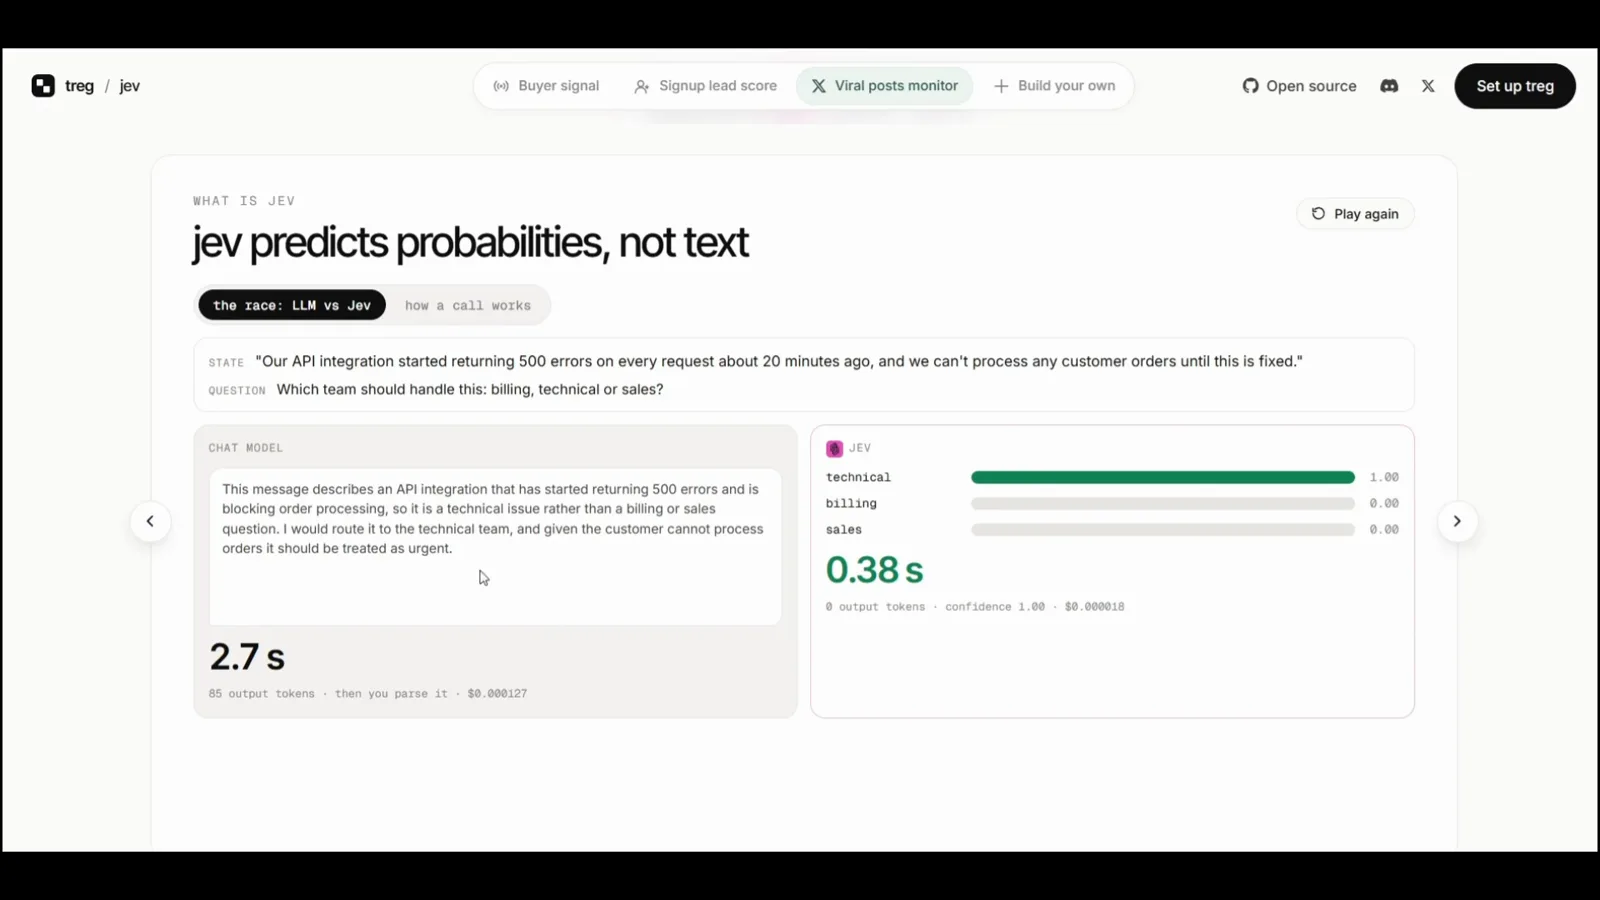
Jev Lead Enrichment with Treg: ICP and Signup Scoring
Turn LinkedIn engagement and signup data into typed Jev decisions inside Treg, with an explicit caveat that the video’s figures are creator-reported demos.
Read guide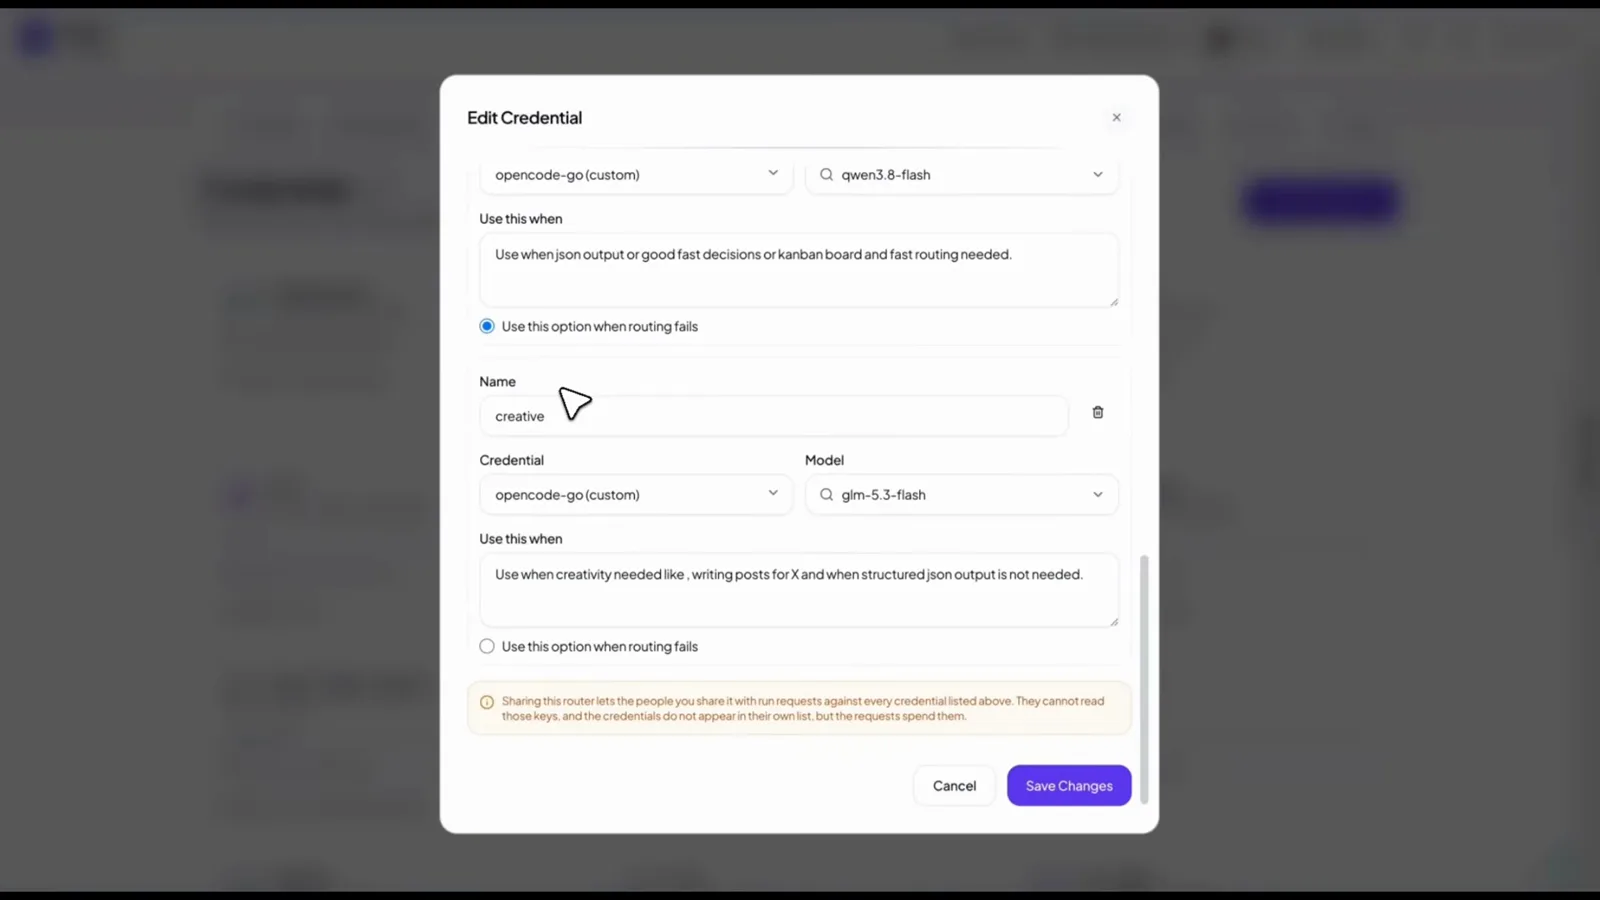
Use Jev Decision Nodes in Heym for Model Routing
A screen-by-screen Heym workflow guide: configure routing options, test a Jev Noul language decision, and review model choices in a trace.
Read guide
Laya Tutorial: Open-Source AI Routing With Calibrated Probabilities (Laya vs Jev Setup)
A visual, step-by-step Laya tutorial built from Alex Hitt’s 9-minute screen explainer: shape the state-plus-questions payload, keep option sets inside the 192-token budget, calibrate to ECE 0.081, gate actions at 0.85 confidence, route non-English text, and preload both checkpoints onto the GPU.
Read guide
Train Your Own Jev: Fine-Tune a Jev-Style Decision Model for $5–$17 (What You Can and Cannot Train)
A visual, step-by-step guide to training your own Jev-style decision model, built around TerraNet’s 4-minute fine-tuning explainer and cross-checked against two real replicas — Hassan’s $17 Together AI run and CoderOne’s $4.17 Modal run — covering what can and cannot be fine-tuned, where the 38,000 training questions come from, how to fit calibration honestly, and when the pipeline pays off.
Read guide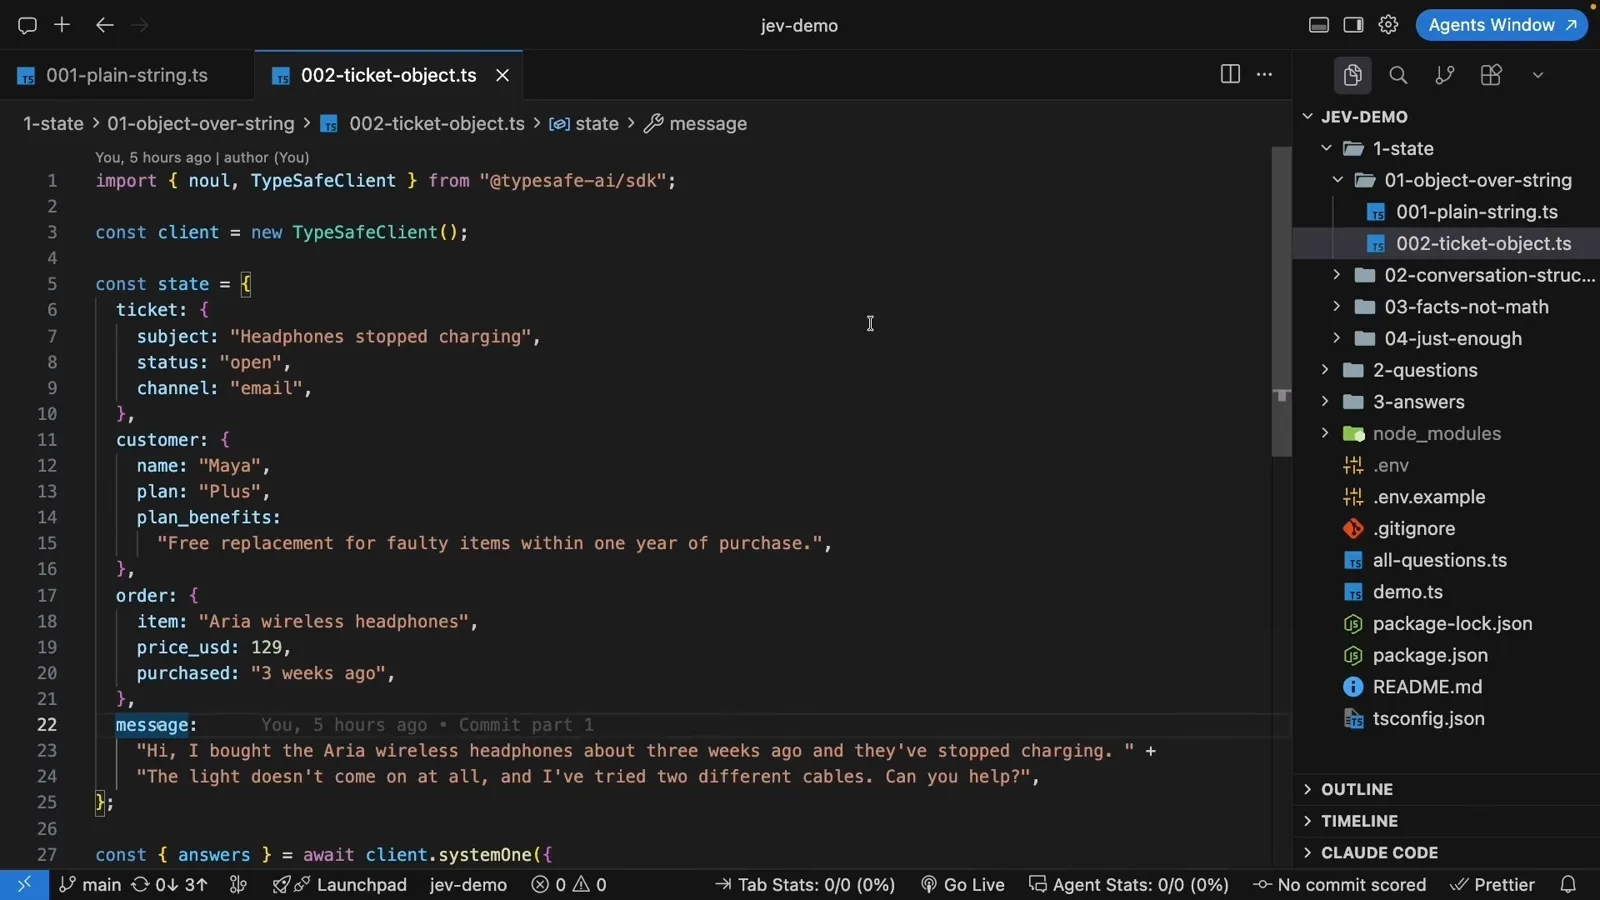
Jev Tips: 8 Best Practices for Better Decisions (State, Questions, Criteria & Thresholds)
Eight field-tested Jev tips distilled from Codevolution’s 43-minute best-practices deep dive: shape the state as an object, let your code compute facts before the call, send only the context the question needs, choose Noul vs Choice vs Score by whether you want a verdict or a ranking, define every answer with criteria (and per-level signals for sarcasm), batch independent questions into one request, and set a different confidence threshold for every action your code can take.
Read guide
Jev Context Compaction: Prune AI Agent Memory Without Generative Summaries
fast-jev-compaction replaces generative self-compaction with typed Jev evaluation: anchor the edges of the conversation, compress the middle below a 25,000-token state cap, and let two yes/no questions per tool call decide what is verbatim-kept, truncated, or deleted.
Read guide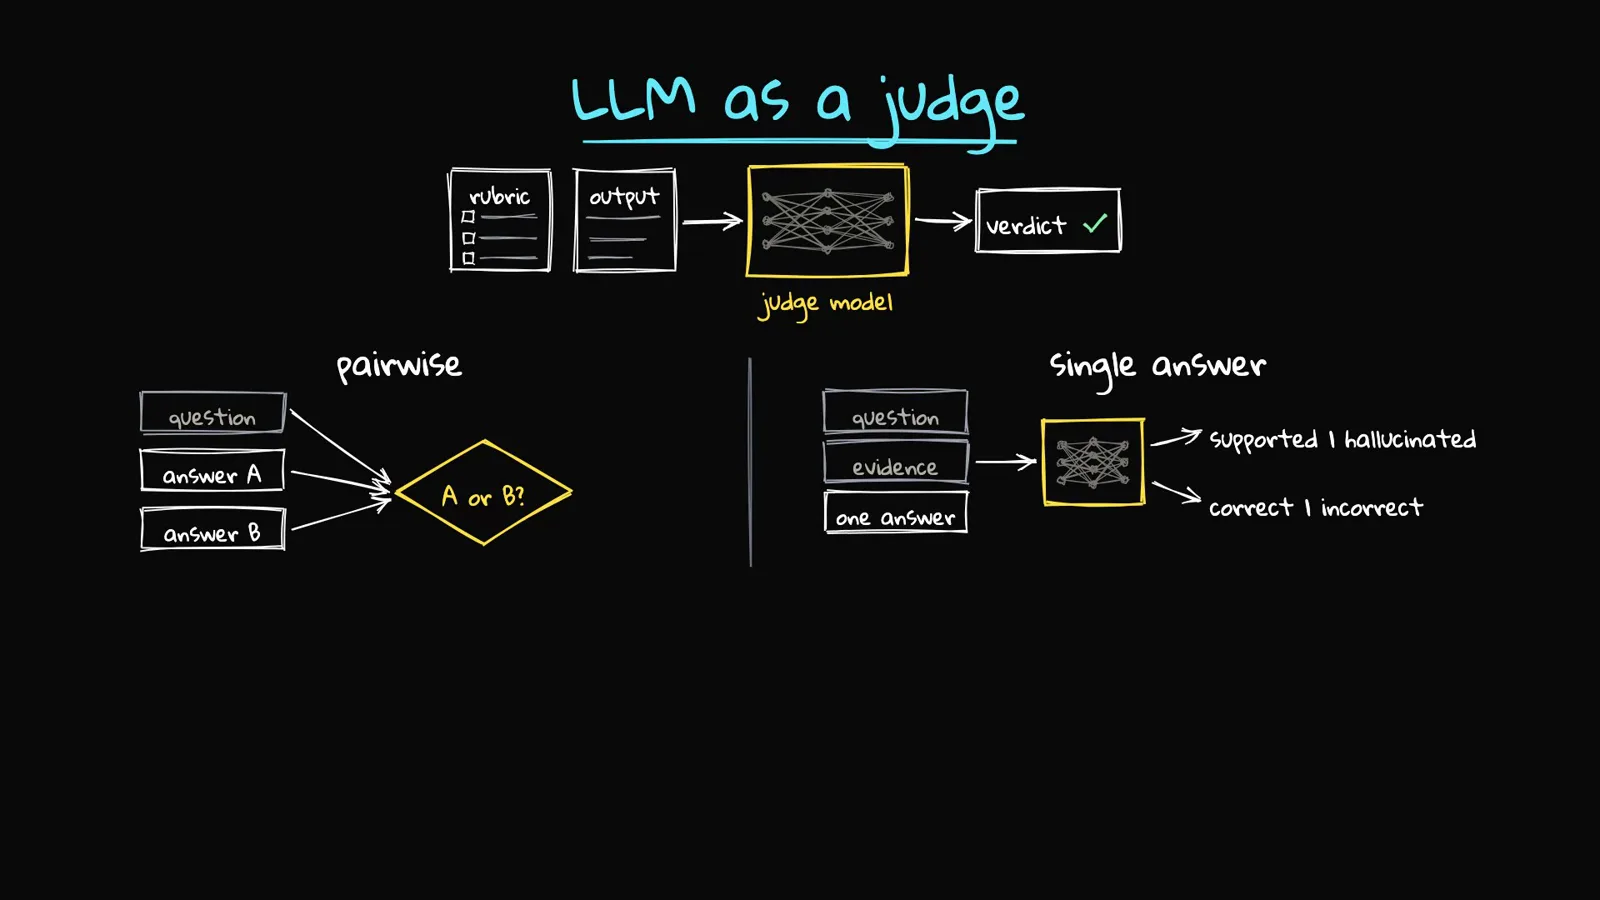
Jev as an LLM Judge: Confidence-Gated Cascades at 0.36% of the Cost
A Carnegie Mellon study put Jev 1.13 up against 16 judges: within about 3 points of GPT-6 on ordinary preference and grounded factuality at $0.044 versus $12.18 per 1,000 judgments — and its confidence is honest enough to gate a cascade that keeps 99% of the strong judge’s accuracy at 57% of the fee.
Read guide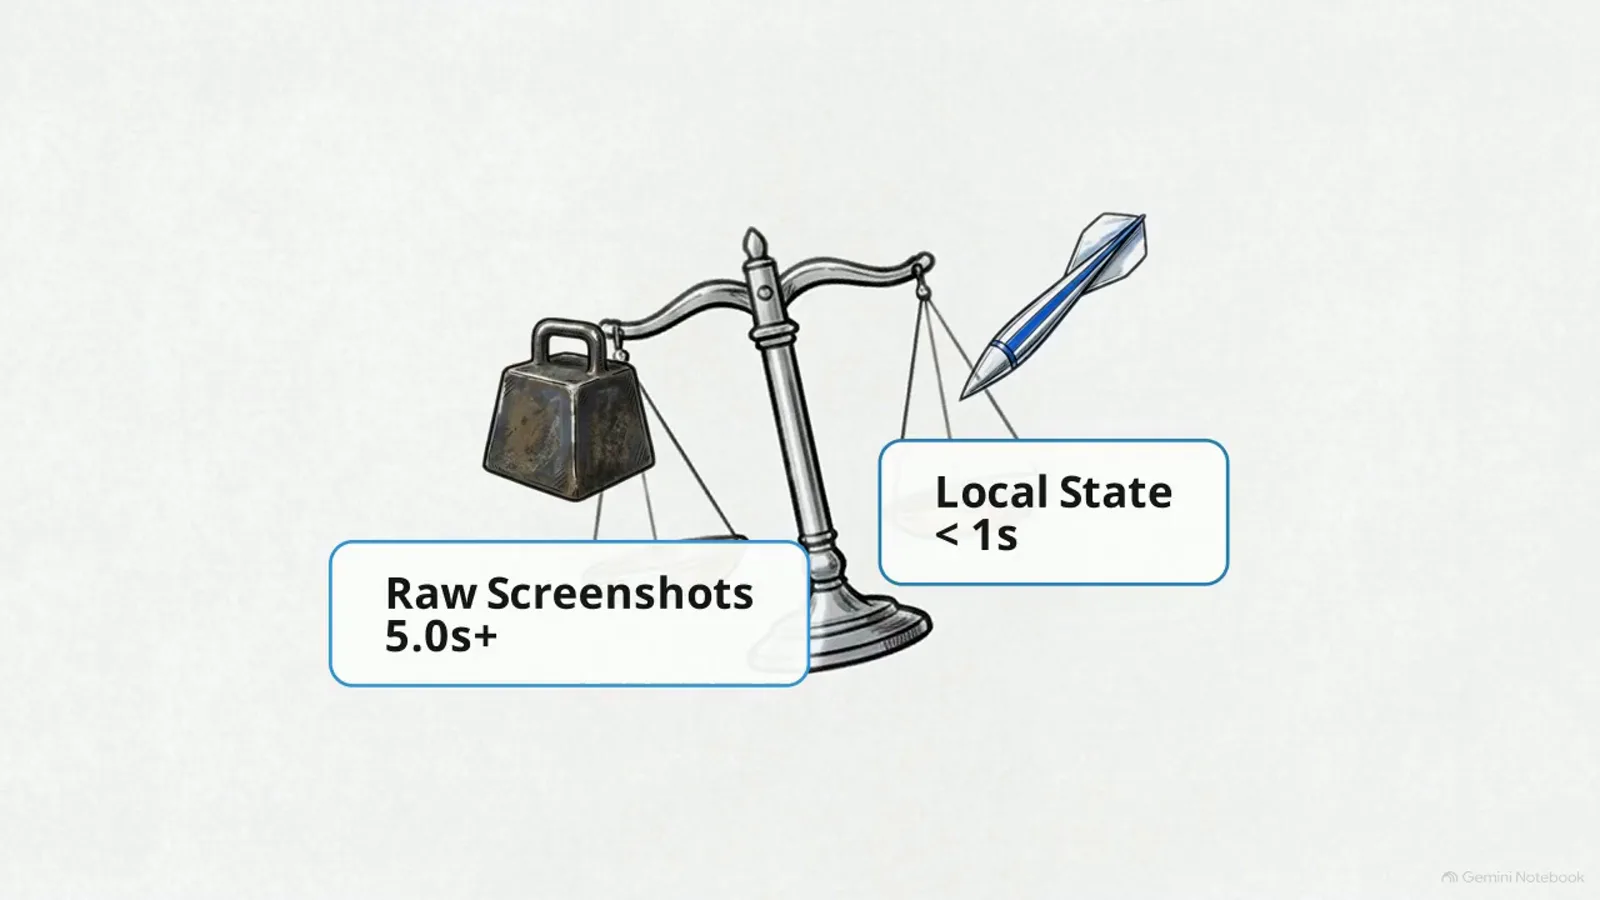
TypeSafe Computer Use: Local Desktop Automation with Jev, Step by Step
typesafe-computer-use replaces multi-megabyte screenshot calls to a frontier model with local Vision OCR + accessibility-tree parsing and one Jev classification per step — $0.0002 and under a second per decision, with a hard candidate-action list and hardware-level stops.
Read guide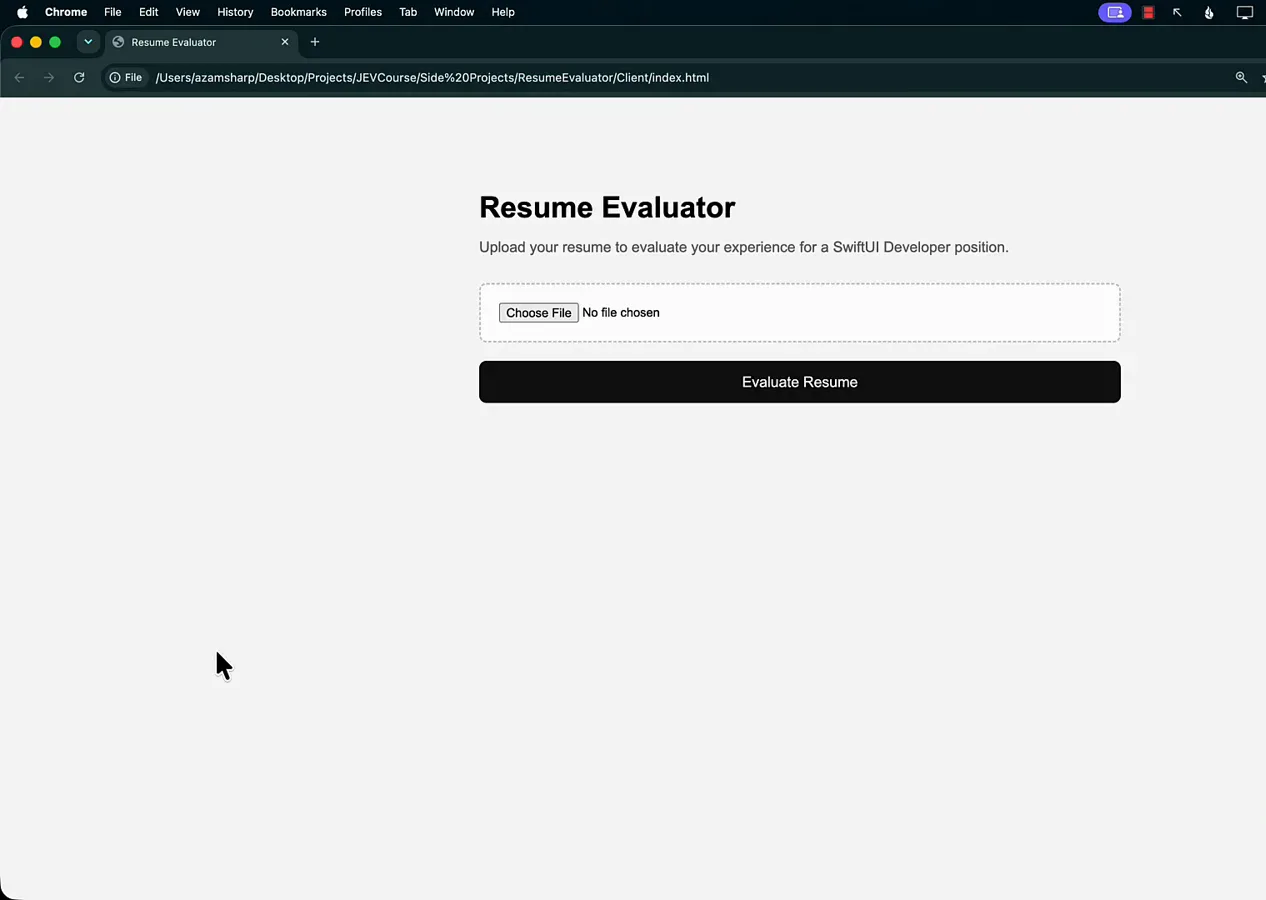
Jev Resume Screening: Build an AI Resume Evaluator with the Jev JavaScript SDK
A 6:48 demo of Jev resume screening: an Express endpoint extracts the text from an uploaded PDF, ten typed questions (noul, choice, score) grade the candidate for a Senior SwiftUI Developer role, and a mapper converts noul probabilities into a Yes/No skills card with confidence percentages and a match verdict.
Read guide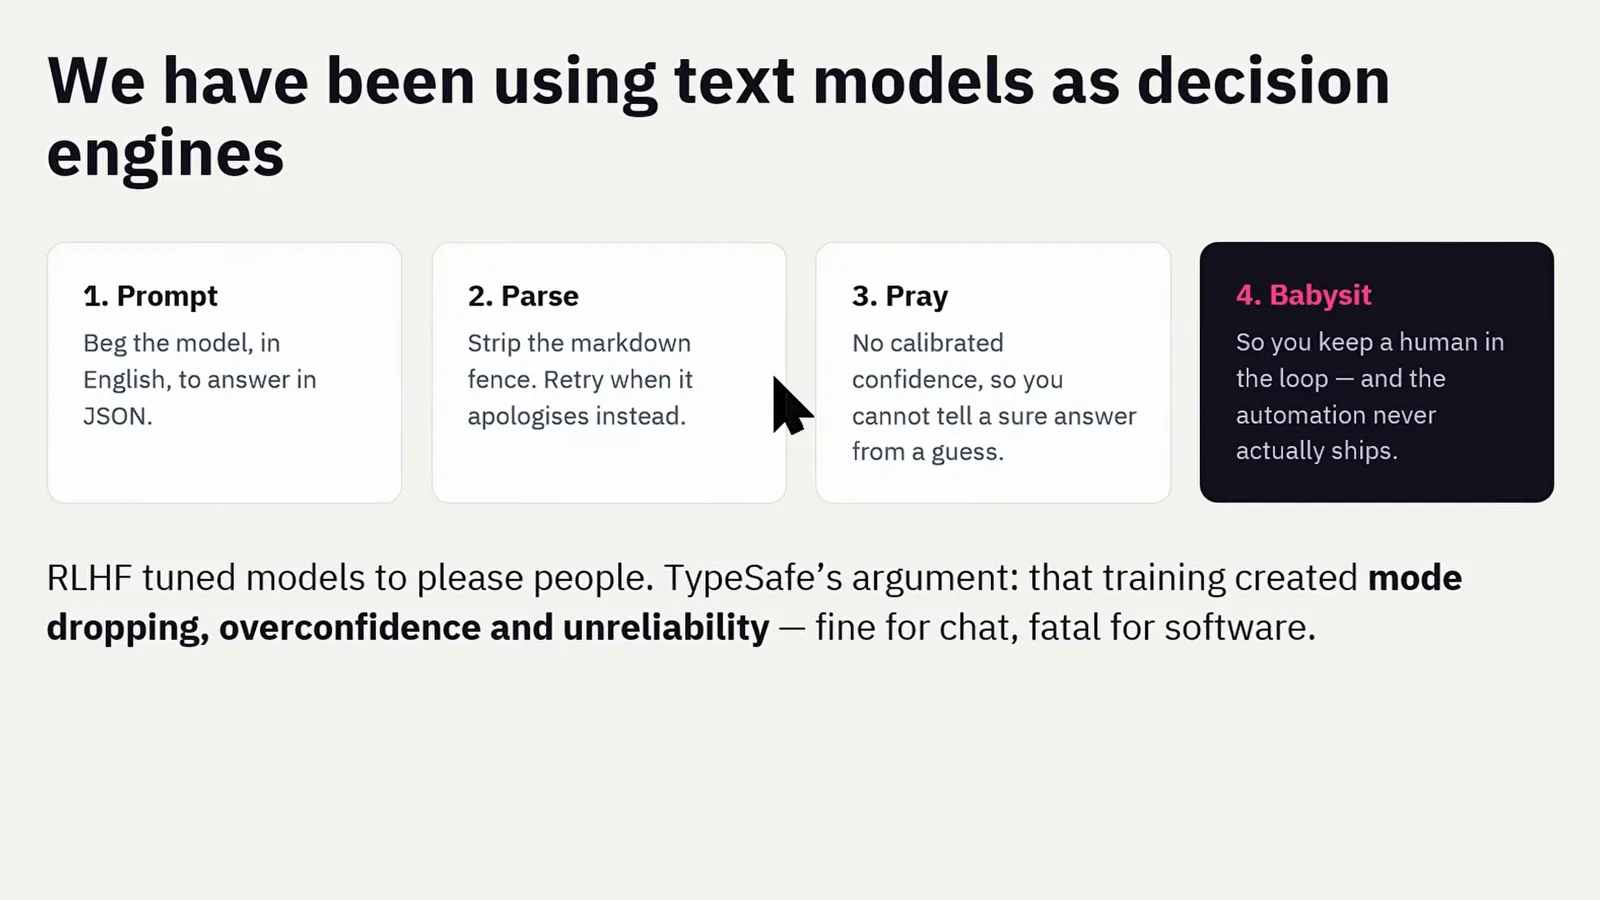
Jev + Claude Code Guide: Voice-Controlled Browser Automation with Typed Decisions
An 18:25 agent-integration walkthrough: why text LLMs fail as decision engines, how Jev’s three typed primitives route a Stripe ticket with visible confidence, what decisions cost at $0.042/M input tokens, and how a voice-chrome project pipes mic → Whisper → Jev → Playwright so a spoken “Click on videos” clicks the right link at P=0.78.
Read guide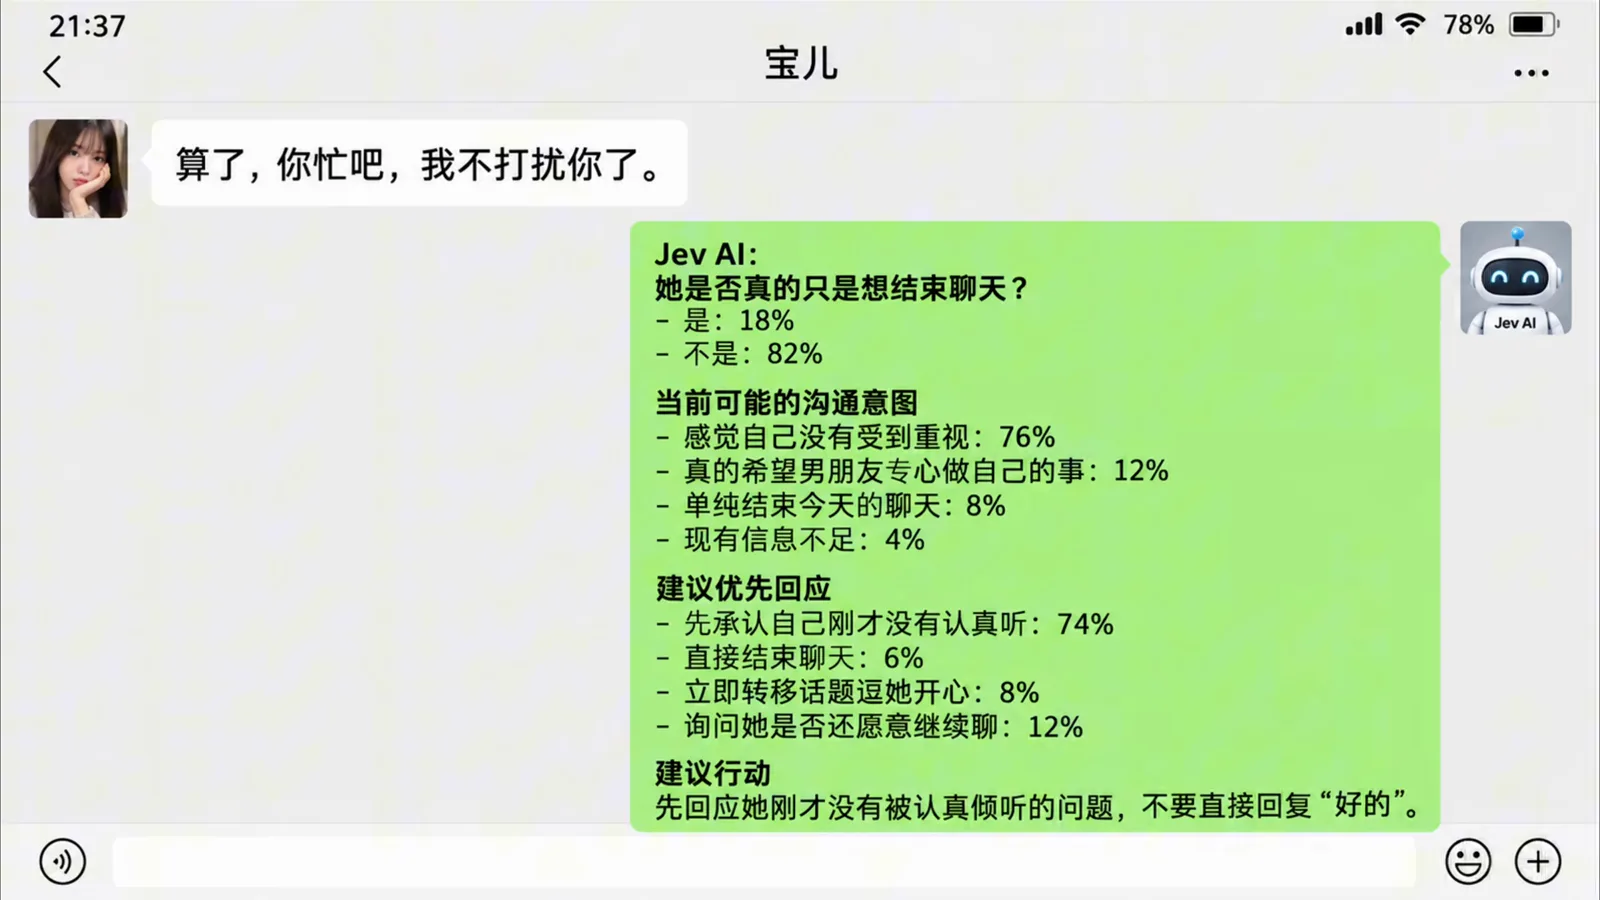
Jev + Codex: Install the TypeSafe Skill and Triage a Real Gmail Inbox
The typesafe-ai/skills repo teaches a coding agent when and how to call Jev. This walkthrough installs it into Codex, drills the three question types in the Playground, sets TYPESAFE_API_KEY, then lets Codex read 30 real Gmail messages and priority-sort them — 1.19 seconds of that work was the Jev API; the other minute and a half was the agent itself.
Read guide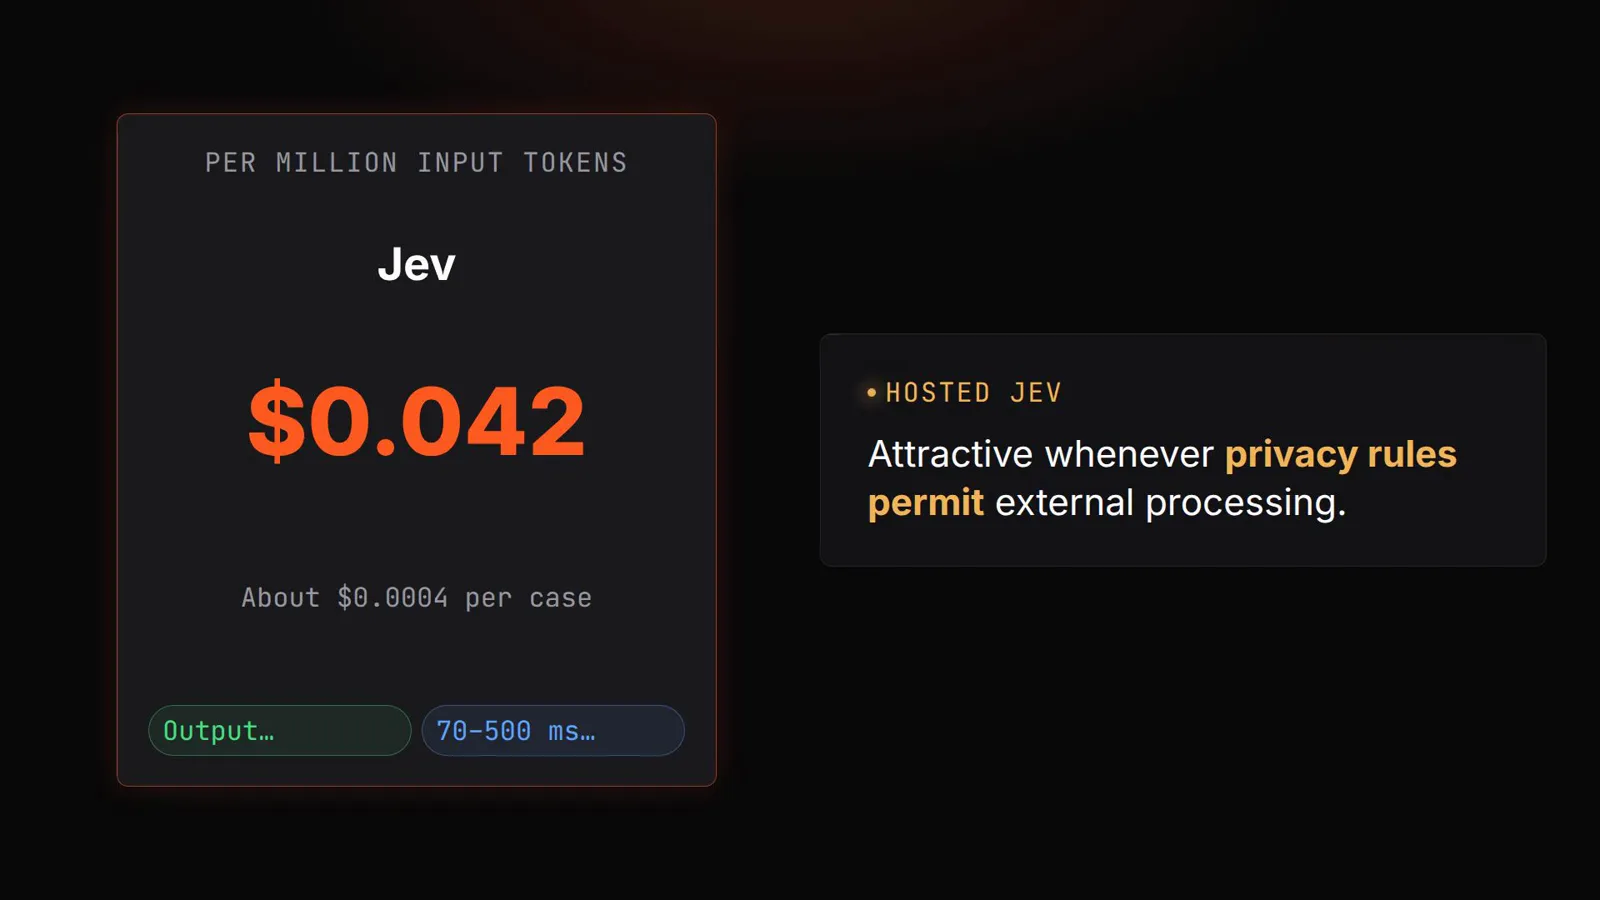
Jev vs Ollama: Can Local AI Replace Hosted Jev Without Sending Your Data Away?
Hosted Jev costs about $0.0004 per decision; Kev serves the same System One interface from 127.0.0.1 — and the accuracy, latency and calibration numbers decide when local actually beats cloud.
Read guide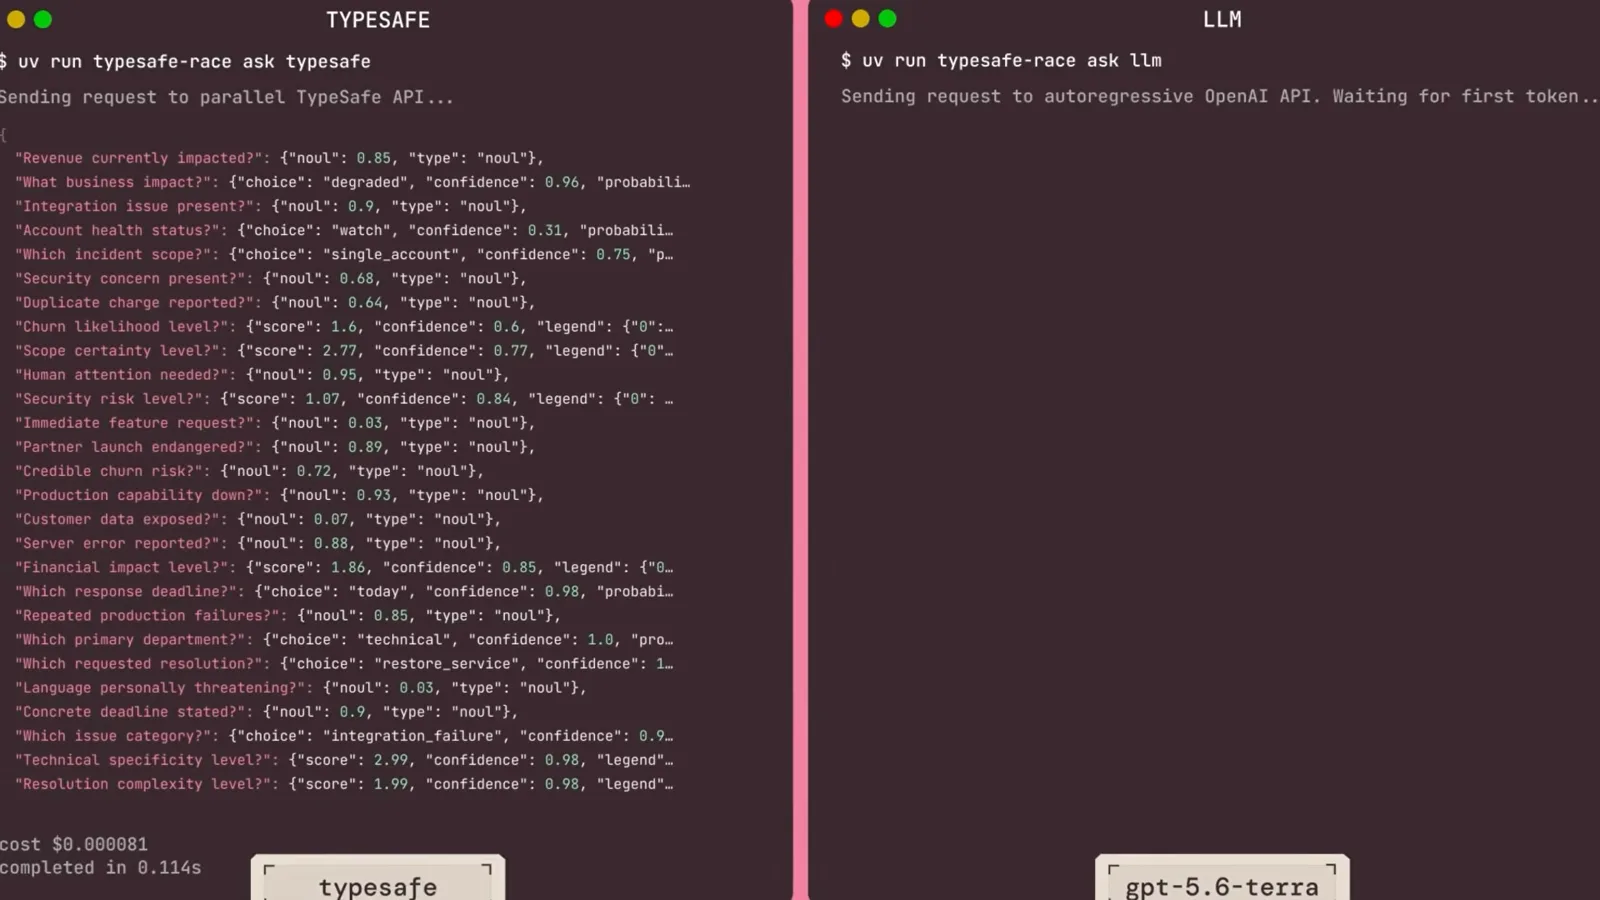
Build Your Own Jev: Train a Free Open-Source Zero-Shot Classifier (That Plays Doom)
A 0.6B student distilled from a 45×-larger teacher picks Doom moves in one forward pass — 93/100 teacher agreement on unseen rounds, ~900× faster than letting the teacher answer.
Read guide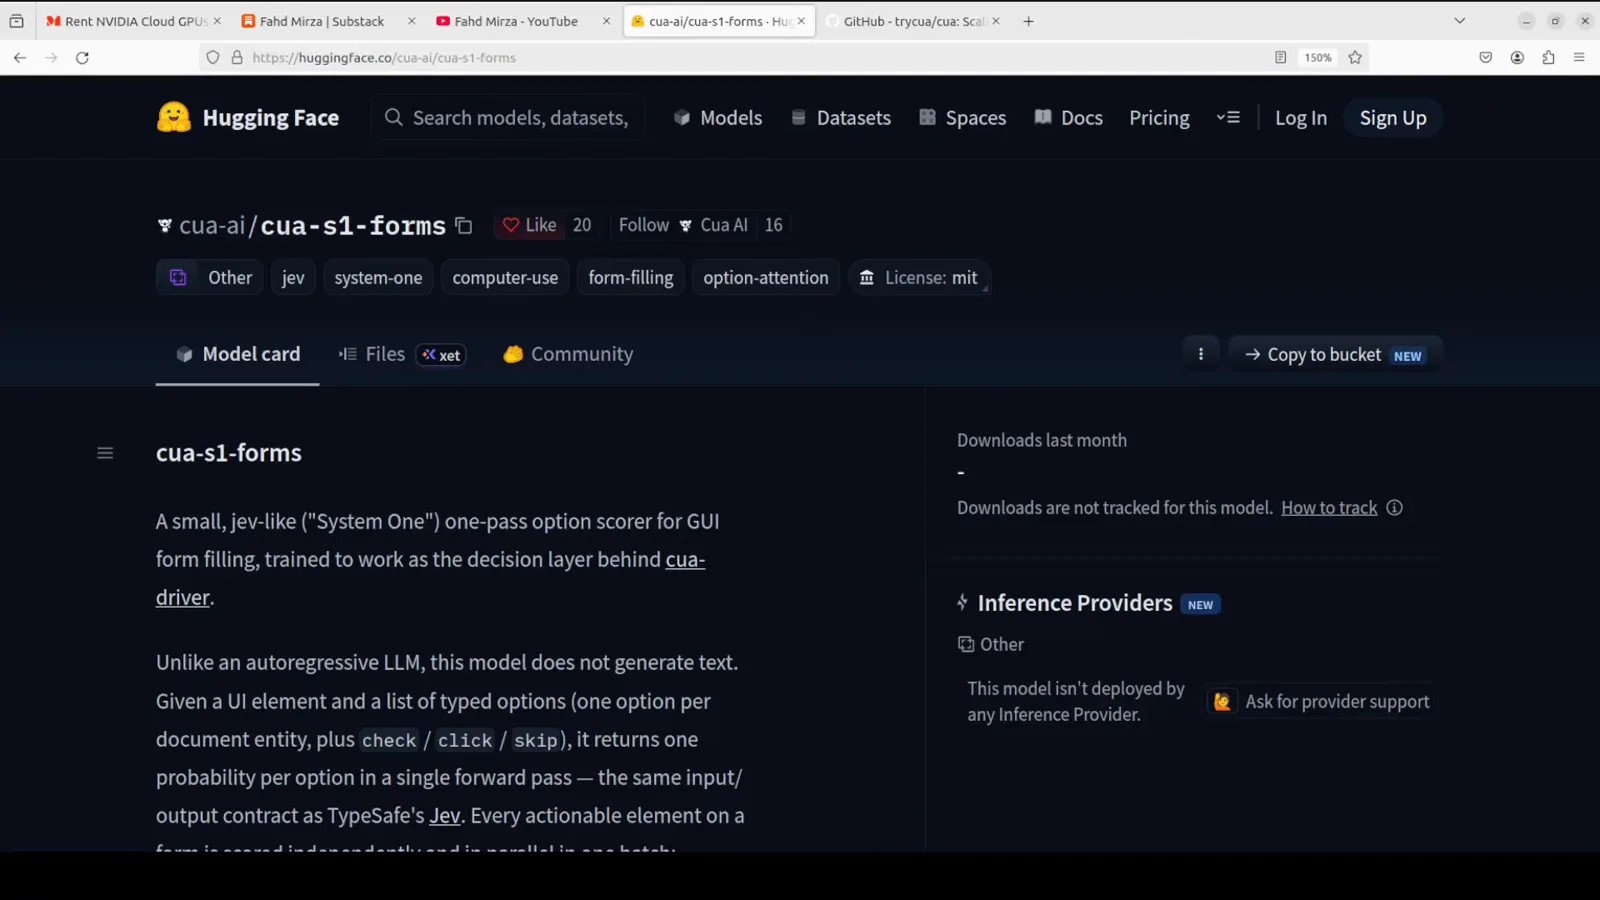
CUA-S1-Forms: a 706K-Parameter Jev-Like Model That Fills GUI Forms on Your CPU
A 2.8MB byte-level scorer rates fill/check/click/skip for each form field in one pass — 99.7% on real form-filling decisions, on CPU, while the GPU meter stays at 9MiB.
Read guide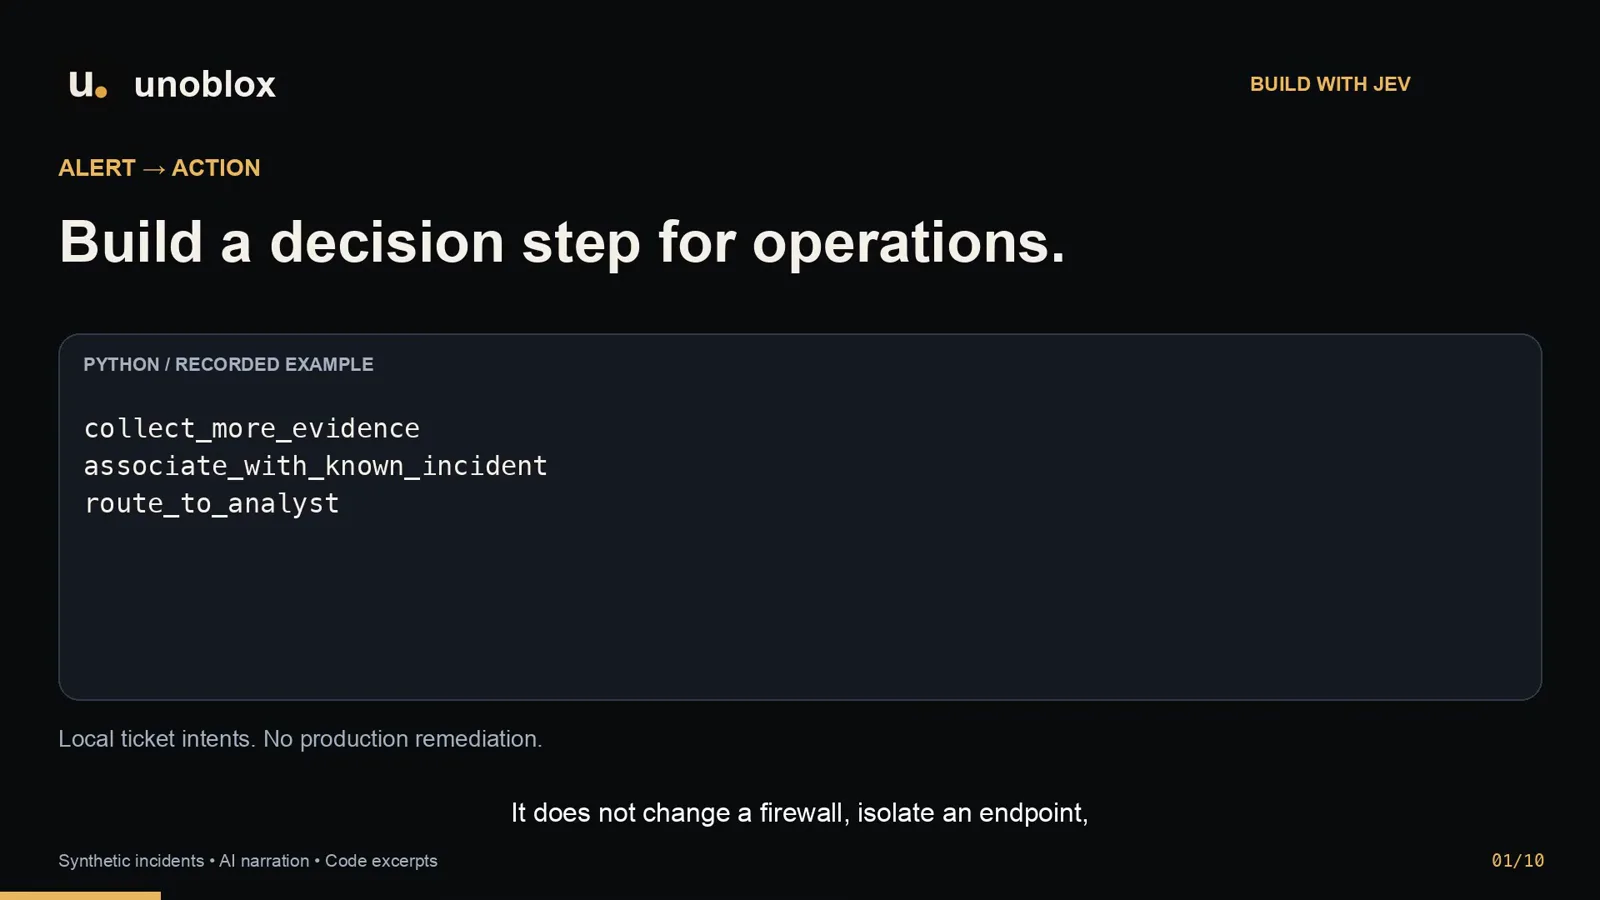
NOC/SOC Alert Triage with Jev: Rules First, One Typed Question, a Policy Gate
Rules solve what they already solve; Jev answers one typed question about the rest; a 0.85 confidence policy gate keeps every uncertain alert with an analyst.
Read guide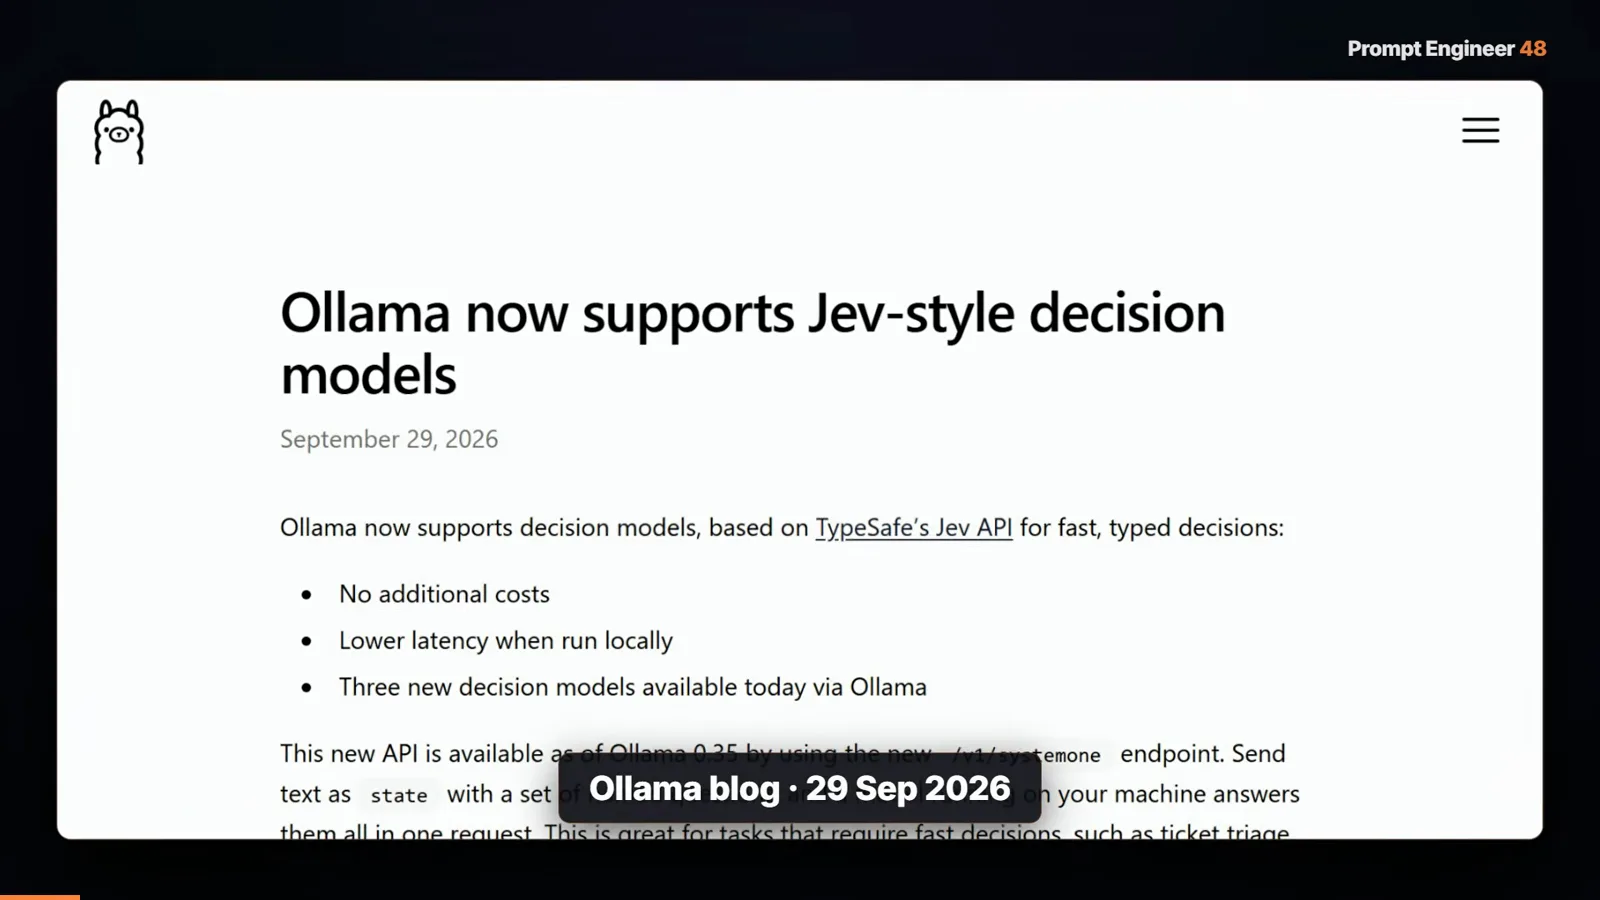
Ollama Decision Models: Run tev1 and Nimble Locally (Tested on an 8 GB Card)
Ollama 0.35 ships a /v1/systemone endpoint and two Jev-style model families — tev1 and Nimble. On one 8 GB card, tev1 4B routes tickets at 470 ms with usable confidence; a JSON-forced Qwen 3.5 chat model matches the accuracy but ships no confidence and flips answers between calls.
Read guide
Jev Guardrails in Production: A Five-Step Playbook for Decision Automation
A five-step playbook for wiring Jev in as a decision guardrail layer — with the honest numbers: Jev is ~4x cheaper and 10–25x faster than a chat model on routing decisions, and still trails frontier accuracy on complex tasks, which is exactly why thresholds and human review are steps three and five.
Read guide
A Session Drift Guard for Pi Agent: Let the Jev Model Propose, Let Code Decide
A working Pi Agent plugin that catches session drift before the context gets polluted — and the most instructive Jev lesson in it: when Choice options semantically overlap, probabilities split (0.45/0.47 both under the 0.6 gate), so sum related options in code and let the model propose while code decides.
Read guide
50 Tev1 Use Cases: What a Local Decision Model Can Actually Do (Tested on an 8 GB Laptop)
One RTX 4060 8 GB laptop, 50 tasks, $0 per request. Across 44 text tests, tev1 0.8B scored about 73% at 190 ms and the 4B hit 91% at 360 ms — routing tickets and models, moderating content, screening resumes, triaging logs at 97 ms, and even playing tic-tac-toe, with every answer carrying a probability.
Read guide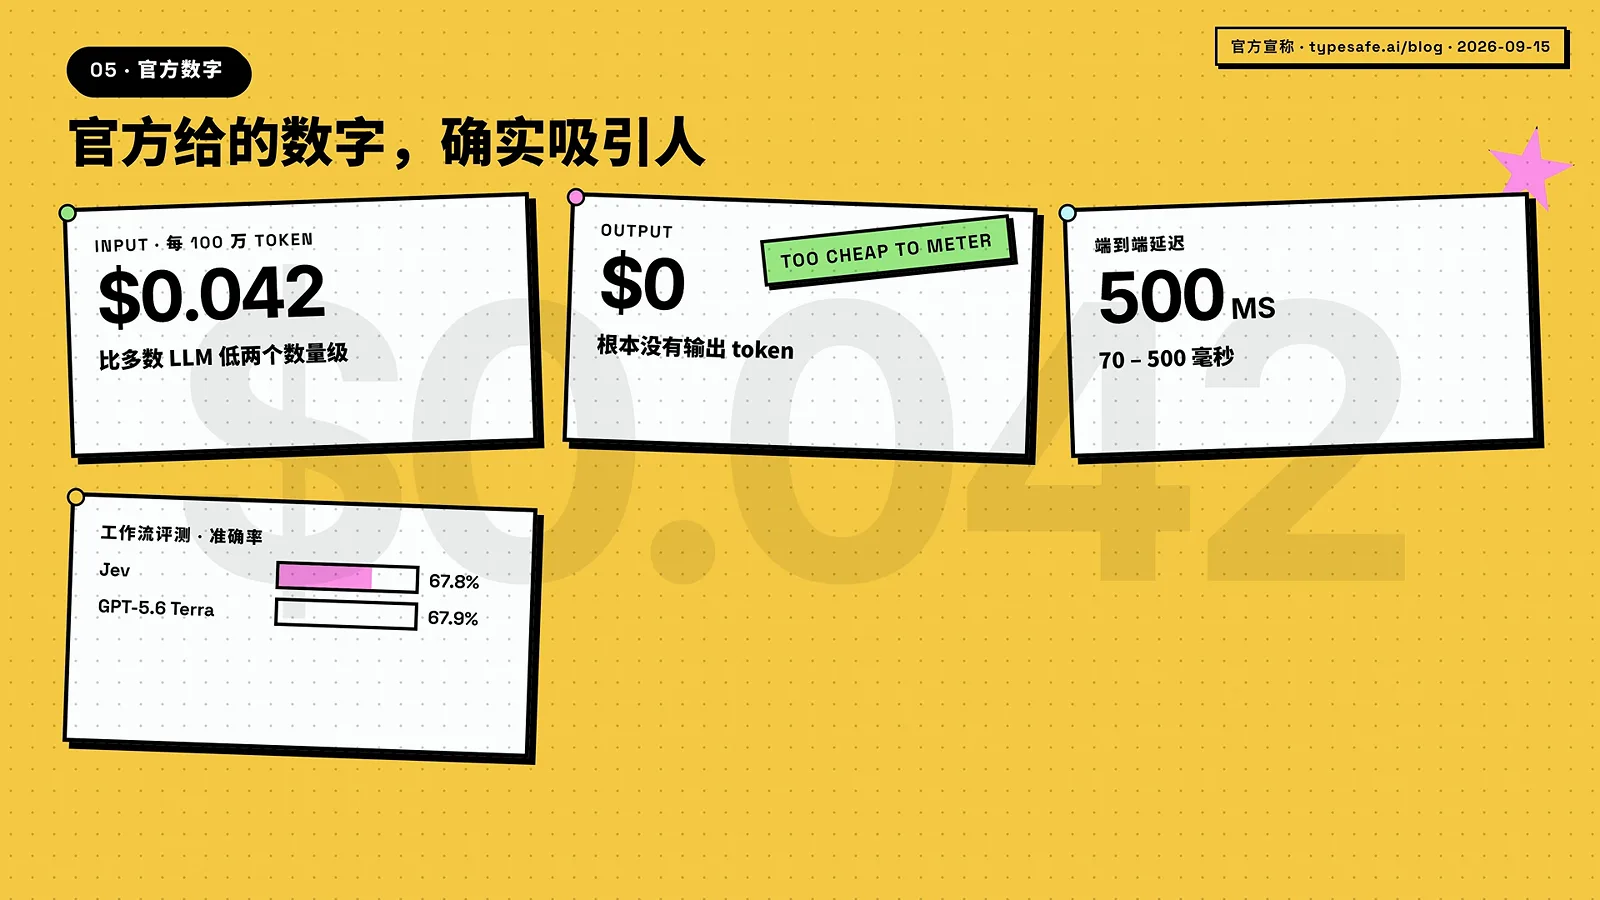
Jev, Hands-On: Where the Official Claims Meet Independent Remeasurement
A Chinese creator’s independent audit of Jev: the 20-400x claim meets a 5-25x remeasure, latency lands at 1.6-3.7s depending on the route, calibration stays unverifiable, and "no hallucination" does not hold — plus four integration paths and six playground scenes.
Read guide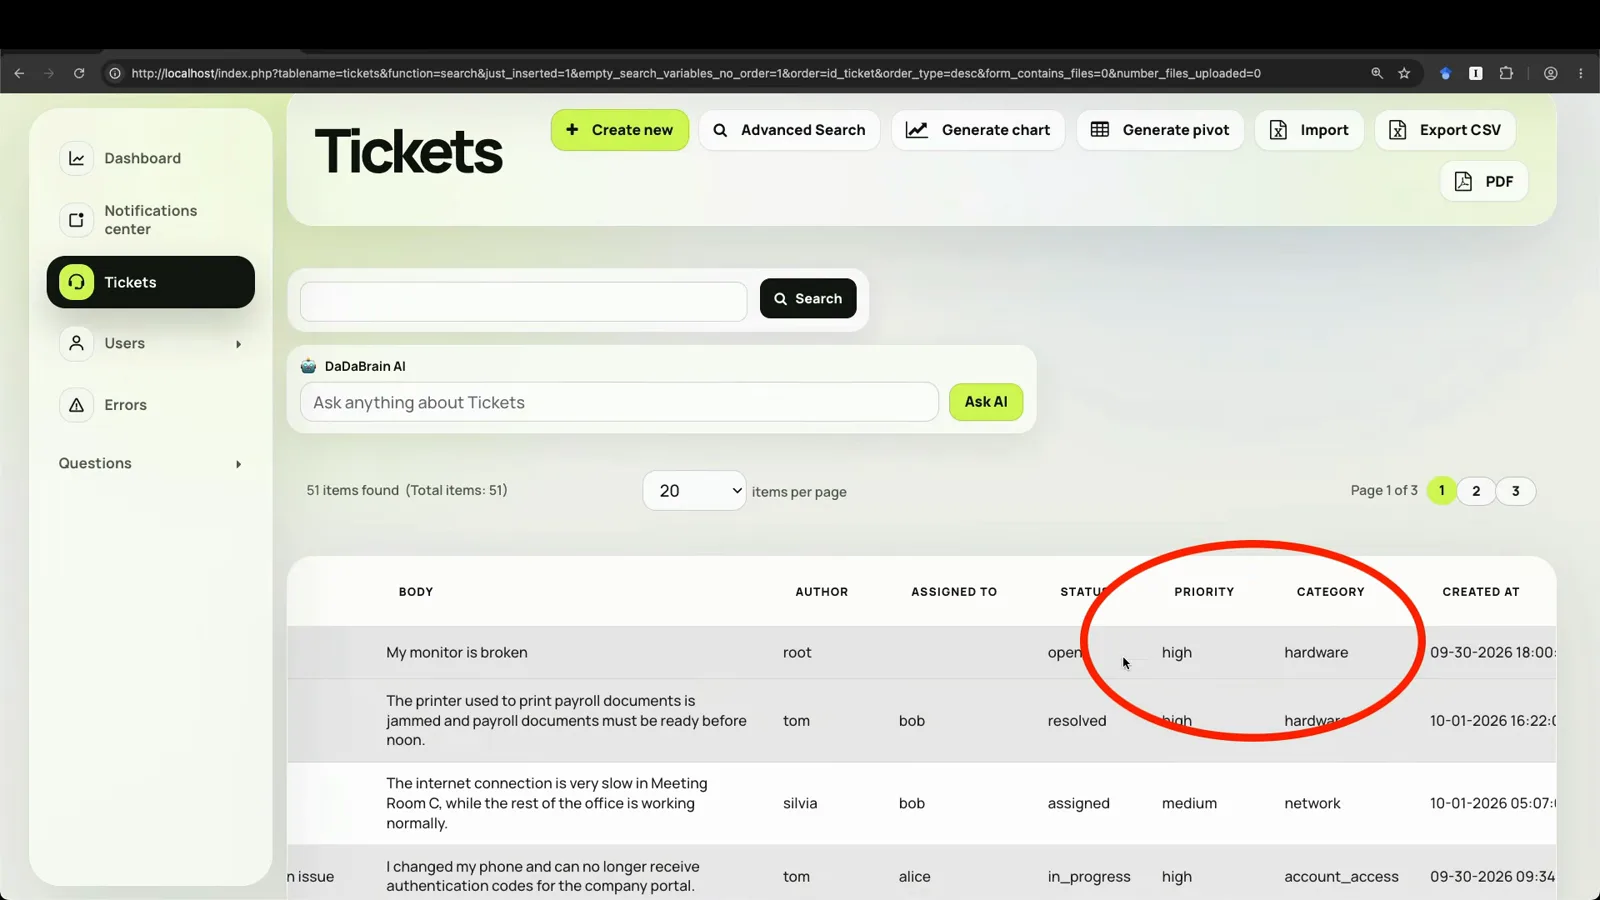
Jev Ticket Classification in a Real App: the After-Insert Hook and the Calculated Field
Two ways to wire Jev ticket classification into a real app — an after-insert hook and a calculated field — with a 47/50 accuracy test, a 0.9 confidence review rule, and a $0.003 bill.
Read guide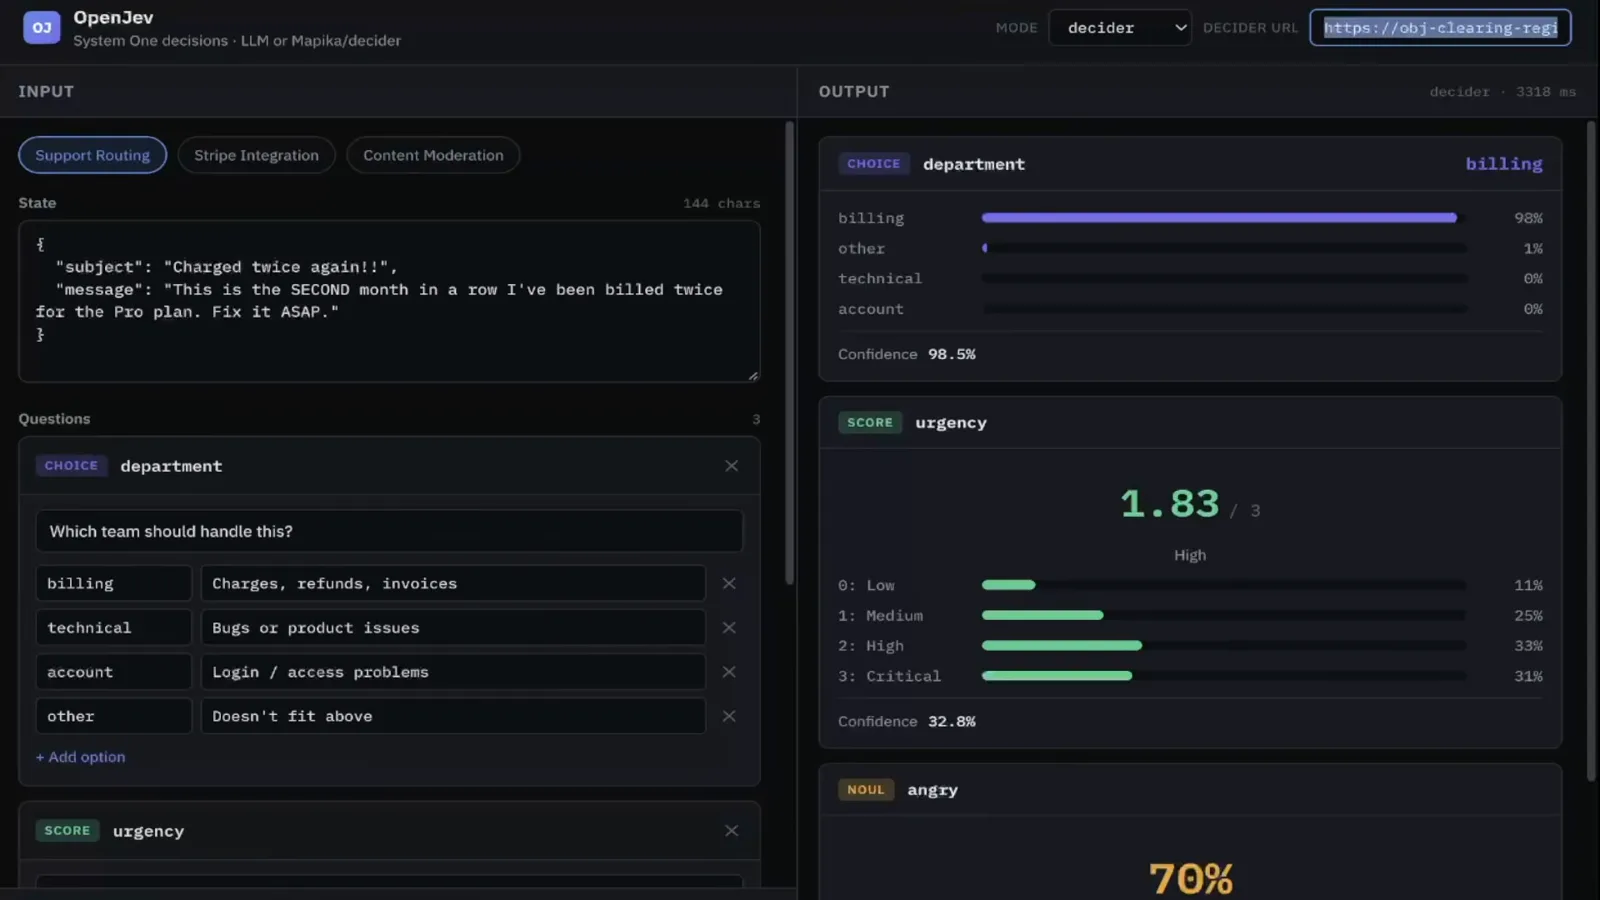
OpenJev RLCD: Run the Open-Source Calibrated Decision Model Locally (Full Guide)
OpenJev (the open-source Jev stack) added decider support: point it at an RLCD model from the Mspika/decoder repo and it answers typed questions with calibrated probabilities, speaking a wire format very close to the TypeSafe Jev API. The video runs the same billing complaint through the decider (urgency 1.83 High, angry 70%) and a parallel Qwen chat model on Groq (urgency 2.38, angry 95%) — and closes with the honest read that on simple tasks, nine parallel LLM calls beat one slow decider call on old Kaggle hardware.
Read guide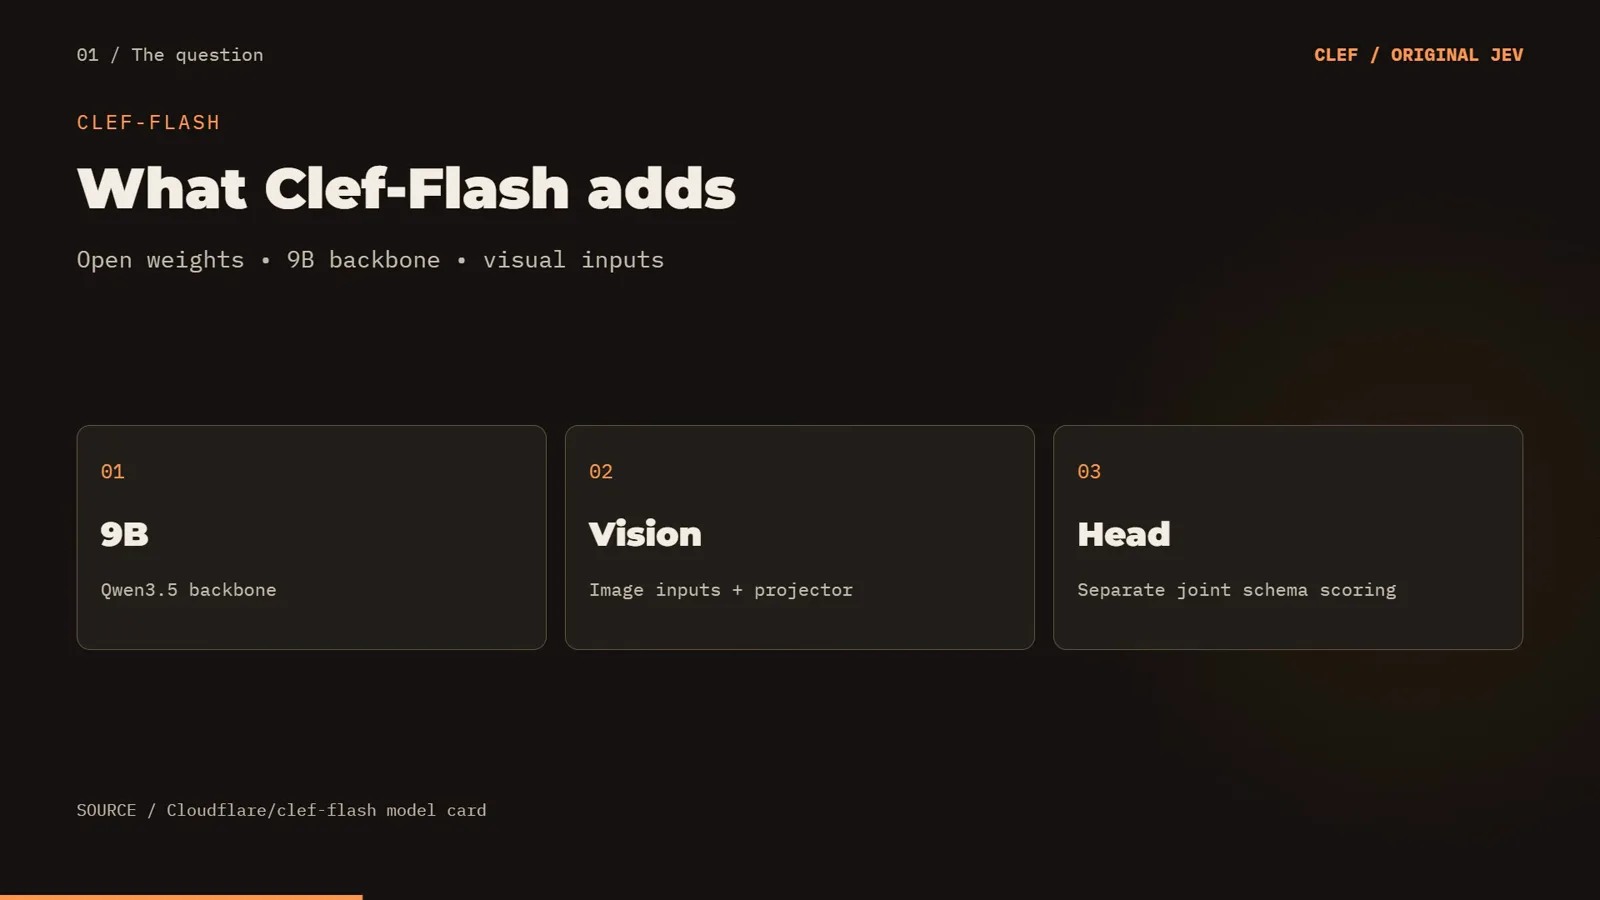
Clef-Flash vs Jev: I Tested Cloudflare's Decision Model Locally in Ollama (Q4_K_M)
The bartowski Q4_K_M quantization of Cloudflare's Clef-Flash runs on an RTX 4060 laptop through Ollama 0.35: the schema-constrained support-routing demo parses to valid JSON (~1.4–2 s warm) and the vision demo reads a peace sign at 1.35 s — but the same outage prompt returned technical on one run and billing on a zero-temperature repeat, and the inspected quantization file contains 427 backbone tensors with zero schema-head matches. The published Clef-vs-Jev numbers are real but come from Cloudflare's hosted evaluation, not this laptop.
Read guide
Clef-Flash Tutorial: Install and Run Cloudflare's 9B Multimodal Decision Model Locally on Ubuntu
Clef-Flash (Cloudflare/clef-flash on Hugging Face, Apache-2.0) is the 9-billion-parameter member of Cloudflare's Clef family — a multimodal model built for structured decisions, not free-form chat: you define a text state, optionally attach a raw photo, ask multiple-choice questions, and get calibrated JSON probabilities for every option. The install on Ubuntu fits in five commands: sudo apt update && sudo apt upgrade, a testClef2 workspace, python3 -m venv env1, then pip install torch transformers accelerate pillow huggingface_hub torchvision (roughly 2–3 GB — the creator says the minimum set took a while to pin down). The optional causal-conv1d and flash-linear-attention speed-ups need the CUDA toolkit and GCC and compile on first install. The model loads through snapshot_download, and the model card's Usage section (as shown at recording) lists torch 2.11 with transformers 5.10.2 on a single H200, with pillow required for image and video inputs. Two demos prove the loop end to end: a text-only invoice (Acme, 1250.0 USD, status overdue) comes back overdue at 0.9728, and a photo of a cracked-screen phone in a crumpled-paper-packed box returns cracked at 0.9626 plus a 0.957 yes on "is there paper or bubble wrap in the box?". On the creator's RTX 3090, nvtop showed the python3 test2.py process holding about 18.7 GB of the card's 24 GB while the 760/760 weights were live.
Read guide
CLM-8B: the Contrastive Decision Model That Scores 1,024 Options in 44 ms (13x Faster Than Jev)
CLM-8B (CLM-v0.1, a Stanford + NVIDIA Research team) is an 8B "CLIP for decisions": a frozen Qwen3-8B backbone embeds the situation while two small trained heads (~20M parameters each) embed state and actions into one space, so a decision is just distance in embedding space — options are embedded once, cached, and scored by dot products. That is why latency barely moves as the option list grows: 44 ms at 1,024 options versus 570 ms for Jev on the video chart, with the same three-primitive Jev API and the same fine print (it never invents an off-list answer, but it can confidently pick a wrong on-list one). This page walks the two-tower architecture, the three-stage contrastive recipe (60M QA pairs, then 30M Gemini hard negatives, then 1M agent trajectories), the frozen-backbone economics (about one hour of pre-training on a single RTX 4090), the DGX Spark demo (a ticket scored urgent 84% / billing 99% / very angry, cached re-asks under 2 ms), the 1,080-tool router and the WikiRace replay — and the honest boundary: accuracy fell from 86% at 8 tools to 17% at 1,080.
Read guide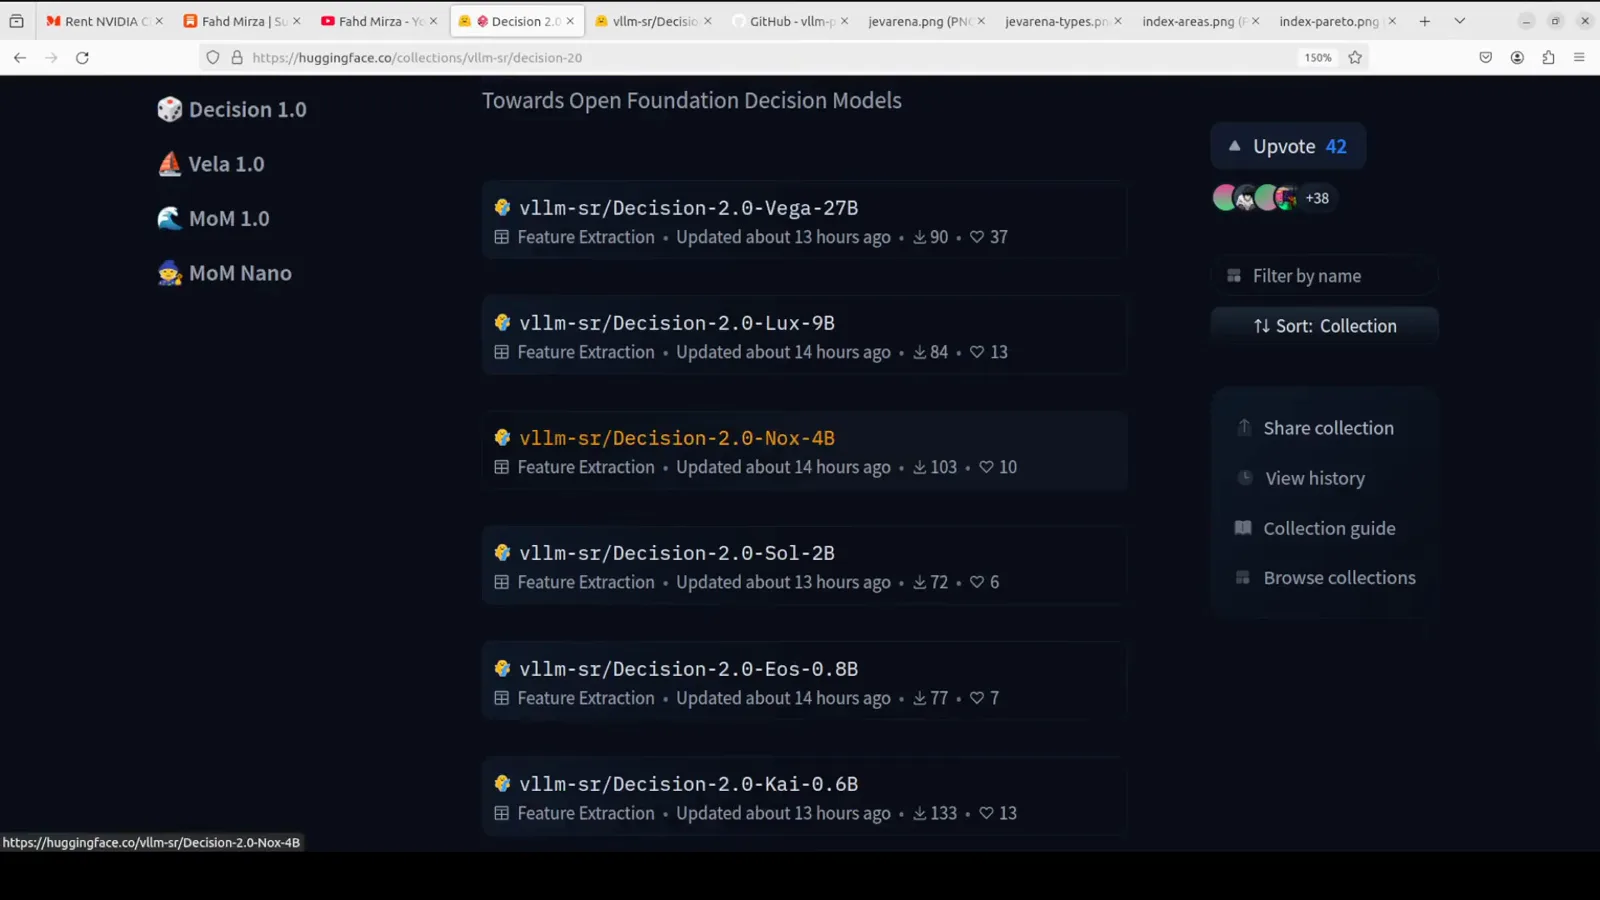
Nox 4B Tutorial: Run the Decision 2.0 Model Locally and Put It Through Four Real Decisions (One Ends in a Fail)
Nox 4B (vllm-sr/Decision-2.0-Nox-4B on Hugging Face) is the recommended middleweight of the Decision 2.0 family — six Apache-2.0 decision models from the vLLM semantic-router team, sized 0.6B to 27B behind one interface. The whole install is one from_pretrained line, decisions come from a single system_one(state, questions) call with three question types (noul yes/no, choice, score), and everything runs in milliseconds without generating text. In the video's four tests it routes an angry-customer ticket on the first pass (billing 89.4%, urgent 77.8%, frustration 1.40/2), fails a social-engineering trap by granting database access at 85.2% while detecting the manipulation at just 22.1%, fails a restaurant at 96.9% with a suspend recommendation, and declines a risky mortgage with approve at only 19.4% — at a 13.3% decision confidence that itself argues for a human loan officer. Official cards: first in its JevArena size class at 63.6, strongest on yes/no (88%) and score (66%), under 10 GB of VRAM.
Read guide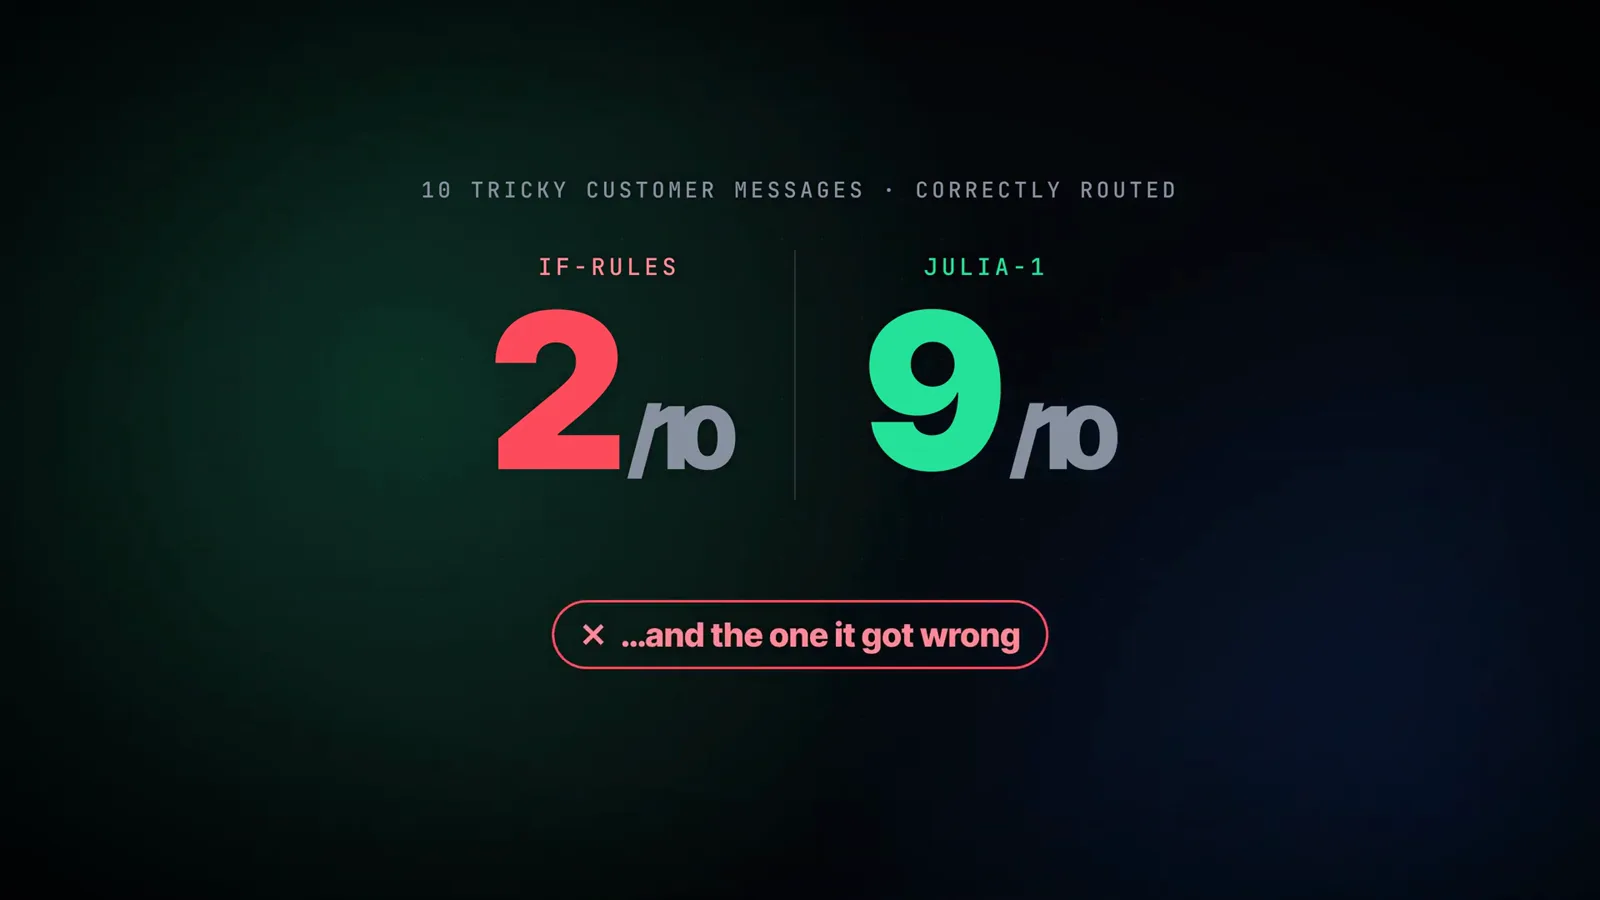
Julia-1 Tutorial: Install the Open-Source Jev Replacement in Pure Python (and Watch It Beat If-Statements 9 to 2)
Julia-1 (Supersonic Labs) is a free, CPU-only decision model you install in three commands: a venv, one snapshot_download of about 550 MB from Hugging Face, and pip install -e ./Julia-1. You ask it typed questions — choice with 2–20 described options, or noul for yes/no — and it returns a probability per option. In the video's demo it routes 9 of 10 tricky support messages correctly against 2 of 10 for keyword if-rules, winning on negation, missing keywords, typos, and Portuguese; the one loss is a shipping message it sent to billing at 100% confidence. On a 2-core cloud VM: ~9 s to load once, ~40 ms per decision.
Read guide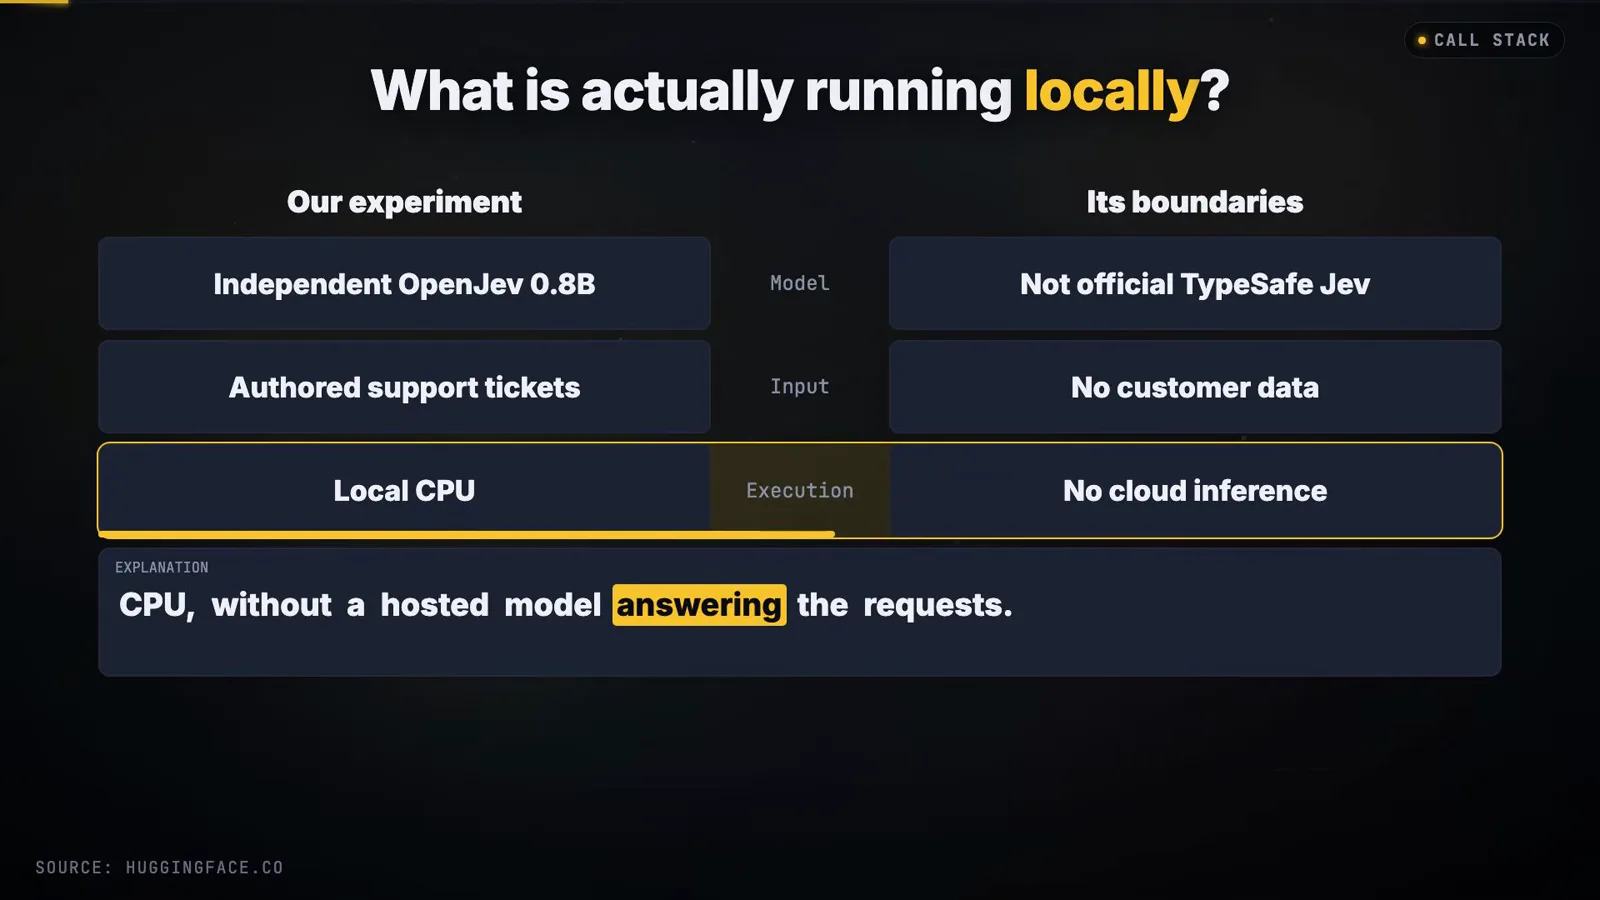
OpenJev 0.8B on CPU: I Built a Ticket-Routing Inbox and Calibrated the Thresholds
A working inbox app runs on AlexWortega's independent OpenJev 0.8B checkpoint: each authored ticket is scored against four department hypotheses for contradiction, entailment, and neutral, and the app reads those scores directly instead of asking the model to generate replies. The engineering story is threshold calibration: v1 (largest entailment, 0.60 minimum, 0.10 lead) hides a second real issue when billing 0.97 and login 0.78 both clear; v2 sends multi-proposition tickets to human review but also defers a clean refund ticket (0.9883 vs 0.7277); and the frozen test set finishes at 2/4 calibration and 7/12 held-out — counts the video explicitly refuses to call standalone model accuracy. All on CPU float32: 1.71 GB of weights, 3.20 GB peak memory, 5.63 s median per request, fully offline after download.
Read guide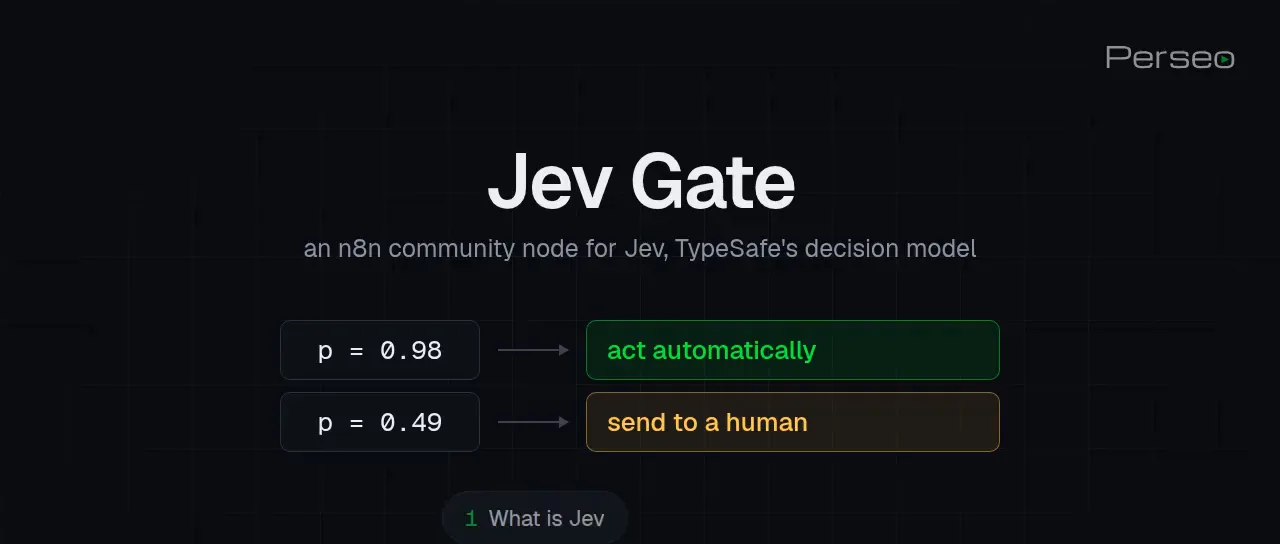
Jev n8n Integration: the JevGate Community Node, Step by Step (Plus a Plain-HTTP Fallback)
JevGate (n8n-nodes-jev-gate) wires TypeSafe's Jev decision model into n8n: Decide gates each item on a confidence threshold, Calibrate finds that threshold from labeled examples (0.7 recommended on the demo's 12 messages), and Route gives every option its own output with review last — while a stock HTTP Request node to OpenRouter covers workflows that cannot install community nodes.
Read guide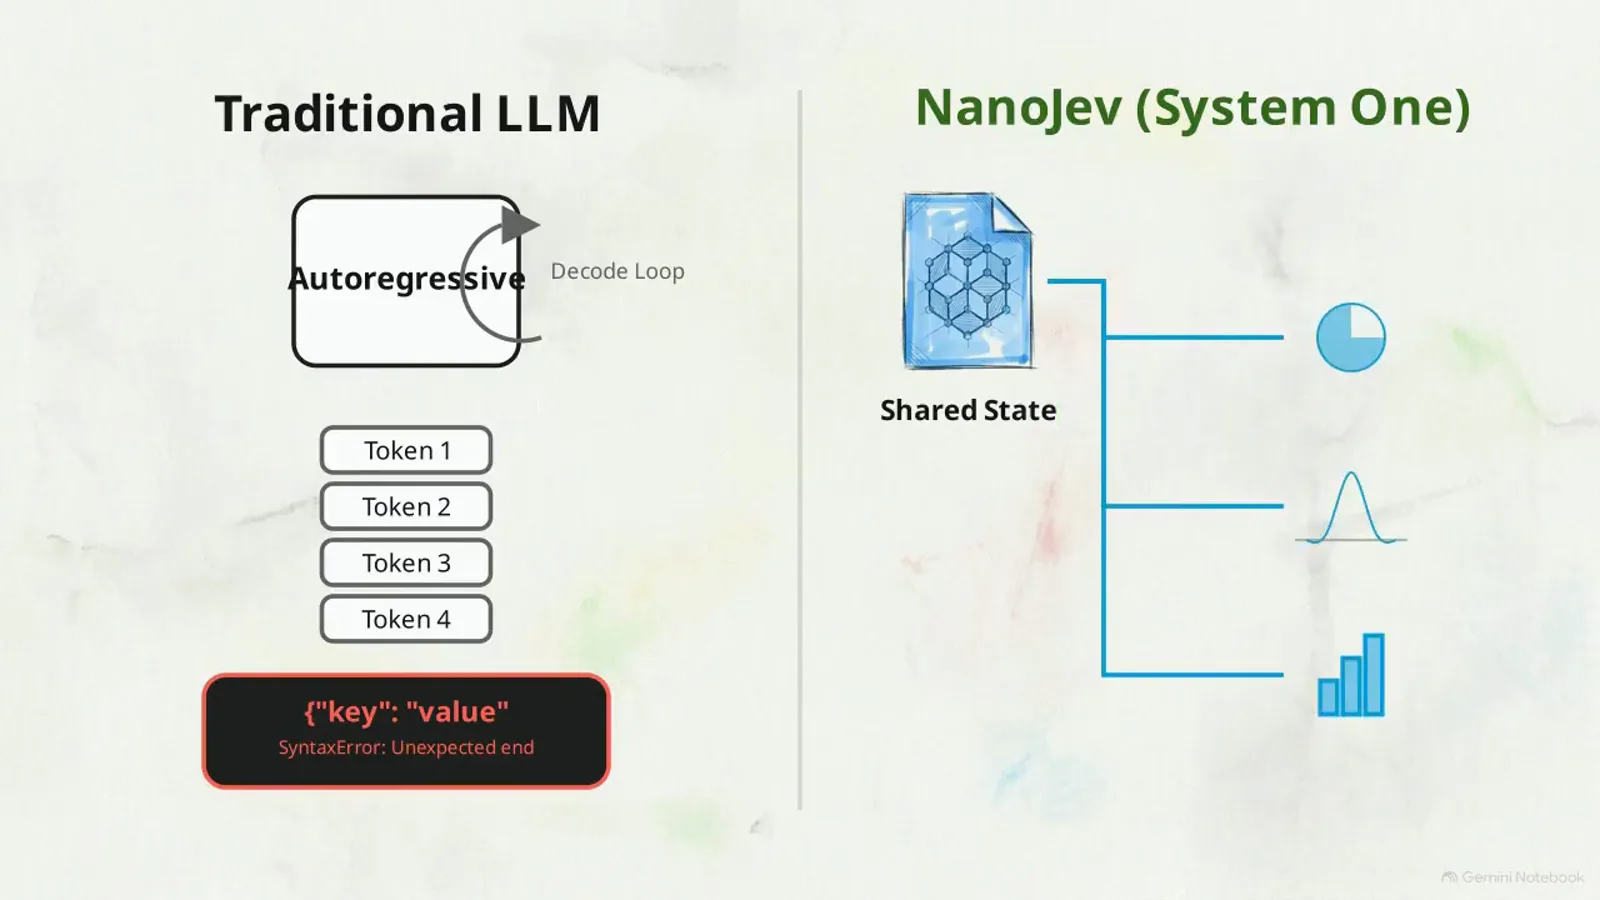
NanoJev Tutorial: Install the 0.6B Open-Source Jev Replica and Watch It Route Decisions at 47 ms
NanoJev (GitHub TianyuCodings/NanoJev, Hugging Face C-Tianyu/NanoJev) is a community-built nano replica of the Jev System One architecture: a 0.6B parallel decision model on a Qwen3-0.6B backbone with decision heads, and no vocabulary generation head at all — it is architecturally incapable of producing a sentence. States and questions go in, complete probability distributions come out, in a single matrix pass the video measures at well under 50 ms. This walkthrough follows the video from git clone to routing script: the requirements-toy.txt install that pins torch==2.14.0 (and the RTX-5090 wheel override you need on newer cards, because ignoring it drops you to a 400 ms CPU fallback), the snapshot_download of the unified-games-v1 checkpoint filtered to best.safetensors, the two-terminal verification (inference engine on port 8765, HTML front-end on 8080) watching NanoJev drive a 50x50 maze with live confidence bars, then a Python routing script built on the entry contract — no conversational prompts, a shared state payload, and parallel typed questions (choice 0.842, boolean 0.991, score 0.740 in the demo) answered in one forward pass. On top sits the asymmetric-error routing rule: above 85% autonomous, 50-85% to a human, below 50% to a backup frontier model. And the video keeps its honest section: the unified checkpoint is conditioned on game spatial mechanics — near 88% on spatial navigation, collapsed on semantic text — so plan your own supervised fine-tune before pointing it at your domain.
Read guide
PPLX Decider Tutorial: Perplexity's Open 27B Decision Model, Its Decisions API, and a 12-Ticket Triage Run
PPLX Decider (Hugging Face perplexity-ai/pplx-decider-v1-27b) is Perplexity's open-source decision model: an Apache 2.0 fine-tune of Qwen3.8-27B that answers with probabilities instead of text — a yes/no probability, one of your options, or a level on your rubric. This walkthrough follows the video through the whole pitch: the model card (Text Classification, multimodal, custom-code, apache-2.0), the 11-benchmark panel on a fixed 2,710-row set measured September 2026 (Decider 85.71% overall vs Jev 84.51% and its own Qwen3.8-27B base at 74.76% — vendor-reported, with the card's own disclaimer kept in), and the community Jev Decision Index where the board's own hover cards read Jev 57.9 at rank #1 (524 ms median, hosted) against pplx-decider-v1-27b's 56.4 at rank #4 (101 ms, 28B, full fine-tune). Then the hosted half: the Decisions API with its three question primitives — noul (yes/no probability), choice (1 to 255 options with per-option probabilities and confidence), score (an ordered rubric of up to 10 levels with an expected score) — plus state that can carry base64 screenshots under a 2,048-tile image budget, all capped at 128 questions and roughly 262K input tokens per request. It ends in Perplexity's official cookbook: three probabilistic questions per support ticket, twelve tickets classified in about 2.5 seconds, three escalations out, and only those three sent on to the expensive Agent API. Two things have moved since the video: input pricing is now $0.02 per million tokens (halved from the $0.04 the video quotes), and a v1.1 checkpoint has raised the Decision Index to 61.56 — ahead of Jev.
Read guide
AutoTrust JEV-27B Tested Locally: Four Arms, 72 Cases, and One 0.969 Score That Was Wrong
AutoTrust JEV-27B (huggingface.co/autotrust/JEV-27B) is the AI lab's second integrated System 1 + System 2 release: a frozen Qwen3.8-27B backbone carrying roughly 109 million trained parameters — a decision adapter plus a scoring head — distilled from TypeSafe's hosted Jev, so the local weights make decisions without calling the teacher. Quick naming note before anything else: it is not the only open 27B Jev-family model — ZefanCai/Open-Jev-27B-v1.1 is a separate community LoRA-adapter release on the same Qwen3.8-27B base — and AutoTrust also ships a vision sibling, JEV-27B-VL; this page is about the text model in the video. That video, from the RUNTIME. channel, is a ten-and-a-half-minute independent field test on a DGX Spark (GB10) with 16-bit BF16 weights: four arms scored on the same inputs — a small deterministic rules parser, the trained decision head, the same backbone generating an ordinary answer, and a reasoning path that thinks before scoring — across 72 held-out policy-routing cases plus 96 perturbation variants. The scoreboard: ordinary generation 50/72, quick decision head 63/72, reasoning 71/72, rules 70/72. Then come the sections a launch post would cut, kept here in full: the testers found a wording flaw in five of their own routing cases (a policy exception sends billing issues to Security while the Security option describes unauthorized activity) and re-scored without them — reasoning goes 67/67; they tried six confidence thresholds from 0.50 to 0.95 on 24 development cases and none qualified, so no working hybrid gate exists in this video; and the centerpiece error case shows the quick head scoring 0.969 on a wrong answer that the highest threshold would have waved through. Median end-to-end latency on the Spark: 0.65 s for the quick head, 2.34 s for ordinary generation, 102.20 s for reasoning — with reasoning hitting its 512-token budget on 20 of 72 cases and the download weighing about 50 GiB. The takeaway the video earns: a preference score is not proven reliability — keep clear conditions in code, and test before production.
Read guide
Clef 27B Locally: Watch Cloudflare’s Multimodal Decision Model Read an Image, a Video and an Uzbek Newspaper in One Pass
Clef 27B (Hugging Face Cloudflare/clef) is Cloudflare’s open-source multimodal decision model: 27B parameters on a BF16 tensor type, Apache 2.0, and a card that says it plainly — hand it a state as text, JSON, images or video plus a schema of typed questions, and it returns a probability for every allowed option of every question in a single forward pass. No tokens are ever generated; the video’s framing is "everything we tested with CLM, Laya, Jev, and Julia — but now with eyes." This walkthrough follows the video test by test, every number checked against the on-screen frames: the recycled social-engineering trap (an employee demanding immediate production-database access on an unverified manager approval) answered in one pass with grant access at 5.9%, risk level 2.48/3 High, social engineering at 76.1% and action escalate — which puts Clef in the detected-it club with CLM and Jev, while Kev, Laya and OpenJev took the bait in earlier videos. The official parallel-outputs diagram shows why the single pass matters: one support ticket plus two questions come back as department Technical 100% and urgency Yes 100% simultaneously. The hardware bill is real: on a rented NVIDIA H100 PCIe the nvtop monitor reads 52.06 GiB of 79.65 GiB with python app.py holding 52,682 MiB — matching the narrator’s "less than 54 GB fully loaded, KV cache included." Then the multimodal gauntlet: an AI-generated office love-triangle image read as primary stress work 94.5%, boss intent 7.3% genuine love, her choice neither at 71.9%, outcome "messy but she survives"; an 8-second AI-generated clip of a man with a candle in a frozen forest compressed into 192 frames and read as emotion ritual 72.2%, in danger 16.2%, candle meaning memorial 60.2%, outcome "he survives alone"; Cloudflare’s own benchmark table where Clef leads ToolRet (69.19), BANKING77 (94.20) and CLINC150+OOS (97.43) but loses When2Call — the when-to-hand-off-to-a-human row — to Jev at 80.97; an untranslated kun.uz screenshot identified as uzbek at 95.9% with the Ukraine conflict found at 97.8% and one honest miss (UN mentioned, 39.6%, because BMT is the Uzbek abbreviation); and a college-level titration curve read near-perfectly — titration 99.1%, diprotic acid 97.8%, two equivalence points 96.7%, final pH twelve at 97.3%. If you want one model that proves decision models can see, this is the current reference.
Read guide
Ollaya Guide: Install the "Ollama for Decision Models" Runner, Read Every Vendor-Reported Number, and Run the CPU Test It Leaves Open
Ollaya (GitHub ollaya-dev/ollaya, site ollaya.dev) brands itself with one sentence — "Run open decision models locally: pull and serve Laya, decider, NLI and GliClass behind a TypeSafe-compatible API. Ollama for decision models." — and that branding is a double-edged sword: it is the fastest way to explain the tool and the single most common way people mishear its name. This page follows LocalLayer's nine-minute walkthrough from identity to open question. Ollaya is a Rust CLI plus a resident background daemon that exposes a local HTTP API; the runtime is Apache-2.0, the bundled models split between MIT (llama.cpp, NLI) and Apache-2.0 (Laya, Decider, Kev), and the install is a single curl | sh script with no compile step. The pitch is latency: TypeSafe's hosted Jev API quotes 236-276 ms per call, while Ollaya running laya:en on an RTX 4090 reports 8-10 ms — including the full HTTP round trip, not just on-card compute — with an un-warmed first call at 8.1 ms and decider 2B at ~190 ms to prove not every model is that fast. The video flashes "Every number here is vendor-reported" and this page keeps that label on every figure. Wire compatibility is the migration story: existing hosted-API clients repoint at the daemon because the streaming format matches exactly — native endpoint /v1/systemone, /v1/decisions as an exact alias, Bearer local as the auth header. The traction section reads Hacker News honestly: one thread ("Ollaya – Ollama for open-source, Jev-style decision models", submitted by Ardakilic, item 49848269) captured at a live 586 points / 139 comments and at an earlier 18-hour 489 / 122 — same thread, two time points — while a second Web-UI post stalled at 5. The skeptics get their own section: HN user hbrn's "Decision model is just marketing jargon. Decision model = classifier," answered by showing the menu (nli 435M and qwen3guard 600M are classifiers; kev 9B and winnow 12B are decoders repurposed to score choices) and the one contract above them: written question + input state → single forward pass → calibrated probability map, decoding loop skipped. The leaderboard section quotes benchmarkheaven.com as a live, unaudited snapshot — Jev 1.13.0 at capability 64.7 / composite 63.3, Laya (ModernBERT-Large 421M, credited to Convai Innovations, packaged but not trained by Ollaya) at #41 on both with 49.9 / 30.3 and ~$0.0029 per 1,000 decisions. Then the practical payoff: ticket triage, shell-command filtering and agent tool calls on one daemon, MCP support so Claude Code can spend one tool call instead of a full LLM call, and an end-to-end demo that answers a duplicate-charge ticket with billing at confidence 0.78 plus a receipt of nanosecond timing fields — eval_duration, load_duration, total_duration. The video ends with an open exercise: no vendor publishes CPU-only numbers, so it runs OLLAYA_DEVICE=cpu on camera and leaves the result unread — this page keeps that number blank on purpose. Run the CPU test. What's your eval_duration?
Read guide
Strands Decider 2B Tutorial: Install the AWS Strands Decision Model on an 8GB Laptop — and Keep Its Failures In
Strands Decider 2B (Hugging Face StrandsAgents/strands-decider-2B-hobson-v19, GitHub strands-labs/strands-decider) is an open-source, Apache 2.0 decision-making model out of the Strands team — the same ecosystem as the AWS-originated Strands Agents SDK, with AWS attribution corroborated by builder.aws.com and press coverage — announced on the project blog on October 1, 2026. It is a "system one" model: it picks between options you put in the request, rates on ordered scales, and answers yes/no with a probability, and it cannot generate text at all because the LM head of its Qwen3.5-2B-Base torso was removed and replaced with a ~1M-parameter fp32 pointer head (LoRA r16, 1.9B parameters total). This walkthrough follows the video from pip install to the closing verdict: reproducing the blog ticket-routing example digit for digit (billing at confidence 0.768), surviving the honest 229.75-second first load on a Windows laptop with fast-kernel fallback warnings, serving the model and POSTing to /v1/systemone for a JSON response with probabilities, token usage and latency_ms, watching option descriptions lift confidence from 0.768 to 0.922, batching five questions into one ~518 ms request, measuring 30 warm requests at a 178 ms median on an RTX 4060 laptop against the 115 ms RTX 3090 repo claim, routing small-vs-large models on confidence (France 0.913 → small; proofs 0.565 at confidence 0.13), wiring a before_tool_call tool guard that GUIDEs a Seattle guess and barely PROCEEDs on Paris, and — kept on purpose — the failure section: strawberry P(yes) 0.463 and an injection prompt that reads injection 0.656 but policy allow 0.757, so do not use it as your only guardrail. Repo numbers put v19 at 72.3% on JevBench (167/231, ranked 3rd of 33 in the 2B class), trained in 11 hours on one RTX 3090, with a v20 that failed to beat v19 published anyway.
Read guide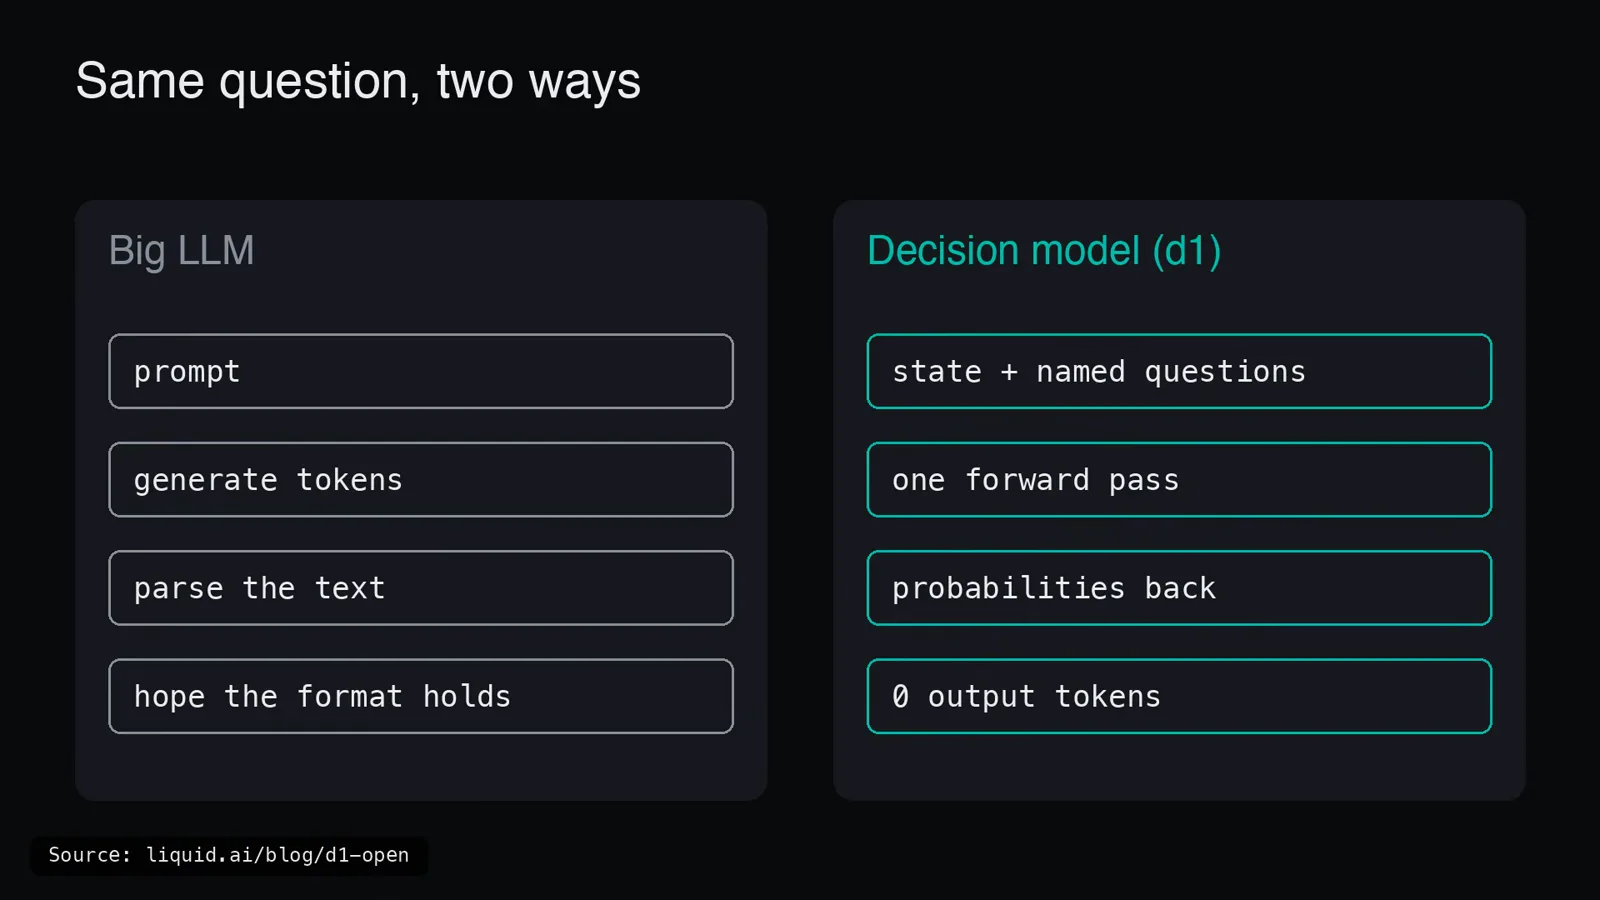
Liquid AI Open d1 Locally: d1-3B and d1-omni-600M on a MacBook Air M5 — Guardrails, Screen Checks, Voice Routing and Document Triage, Every Number Frame-Checked
Open d1 is Liquid AI’s move from closed demo to open weights: two multimodal decision models, announced on X and liquid.ai/blog/d1-open on October 7, 2026, that read a state once and return probabilities instead of writing a single token. d1-3B (~3.1B parameters, text + image, 32K context, built from LFM2.5-VL-3B) and d1-omni-600M (~587M parameters, text + image OR text + audio, 16K context, an experimental checkpoint) both answer the same three typed questions: noul for yes/no ({"noul": 0.93}), choice over options you name ({"choice": "billing", "confidence": 0.81}) and score on a scale you define ({"score": 2.4, "confidence": 0.77}). The pitch card is blunt about the alternative — a big LLM prompt → generate tokens → parse the text → hope the format holds, versus d1: state + named questions → one forward pass → probabilities back → 0 output tokens. Inside the 3B, a SigLIP2 vision encoder (27 layers) and the tokenizer fill one sequence through the LFM2.5-2.6B torso (30 causal layers), and an LM head reads one marked position per question — Liquid built it by averaging two base models, retraining many copies with different seeds and data, then merging, and says the biggest gains came from longer input texts and shuffled answer choices. The omni swaps in a bidirectional LFM2.5-Encoder-350M (16 layers), a 12-layer SigLIP2 or a 17-layer FastConformer audio encoder (never both), and a decision head trained in stages. On Liquid’s own Decision Index v0.2.1 d1-3B scores 48.57 — first under 10B, on par with a ~35B model twelve times its size — against omni’s 15.95, though omni tops the text tables for toxicity detection and paraphrase identification; the 7-task text mean runs 82.9 for d1-3B, 81.1 for Decider 4B, 78.4 for omni, 77.1 for Decider 2B. Vendor-reported single-question latency: 8 ms on an RTX 4090, 16 ms on Jetson AGX Thor, 26 ms on Jetson AGX Orin 64GB, 50 ms on Orin Nano, 30 ms on an M5 Pro — with llama.cpp support from day one. This video’s half is the honest part: everything runs locally on a fanless MacBook Air M5 over Hugging Face Transformers on Apple’s GPU, and the Air pays for its silence — 78 ms per question against Liquid’s 30, 2649 ms on a ~3.4K-token log, 8 states/s packed against 78. Then four tests: an agent guardrail that cleared read-only and test runs but flagged force-pushes, deletions, a piped internet script, a $5,000 transfer and a mass staff email (needs-human-approval YES 0.94) at 14/14 agreement for ~155 ms a call; a screen inspector that named every screenshot perfectly yet waved the agent through a payment form and a login page — 8/10 with a hard-rule lesson attached; the video’s only audio test, where d1-omni-600M routed raw speech to lights/music/timer_alarm/weather/call/cancel with no speech-to-text stage, nailing “It’s way too dark in here” → lights but missing “Never mind, forget what I just asked” — 8/10 at 45–84 ms a clip; and document triage, where d1-3B went 8/8 at a median 1989 ms/image while omni went 2/8, calling nearly everything a legal notice. The limits card keeps you grounded: no chat, omni is early research, omni+image truncates text to 896 tokens, omni audio is English-only with a 30-second cap and no hosted option, and the narrator’s own numbers are small single runs on his own labels. Weights live on Hugging Face under the lfm1.0 license, runnable via transformers, llama.cpp, vLLM and SGLang, with hosted access through the Liquid console, OpenRouter or Vercel AI Gateway — and if your app calls a big LLM just to get a label, that is the swap worth testing. (And no — this d1 is not Cloudflare’s D1 database, an NCAA division, or a cleaning product; the search results around that name are a mess, the model is not.)
Read guide
Image Decision Models for RPA: Watch Two Open Models Review an Unsigned W-8BEN With No OCR
Image decision models are Jev-style decision models that take the raw image as the state — no OCR pass, no text extraction; pixels go in and calibrated probabilities come out. This walkthrough follows Sam Witteveen’s build of a Form Decision Inspector that runs two community open models side by side — Imajev-4B (Hugging Face mohit67890/imajev-4b) and Jev-Omni (akhilaaa3/Jev-Omni) — over scanned forms, and every number below was read off the frames. The framing is RPA’s boom and bust: UiPath looked unstoppable in 2018, IPO’d in 2021 at a ~$30-40B valuation with shares in the high $70s, and now trades at $13-14 per share under a $6.5B market cap — the verdict from practitioners being not that the product was bad, but that era’s deep learning needed heavy per-task tuning because no universal classifier could hold accuracy across many decision tasks. The benchmark card is ImageJevBench v0.1.3, “a held-out comparison of systems that make decisions from images”: 684 scored items (228 public, 456 sealed, 93 retired), a disclosed caveat that the 333 fresh sealed items are synthetic, and a composite board of 49 systems where Imajev-4B — built by one person in 15 days on $1,200 of GPU rental, by a business process consultant who wrote a Reddit post explaining that almost every decision node in his clients’ process maps ended on a human — leads at 76.39 ahead of Jev-Omni 73.10, NeoHorse Jev 4B 71.94, Visual-Jev 4B Answer-SFT 69.81 and JPT-4B 69.55. The demo form is an unsigned W-8BEN (printed name Oliver Bennett, dated 03-25-2026, DOB field filled, signature line empty), and the question set asks signed, date-next-to-signature, mailing address, date of birth, which required field is empty, form type, and handwriting legibility. First run: 7 questions in 3.3 seconds total, Imajev-4B 3,159 ms on the page vs Jev-Omni 1,072 ms. On the signature, Imajev-4B answers True 91.5% and clears the 90% auto-accept slider (Auto badge) while Jev-Omni answers False 73.2% and gets flagged Human — and the flagged answer is the correct one, because the form is not signed. Auto means confident, not correct. Rephrased as a choice (“What is on the signature line?”), both models return typed name only — 74.2% ≡ 75.1% with an agree marker — which is the page’s core method: classification-shaped questions are safer than true/false for these models, and you have to test which shape fits which model. The follow-up email (“could you please sign the form in the signature field”) is pure conditional logic keyed off the missing answer at 92.5% Auto — no LLM writes a word. And when a date-of-birth option is added to the missing question — literally just a new text box, no retraining — Imajev-4B keeps answering signature 94.5% while Jev-Omni drifts to nothing missing 45.3% with date of birth second at 30.7%, and answers False 88.1% on a date of birth the form clearly contains (Imajev: True 99.4%). A second form — signed but missing the DOB — then shows both models agreeing on the signature and both catching the missing DOB with different confidence. The closing advice: tailor the questions and the model to the use case, and set per-question confidence thresholds — for RPA, rapid image classification, and large-scale image processing.
Read guide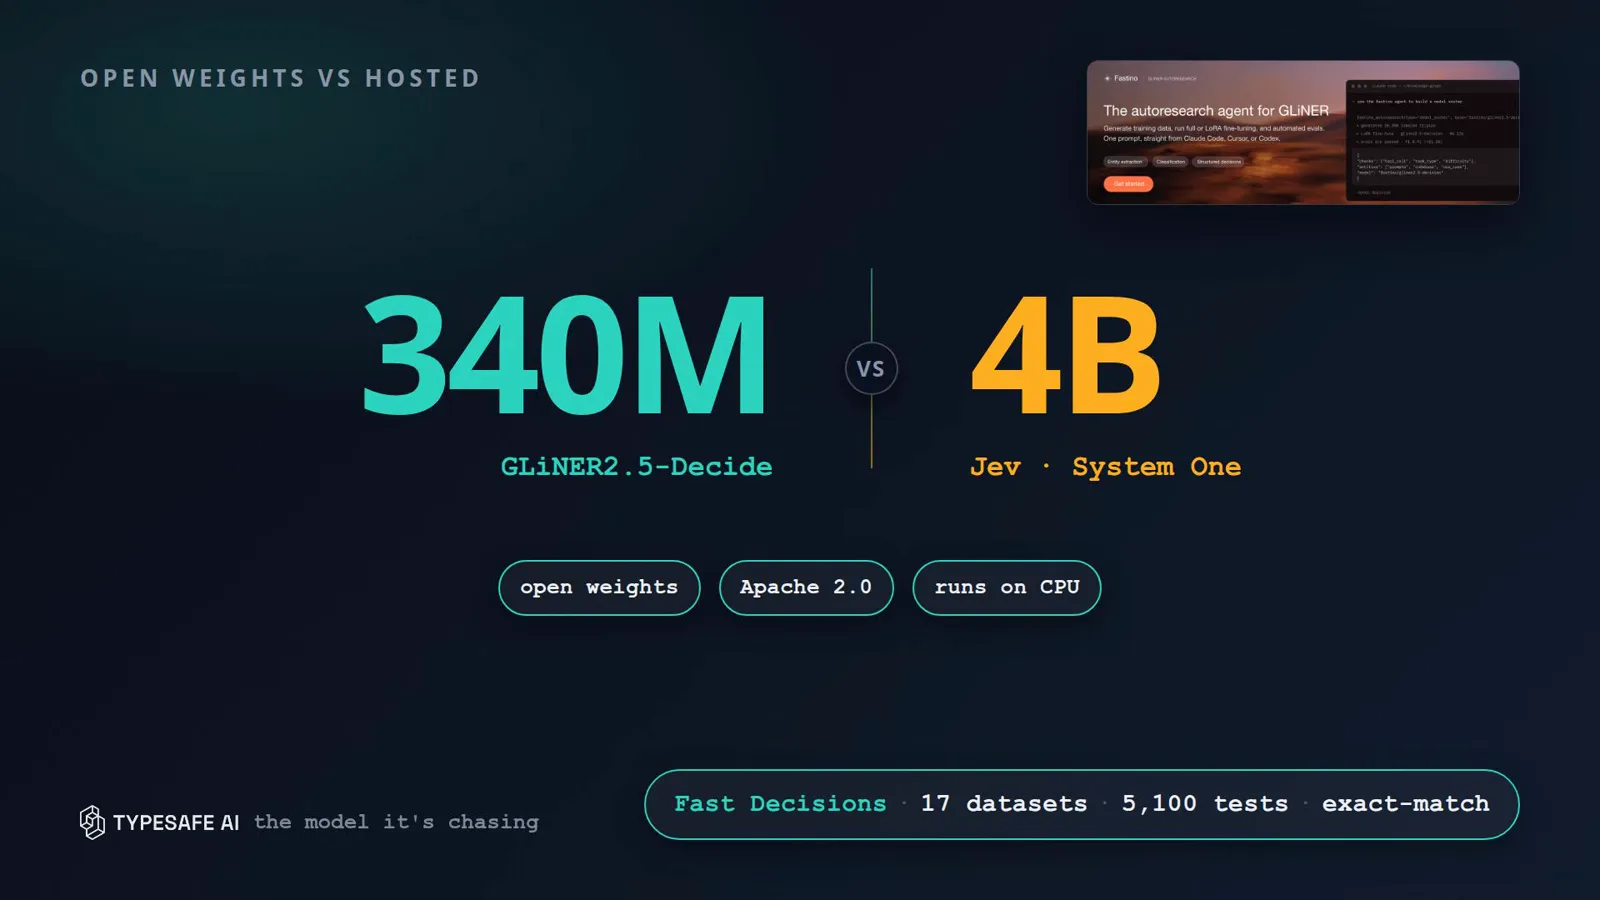
GLiNER2.5-Decide (340M) vs Jev (4B): Which Decision Model Actually Wins? A Frame-by-Frame Selection Guide
GLiNER2.5-Decide is a 340 million parameter text encoder from Fastino — a fine-tune of the GLiNER-2-large line with a DeBERTa-v3-large encoder under the hood (confirmed against the fastino/GLiNER2.5-Decide config on Hugging Face; the narration mangles the name) — and the video’s thesis is blunt: it outran 4 billion parameter decision models on 17 real routing and classification datasets, 5,100 held-out test examples, exact-match scoring, as open weights under Apache 2.0 that run on a CPU. This walkthrough follows the head-to-head card by card and checks every number against the frame: the two-line onboarding (pip, AutoExtractor, a plain Python dict of labels — no prompt template, no generated tokens, no API key); the Kahneman framing where Jev plays System 1 with three primitives (choice, score, noul) answered in parallel with calibrated probabilities at $0.042 per million input tokens and free output — TypeSafe’s public rate, appearing on this site for the first time; the architectural fork, where GLiNER scores every permitted answer in a single forward pass and a constrained decoder searches for the highest-scoring joint assignment the rules allow, while the Jev family evaluates each question independently in parallel and no question ever sees another; the centerpiece, where a prompt-injection attempt scored question-by-question reads harm_type=prompt_injection 0.82 but safety=safe 0.52 — it saw the attack and still labeled it safe — until one rule (“detected harm ⇒ unsafe”) makes joint decoding return the coherent pair, safety=unsafe plus harm=prompt_injection, that two independent readouts would have waved through; Fastino’s own fast-decisions benchmark (17 subsets × 300 held-out = 5,100 test cases, all English, one wrong label voids the whole decision); the scoreboard where GLiNER2.5-Decide averages 60.2 ahead of Decide-1B 59.6, JevK5 57.6, GLiNER2.5-multi 56.7, SemIf 56.4, GLiFormer 49 and Laya 46.6 — with support intent won at 75.3% (+18.6 over the runner-up), banking intent at 64.3% (+8.6) and nine of the seventeen datasets led outright; latency of 38.3 ms on a V100 at batch 1 and 64 tokens with all five GPUs inside 9 ms of each other and a CPU-only 48-vCPU Xeon at 167.3 ms; and the counter-ledger — JevBench v1.4.2, an independent, MIT-licensed, four-axis blended score — where decider-4b v2 leads, Jev 1.13.0 sits second at 63.29, JevK5 third at 62.04, and the GLiNER family shows up at 63.1 (multi) and 62.1 (small — frame-verified against the narration). Different bench, different winner. The video then volunteers three caveats most head-to-heads bury, and closes on a 2×2 selection matrix with one deliberately empty quadrant: hosted and calibrated points to Jev, air-gapped silicon with cross-question rules and character-level spans points to GLiNER2.5-Decide, and the Jev request shape on your own GPU points to JevK5.
Read guide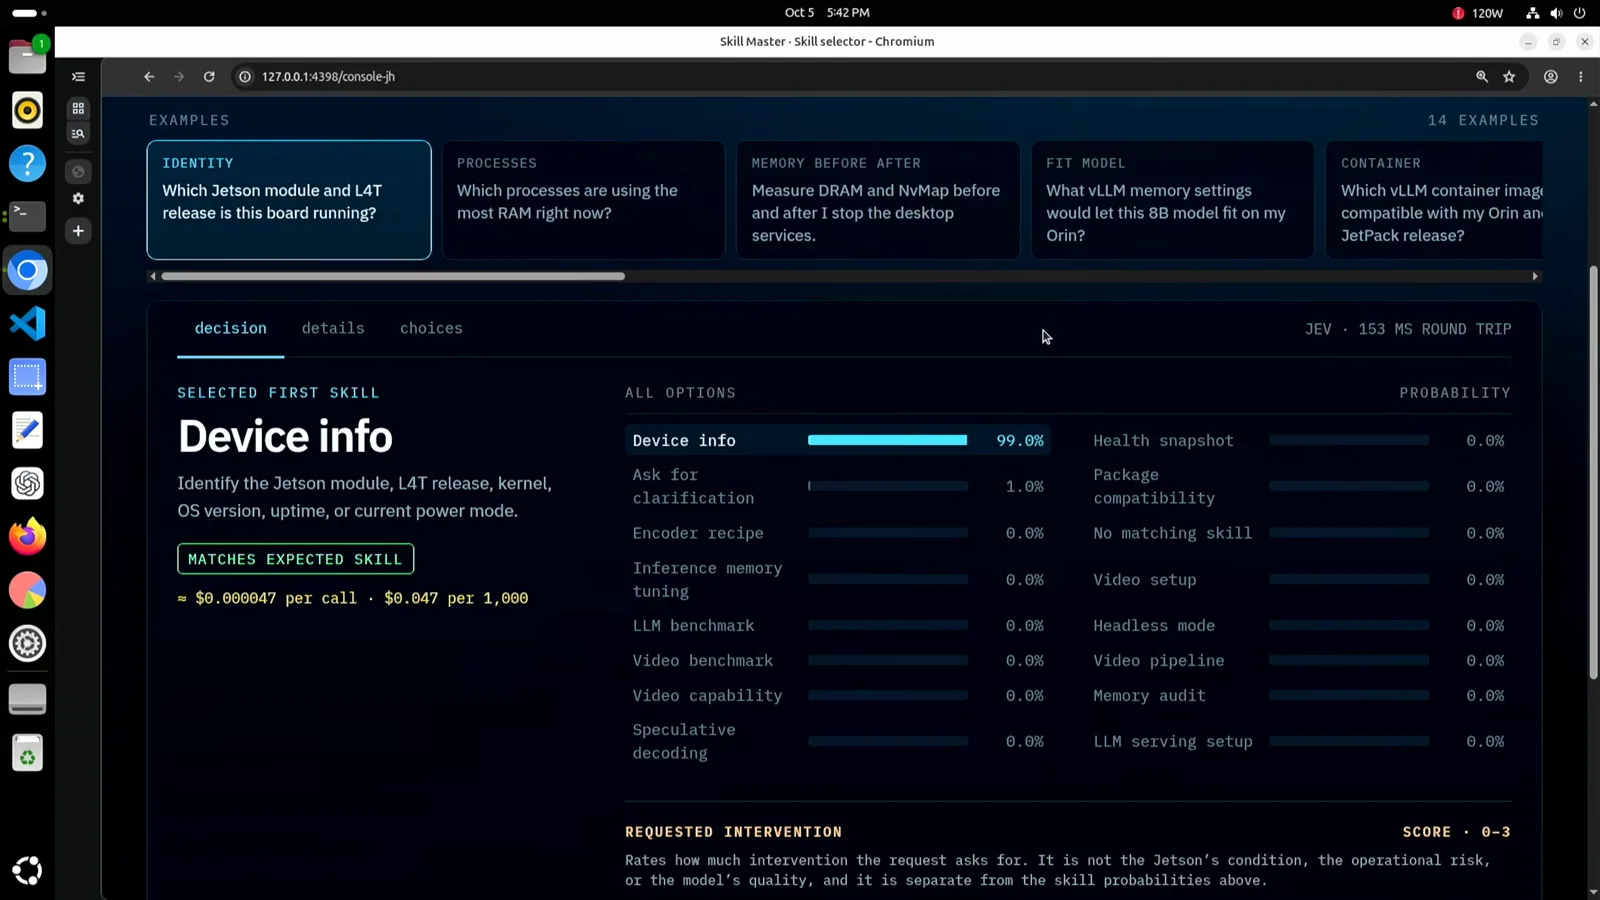
Decision Models on Jetson: Jev vs Strands Decider 2B vs Laya vs d1-3B — Skill Master Scores, Thor Latency and JevBench, Every Number Frame-Checked
Skill Master is a test harness Jim built at jetsonhacks.com to answer one question: can the new crop of decision models actually carry their weight on Jetson-class hardware? The app sends the same query to multiple models and lines up the answers — a hosted Jev tab beside three small open-weight locals, AWS Strands Decider 2B, Laya and Liquid AI’s d1-3B, chosen for one reason: they are small enough for Jetson memory. Fourteen example tasks (identity, processes, memory before/after, fit model, container, serve, LLM performance, speculate, codec support, video ready, transcode, video speed, vague, outside-the-catalog) get fired at every model, and every number on this page was checked against the on-screen frames. The demo opens with Jev answering “Which Jetson module and L4T release is this board running?” with Device info at 99.0% — Ask for clarification gets the other 1.0%, everything else 0.0% — in a 153 ms round trip, at a displayed cost of about $0.000047 per call. Then he deliberately breaks it: a vLLM setup question where the winning option “LLM serving setup” lands at only 45.0% (Ask for clarification 27.0%, Package compatibility 15.0%) — below the narrator’s rule that you usually want over 60% to trust a choice — while the requested-intervention question fires 2.99 on the 0–3 scale at 99% confidence, most probable level “Change and verify,” all inside the 137 ms round trip he cites. A vague “Can you check it?” returns Ask for clarification at 100.0% (intervention 0.11, most probable level Inspect — which he finds a bit off), and “Write a poem about a robot dinosaur” gets No matching skill at 100.0%, because the request is clear but outside the catalog. The wire format is TypeSafe’s SystemOne API (api.typesafe.ai/v1/systemone): model jev-latest, the user’s request as state, and a choice question named skill whose instructions demand clarify or no_matching_skill when warranted and whose criteria map the full option set — fourteen Jetson skills plus clarify and no_matching_skill — to plain-English descriptions; the response comes back as model jev-1.13.0 with typed answers, confidence, and for score questions a legend plus per-level probabilities (the intervention scale runs 0 Inspect / 1 Measure / 2 Recommend / 3 Change and verify). A diagram card fixes the taxonomy: all three model types share the input phase — prompt, encoding (pre-fill), contextual representation — and differ only downstream: a classifier answers with a label fixed by training, an LLM writes free text one token per pass, and a decision model picks among options you can change at run time and answers noul, choice or score in a single pass. Then the hardware: on an Orin Nano, Strands and d1-3B consume most of the memory while Laya — the smallest model in the group, and the weakest — squeezes in; on a larger Orin or a Jetson AGX Thor everything fits comfortably. Results, card by card: Jev 14/14 correct at an average 150 ms per decision (1,109 tokens in, 222 out; 12 A grades, 1 B, 1 C — the C on the serve case, matching that low-confidence vLLM answer); Strands 14/14 at an average 353 ms (794 in, 354 out; 10 A, 4 B); Laya 8/14; d1-3B 14/14 (9 A, 4 B, 1 C). The identity question separates them — Jev 99%, Strands a shaky 61%, Laya flat wrong, d1-3B in between — and the maintenance question flips the order: d1-3B posts the highest probability of all four, Strands runs far ahead of Jev, whose serve answer only managed 45%. Against Claude, which averaged about 2.5 seconds to pick a skill, Jev’s ~135 ms is an 18× win — the vendor’s “10–20× faster than a regular LLM” claim fully holds in this test. The deployment math is the centerpiece: running directly on Thor, these small models decide in 30–50 ms, but wrapped in a FastAPI server emulating the TypeSafe Jev API they gain 75–100 ms — the benchmark numbers actually underestimate local models, and skipping the server roughly doubles speed again. On JevBench the card reads Jev 1.13.0 86.6% (200/231), d1-3B 75.3% (174/231), Strands V19 72.3% (167/231): near-identical on easy questions, Jev slightly ahead on standard ones, decisively ahead on hard ones — yet for the task types these models actually get hired for (routing, policy decisions, tool selection, complex routing), all three are essentially equivalent, and only the local ones can be fine-tuned to your workload. The closing card is the thesis: the application defines the decision table — a noul, a choice where clarify is “a category too,” a 0–3 intervention score — so a new decision needs a new context, not a retraining run; but the flexibility bills you on the application side, in instructions, category lists and combination tests. The model is simpler and much faster; the system doesn’t have to be.
Read guide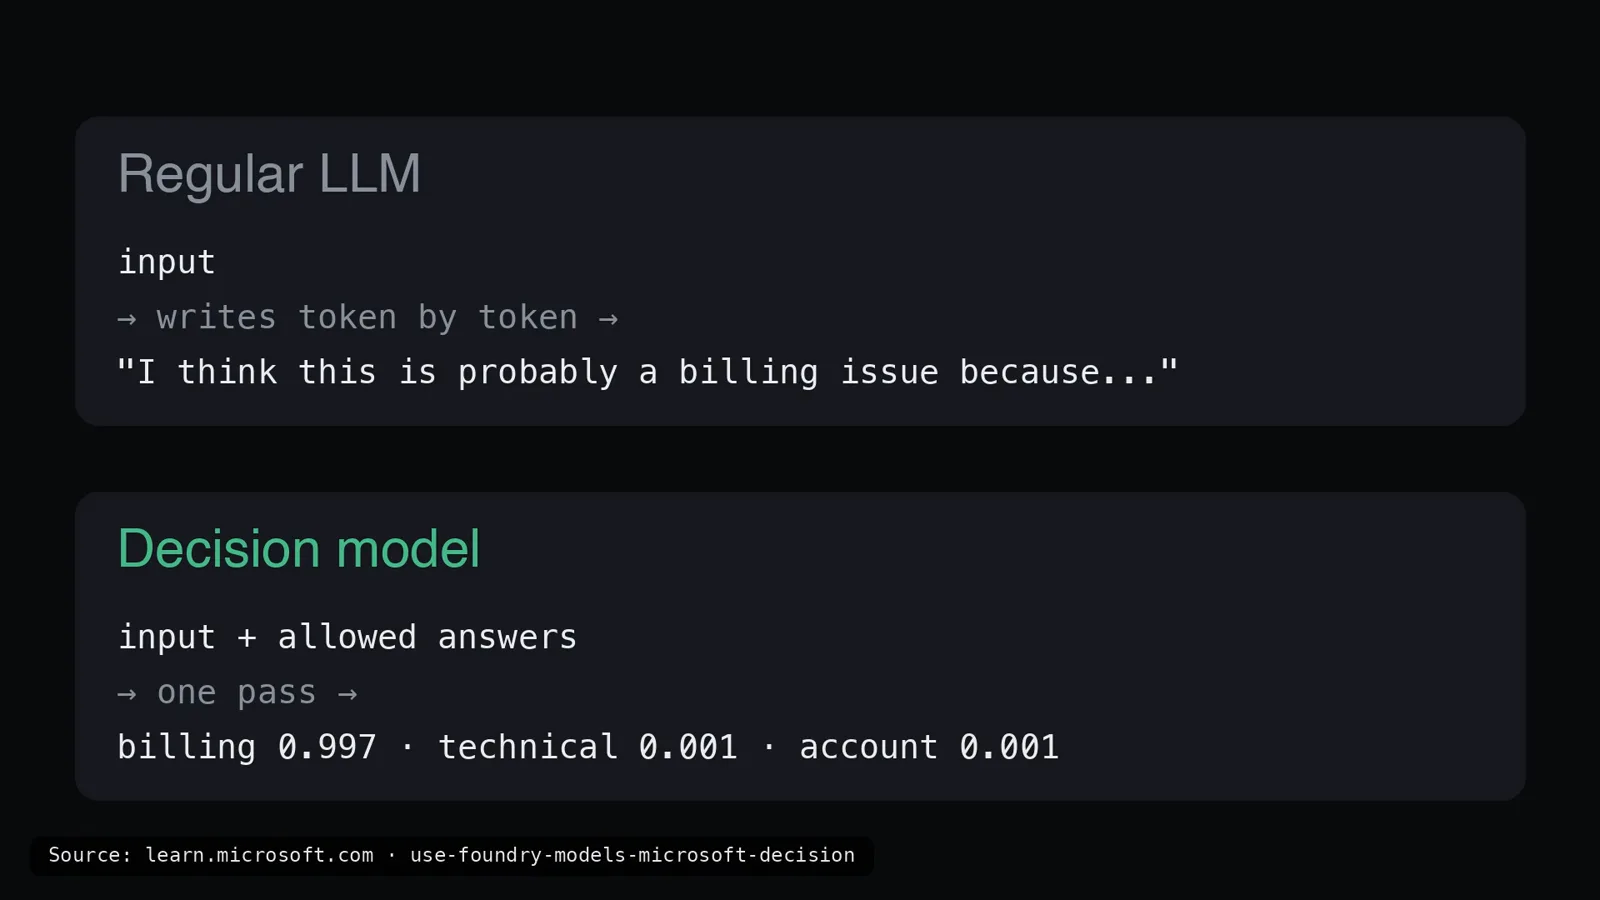
Microsoft Decision-1 Tested: 146 Independent Tests, a 93% Mean, 124/125 When Confident — Every Number Frame-Checked
Microsoft Decision-1 (released October 9, 2026; OpenRouter id microsoft/microsoft-decision-1) is Microsoft’s entry into the decision-model wave: a model that never writes a sentence — it reads a state once and returns a calibrated probability for each allowed answer, priced at $0.042 per million input tokens with output free. One naming note before the numbers: Decision-1 is a product name with a hyphen, not a claim to being “the first decision model” — the video’s own timeline card shows it arriving last. That card puts the whole five-week arc in one line: Jev (TypeSafe, Sep) → Laya (open source, Sep) → Clef (Cloudflare, Oct 1) → Decider v1.1 (Perplexity, Oct 6) → Decisions API (OpenAI, Oct 6) → d1 (Liquid AI, Oct 7) → Decision-1 (Microsoft, Oct 9) — and Microsoft even evaluates itself on the Jev benchmark. Per the video, the base is Alibaba’s open Qwen3.5 with 9 billion parameters, retrained by Microsoft to evaluate responses in a single pass, with a stated plan to transfer the recipe to Microsoft’s own and OpenAI models; there is one size and it only reads text. The explainer card, sourced from Microsoft’s own docs, draws the category line: a regular LLM takes the input and writes token by token (“I think this is probably a billing issue because…”), while a decision model takes input plus allowed answers and makes one pass — billing 0.997, technical 0.001, account 0.001 — so your code receives a number and acts: continue when confident, hand the task to a human when not. The vendor cards, literally headed “Microsoft says / vendor-reported”, claim top accuracy on 36 benchmarks with ~150,000 held-out questions it never studied, median latency 35× faster than GPT-6 Sol, 200× cheaper than GPT-6 Sol on 10,000+ Xbox feedback items at similar quality, and answers that flip on only 1.3% of reworded or reordered requests. The reviewer wanted his own numbers instead: 146 tests in 17 sets, each with a known correct answer, plus 36 long-document calls (a clause hidden at the top, middle or end) and 180 reworded or reordered requests — everything through OpenRouter with no Azure configuration, run from a laptop in Bengaluru on 12 October 2026. Result: a 93% mean, with ten of seventeen sets at 100% — ticket routing, gamer feedback themes, phishing emails, prompt injection, content moderation, JSON validation, multilingual (10 languages plus code-mixes: Hindi, Kannada, Tamil, Japanese, Arabic, and Hinglish like “Bro, OTP is not coming at all”), code vulnerabilities, fraud on CSV rows, and HTML page type; on camera, a French “I’d like an invoice for last month’s payment” routes to billing and a German “my package is marked delivered but never arrived” routes to shipping, each at 99.9%. The remaining seven sets are where it slipped: model routing 90%, bug severity 88%, multi-question call 88%, LLM-as-judge 81%, log triage 81%, agent guardrail 80%, search relevance 75% — every miss a matter of judgment, and both quoted error examples err on the cautious side (demanding approval before a harmless code fix; flagging a true additional fact as a hallucination), which the reviewer considers the right failure mode for a guardrail. The calibration pair is the video’s centerpiece: above 90% confidence the model was right 124/125 times; below 70% it was right 2/7; calibration error 0.025 (lower is better) — so the confidence number works as a routing gate: let it act when confident, send the rest to a person or a larger model. Robustness: 180 perturbed requests — shuffled options, changed order, renamed to A/B/C, rephrased, random spaces added, whole text wrapped in JSON — produced zero answer flips, making Microsoft’s 1.3% look conservative on this dataset. Long documents: the hidden pet clause was found every time up to ~19,000 tokens; at ~33,000 the API refused outright — the hard limit is 32,768 tokens including the decision token (HTTP 422), so split long inputs first. Speed: a median of ~620 ms from Bengaluru via OpenRouter to Azure against the ~230 ms listed on OpenRouter’s own page — most of the wait is network. The entire experiment cost about one US cent. The closing argument doubles as this page’s: don’t think chatbot, think a management layer for your agents — something that directs, labels, evaluates and blocks — accurate, unbothered by rephrasing, and, most importantly, aware of when it isn’t sure. Every number above was checked against the on-screen card it came from, and every self-test number is the uploader’s own small sample, not a benchmark.
Read guide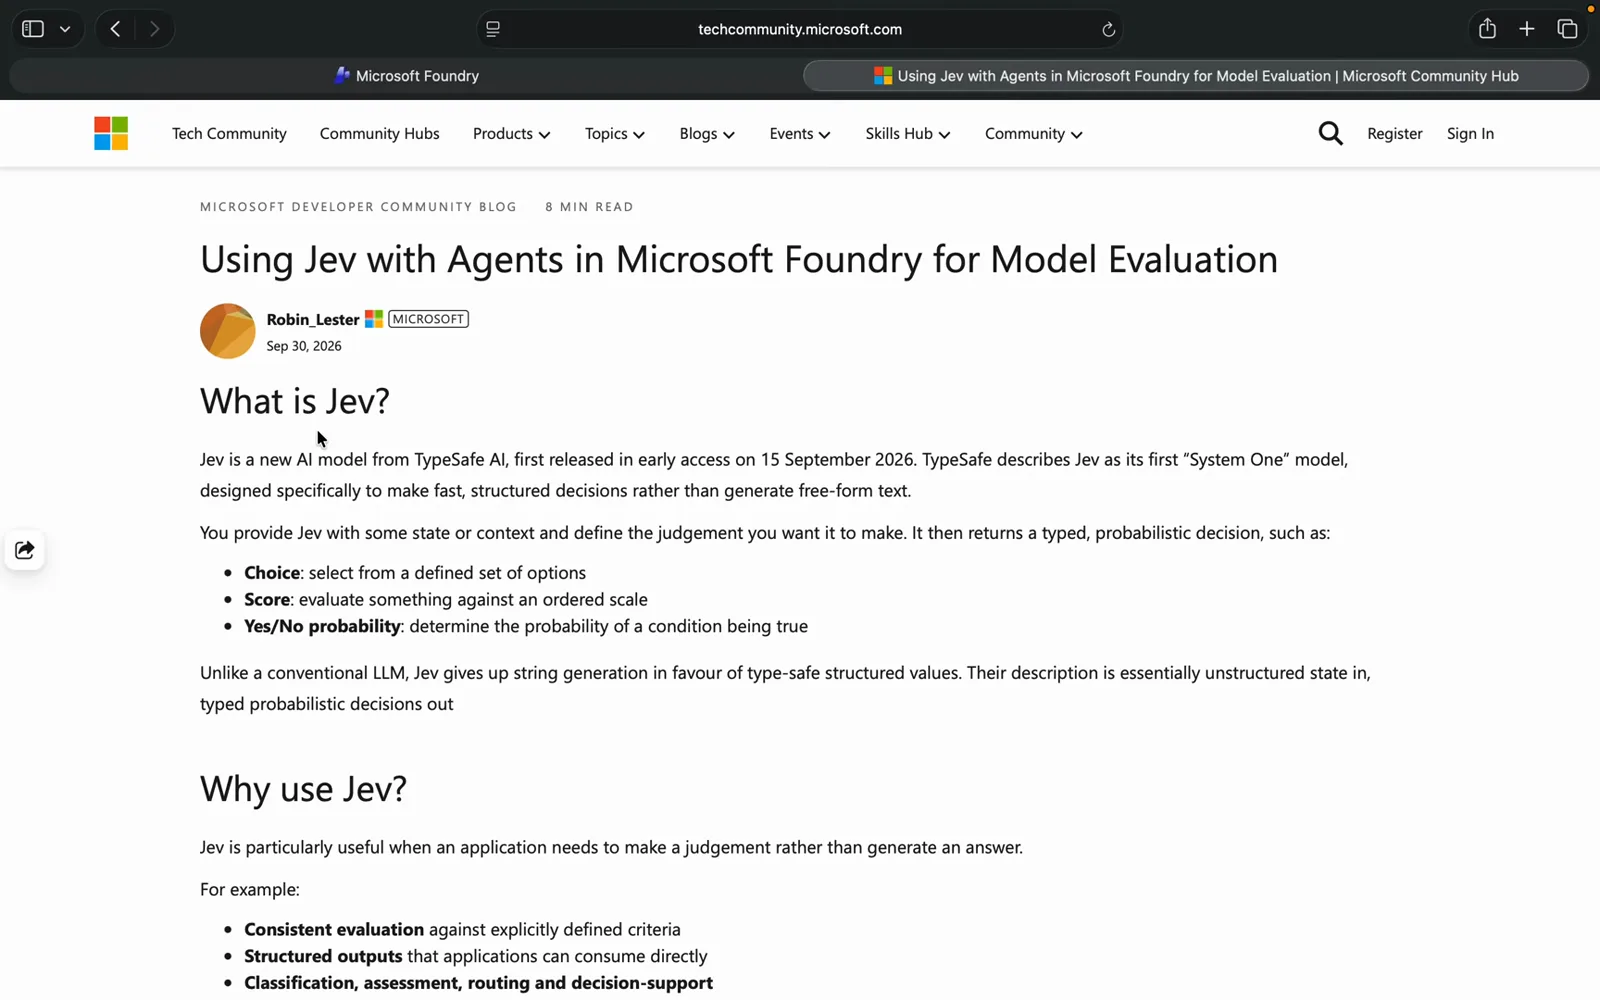
Wire Jev into an Azure AI Foundry Agent as the Evaluation Layer — OpenAPI Tool, TypeSafe Connection, Triage Instructions and an Honest First-Run Failure
Azure AI Foundry is the seventh wall of the Jev integration family, and Mohamed Naji Aboo walks the whole thing on camera, following Robin Lester’s Microsoft Tech Community tutorial “Using Jev with Agents in Microsoft Foundry for Model Evaluation” (Sep 30, 2026). The pattern: a Foundry agent runs GPT-5 mini as the conversation layer, and Jev — TypeSafe AI’s “System One” decision model, in early access since 15 September 2026 — attaches as an OpenAPI custom tool that judges every customer message. The walkthrough in frames: deploy gpt-5-mini (a 400K-context, text+image-in/text-out model capped at 272k input and 128k output tokens); create the agent (auto-named sincere-agent-21673j20y4, Text interaction mode); claim the $5 free credit at console.typesafe.ai and create an API key; in Tools pick the OpenAPI tool over MCP and Agent2Agent; name it JevTest and put the TypeSafe key into a new connection (host https://api.typesafe.ai); paste the tutorial’s ~200-line OpenAPI 3.0 schema — POST /eval requiring exactly state, model and questions, model enum-locked to jev-latest, apiKey-in-header security satisfied by the connection; then save the triage instructions: “For every customer-support message you MUST call the evaluate_with_jev tool… Do not classify the ticket yourself. Use the values returned by Jev. Always show the Jev output at the end of the response.” The test complaint — “The room had no water in and one of the towels was dirty” — then delivers the video’s most valuable minutes: the first run answers with a flawless apology and zero Jev calls, even confessing “I attempted to run our automated classifier but it was unavailable” before improvising its own labels; the retry states plainly that the tool “isn’t available here” and instead prints the three question payloads (billing as noul; tone as choice over calm/frustrated/angry; urgency as score on 1–3) plus an illustrated response — noul “true”, choice “frustrated”, score 3. Neither on-screen run shows a live callback; the wiring is the lesson, the failure review is the honesty, and that shape is what to verify in Traces on your own project.
Read guideMental Model Shift: Conversational LLM vs Jev Decision Model
| Dimension | Generative LLM (Chat / Free Text) | Jev Typed Decision Model |
|---|---|---|
| Output Format | Unbounded text strings; relies on prompt hacks or regex to parse JSON | Strict categorical options (Choice), scalar values (Score), or binary gates (Noul) |
| Code Integration | Fragile JSON deserialization; vulnerable to schema mismatches | Direct switch/case branching: `if (answer === "refund")`, fully type-safe |
| Confidence Metric | No calibrated uncertainty signal; verbal self-evaluations are often overconfident | Native normalized probability distribution (e.g. `shipping: 0.91`) for thresholding |
| Failure Mode | Hallucinations and verbose tangents that can corrupt downstream logic | Gracefully diverted to human triage or deterministic rule fallback on low confidence |
| Latency & Cost | Autoregressive multi-token generation incurring high latency (1s+) and high token costs | Single-step forward classification returning in sub-second latency with minimal tokens |
Frequently Asked Questions (FAQ)
How does Jev differ from GPT-4o / Claude Structured Outputs?
While traditional LLMs generate JSON by predicting tokens sequentially (which is slow, costly, and lacks calibrated uncertainty), Jev is a dedicated decision model that computes classification probabilities directly over bounded options. This yields faster response times, lower token overhead, and native confidence scores.
Do I need complex prompt engineering to use Jev effectively?
No. Jev eliminates conversational fluff. Inputs consist of `state` (the factual context) and `criteria` (unambiguous descriptions for each option). Writing criteria mirrors drafting a clean team SOP (e.g., "refund: user is requesting financial reimbursement") rather than coaxing an AI persona.
What is Confidence and how should production thresholds be set?
Confidence represents the model posterior probability for its decision (0 to 1). In production routing or moderation, scores above 0.85 or 0.90 typically trigger automated action; scores between 0.50 and 0.85 can be routed to human review; and scores below 0.50 should trigger safe default fallbacks.
What is the recommended architecture for calling Jev in web applications?
Always call Jev from a secure backend service (such as Next.js API Routes, Express, or Cloudflare Workers) rather than directly from browser clients. This protects provider API keys, allows sanitizing state data, and enables immediate enforcement of fallback routines before responding to clients.
Does Jev suffer from generative AI hallucinations?
Because Jev outputs are structurally bounded to predefined discrete options, numbers, or boolean values, it cannot invent imaginary facts or generate invalid schema keys. Risk is confined to classification ambiguity on edge cases, which is explicitly mitigated through confidence thresholding.