
Guides / illustrated walkthrough
OpenJev 0.8B on CPU: I Built a Ticket-Routing Inbox and Calibrated the Thresholds
A working support-ticket inbox on the independent OpenJev 0.8B NLI checkpoint: premise-hypothesis scoring on CPU, a routing rule calibrated in two versions with its trade-offs on camera, and an evaluation the video refuses to inflate.
Quick takeaway
Call Stack builds a real application — a support-ticket inbox — around the independent OpenJev 0.8B checkpoint: AlexWortega's, NLI-trained, and explicitly not the official TypeSafe Jev ('shared naming does not transfer the official model's performance claims'). The mechanics: each ticket is a premise scored against four department hypotheses (refund, billing, login, broken functionality), each pair returning contradiction/entailment/neutral, and the adapter reads the numbers directly — no generated replies. A refund demo hits about 0.995 entailment; routing rule v1 takes the largest entailment at 0.60 or above with a 0.10 lead, else review. The calibration story is where it gets honest: a ticket naming login trouble plus a duplicate charge scores billing 0.97 and login 0.78 — v1 routes billing and silently drops the second real issue — so v2 adds one condition (multiple propositions over threshold means review) and the same ticket becomes Human Review. The cost gets billed on camera: a clean refund request (refund 0.9883, billing 0.7277) that v1 routed correctly is deferred into the review queue. Three misses are diagnosed at the JSON level — a password-reset ticket where bug (0.687) beats login (0.491) on taxonomy overlap, an invoice-copy request under a too-narrow billing hypothesis, and a praise message with no category at all — and the frozen test set reports 2/4 calibration and 7/12 held-out, counts the video defines as model + taxonomy + routing logic together, not standalone model accuracy. Footprint: 1.71 GB weights, 3.20 GB peak RSS, float32 on CPU, 5.63 s median per request, offline after download. The recommended deployment shape is a suggestion queue with a human approving — local inference removes one data transfer, not every risk.
Video source
Call Stack
Step-by-step walkthrough
- 1
The experiment: a real inbox app, and its boundaries
The video fences the experiment before running it. The application is an inbox built around AlexWortega's independent OpenJev 0.8B checkpoint, loaded locally on a Mac — no hosted model answers the requests. The tickets are authored support tickets, not customer data, and the card says so on both sides: what the experiment is (independent model, authored tickets, local CPU) and what it is not (not official TypeSafe Jev, no customer data, no cloud inference). That second column frames every number on this page: they describe one checkpoint on one machine inside an authored pilot, not a hosted product.
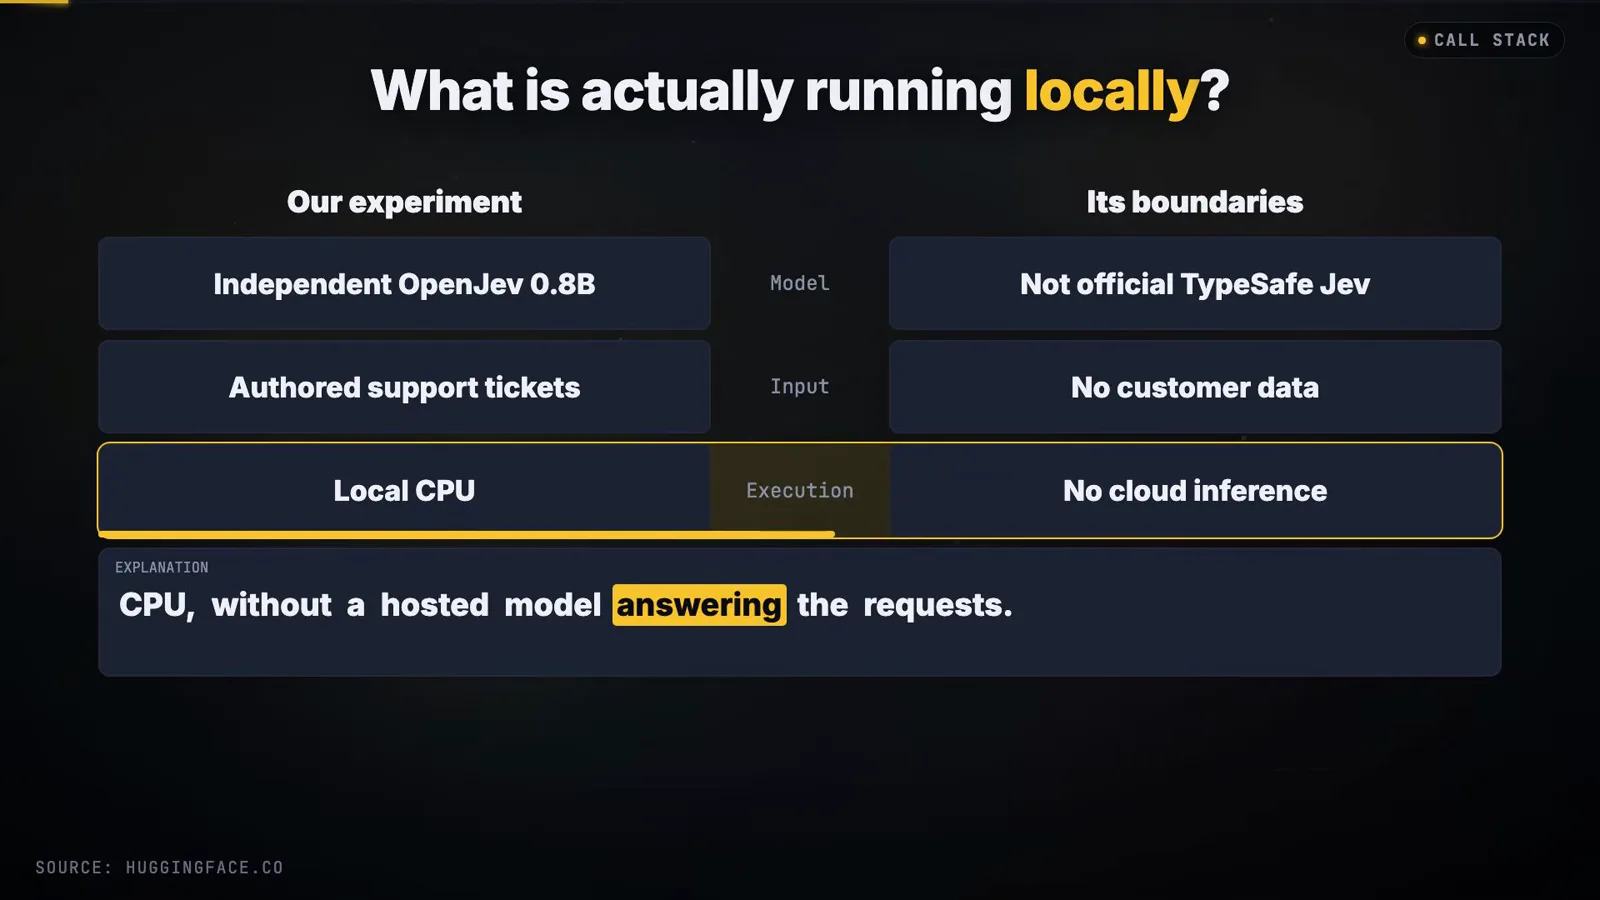
The two-column fence: what the experiment is — and what it explicitly is not.Watch at 0:22 - 2
Shared name, different model: the disclaimer that stays
OpenJev shares its name with TypeSafe's official Jev, and the video stops to kill that confusion on purpose. The distinction card puts the two side by side: publisher TypeSafe versus AlexWortega, training claim of reinforcement learning for calibrated decisions versus NLI cross-entropy, "not tested here" versus "actual local pilot". Then the sentence this page keeps repeating because the video does: shared naming does not transfer the official model's performance claims. Whatever you think of either project, they are different models with different training objectives — evaluating one tells you nothing about the other.
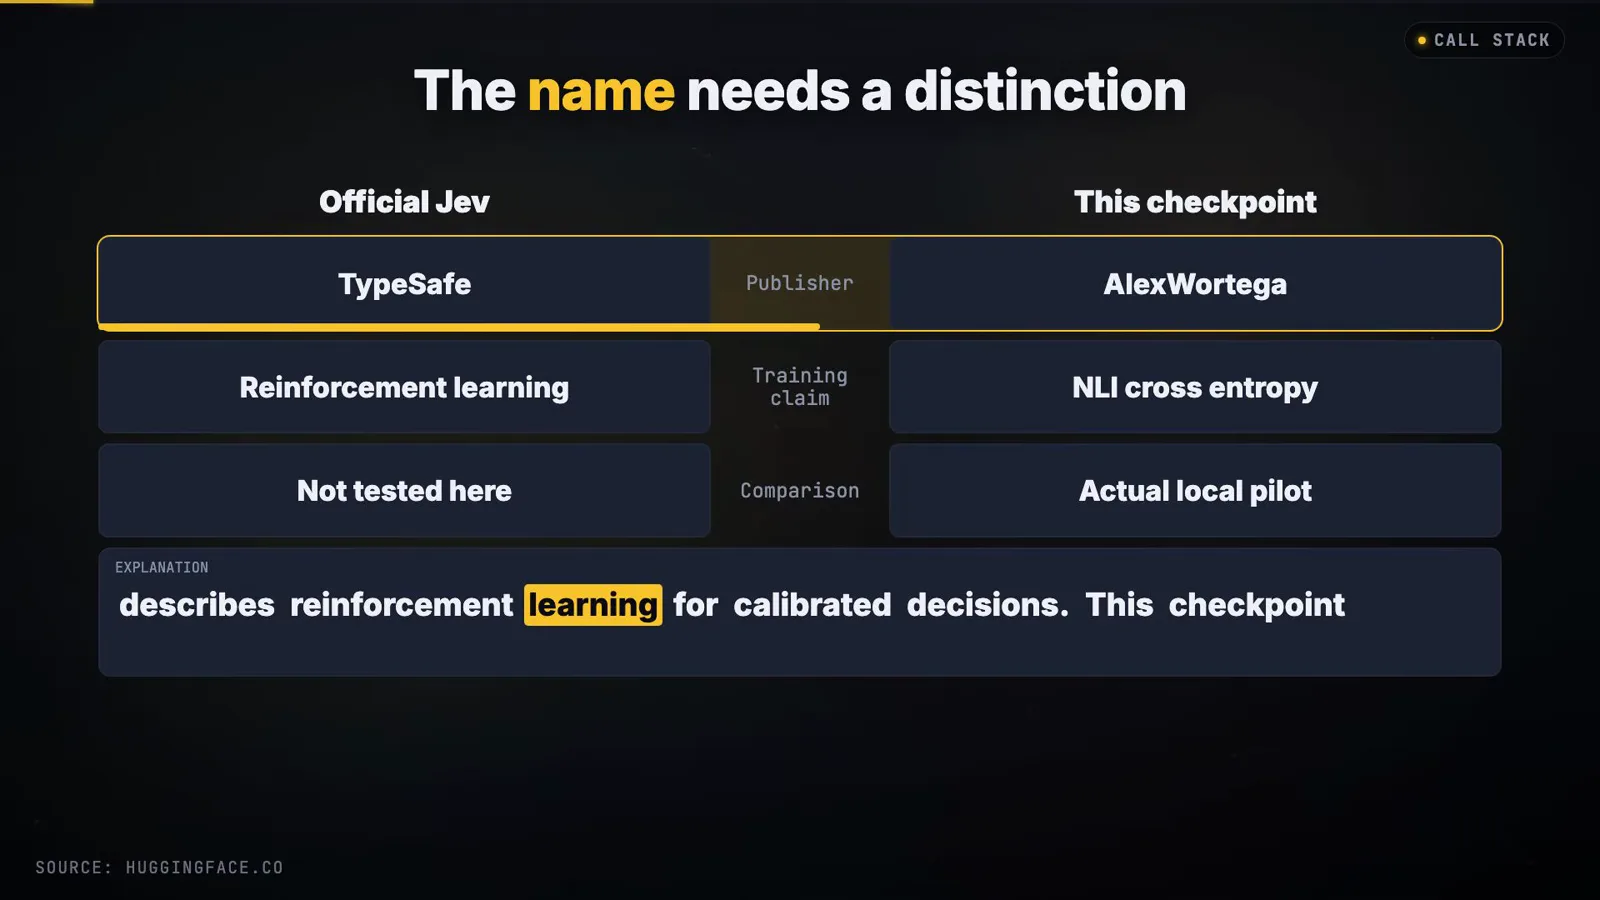
TypeSafe vs AlexWortega, RL vs NLI cross-entropy — different products sharing a name.Watch at 0:30 - 3
One ticket becomes four premise-hypothesis pairs
The model does not read the inbox the way a chatbot does. Each ticket becomes a premise, and each department becomes a hypothesis — a plain statement such as "the customer is requesting a refund". The frame shows the pair for the first demo ticket ("Please refund my unused subscription"); the app evaluates that pair, then repeats it for billing, login, and broken functionality. Four candidates, four separate pairs — and the design decision this whole page turns on: the adapter reads the scores directly instead of asking the model to generate a support reply.
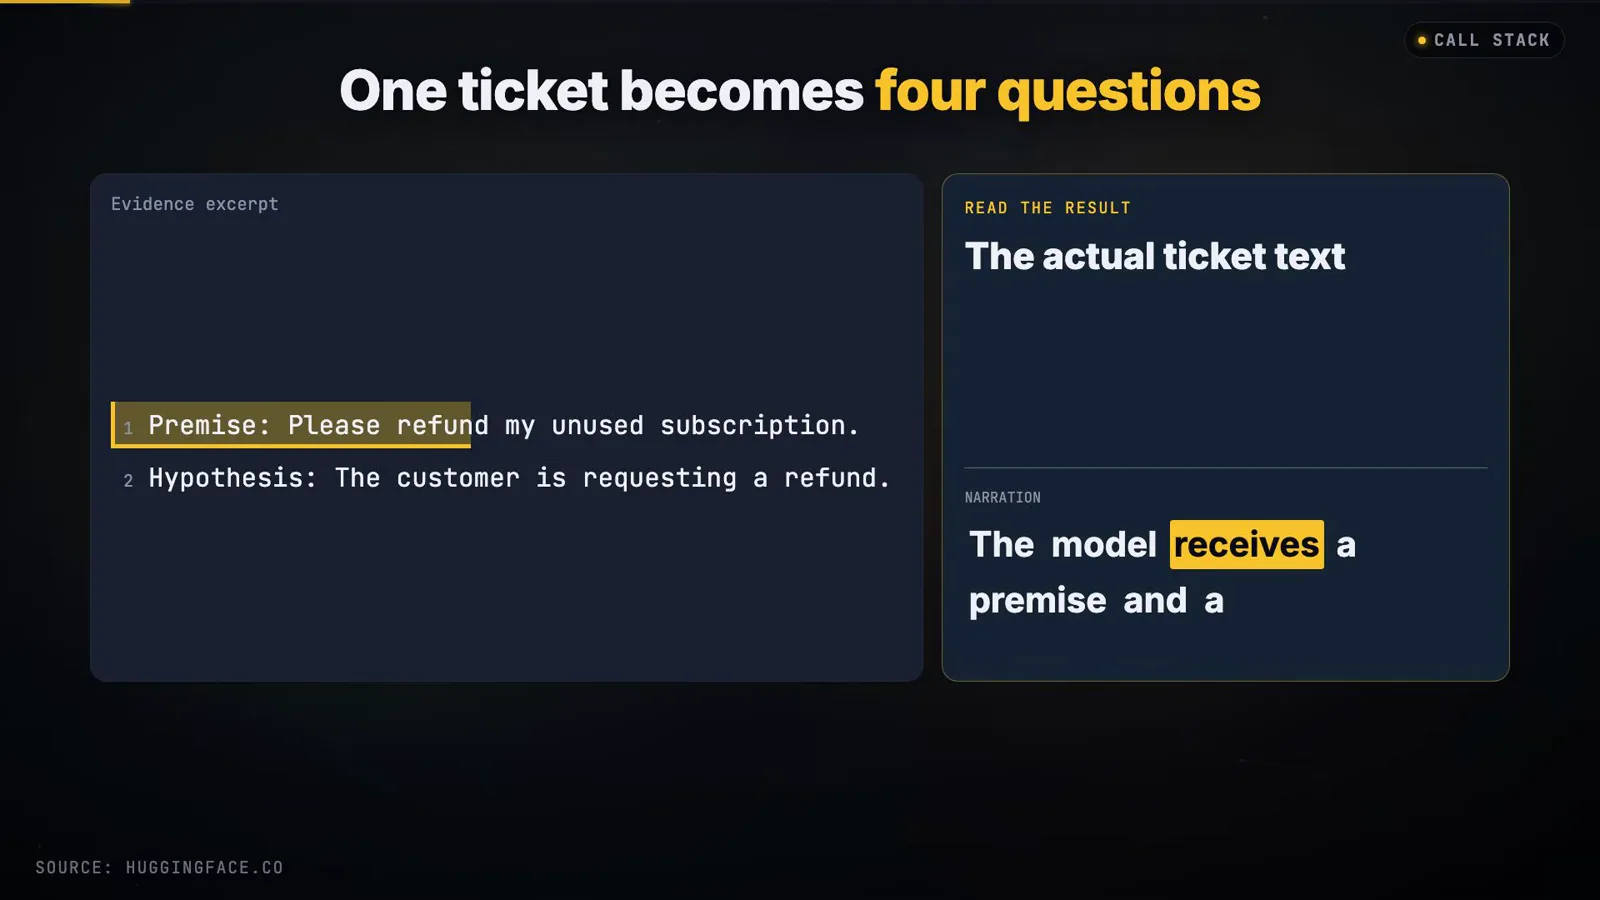
Premise in, one hypothesis per department — the pair is what gets scored.Watch at 0:42 - 4
Three scores per pair, three different meanings
Every premise-hypothesis pair comes back with contradiction, entailment, and neutral scores, and the card gives each a reading: contradiction means the ticket argues against the statement (check what was negated), entailment means it supports the statement (candidate evidence), and neutral means the evidence is missing or unrelated — which is not the same as contradicting it. The demo ticket scores roughly 0.995 entailment against the refund hypothesis, with contradiction and neutral holding the rest of that one proposition's output. The application selects refund, and the exact returned numbers stay visible in the JSON — application output calculated from scores, not generated text.
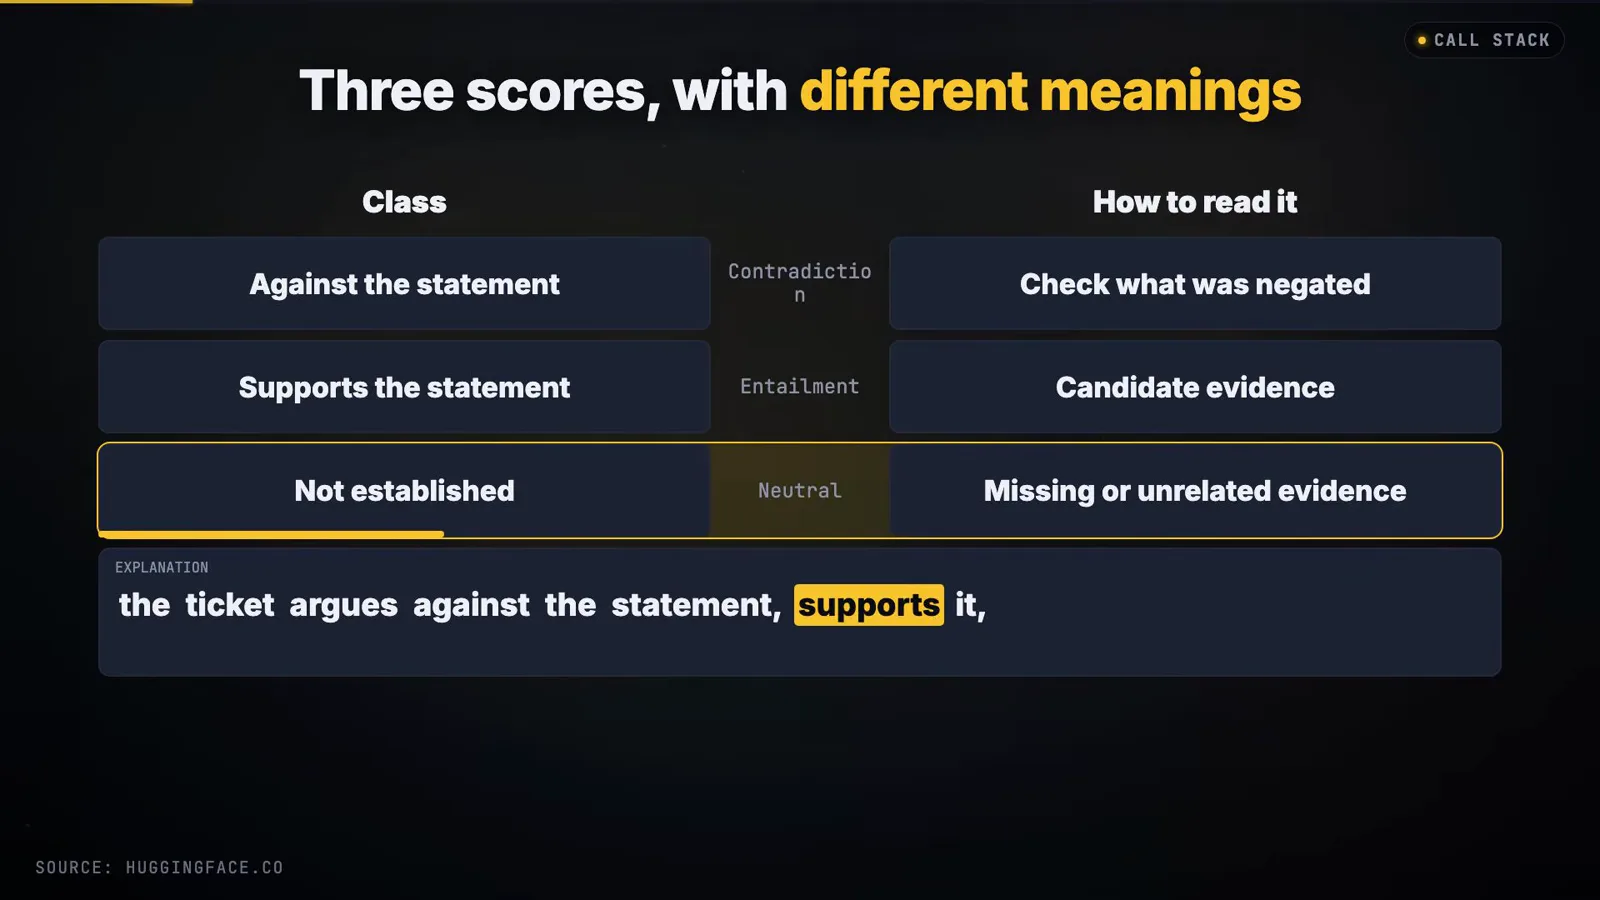
Contradiction, entailment, neutral — and why neutral is not a soft contradiction.Watch at 1:02 - 5
First routed ticket: refund at 99.46% entailment
The first demo ticket runs end to end. The evidence table lists all four propositions with three scores each — refund entailment 99.46% (the narration rounds it to about 0.995), with billing, login, and product bug all under 0.5%. The route banner answers: refund, rule passed, top score 0.9946 with a 0.9904 margin over runner-up billing. Two footnotes on the same frame deserve equal attention: each row sums to 100% but these are not calibrated department probabilities, and entailment across propositions never needed to sum to one in the first place — a ticket can support two department statements at once. That footnote is the seed of the problem two steps ahead. The model request itself took 6.22 seconds on this CPU.
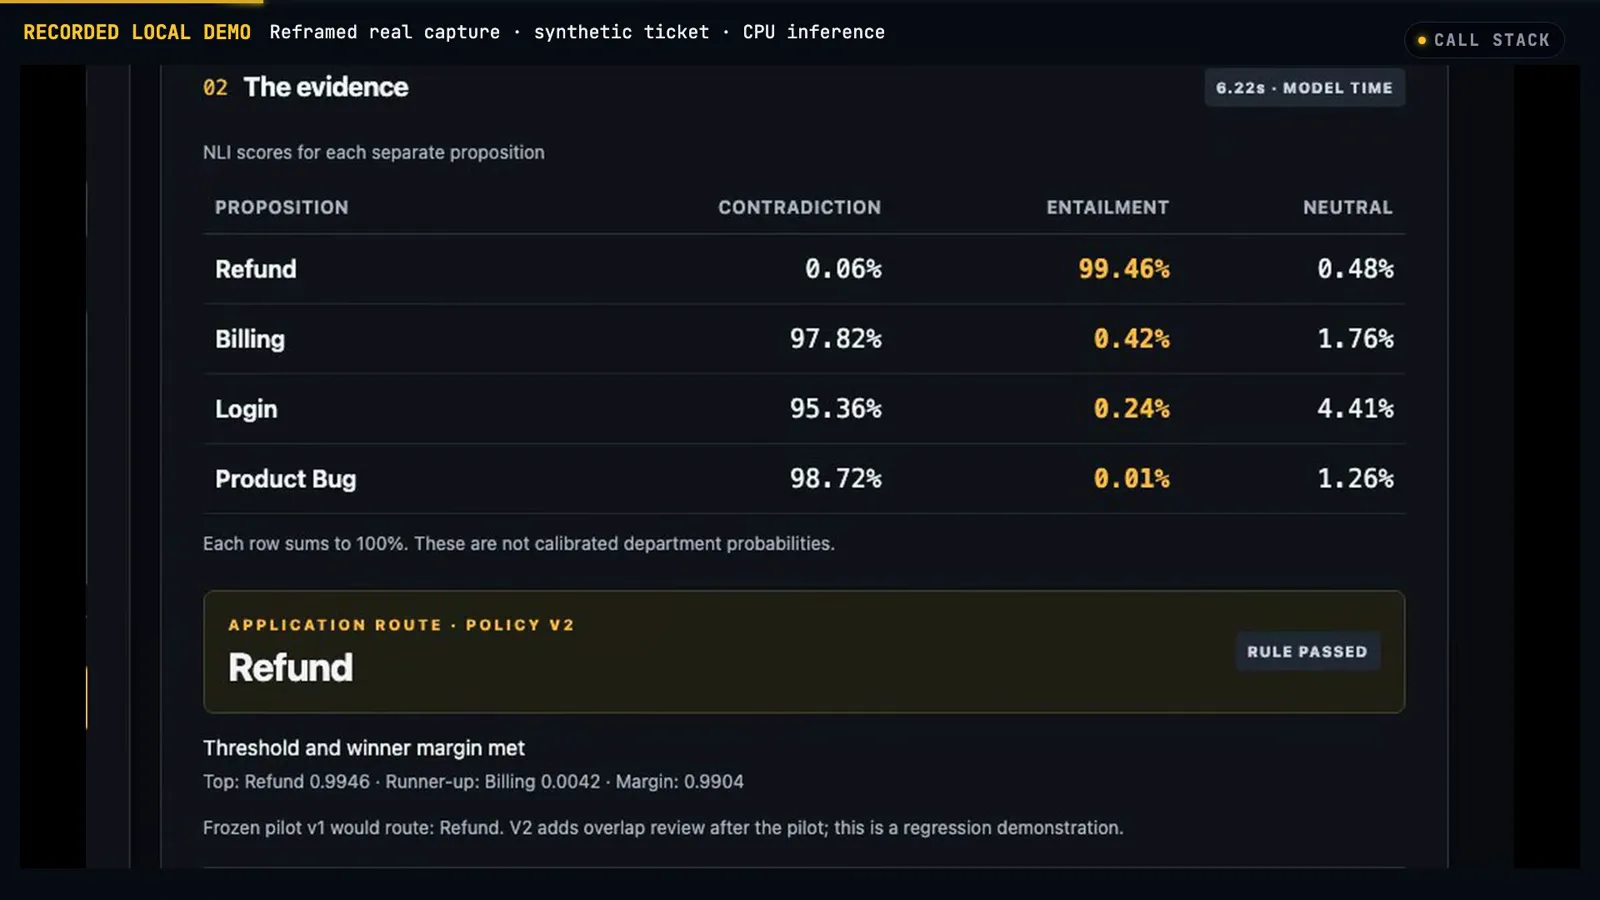
Refund 0.9946, margin 0.9904 — a clean route, with the not-calibrated footnote already visible.Watch at 1:25 - 6
Routing rule v1: 0.60 threshold, 0.10 margin, else review
Scores alone route nothing; the app needs a policy. Version one is three lines: take the largest entailment score, require at least 0.60, require a 0.10 lead over second place, and send everything else to review. The card is careful with its own status — those are provisional thresholds chosen before seeing the pilot outputs, not validated guarantees of correctness. That is the right way around: pick a policy first, then test it, instead of tuning thresholds on the demo outputs and calling the result an evaluation.
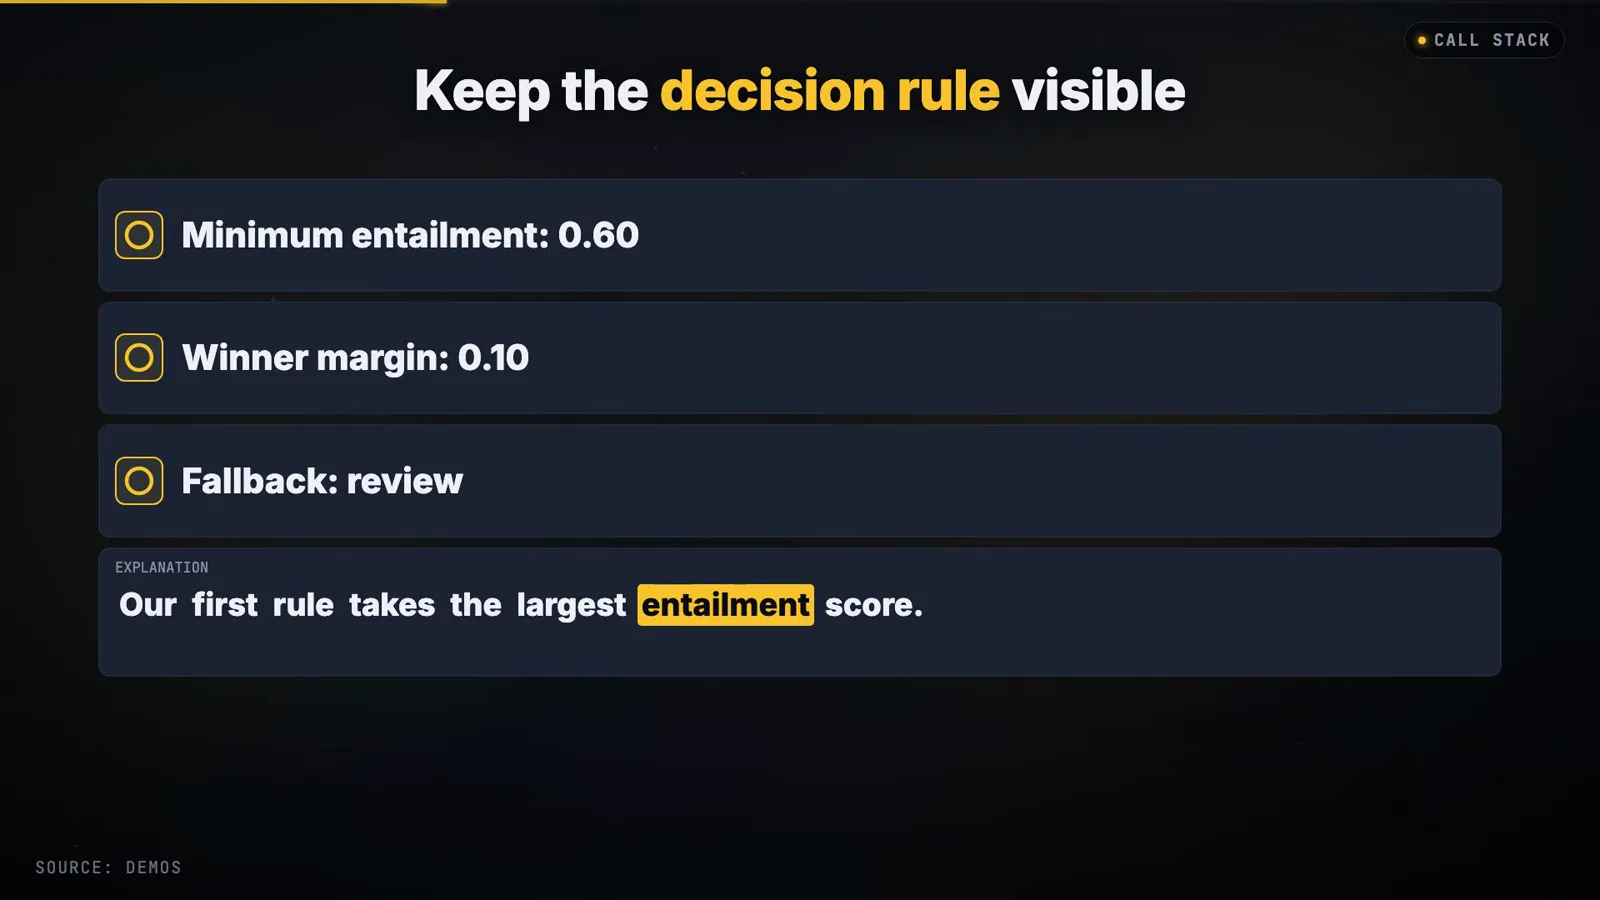
Three numbers define v1 — chosen before the pilot, labeled provisional.Watch at 2:24 - 7
The two-issue ticket v1 silently hid a second problem
The opening ticket of the pilot mentions login trouble and a duplicate charge in the same breath. The model holds up its end: billingEntailment 0.973130, loginEntailment 0.776559 — both clear the 0.60 threshold, and the JSON keeps both numbers. But v1 takes only the largest score, so it routes billing and the login evidence never becomes a decision. The video names this correctly: not a model failure — the login evidence remained in the model output — but a policy limitation, where the application discarded it at the routing stage. The ticket explicitly named both problems, and the rule could only hear one.
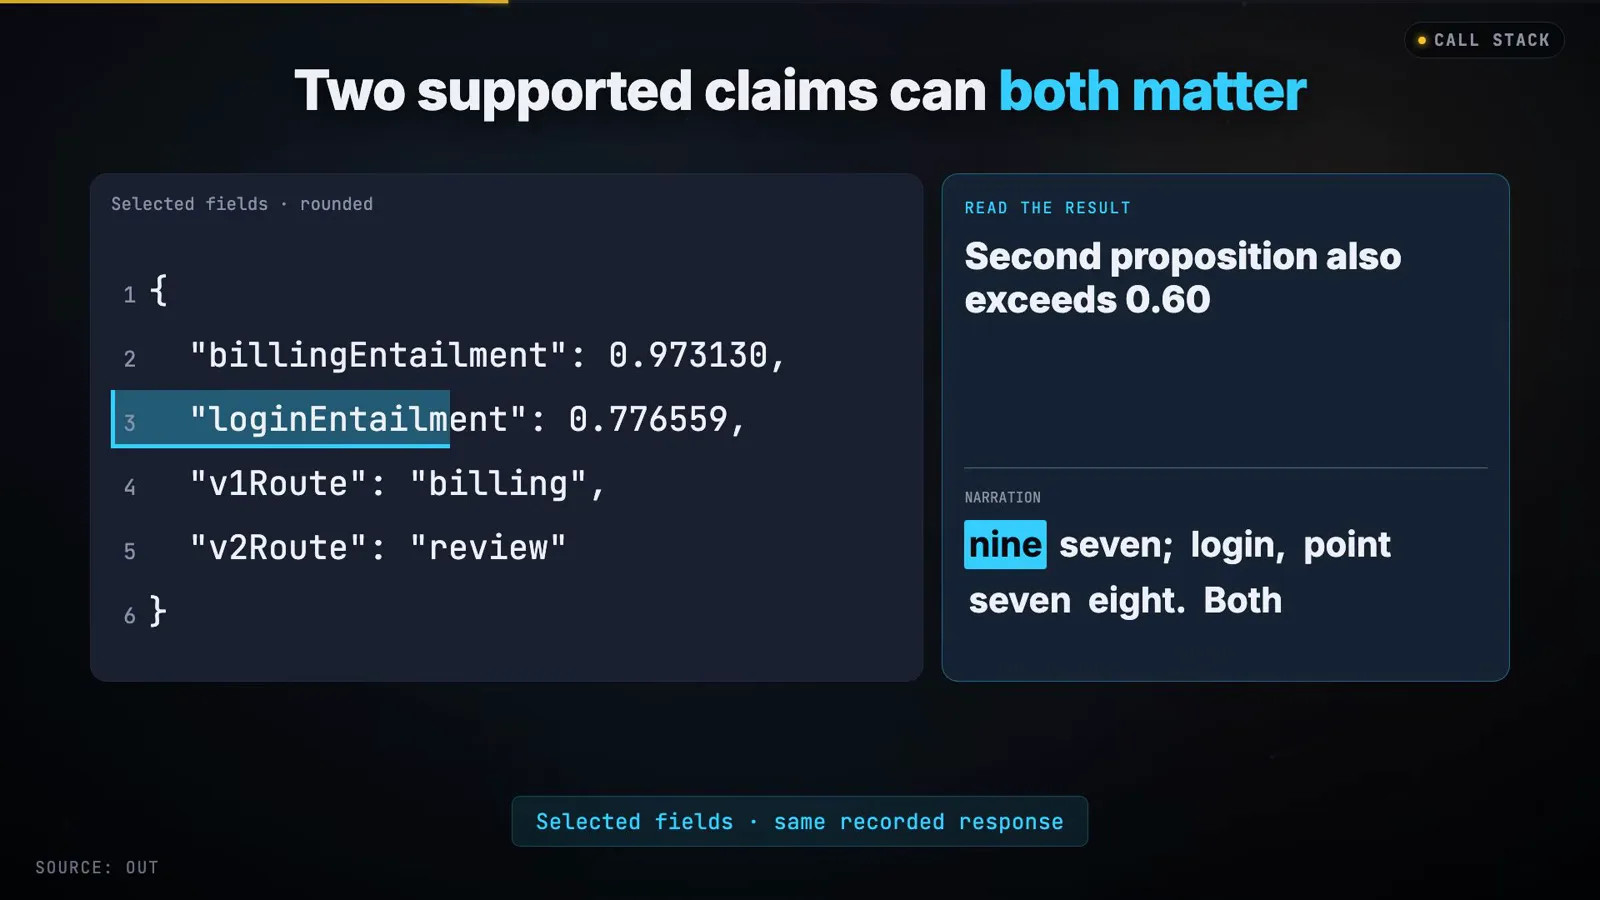
Both scores cleared 0.60. v1 picked one and dropped the other on the floor.Watch at 2:44 - 8
Rule v2: multiple propositions over threshold means review
Version two changes exactly one condition: when multiple propositions clear the threshold, send the ticket to review instead of picking a winner. The frame is the video's cold-open replay of that moment — billing at 97.31% and login at 77.66%, both over the line, and the route banner answering Human Review with an ABSTAIN badge, noting that the frozen pilot v1 would have routed billing. The model scores are identical; only the application decision changed. This is the cheapest possible fix for the hidden-second-issue failure — and the next step bills for it.
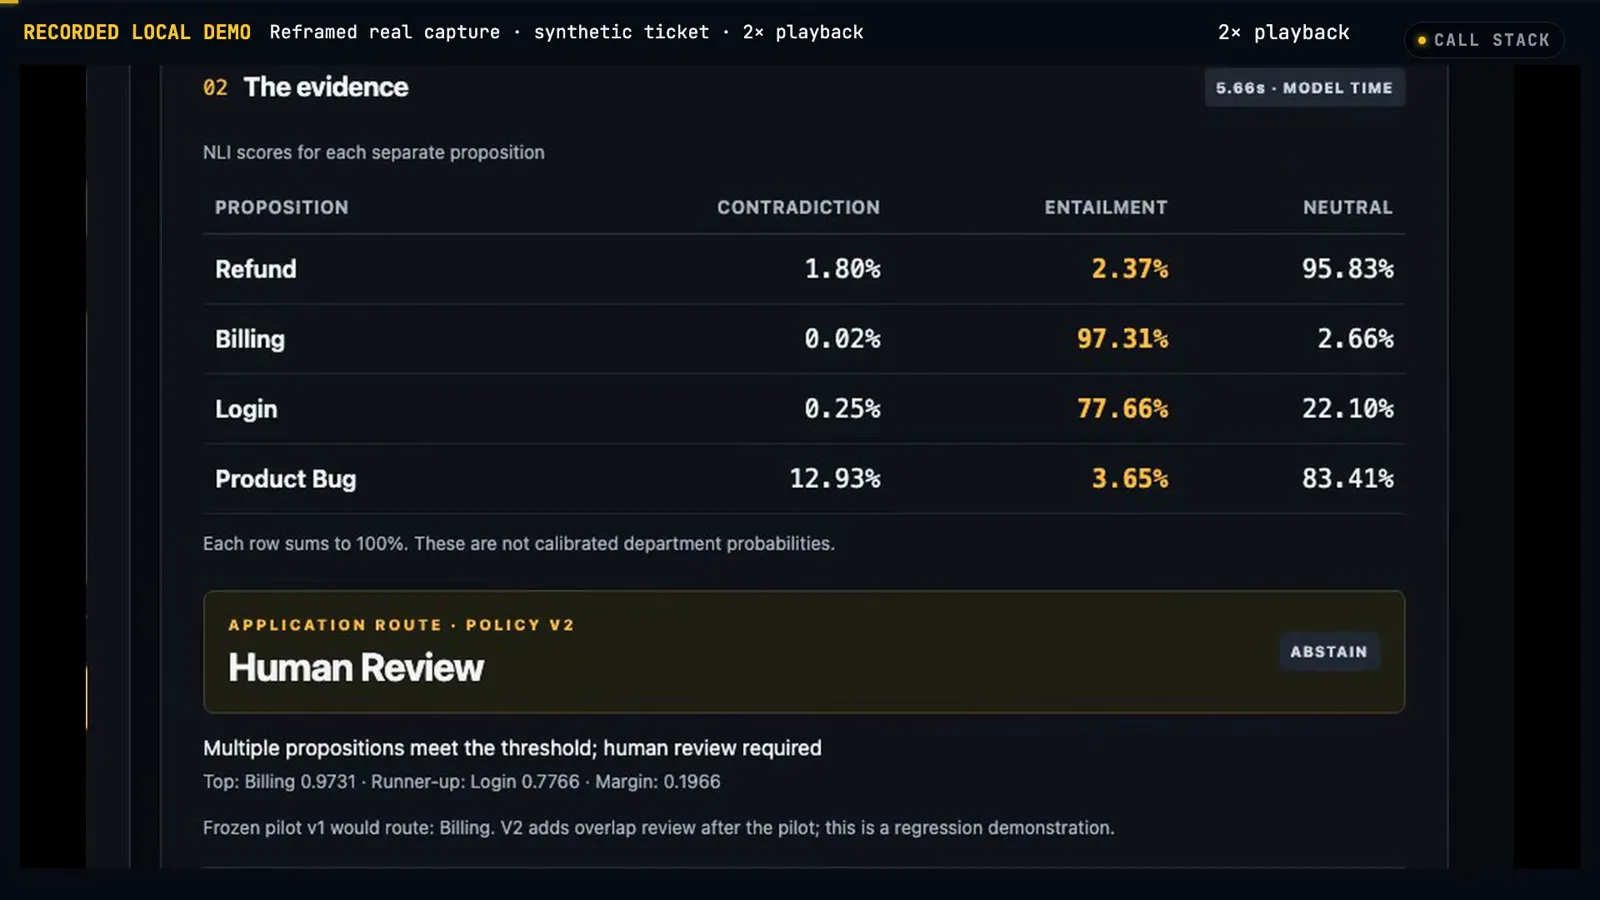
Same scores, new rule: two propositions over 0.60 now abstain to a human.Watch at 0:06 - 9
The cost: a clean refund ticket gets deferred
The stricter rule has to fail somewhere, and the video shows where. "I cancelled yesterday. Please return the payment for the unused month" is a refund request that mentions payments — so refund entailment 98.83% and billing entailment 72.77% both clear the threshold, and v2 defers a ticket the frozen pilot v1 would have routed to refund, matching the intended route. Both results stay in the video: the two-issue case improves, the refund case regresses into the review queue, and more reviews means more human work. The video adds the scope note this page insists on: the regression check ran on examples that had already been inspected, so it does not establish better performance on unseen tickets.
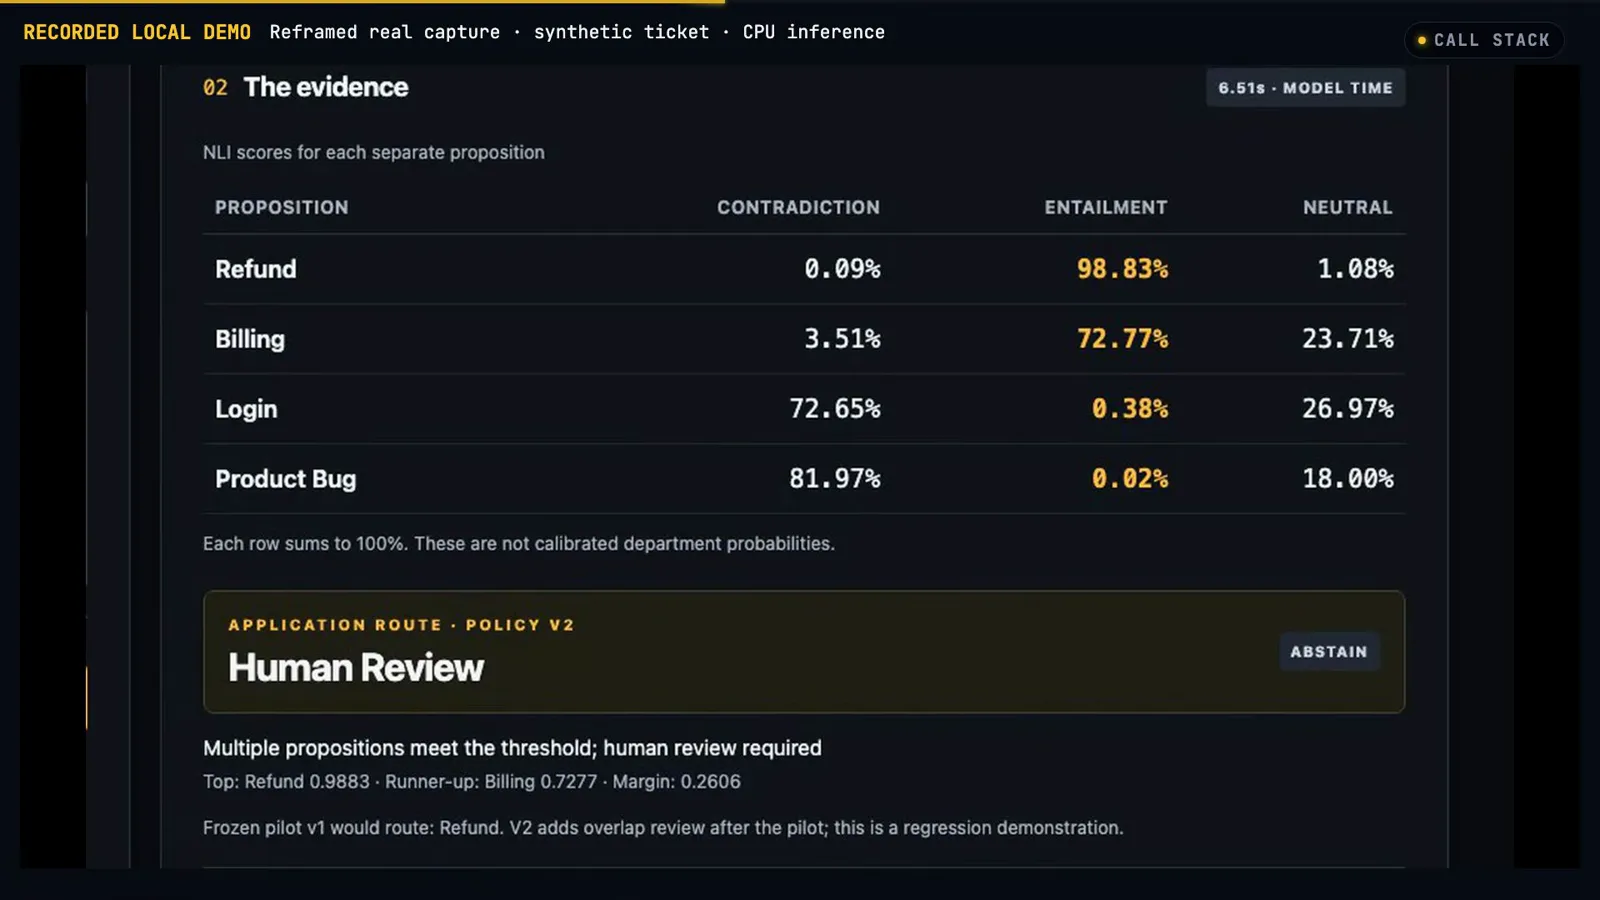
Refund 0.9883 and billing 0.7277 both clear — v2 sends a good ticket to review.Watch at 3:54 - 10
Miss diagnosis: bug beats login on a password reset
Next miss: an expired password reset link, labeled login beforehand. The returned scores promote product bug — 0.6866 against login's 0.4913 — and the app routes Product Bug, rule passed. The video refuses to stop at blaming the model: "broken application functionality" can legitimately overlap a login problem, so examine both wording and scores to decide whether the model, the taxonomy, or the routing policy needs revision. A valid probability vector can still produce an unwanted route. Two more authored misses get the same treatment in the video: an invoice-copy request falls under a billing hypothesis written too narrowly ("a problem with a charge or invoice"), and a praise message finds no category at all — forcing it into a department would add an assumption the taxonomy never earned.
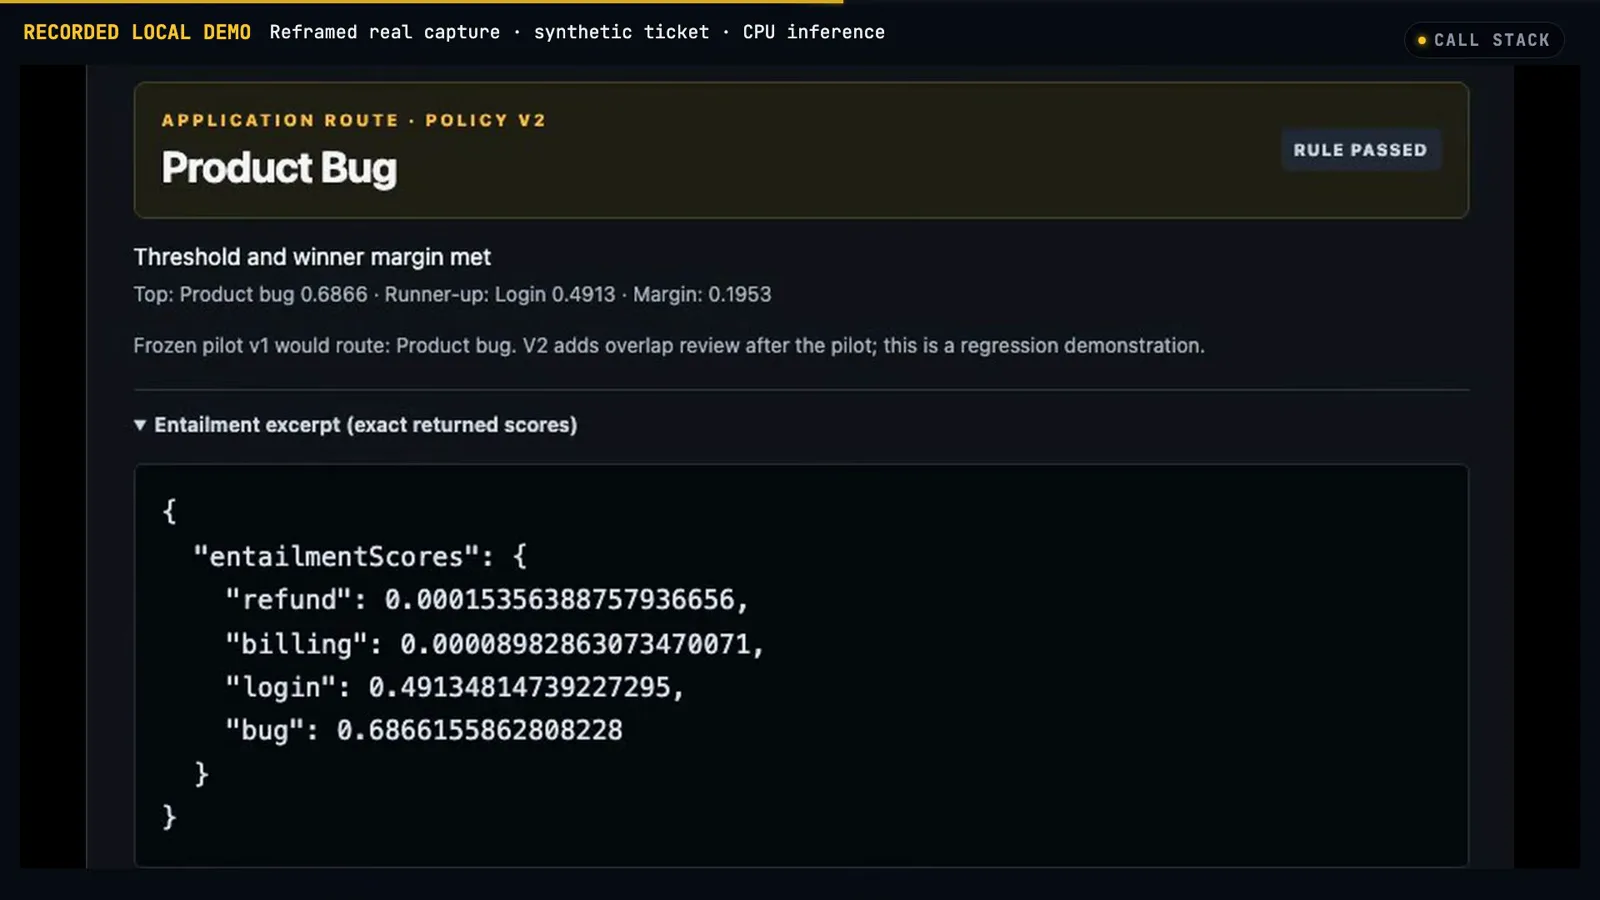
Bug 0.6866 vs login 0.4913 — the route mismatch the JSON makes inspectable.Watch at 4:32 - 11
The honest scoreboard: 2 of 4 and 7 of 12
Before any inference, the video wrote four calibration cases and twelve held-out cases — straightforward requests, negation, multiple issues, unrelated messages — and froze them. Under the original v1 rule the app matched 2 of 4 calibration routes and 7 of 12 held-out routes, by the metric shown in the JSON: "authored end-to-end route match". Then comes the framing this page borrows: those counts measure the model, the category definitions, and the routing logic together — they are not standalone model accuracy, and the scores are not calibrated chances of being right. The closing advice compounds it: settle what each department means, write examples before seeing predictions, keep an unchanged test set when you revise the policy, and preserve failures instead of replacing awkward outputs with nicer ones — otherwise you are testing your presentation layer.
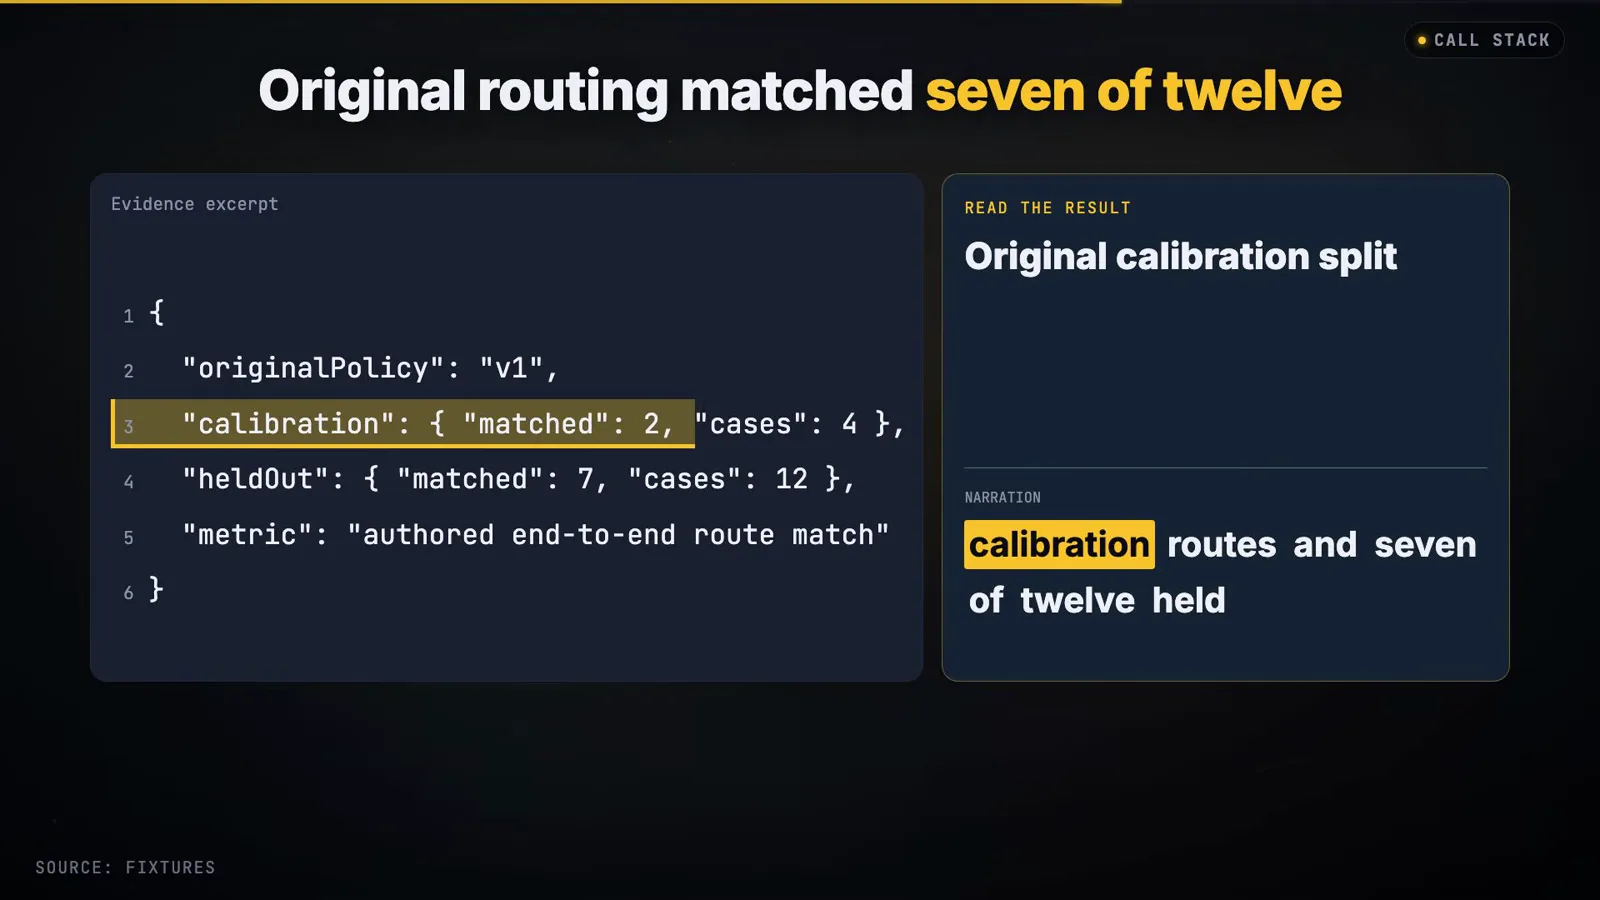
calibration 2/4, heldOut 7/12 — a scoreboard about the whole system, not the model alone.Watch at 6:02
Frequently asked questions
What is the OpenJev 0.8B checkpoint — and is it the official Jev model?
It is an independent 0.8-billion-parameter checkpoint published by AlexWortega, trained with NLI cross-entropy: it scores a premise (the ticket) against a hypothesis (a department statement) and returns contradiction, entailment, and neutral scores, which the application reads directly instead of asking the model to generate text. It is not TypeSafe's official Jev, which the video describes as trained with reinforcement learning for calibrated decisions — and per the video's own disclaimer, shared naming does not transfer the official model's performance claims.
What hardware does the CPU inbox need?
Modest, by local-model standards: the weights occupy about 1.71 GB on disk and the pilot process peaked around 3.20 GB of memory, running CPU inference in float32 — no GPU involved. Median model time was 5.63 seconds per request across 16 requests, each evaluating four hypotheses sequentially; that figure excludes model loading and the browser interaction, and no optimized GPU deployment was measured. After the files are downloaded, everything runs offline.
How do I read the contradiction / entailment / neutral scores?
Each department hypothesis is scored against the ticket separately: entailment means the ticket supports the statement (candidate evidence), contradiction means it argues against it (check what was negated), and neutral means the evidence is missing or unrelated — not a weak contradiction. Two reading rules from the video: entailment scores across propositions do not need to sum to one (a ticket can support billing and login at the same time), and each row's three scores are not calibrated department probabilities even though they sum to 100%.
How were the 0.60 threshold and the review rule chosen?
Provisionally, before seeing outputs: v1 takes the largest entailment, requires at least 0.60 and a 0.10 lead over second place, otherwise review. v2 adds one condition — when multiple propositions clear the threshold, the ticket goes to review. The video shows the trade-off honestly: v2 surfaces a hidden second issue (billing 0.97 + login 0.78) but defers a clean refund ticket where refund 0.9883 and billing 0.7277 both pass. Neither version is validated as correct; the advice is to fix the policy first, then measure wrong routes and unnecessary reviews against an unchanged test set.
Does 7-of-12 mean the model is 58% accurate?
No — and the video is explicit about it. The pilot used 4 authored calibration cases and 12 held-out cases, and v1 matched 2 of 4 and 7 of 12 end-to-end routes. Those counts measure the model, the category definitions, and the routing logic together; they are not standalone model accuracy, and the raw scores are not calibrated probabilities. The cases are authored probes written to exercise the application — not samples of real customer traffic — so treat the numbers as a baseline for the next policy revision, not a benchmark score.
What is this app good for — and what should it not do?
The suggested shape is modest on purpose: an assistant that suggests a queue while a person stays in control, with similar classifiers plausibly extending to tagging internal notes or sorting feedback — possible projects, not further results of this 16-ticket experiment. It should not auto-route consequential tickets on raw scores, and forcing off-taxonomy messages (praise, for example) into a department only adds wrong assumptions. Local inference removes one data transfer — not every risk: logging and deployment still need attention, and a public deployment needs a real backend design, since the browser is only an interface for the local Python worker.
Related guides
OpenJev RLCD: Run the Calibrated Decider Locally
The install-and-serve sibling: stand up the RLCD decider on Kaggle or llama.cpp. This page instead builds an application on an NLI checkpoint you download once.
ReadBuild Your Own Jev
The build-it-yourself axis: feed state plus strategy questions into your own typed decider. This page consumes a ready-made checkpoint and spends its time calibrating the routing policy.
ReadTrain Your Own Jev
The training-lever axis: what it takes to produce a decision model from scratch instead of downloading one — the upstream complement to this checkpoint.
ReadRun Jev Locally: the Official Path
The official TypeSafe model on your own hardware — the calibrated alternative whose performance claims this checkpoint explicitly does not inherit.
ReadTicket Classification with the Official API
The hosted-API version of the same job: support-ticket routing with typed questions and confidence — compare its latency and confidence semantics against this CPU pilot.
ReadMore video walkthroughs
- Jev Classification Quickstart: OpenRouter API, Primitives & Real Probabilities
- Jev Architecture Explained: Why 70ms Decision Models Beat LLMs for Workflow Automation
- Ultra-Fast Browser Agents with Jev: 178ms DOM Loops & Dual Model Orchestration
- Open Jev Models Are Here: Semif, Nimble, Decider, DiffusionGemma & Laya Hands-On
- Jev vs LLM: Will Jev Replace LLMs? Krish Naik's Whiteboard Explainer
- Jev Trader Tutorial: Build a Subsecond AI Trading Bot on Monad
- Jev Model Router: Build a Privacy-Gated LLM Router with Jev & OpenJev
- Jev Tutorial for Beginners: State, Questions & the TypeScript SDK
- Run Jev Locally: Kev, SemIf & Von on Your Own GPU (OpenJev Guide)
- Jev RAG Reranker: Policy-Steered Reranking for Retrieval-Augmented Generation
- When to Use Jev: An Engineer's Audit of Claims, Gates, and Failure Modes
- LangChain + Jev Integration Tutorial: Routing, Guardrails & Evals
- Jev MCP Server: Connect Jev Decisions to Claude Code & Cursor
- Jev vs Luna: Independent Benchmarks Put "Better, Faster, Cheaper" to the Test
- Jev Agent Harness: Where the Decision Gate Sits in Your LLM Loop
- Jev Playground Walkthrough: The Hotdog Lesson, Criteria, and a Four-Console Token Test
- Jev Text Classification API: Zero-Shot CLI & REST with classifier.dev
- Jev API Examples: First Request, curl & All Three Question Types
- Jev Log Triage with Expanso Edge
- Jev Lead Enrichment with Treg: ICP and Signup Scoring
- Use Jev Decision Nodes in Heym for Model Routing
- Laya Tutorial: Open-Source AI Routing With Calibrated Probabilities (Laya vs Jev Setup)
- Train Your Own Jev: Fine-Tune a Jev-Style Decision Model for $5–$17 (What You Can and Cannot Train)
- Jev Tips: 8 Best Practices for Better Decisions (State, Questions, Criteria & Thresholds)
- Jev Context Compaction: Prune AI Agent Memory Without Generative Summaries
- Jev as an LLM Judge: Confidence-Gated Cascades at 0.36% of the Cost
- TypeSafe Computer Use: Local Desktop Automation with Jev, Step by Step
- Jev Resume Screening: Build an AI Resume Evaluator with the Jev JavaScript SDK
- Jev + Claude Code Guide: Voice-Controlled Browser Automation with Typed Decisions
- Jev + Codex: Install the TypeSafe Skill and Triage a Real Gmail Inbox
- Jev vs Ollama: Can Local AI Replace Hosted Jev Without Sending Your Data Away?
- Build Your Own Jev: Train a Free Open-Source Zero-Shot Classifier (That Plays Doom)
- CUA-S1-Forms: a 706K-Parameter Jev-Like Model That Fills GUI Forms on Your CPU
- NOC/SOC Alert Triage with Jev: Rules First, One Typed Question, a Policy Gate
- Ollama Decision Models: Run tev1 and Nimble Locally (Tested on an 8 GB Card)
- Jev Guardrails in Production: A Five-Step Playbook for Decision Automation
- A Session Drift Guard for Pi Agent: Let the Jev Model Propose, Let Code Decide
- 50 Tev1 Use Cases: What a Local Decision Model Can Actually Do (Tested on an 8 GB Laptop)
- Jev, Hands-On: Where the Official Claims Meet Independent Remeasurement
- Jev Ticket Classification in a Real App: the After-Insert Hook and the Calculated Field
- OpenJev RLCD: Run the Open-Source Calibrated Decision Model Locally (Full Guide)
- Clef-Flash vs Jev: I Tested Cloudflare's Decision Model Locally in Ollama (Q4_K_M)
- Julia-1 Tutorial: Install the Open-Source Jev Replacement in Pure Python (and Watch It Beat If-Statements 9 to 2)
- Jev n8n Integration: the JevGate Community Node, Step by Step (Plus a Plain-HTTP Fallback)