Guides / illustrated walkthrough
Jev vs LLM: Will Jev Replace LLMs? Krish Naik's Whiteboard Explainer
Krish Naik breaks down Jev, the System One model from TypeSafe AI: how it makes probabilistic decisions instead of generating tokens, why it will not replace LLMs, and the hybrid Jev + LLM architecture for agentic AI — with support-routing, tool-selection, and multi-agent examples.
Quick takeaway
Jev is TypeSafe AI's System One model: instead of generating tokens and strings, it makes probabilistic decisions — classify, route, score, decide — the way a classifier outputs a probability for cat, dog, monkey, or horse. Krish Naik's verdict on whether Jev replaces LLMs is a clear-cut no: LLMs stay the brain for text, code, and reasoning generation, while Jev takes over the fast judgments in front of and behind them. In his examples, an EdTech support query routes as support 0.3, finance 0.1, sales 0.6, and an agent with five tools picks SQL at 0.96 — decisions an LLM only reaches after reasoning and burning tokens. The reference architecture: user → Jev → RAG/tools/agents → LLM → Jev verification gates that accept or regenerate. TypeSafe's side-by-side demo shows 0.114s vs 8.5s completion and $0.00081 vs $0.013 cost, with 70–500ms end-to-end responses claimed.
Video source
Krish Naik
Step-by-step walkthrough
- 1
See why the LLM ReAct loop burns so many tokens
Krish opens by drawing how agentic AI applications work today: an input goes to the LLM, which acts as the brain. The LLM thinks, decides whether to call external tools, loops through the ReAct loop, and finally generates an output. Along that loop most of the work is generation — text, code, summaries — and reasoning itself produces a large number of tokens. His core claim: the future belongs to whoever can optimize tokens efficiently.
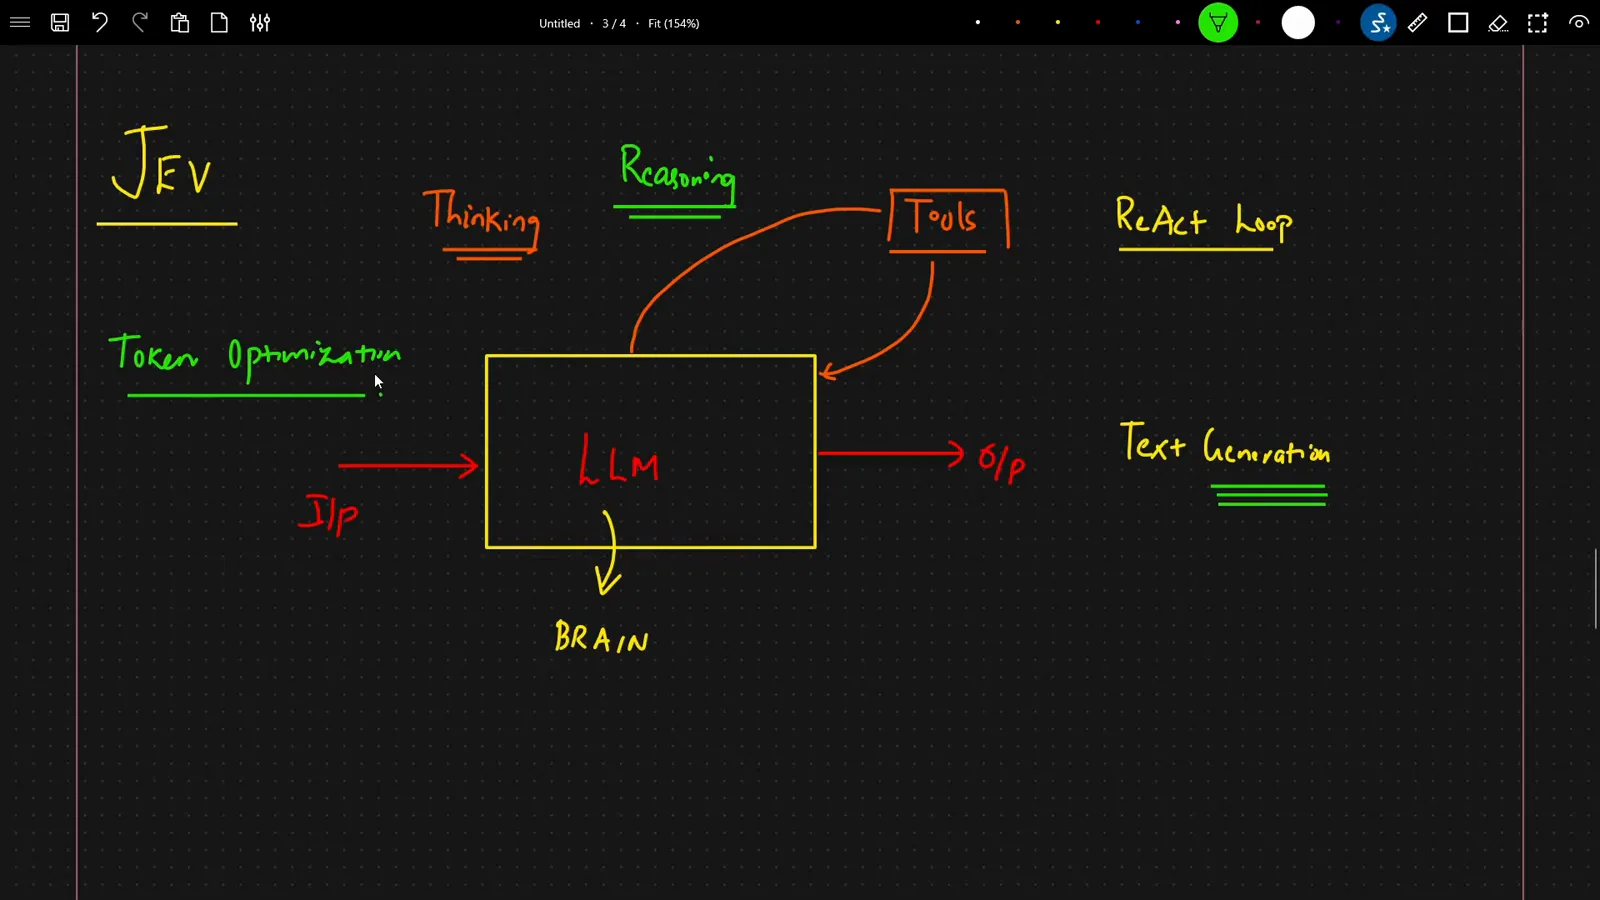
The ReAct loop: LLM as the brain, tools on the side, tokens generated at every reasoning turn.Watch at 4:25 - 2
Understand Jev as a System One model that judges, not generates
Jev, built by TypeSafe AI, is what TypeSafe calls a System One model. Instead of generating tokens and strings, it makes probabilistic decisions — like a classifier deciding cat, dog, monkey, or horse, or a quick yes/no judgment such as whether you are hungry. That judgment can then be passed to the LLM, which remains very good at generation: text, code, emails, summaries, reasoning, and conversation. On the replacement question, Krish is unambiguous: if you think Jev will replace the LLM, the answer is clear-cut no — it complements it.
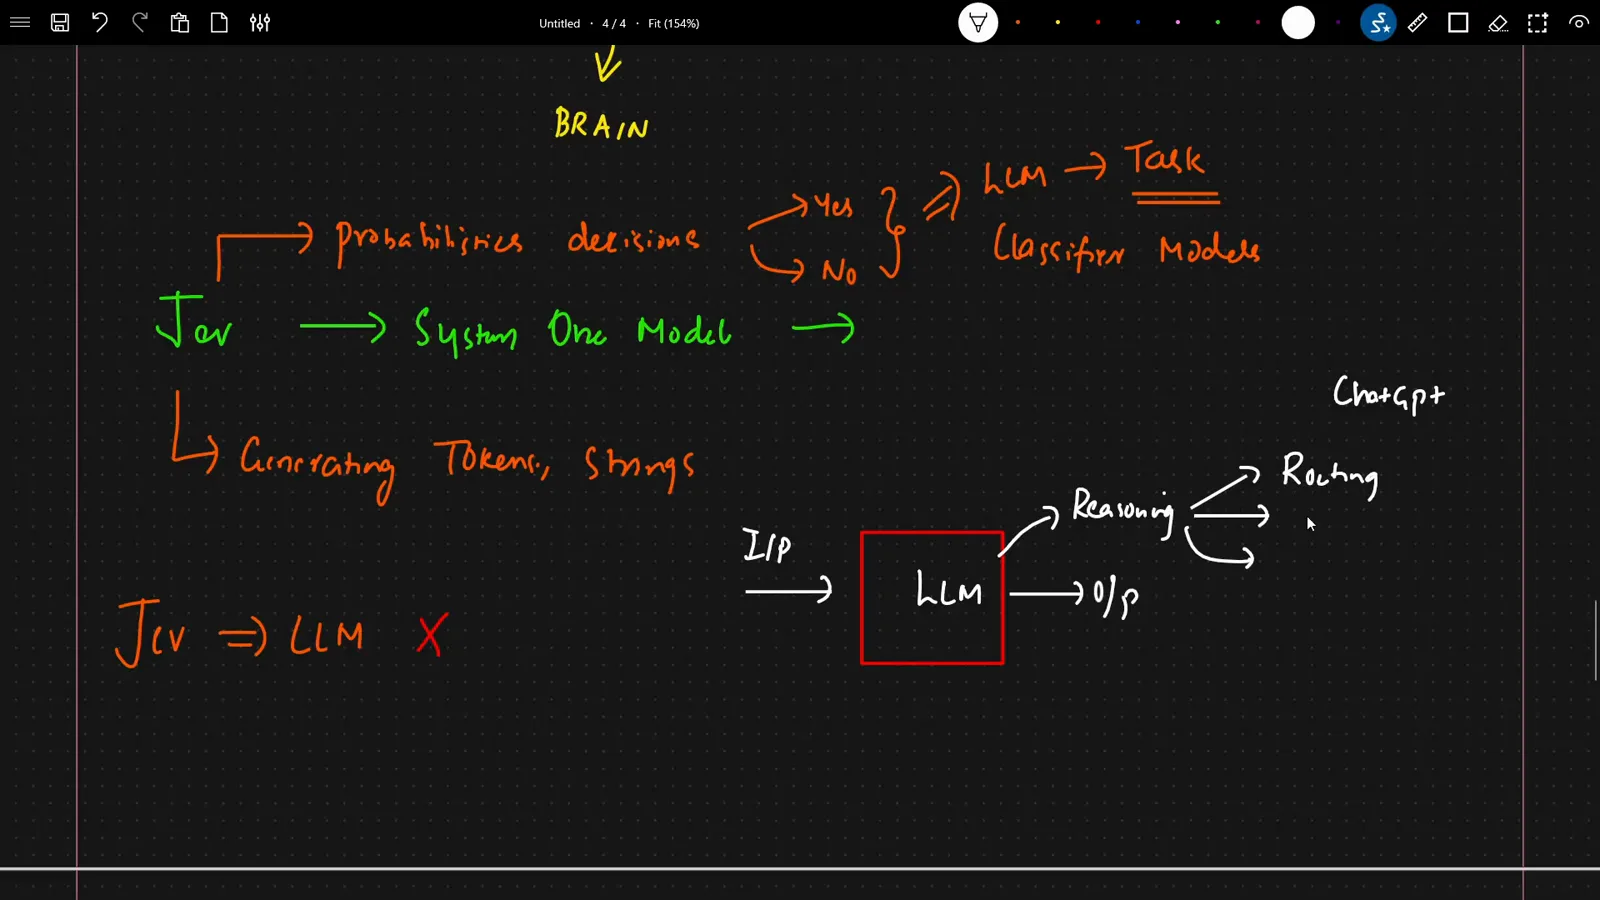
Jev judges, the LLM generates — the crossed-out 'Jev ⇒ LLM' settles the replacement question.Watch at 7:00 - 3
Route support tickets with probabilities: 0.3 / 0.1 / 0.6
In his EdTech company example, a chatbot receives "I have some queries related to one of the courses which we need to buy" — an NLP unstructured query that must reach the support, finance, or sales team. Fed to Jev, the same query comes back as a probability distribution: support 0.3 (30%), finance 0.1 (10%), sales 0.6 (60%), so it routes to sales. Given to the LLM instead, the model reasons internally about the person wanting to buy a course, taking more time and generating more tokens before reaching the same decision. From Jev’s output, custom code can send the query to the LLM, a human, another department, or handle it directly.
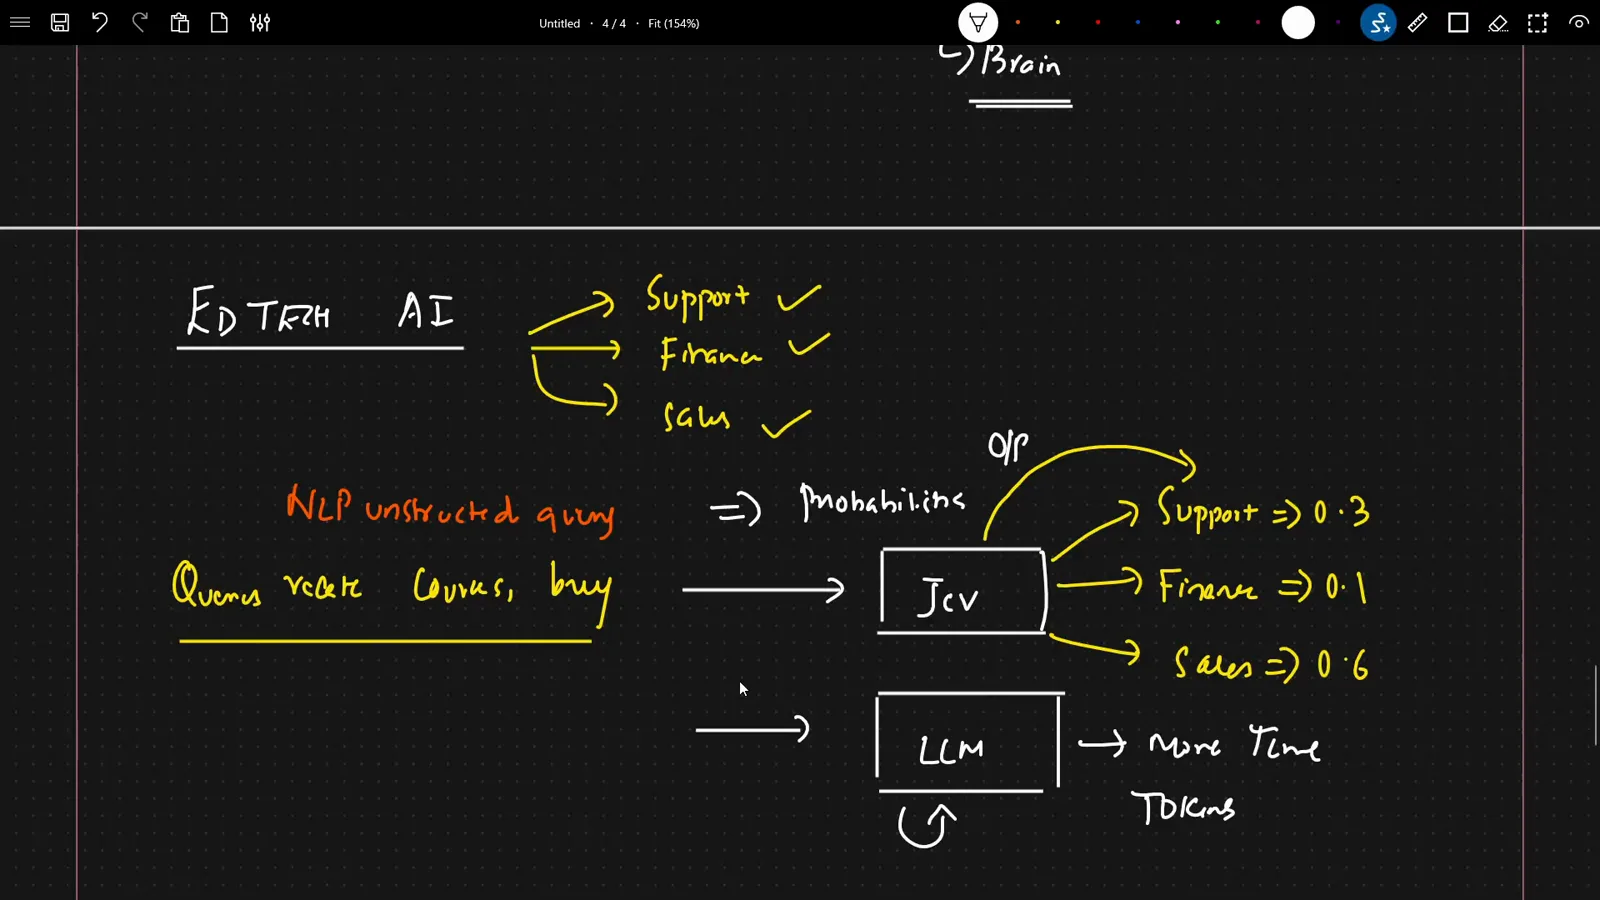
One unstructured query, three probabilities: sales 0.6 wins, and the LLM path pays in time and tokens.Watch at 11:10 - 4
Pick agent tools in one pass: SQL at 0.96
Second example: an AI agent with five tools — SQL, web search, Python, calculator, and email — is asked to find the company’s revenue for the last month or six months. The current LLM path reasons step by step, generates tokens, and finally understands it should hit the SQL database. The Jev path assigns SQL a 0.96 probability, Python 0.02, web search 0.01, and calculator 0.005, so the query goes straight to the SQL tool. Routing and classification like this, Krish argues, is exactly what Jev is good at — the LLM never has to think.
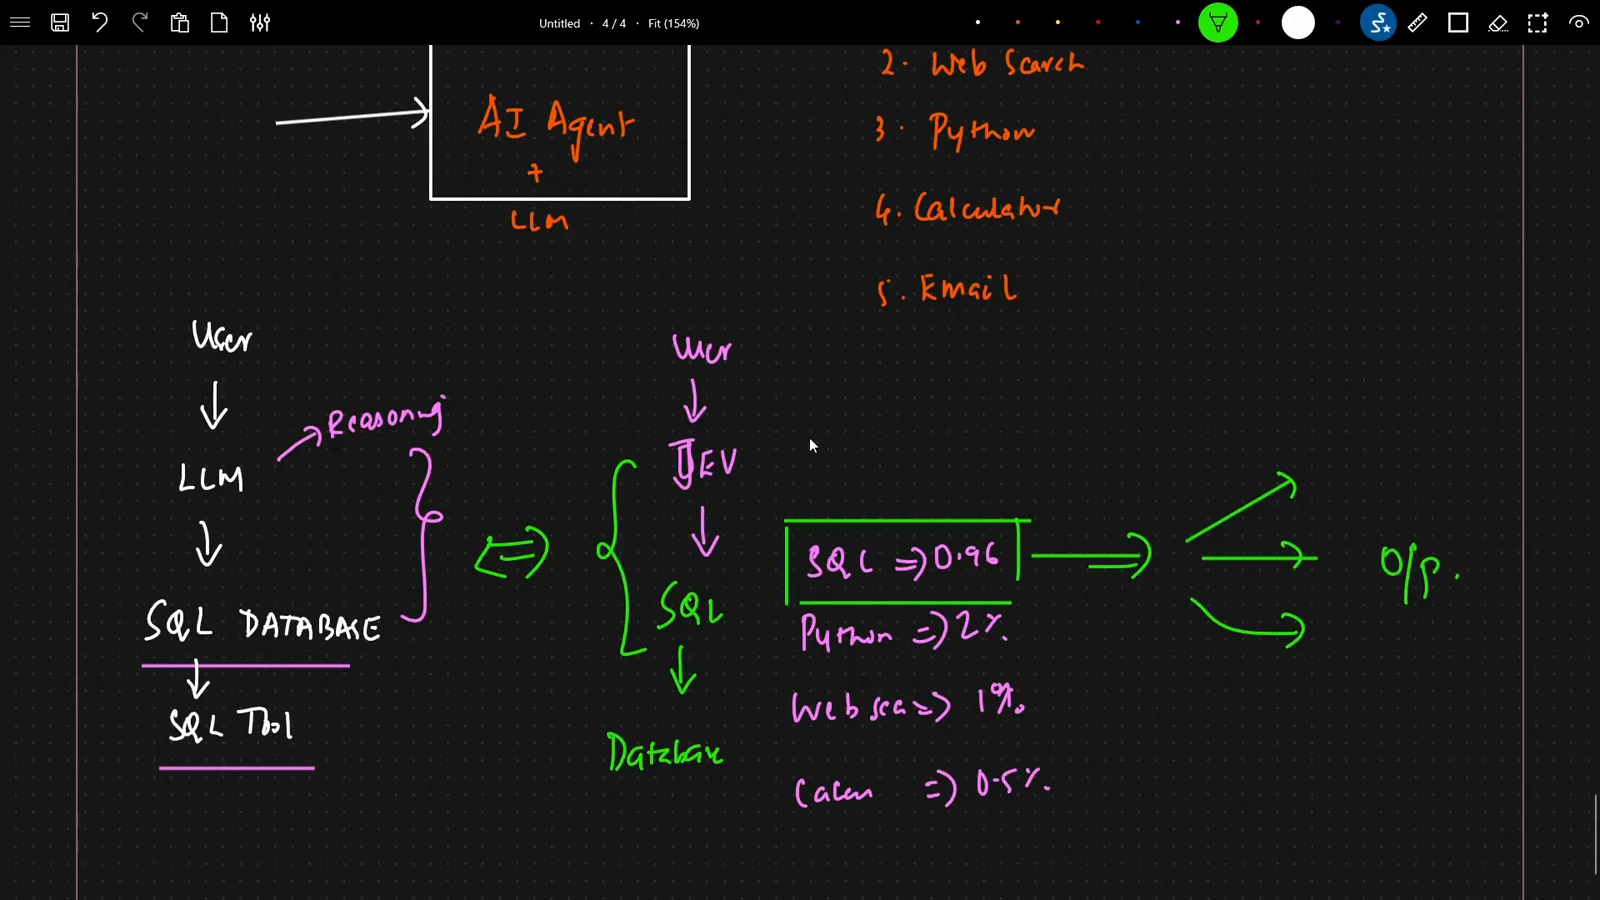
SQL at 0.96 — Jev picks the tool in one pass so the LLM never reasons its way there.Watch at 16:45 - 5
Scale to multi-agent platforms: Jev complements, not replaces
The board repeats it in green ink: Jev ≠ LLM, therefore complement. In a multi-agent enterprise AI platform scenario, the user asks the system to analyze the AWS bill and identify why GPU spending increased by 30 percent. Sent to an LLM, the query triggers internal thinking about which agent to hit; with Jev, an unstructured natural-language query maps straight to the right specialist among coding, finance, and research agents — here, the finance agent. Agent and model routing, Krish says, becomes super easy with a Jev model in front.
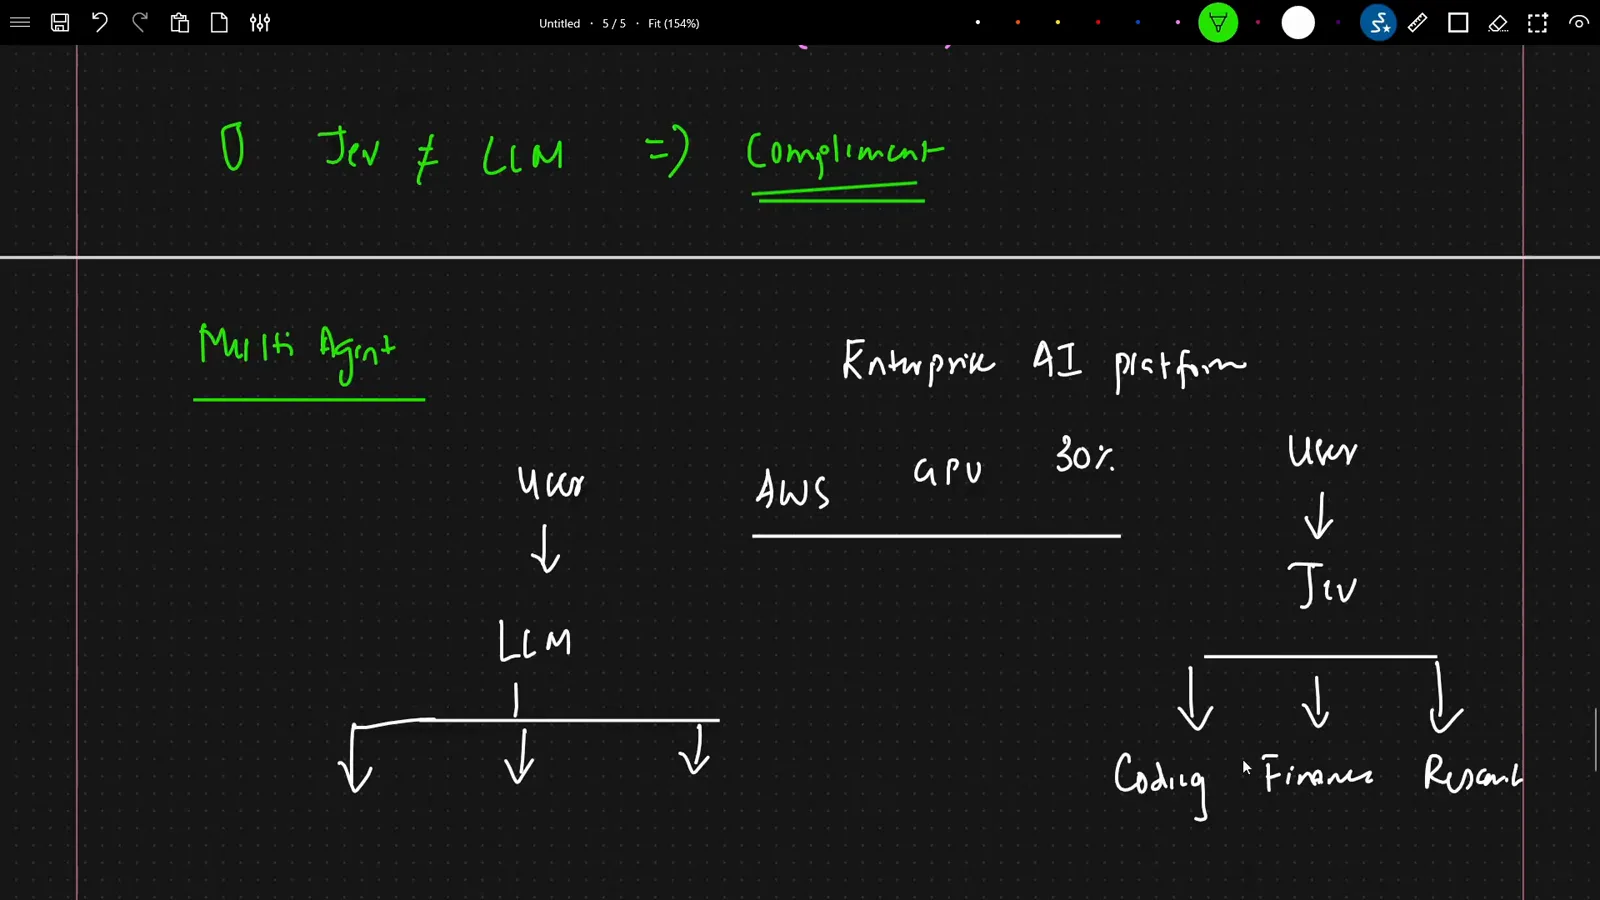
AWS bill, GPU spend up 30% — Jev routes straight to the finance agent.Watch at 19:20 - 6
Adopt the hybrid architecture: Jev gates on both ends
The resulting agentic AI architecture puts Jev at the entrance and the exit. The user query hits the System One model first to classify, route, score, and decide which tool, RAG pipeline, or agent to call; the LLM then handles the complex work — reasoning, generating, explaining; and a second Jev pass judges the output, working like guardrails with logical gates that output accept or regenerate. Because Jev only decides yes or no, hallucination drops, cost stays low, and the whole loop gets faster. TypeSafe’s side-by-side numbers shown in the video: 0.114s vs 8.5s completion, $0.00081 vs $0.013 cost, and 70–500ms end-to-end — 200 to 400 times faster at similar frontier intelligence.
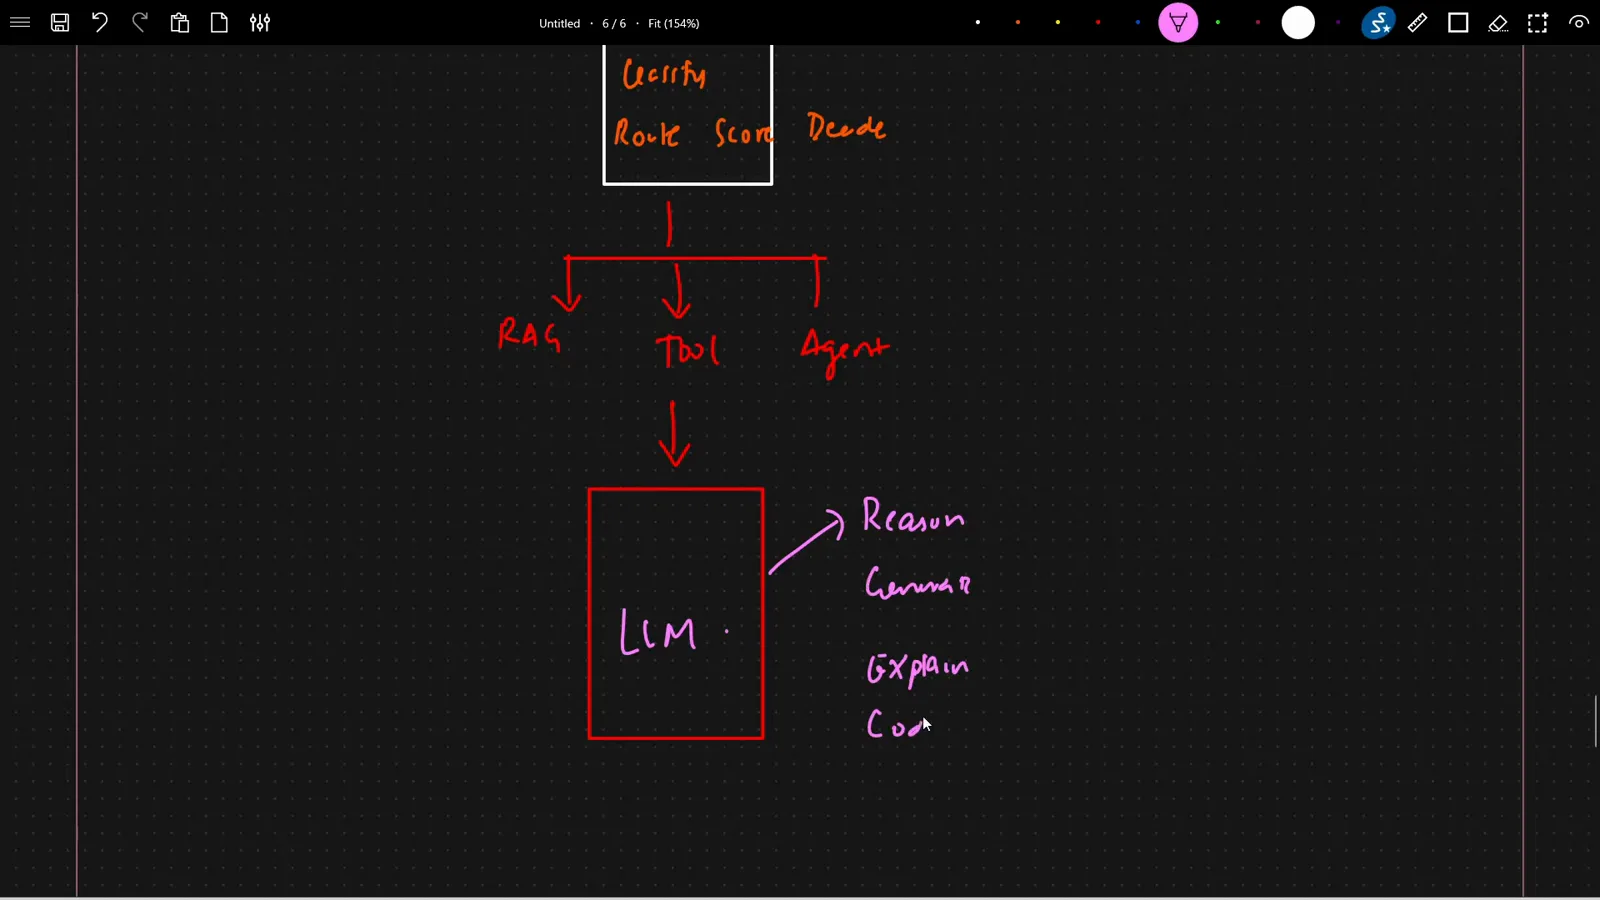
The full stack: Jev classifies and gates, RAG/tools/agents act, the LLM generates, Jev verifies.Watch at 21:46
Frequently asked questions
Will Jev replace LLMs?
No — Krish Naik calls it a clear-cut no in the video. Jev does not generate text at all; it makes probabilistic judgments that feed the LLM. LLMs remain the brain for text, code, email, and summary generation, reasoning, and conversation. Jev complements them by taking over fast routing and classification decisions so the LLM generates fewer tokens.
When should I use Jev instead of an LLM?
Use Jev when software needs a fast judgment rather than prose: customer-support routing (his EdTech example scored support 0.3, finance 0.1, sales 0.6), agent tool selection (SQL picked at 0.96 among five tools), multi-agent routing (AWS GPU question to the finance agent), and output verification guardrails. Once the decision is made, the LLM still handles generation.
What is a System One model?
The term TypeSafe uses to position Jev: a fast, instinctive layer that makes probabilistic decisions the way a classifier outputs cat/dog/monkey/horse probabilities or a yes/no answer. It contrasts with the deliberate, System Two-style reasoning of LLMs, which think through steps and generate tokens for every decision.
Can Jev and LLMs work together in one pipeline?
Yes — that is the architecture Krish recommends for agentic AI: user query first hits Jev to classify, route, score, and decide; the request then flows to the chosen tool, RAG pipeline, or agent; the LLM does the heavy reasoning, generation, and explanation; and a final Jev pass acts as a guardrail, scoring the output through yes/no logical gates that accept or regenerate. The video cites 70–500ms end-to-end responses, 200–400x faster completion, and demo costs of $0.00081 vs $0.013.
Related guides
What is Jev?
The foundational overview of Jev as a System One decision model — what it is, and how it differs from generative LLMs.
ReadJev Architecture Explained
Why 70ms probabilistic decision models beat autoregressive LLMs for workflow automation latency and cost.
ReadJev vs Instructor
Native probabilistic decisions versus coercing structured JSON out of an LLM — a practical comparison.
ReadMore video walkthroughs
- Jev Classification Quickstart: OpenRouter API, Primitives & Real Probabilities
- Jev Architecture Explained: Why 70ms Decision Models Beat LLMs for Workflow Automation
- Ultra-Fast Browser Agents with Jev: 178ms DOM Loops & Dual Model Orchestration
- Open Jev Models Are Here: Semif, Nimble, Decider, DiffusionGemma & Laya Hands-On
- Jev Trader Tutorial: Build a Subsecond AI Trading Bot on Monad
- Jev Model Router: Build a Privacy-Gated LLM Router with Jev & OpenJev
- Jev Tutorial for Beginners: State, Questions & the TypeScript SDK
- Run Jev Locally: Kev, SemIf & Von on Your Own GPU (OpenJev Guide)
- Jev RAG Reranker: Policy-Steered Reranking for Retrieval-Augmented Generation
- When to Use Jev: An Engineer's Audit of Claims, Gates, and Failure Modes
- LangChain + Jev Integration Tutorial: Routing, Guardrails & Evals
- Jev MCP Server: Connect Jev Decisions to Claude Code & Cursor
- Jev vs Luna: Independent Benchmarks Put "Better, Faster, Cheaper" to the Test
- Jev Agent Harness: Where the Decision Gate Sits in Your LLM Loop
- Jev Playground Walkthrough: The Hotdog Lesson, Criteria, and a Four-Console Token Test
- Jev Text Classification API: Zero-Shot CLI & REST with classifier.dev
- Jev API Examples: First Request, curl & All Three Question Types
- Jev Log Triage with Expanso Edge
- Jev Lead Enrichment with Treg: ICP and Signup Scoring
- Use Jev Decision Nodes in Heym for Model Routing
- Laya Tutorial: Open-Source AI Routing With Calibrated Probabilities (Laya vs Jev Setup)
- Train Your Own Jev: Fine-Tune a Jev-Style Decision Model for $5–$17 (What You Can and Cannot Train)
- Jev Tips: 8 Best Practices for Better Decisions (State, Questions, Criteria & Thresholds)
- Jev Context Compaction: Prune AI Agent Memory Without Generative Summaries
- Jev as an LLM Judge: Confidence-Gated Cascades at 0.36% of the Cost
- TypeSafe Computer Use: Local Desktop Automation with Jev, Step by Step
- Jev Resume Screening: Build an AI Resume Evaluator with the Jev JavaScript SDK
- Jev + Claude Code Guide: Voice-Controlled Browser Automation with Typed Decisions
- Jev + Codex: Install the TypeSafe Skill and Triage a Real Gmail Inbox
- Jev vs Ollama: Can Local AI Replace Hosted Jev Without Sending Your Data Away?
- Build Your Own Jev: Train a Free Open-Source Zero-Shot Classifier (That Plays Doom)
- CUA-S1-Forms: a 706K-Parameter Jev-Like Model That Fills GUI Forms on Your CPU
- NOC/SOC Alert Triage with Jev: Rules First, One Typed Question, a Policy Gate
- Ollama Decision Models: Run tev1 and Nimble Locally (Tested on an 8 GB Card)
- Jev Guardrails in Production: A Five-Step Playbook for Decision Automation
- A Session Drift Guard for Pi Agent: Let the Jev Model Propose, Let Code Decide
- 50 Tev1 Use Cases: What a Local Decision Model Can Actually Do (Tested on an 8 GB Laptop)
- Jev, Hands-On: Where the Official Claims Meet Independent Remeasurement
- Jev Ticket Classification in a Real App: the After-Insert Hook and the Calculated Field
- OpenJev RLCD: Run the Open-Source Calibrated Decision Model Locally (Full Guide)
- Clef-Flash vs Jev: I Tested Cloudflare's Decision Model Locally in Ollama (Q4_K_M)
- Clef-Flash Tutorial: Install and Run Cloudflare's 9B Multimodal Decision Model Locally on Ubuntu
- CLM-8B: the Contrastive Decision Model That Scores 1,024 Options in 44 ms (13x Faster Than Jev)
- Nox 4B Tutorial: Run the Decision 2.0 Model Locally and Put It Through Four Real Decisions (One Ends in a Fail)
- Julia-1 Tutorial: Install the Open-Source Jev Replacement in Pure Python (and Watch It Beat If-Statements 9 to 2)
- OpenJev 0.8B on CPU: I Built a Ticket-Routing Inbox and Calibrated the Thresholds
- Jev n8n Integration: the JevGate Community Node, Step by Step (Plus a Plain-HTTP Fallback)
- NanoJev Tutorial: Install the 0.6B Open-Source Jev Replica and Watch It Route Decisions at 47 ms
- PPLX Decider Tutorial: Perplexity's Open 27B Decision Model, Its Decisions API, and a 12-Ticket Triage Run
- AutoTrust JEV-27B Tested Locally: Four Arms, 72 Cases, and One 0.969 Score That Was Wrong
- Clef 27B Locally: Watch Cloudflare’s Multimodal Decision Model Read an Image, a Video and an Uzbek Newspaper in One Pass
- Ollaya Guide: Install the "Ollama for Decision Models" Runner, Read Every Vendor-Reported Number, and Run the CPU Test It Leaves Open
- Strands Decider 2B Tutorial: Install the AWS Strands Decision Model on an 8GB Laptop — and Keep Its Failures In
- Liquid AI Open d1 Locally: d1-3B and d1-omni-600M on a MacBook Air M5 — Guardrails, Screen Checks, Voice Routing and Document Triage, Every Number Frame-Checked
- Image Decision Models for RPA: Watch Two Open Models Review an Unsigned W-8BEN With No OCR
- GLiNER2.5-Decide (340M) vs Jev (4B): Which Decision Model Actually Wins? A Frame-by-Frame Selection Guide
- Decision Models on Jetson: Jev vs Strands Decider 2B vs Laya vs d1-3B — Skill Master Scores, Thor Latency and JevBench, Every Number Frame-Checked
- Microsoft Decision-1 Tested: 146 Independent Tests, a 93% Mean, 124/125 When Confident — Every Number Frame-Checked
- Wire Jev into an Azure AI Foundry Agent as the Evaluation Layer — OpenAPI Tool, TypeSafe Connection, Triage Instructions and an Honest First-Run Failure